@heyitskevinai Running the same prompt on two models is such an underrated move, the differences jump out way faster than any leaderboard. Which pairing do you end up comparing most often?
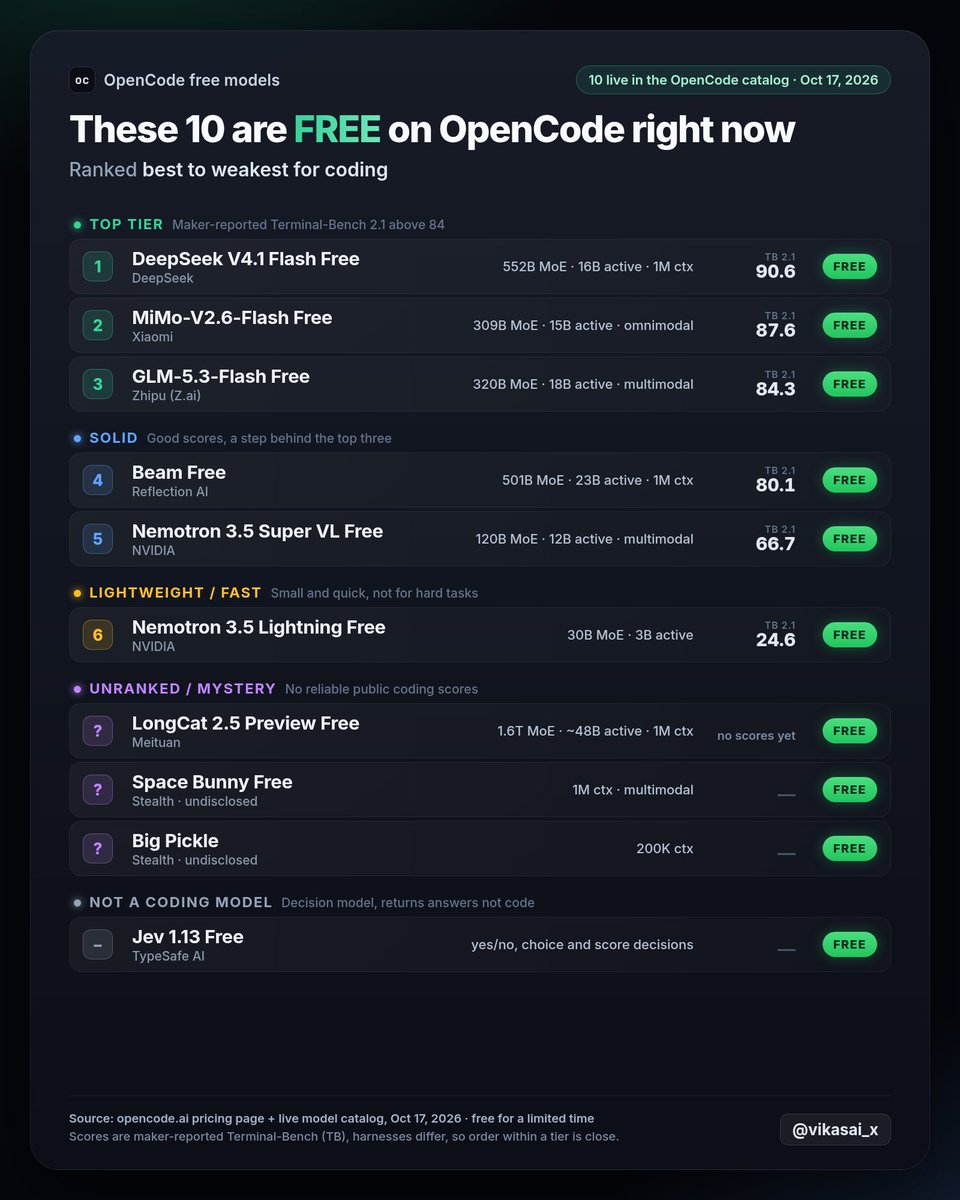
OpenCode has gone crazy 🤯 10 models are completely free right now, including DeepSeek V4.1 Flash, GLM 5.3 Flash and Beam. Four have already been retired, so this won't last forever.
Which of these were you paying for on OpenRouter? 👇 @opencode#OpenCode
@opencode Here's the pricing page if you want to check the list yourself. Every model marked Free shows $0 for input and output, for a limited time https://t.co/QLCDFRhQ2j
There are 10 free models in OpenCode right now, and DeepSeek V4.1 Flash and GLM 5.3 Flash are among them 🤯
I honestly can't work out how @opencode affords this. Who is actually paying for all these tokens? If you know how this works, please tell me #OpenCode#AI
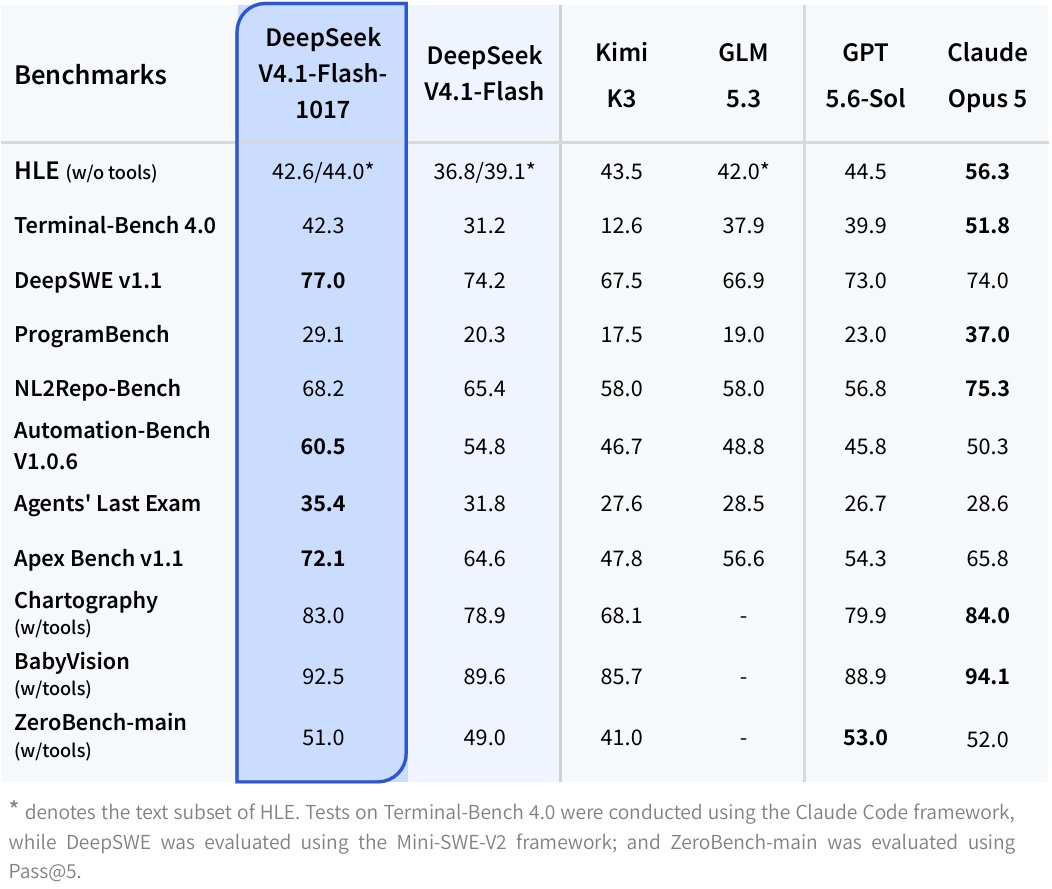
@deepseek_ai@DeepSeekHarness Better scores and shorter answers at the same time is the part I like most. Is 1017 now the default behind deepseek-v4.1-flash in the API or do we need to pin it?
DeepSeek calls V4.1 Flash 1017 a "minor update" but by their own numbers Terminal-Bench jumped from 31 to 42 😅 Open weights under MIT, shorter outputs, live now in their app and API. Curious if it feels that much better in real coding @deepseek_ai#DeepSeek#OpenSource
@ClaudeDevs That cloud number going from 17s to 6s is the one that surprised me most. Is starting the session up while someone is still typing something you might bring to local sessions too, or does that only make sense in the cloud?
@ClaudeDevs@bcherny@claudeai Want to feel it yourself? Update Claude Code to the latest version (large requests are gzipped by default since v2.1.300). Cloud sessions get the faster startup too. Install and docs 👇
https://t.co/jGyrlelr2b
Claude Code now starts replying about 3x sooner 🔥 Per @ClaudeDevs it gzips the conversation every turn, and the p90 wait before the first token fell from 4.07s to 1.33s locally. Love seeing a speed win come from plumbing work like this. Kudos @bcherny@claudeai#ClaudeCode
@henriquebuilds Meetings are such a good fit for that, nobody wants that audio leaving their laptop. How does the Apple foundation model hold up on an hour long call, do you have to chunk the transcript before summarizing?
Reflection just dropped Beam 1.0 open weights, Apache 2.0. 501B MoE, 23B active, built for coding and long agent runs.
Been waiting for a serious open model not from China or Meta. Going on my local testing list this weekend
https://t.co/ytgj6RzW9B
@henriquebuilds Honestly the 23B active part is the easy bit, it's holding all 501B weights in memory that's the real wall. I'd guess most people end up on a heavy quant or a rented GPU box for this one. What kind of small on-device models are you shipping on the Mac?
@pika_labs Timeline editing just by asking ChatGPT is the part I didn't expect. Curious how well it keeps a character consistent when you regenerate only one clip
Elorian just dropped Glimpse, their first model, and I love that it goes back to the image while it reasons. It zooms in, rewatches a clip at a higher frame rate, runs code to count things. Their own evals put it near GPT-6 Astra on several tasks. @ElorianAI@AndrewDai#VLM
@ElorianAI The teleop labeling demo looks really useful. Boxing objects and splitting an episode into pick and place events is grunt work robotics teams hate doing by hand. Does the visual scratch space show up through the API too or only in the chat UI?
Loved this bit from @bcherny on @lennysan's podcast. Plan mode in Claude Code is literally one injected sentence telling the model not to write code yet. You hit Shift+Tab twice, go back and forth on the plan, and then let it auto accept edits #ClaudeCode