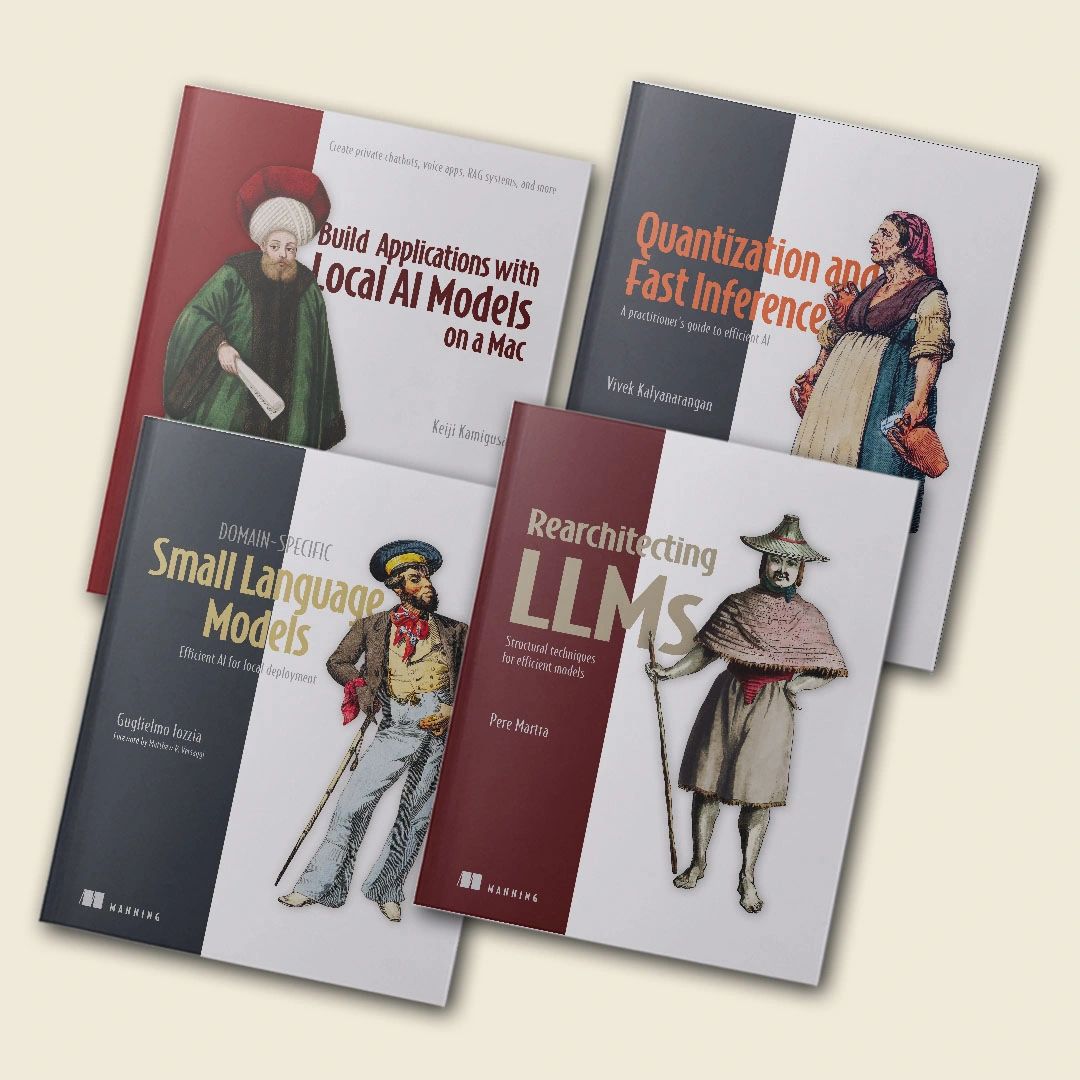
For a year I've been writing a book and not telling anyone. Today it goes live.
📚 Quantization and Fast Inference with Manning Publications Co.
🎉 50% off site-wide through May 19.
---
LINKS
✨ MEAP: https://t.co/S0y9CqVHu6
More and more people and companies are convinced that open-source models and custom SLMs are the way to go for serious projects.
@ManningBooks is offering a free eBook, Local AI and Small Language Models, with four chapters on how to choose, adapt, run and build with them. 🧵
Paper: https://t.co/XBgyVlVFOL
Code and results on rented A100s: https://t.co/NMeTDIKYXx
Every table and figure in the paper regenerates from those JSONs with two scripts. (9/9)
Your agent's KV cache moved to host RAM because it stopped fitting on the GPU.
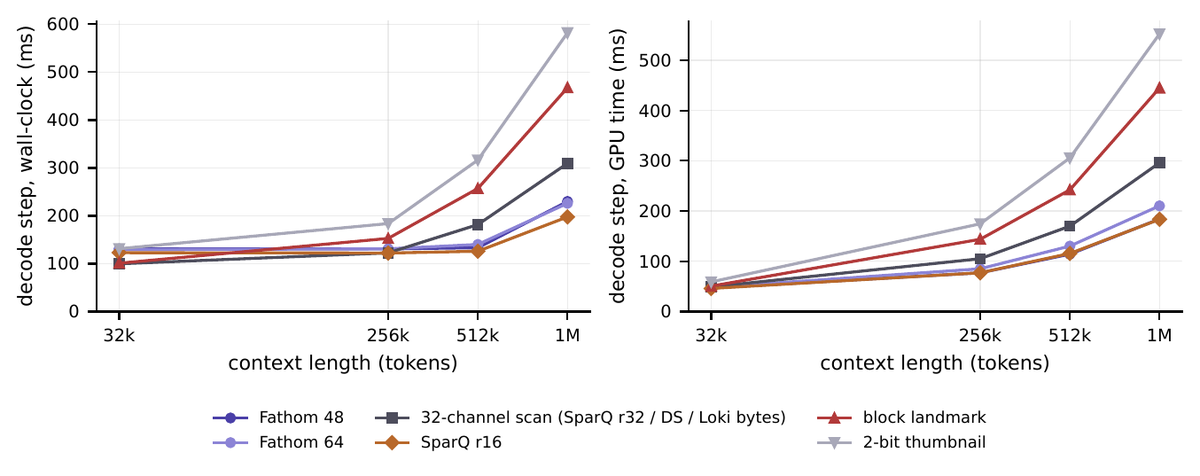
At 1M tokens the index scan that ranks the keys moves 5.1 GB per decode step.
The winner rows everyone optimises move 200 MB.
We were tuning the wrong 4%. (1/9)
That is not an A100 quirk. Counting INT32 lanes against bandwidth, an A100 gives ~5 integer ops per byte and an H100 about the same.
If your index is resident, this buys you nothing. If it is offloaded, bytes are time.
Know which one you are. (8/9)
Qwen3.8-27B ranges from 54.7GB at BF16 down to 9.01GB at 2-bit, a 6.07x compression. The 4-bit UD-Q4_K_XL variant at 17.9GB fits a single 24GB GPU. I walk through this single GPU tradeoff in Chapter 12 of Quantization and Fast Inference - https://t.co/lTWymv7Dej
HALF OFF our new MEAP, only on May 8th!
Today, you can SAVE on Quantization and Fast Inference by Vivek Kalyanarangan @vivk1988 and other related titles: https://t.co/KqPs4V7QTP
From quantization fundamentals to runtime packaging, the book provides a comprehensive overview of the quantization pipeline.
Exploring the Latest Advancements in AI Research: A Deep Dive into Five Groundbreaking Papers https://t.co/lJWiJj0DwX
🚀 Exciting AI Breakthroughs: A Deep Dive into 5 Groundbreaking Papers! 🚀
@ylecun What about a combination of the two? For some of my narrow domain use cases, an architecture based on the two combined have outperformed separate architectures