Today we’ve raised $52M Seed and we are announcing the public launch of S2.1 Pro.
>It can clone a voice from 5 seconds of audio
>2x faster than Cartesia & 1/6th the cost of Eleven Labs
>most expressive model with word level control over emotion, intonation, pacing etc
We support frontier AI companies including HeyGen, LiveKit, Retell, Sanas, and OpenArt all run our model in production.
If you're a business and we can't cut your voice AI costs by 50%, we'll give you 1 year of Fish Audio for free.
Book a demo: https://t.co/vHkyZf9JoG
To celebrate our first birthday, we'll give you 1 month of S2.1 Pro for free. Like, retweet, and comment “Fish” to get it.
🚗 NVIDIA Research named Autonomous Grand Challenge winner for End-to-End Autonomous Driving at #CVPR2025 in Nashville. Theme of challenge: Towards Generalizable Embodied Systems.
Learn more about NVIDIA Research at CVPR: https://t.co/9I9v5zUd1L
💡 New work: You might not need math data to teach models math reasoning.
Recent 🔥 RLVR works challenge the need of *labels* of math questions.
We find just playing video games, eg. Snake, can boost multimodal reasoning. No math *questions* needed.
https://t.co/iAq0MuOgVE🧵👇
Very honored to be part of this effort with Zhiqi Li, David Austin, Mingsheng Fang, @voidrank@jankautz@ALVAREZ_JOSEM
More details👇
https://t.co/P7LaUa2FtN
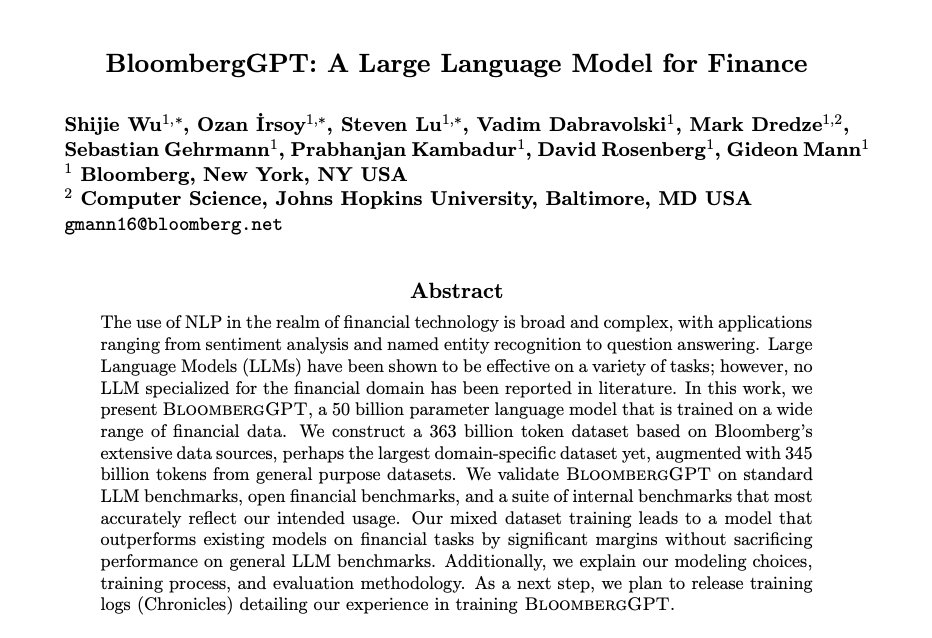
BloombergGPT: A Large Language Model for Finance
a 50 billion parameter language model that is trained on a wide range of financial data. Construct a 363 billion token dataset based on Bloomberg’s extensive data sources, perhaps the largest domain-specific dataset yet, augmented with 345 billion tokens from general purpose datasets
abs: https://t.co/53w2rTN4wB
Come intern with us at @nvidia We collaborate with @ALVAREZ_JOSEM team to build full-stack computer vision and AI models with applications in autonomous driving,e.g https://t.co/0I06HTx4Pi @ZhidingYu@voidrank
Join our AI algorithms team at @nvidia as an intern working on a broad range of topics from generative models, reinforcement learning, neural operators, 3D vision, AI for science, and quantum algorithms. https://t.co/FFsmeP8zmY
Our team won first place in Robust Vision Challenge #ECCV for semantic segmentation. We use FAN -fully attentional networks + Segformer Head. FAN uses channel-wise attention and has zero-shot robustness. @ZhidingYu@voidrank@YuilleAlan@never1andd@nvidia https://t.co/Lbd5Qx1D74
We trained a transformer called VIMA that ingests *multimodal* prompt and outputs controls for a robot arm. A single agent is able to solve visual goal, one-shot imitation from video, novel concept grounding, visual constraint, etc. Strong scaling with model capacity and data!🧵
Still using costly mask labels to train your models? Check our #ICCV paper DiscoBox!
For the first time, box-supervised method is outperforming Mask R-CNN on COCO in both performance and speed.
Paper: https://t.co/hOYEN8vveS
Code: https://t.co/hZ22id1OnK
https://t.co/fd12x42fMN