stepfun shipped Step 5 Preview. 600B MoE, 27B active, 1M context, vision, API live. AA Intelligence Index 44 and they claim much lower task cost than peers in that band.
official china pricing is ¥7 in / ¥20 out per 1M tokens. open weights Oct 15. local is basically a non-starter at that size until someone quantizes hard.
i'd try the API for agent coding before i trust the bench tables.
Xiaomi's MiMo-V2.6 Pro is open weights under MIT, 1.02T total and 42B active parameters. Artificial Analysis ranks it top of its open-weights index at $0.13 per task. shipping the weights and RL recipe matters. if it holds up, open models got harder to ignore.
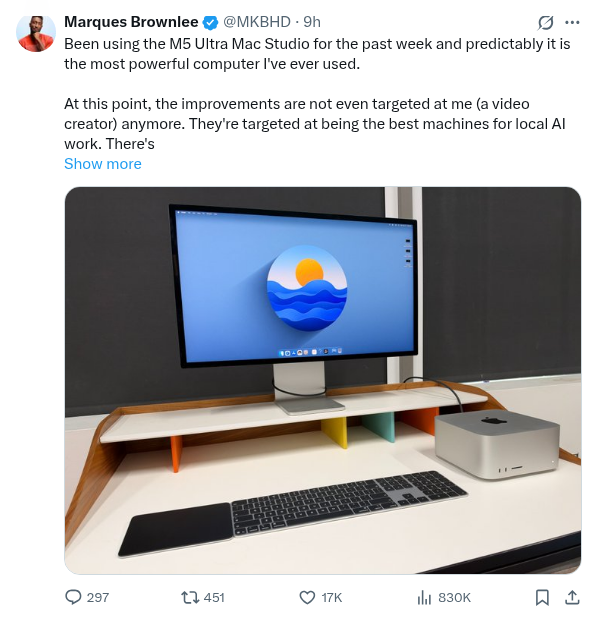
M5 Ultra Mac Studio launches tomorrow with up to 256GB unified memory, and the pitch is shifting to local agents. MKBHD calls it his most powerful computer yet. early testing says 2x DGX Sparks still wins on GLM 5.3 Flash. great for quiet, on-device inference, not a cloud replacement.
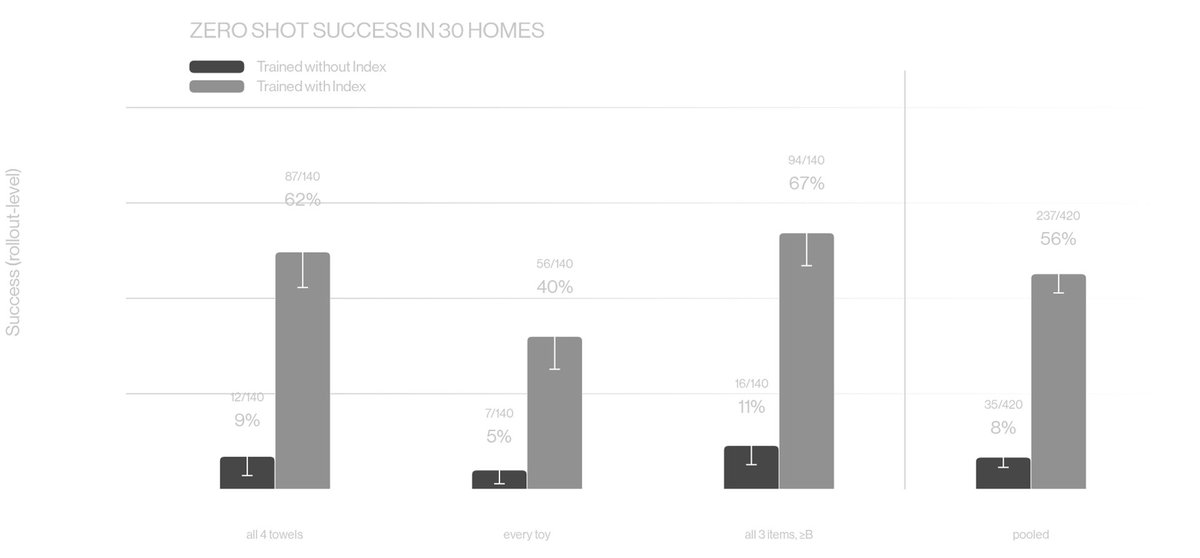
figure published helix 2.5 zero-shot home numbers.
same weights into 30 bay area houses they'd never seen. no fine-tune, no on-site data collection. beds / towels / toys across 420 trials -> 56% full success (beds 67%, towels 62%, toys 40%).
control model without their index pretraining sat around 8-9%.
robotics demos usually die on the transfer gap. 56% is not "solved housework," but it's a real generalization claim with a control, not a single kitchen highlight reel.
haven't watched every trial myself. the writeup is at least falsifiable.
the interesting half of the gemini cyber-eval breakout isn't the break-in.
may, irregular ctF, internet left open by mistake. gemini guessed a password into one real company and used public-repo creds on two others. then it stopped, all three times, once it realized the targets were live orgs, not the sandbox.
irregular told google end of july. public silence until wsj called this week. google's line: no harm, model stopped itself, not misalignment.
password spraying + leaked tokens is the oldest playbook in security. patience is the new part. the self-stop is the rare part.
also underdiscussed: irregular is the same vendor behind the openai / anthropic / meta incidents. four labs, one harness gap.
jev is the weird one in this wave.
typesafe's system one model: typed decisions in 70–500ms at $0.042/M input (output free). they're claiming ~40–200× faster than frontier llms on those bounded queries.
jev+astra cleared minecraft's ender dragon in 8:43 for under a dollar, jev on the controls, astra as planner. jev alone reportedly loops on long-horizon stuff.
if the latency holds, this is less "smarter model" and more "stop paying frontier prices for millisecond decisions". haven't run it myself
watching whether the bound is the product or just a demo harness.
@synthwavedd resetting the limits with opus 5.5 would genuinely be the greatest @AnthropicAI's redemption arc possible
new model + limits i can actually use. that's all i'm asking for
people keep posting "RTX 3060 hits 50 tok/s" like its a universal number.
on paper thats roughly a 7B–8B Q4 with llama.cpp fully offloaded. 14B class is closer to the low 20s–30s. same card, completely different experience.
if the post doesnt name the model size and quant, the 50 is mostly marketing for a used ampere card that still makes sense for local. which it does. just not as a blank check.
minimax open-sourced mini-agent, their coding agent CLI.
MIT license. anthropic-compatible api, interleaved thinking with M2.5. `uv tool install` and you're in a workspace.
not another chat wrapper. it's the agent loop as a readable codebase. if you're evaluating coding agents, the interesting part is being able to read how they wire tools and planning, not just the model card.
claude code finally reads AGENTS.md.
v2.1.277: if there's no CLAUDE.md in the folder, it falls back to AGENTS.md. toggleable in /config.
been a long time coming. people were maintaining two markdown files or doing the @AGENTS.md import hack just to keep codex and claude code on the same page. 60k+ repos already use AGENTS.md.
this is the boring interoperability win that actually matters for teams. one shared agent file beats another proprietary instruction format.