Numerical features come in different forms and sizes, and by default, these figures can be normal when used in a realistic way, i.e., the differences in earnings, age, height, etc. These are normal instances, but systems do not understand what “real-world” means. To humans, there
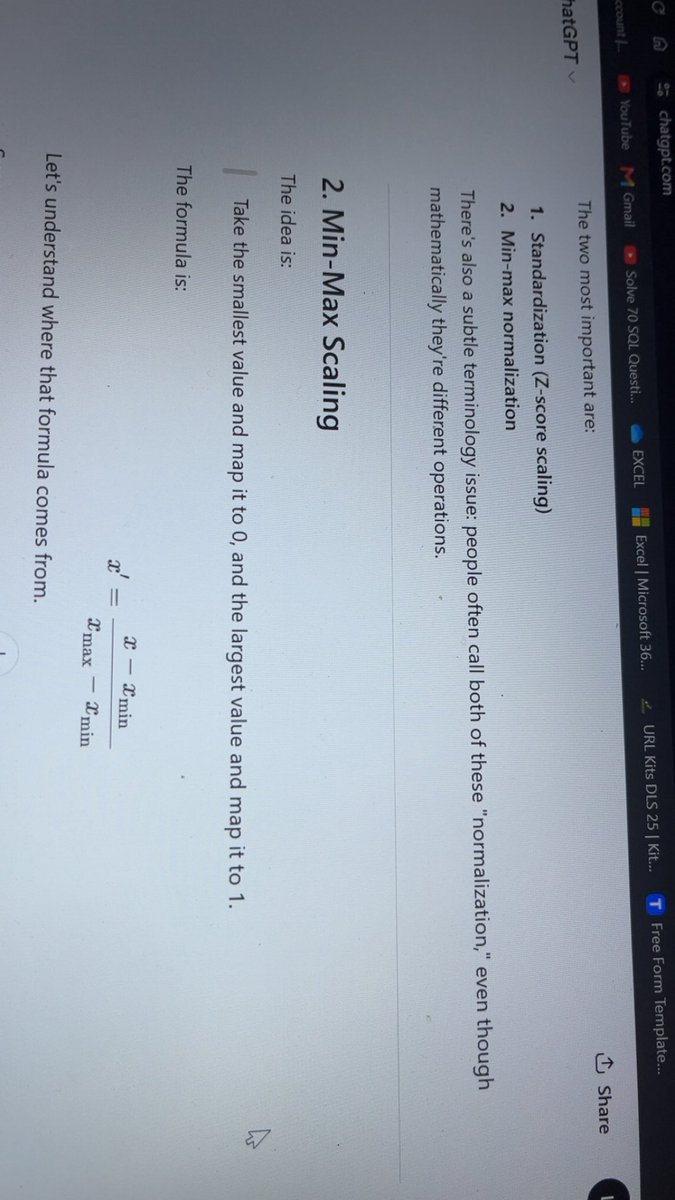
used in ML to make numerical features comparable to one another. Standardization transforms the data so that the feature has a mean of 0 and a standard deviation of 1, while normalization rescales the values in a feature to a specified range, commonly between 0 and 1.
column tend to be much higher than those in the other tcolumns, the difference in scale can cause salary to have a stronger influence on the model. This can lead to biased or inaccurate predictions.
Today, I learned about standardization and normalization. Both are techniques
and possibly make predictions from it just as humans do. Now, there is a drawback: some ML algorithms can give disproportionate importance to features with larger numerical scales. The columns (age, height, salary) point to the same individual, but since the values in the salary
is sense in it; of course, you earn more if you have more experience and certifications. Grouping all of these into different fields/columns is still normal since it can easily be interpreted by a human.
Our focus is to teach/train systems how to interpret this same information
@vheeorji22 Did someone just said she’ll investigate? That’s a clear outlier, compare it to real world instances, it’s definitely UNUSUAL, best solution is to drop it… for ml, you’ll regret not dropping it 😂