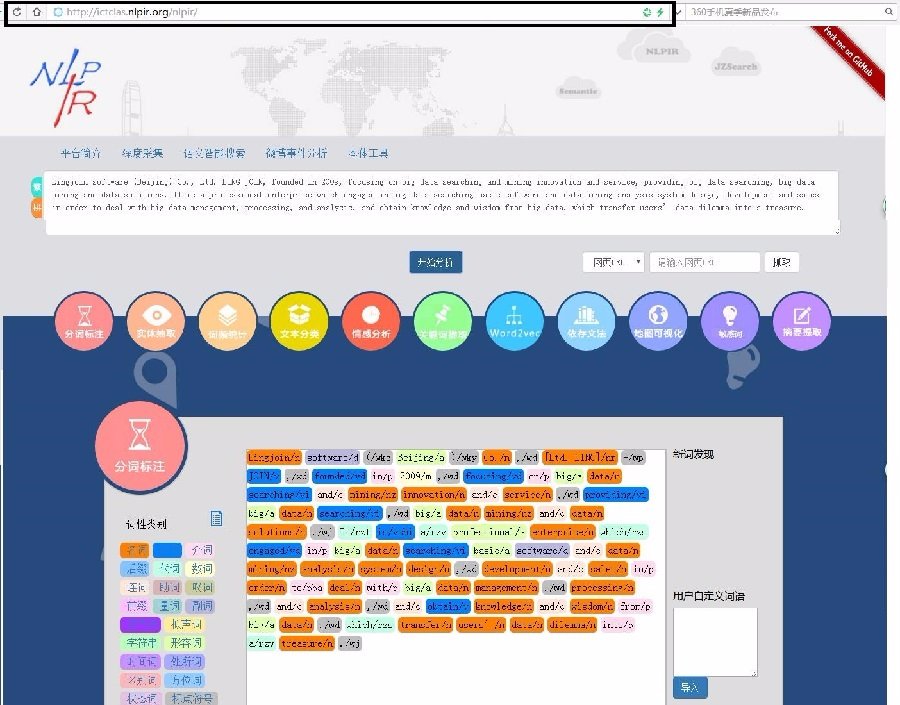
Lab. of NLPIR Big Data Search and Mining in Beijing Institute of Technology(BDSM@BIT)(BDSM@BIT) aims to be the world-class innovation research and technology team in big data intelligence, especially with Chinese language.
Lab. of NLPIR Big Data Search and Mining in Beijing Institute of Technology(BDSM@BIT)(BDSM@BIT) aims to be the world-class innovation research and technology team in big data intelligence, especially with Chinese language.
search, etc. NLPIR platform provides various usage ways including Windows client application, NLPIR cloud services as SaaS, and SDK for further development using popular programming language, such as C/C++, Java and Python. During the past 20 years.
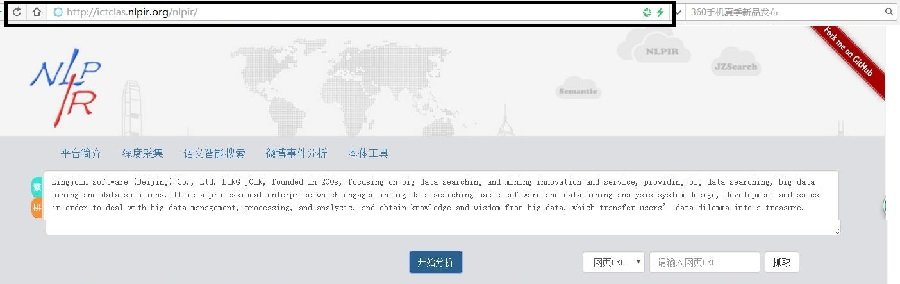
#NLP#NLProc https://t.co/Pukv4wndDU NLPIR Big Data Semantic Intelligent Analysis Platform is a total solution to tackle big data knowledge management problem. It includes four main modules: precise crawling from deep web, natural language understanding, text mining, and web
search engines, text summarization, sentiment analysis etc. Most approaches use parallel data of noisy and correct word mappings from different sources as training data for automatic spelling correction.
#nlpoli#NLP https://t.co/Pukv4wndDU Automatic Spelling Correction for Resource-Scarce Languages using Deep Learning:Spelling correction is a well-known task in Natural Language Processing (NLP). Automatic spelling correction is important for many NLP applications like web
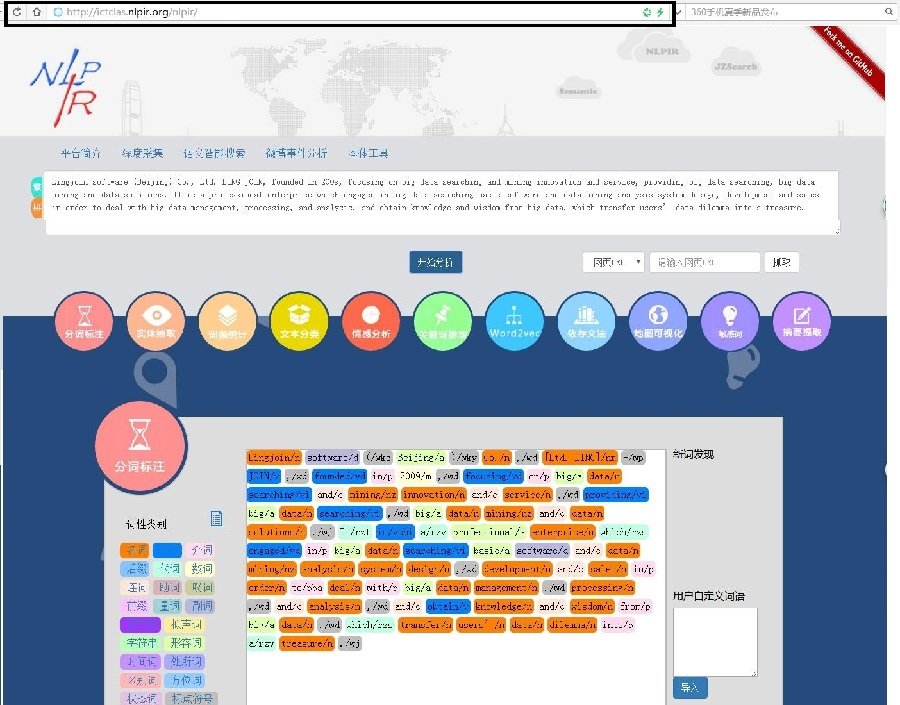
The NLPIR system, a multi-functional Chinese Lexical Analysis System, combines the natural language processing, text mining and Internet search technique to program the Internet content based on the requirements of data processing.
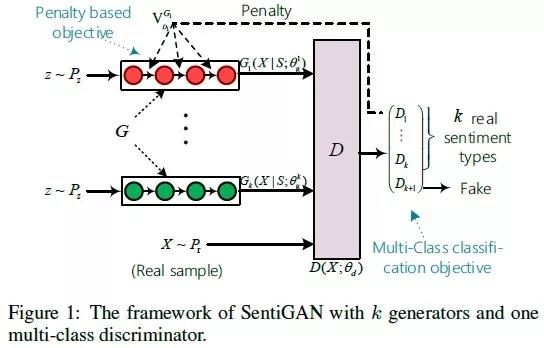
#NLP#NLProc https://t.co/7O0GzrTp0v: Generating Sentimental Texts via Mixture Adversarial Networks
Generating texts of different sentiment labels is getting more and more attention in the area of natural language generation.
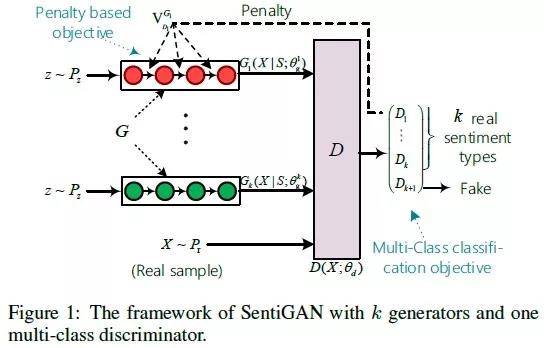
#NLP#NLProc https://t.co/Pukv4wndDU SentiGAN: Generating Sentimental Texts via Mixture Adversarial Networks
Generating texts of different sentiment labels is getting more and more attention in the area of natural language generation.
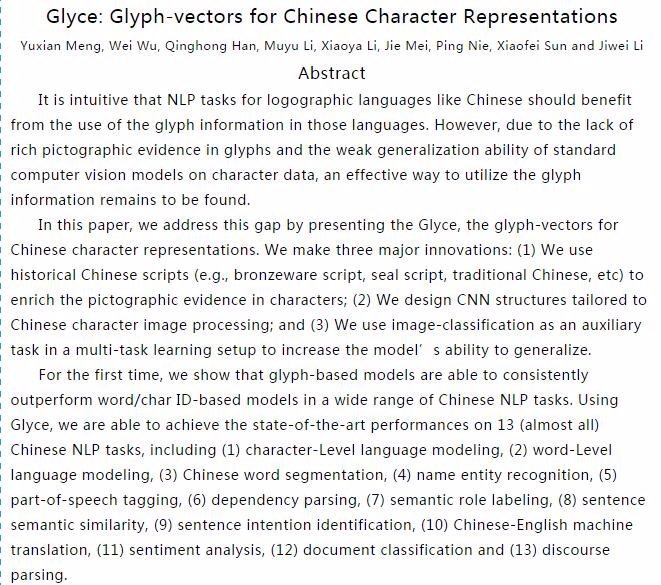
#NLP#NLProc https://t.co/Pukv4wndDU lyce: Glyph-vectors for Chinese Character Representations
It is intuitive that NLP tasks for logographic languages like Chinese should benefit from the use of the glyph information in those languages.
Professor Zhang Huaping and Deputy General Manager of RSN Lee Young Soo attended the signing ceremony to promote in-depth application of Chinese big data semantic intelligence analysis in Korea.
#NLP#NLProc https://t.co/Pukv4wndDU NLPIR Big Data Lab. of BIT Signed Cooperation Contract with Korea RSN Inc:
On the morning of April 9, 2019, NLPIR Big Data Lab held a cooperation signing ceremony with South Korea’s RSN Corporation (Restructure Social Network). Associate
#NLProc#NLP https://t.co/Pukv4wndDU NLPIR Big Data Search and Mining:Self-attention is a useful mechanism to build generative models for language and images. It determines the importance of context elements by comparing each element to the current time step.
#NLP#NLProc https://t.co/Pukv4wndDU End-to-end Sequence Labeling via Bi-directional LSTM-CNNs-CRF:State-of-the-art sequence labeling systems traditionally require large amounts of task-specific knowledge in the form of handcrafted features and data pre-processing.
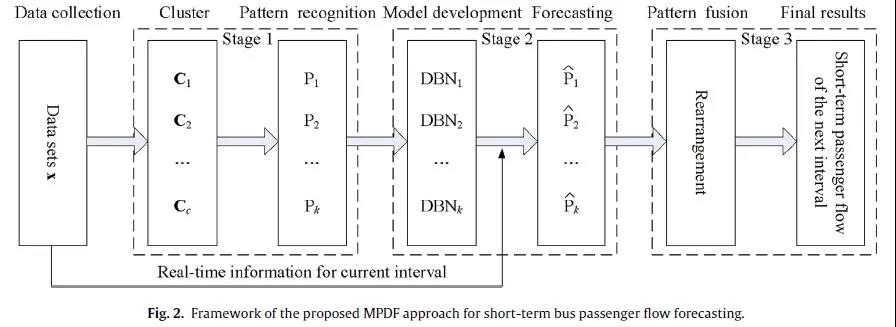
#NLP#nlpoli A multi-pattern deep fusion model for short-term bus passenger flow:For forecasting bus passenger flow, this paper proposes a multi-pattern deep fusion (MPDF) approach that is constructed by fusing deep belief networks(DBNs) corresponding to multiple patterns.
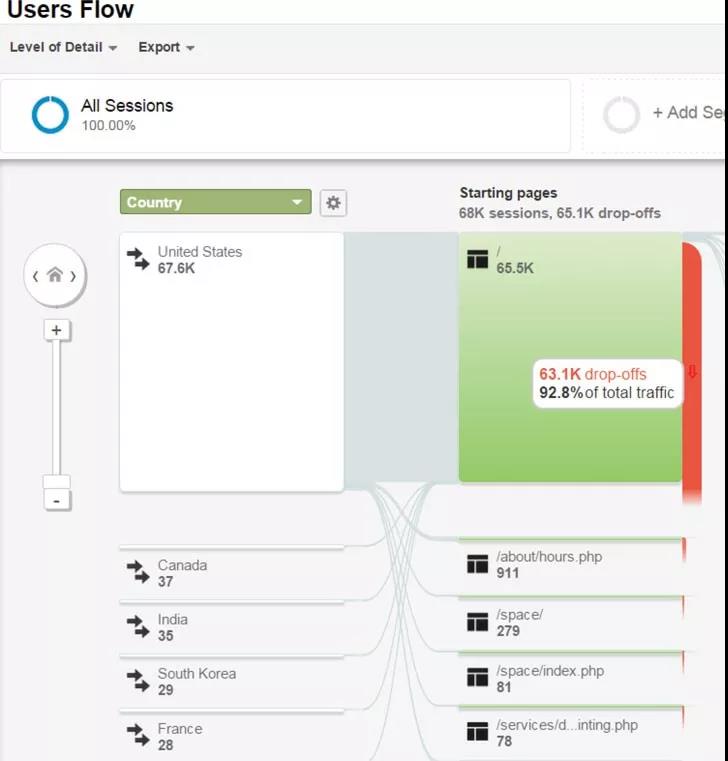
#NLP#NLProc https://t.co/Pukv4wndDU Tracking User Behavior with Google Analytics Events on an Academic LibraryWeb Site:At Albertsons Library, the goal of the navigational design of the Web site is to mimic user behavior on the Web site to help them access information and
#nlp https://t.co/Pukv4wndDU spam-posting:Online Social Media platforms, such as Facebook and Twitter, enable all users, independently of their characteristics, to freely generate and consume huge amounts of data.
#nlproc#NLP https://t.co/Pukv4wndDU Due to an enormous number of scientific publications that cannot be handled manually, there is a rising interest in text-mining techniques for automated information extraction, especially in the biomedical field.