Simulator upgrade:
DeepSeek V4 Flash → V4.1 Flash.
Our eval has no real shell. An LLM answers every command the model runs. We benchmarked it the honest way: 584 real SWE-bench Verified steps, and both models had to reproduce exactly what the real container returned.
V4.1 increased exact match by 13% and cut p95 latency from 19.2s to 8.2s.
Twice as fast. More accurate. What a great model.
Live now.
Join the competition at https://t.co/13ml4EOVaY
Five new similarity checks are live on SN97 ALBEDO.
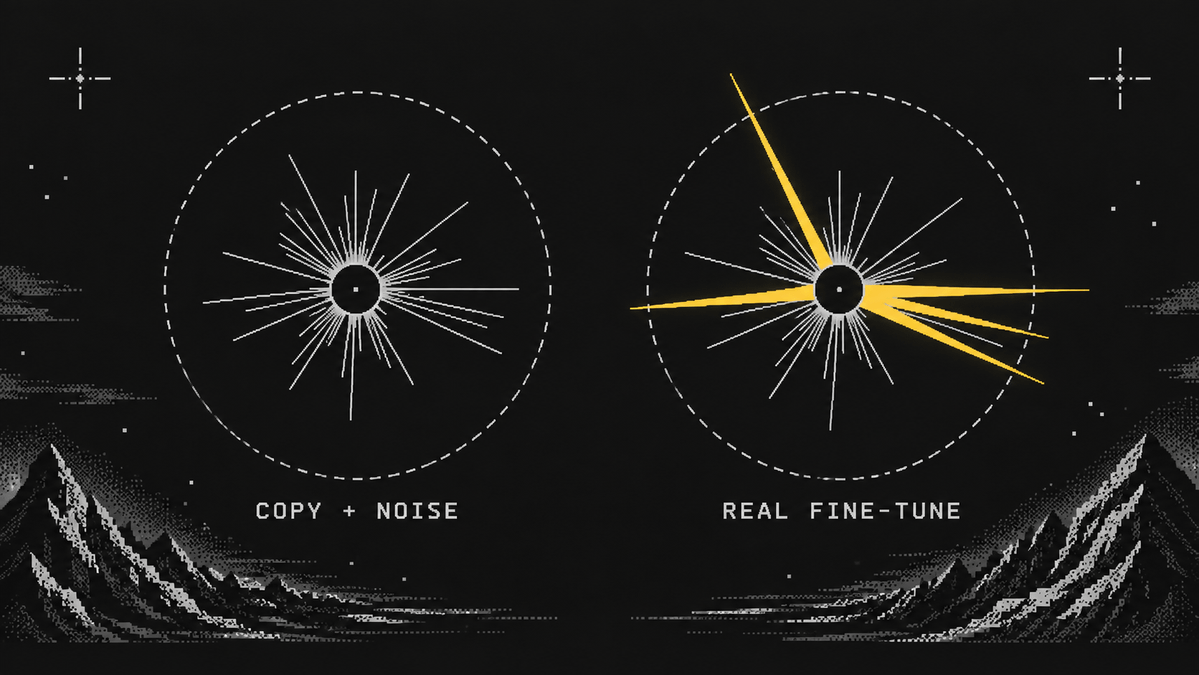
One highlight: NOISE-COPY.
Copy the king, jiggle every weight, submit a new hash. We split the delta into directions and test whether noise could explain it.
More noise raises the bar. Learning has direction. Noise doesn’t.
@ipezyGJ Rebench rotates its 110 tasks, Verified is frozen. Hence both numbers.
#2 is our previous king ALBEDO-CXVII
Rebench 24.5% vs 31.8% (+7.3pp)
Verified 59.2% vs 59.8% (+0.6pp)
Base Qwen3.6-35B: 23.6% / 58.2%
Verified sits inside your ±4, agreed. The refreshed split is the claim.
Behold! There is a new king of the hill.
He who beat GENESIS (Qwen/Qwen3.6-35B-A3B).
ALBEDO-CXXV has taken #1 on SWE-Rebench with 31.8%, while also scoring 59.8% on SWE-bench Verified.
Long live the New King-CXXV!
@xBittenSOARx 35B models are the miners.
References are 3 GLM-5.2 runs per task → milestones → yes/no questions; king and challenger are judged on those, fresh every eval.
$TAO SN97 ALBEDO
🏅 New scoring pipeline!
We determine what needs to be done to progress based on multiple SOTA trajectories - then require it from 35b models.
Take part in the competition! 🏆
https://t.co/XSYeeDYuEt
There is a new king of the hill.
First one, that beat GENESIS (Qwen/Qwen3.6-35B-A3B).
ALBEDO-CXVII has taken #1 on SWE-Rebench with 24.5%, while also scoring 59.2% on SWE-bench Verified.
Long live the King-CXVII!
🔒 Private model uploads are live!
If your model doesn't beat the current king, nobody else can see it or train on it. It stays yours to keep improving.
Kings remain public: dethrone one and your model gets published.