@lydiahallie Wish I saw this sooner. Thx for trying to warn us. With no time listed, we thought we had all day, and wanted to get the most out of it. Checked around 3pm and was shocked. At 88% now, and using codex as much as I can until it resets.
Three files:
plugin.json, the manifest
hooks.json, wires the hook
register.tsx, the turn.complete hook (under 100 lines)
One env var in ~/.claude/settings.json covers every VS Code tab:
CLAUDE_CODE_PLUGIN_DIRS=/path/to/turn-timestamp
Needs 2.1.286+, mods are early access.
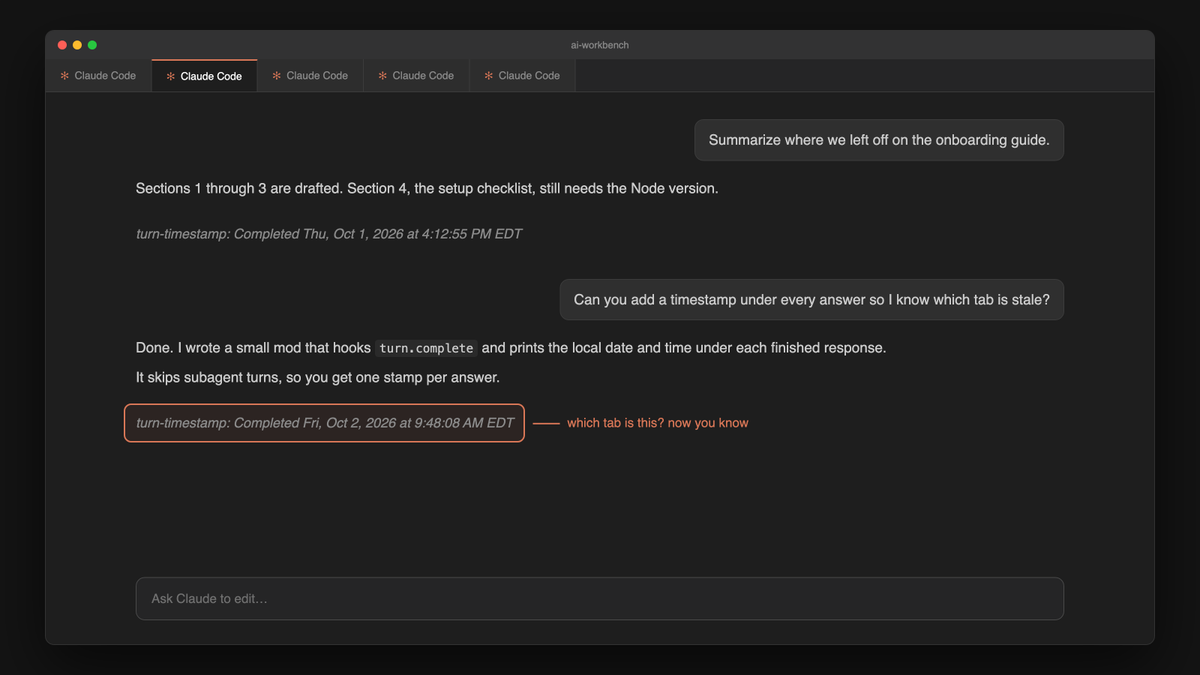
I run Claude Code in a bunch of VS Code tabs. Click into one and I can't tell if that answer landed five minutes ago or five days ago.
So I asked Claude to fix it. It wrote a mod in one turn that stamps the time under every finished answer.
https://t.co/lRMpvUK0U7
Install: hand the guide to your agent in one line. It asks which runtime you use, takes inventory, proposes a numbered plan, backs everything up, and installs only what you approve.
Or run /tune-my-harness in any project.
https://t.co/K10zGy5aL1
New this update:
• Sonnet 5.5 and GPT-6.1 Sol: near-Astra coding at 1/5 the price
• Implementer effort lowered to medium.
•. Reviewer stays at xhigh, because depth pays off in review.
• Rules install machine-wide, so every project gets them.
Cross-vendor review (Claude builds, Codex reviews, or the reverse) is a per-change-class switch, not a habit. It roughly doubles spend, so you turn it on where it earns it.
Cost levers:
• Effort before tier. Turn reasoning down on a capable model before dropping to a smaller one.
• Measure cost per finished task, not per request.
• GPT-6 Luna is 10x cheaper than Haiku. Bulk grunt work goes there.
Rule 3 already paid for itself.
A Sonnet reviewer flagged a dead code branch that two green test suites missed. The implementer had mocked an unreachable path into passing tests.
The frontier model re-checked it. Confirmed.
Green tests aren't proof.
Cheap models need guardrails. Three rules:
1. No self-certification. Cheap work isn't done until tests pass or a frontier model signs off.
2. Auth, payments, deletes, anything irreversible: frontier tier, any size.
3. Every review finding is labeled CONFIRMED or PLAUSIBLE.
Your most expensive model shouldn't be typing.
I built an open routing layer for Claude Code and Codex around one rule:
The frontier model is the manager, not the typist.
It plans, judges, and verifies. Cheap models do the mechanical work.
Free, one-file install 🧵
The team: 5 roles with pinned models, identical in Claude Code and Codex.
Fetcher: Haiku 4.5 / GPT-6 Luna
Summarizer: Haiku 4.5 / GPT-6 Luna
Implementer: Sonnet 5.5 / GPT-6.1 Sol
QA reviewer: same tier, xhigh effort
Architect: Fable 5.1 / GPT-6 Astra
The core idea: route by what failure costs, not by what the task is called.
A "PR review" of an auth change gets the top model. A "PR review" of a typo fix does not.
Same task name. Very different stakes.
Install, for anyone who wants to try it:
/plugin marketplace add JDWorkdog/claude-plugins
/plugin install repo@workdog-plugins
Then /repo:analysis /path/to/your-repo to start.
Needs a terminal session, since /plugin cannot draw its picker inside the desktop app or a VS Code tab. There is a settings.json route in the README if you never leave the IDE.
https://t.co/S0DIyzC0uT
@gregisenberg and @aiwithremy just put out a whole episode about agent skills and how to share them. I watched it two days ago. Then I went and published mine.
First plugin I have ever shipped. Also the least new thing I own.
It is seven /repo commands that have been sitting in my personal workbench since the day I started it. Point Claude Code at any repository and it writes the documentation for you: functional overview, tech stack, feature by feature deep dive, code quality review, technical reference, architecture review. One command runs four of those in parallel. Another one maps several repos at once and shows how they fit together as a single platform.
I use these constantly. Nobody else ever has. Which means every rough edge in there is a rough edge I stopped noticing a long time ago.
So that is the actual ask. Install it, point it at your ugliest repo, and tell me where it falls apart. I would rather hear that it is broken than hear nothing at all.
Episode that pushed me to hit publish: https://t.co/grxwUG4BlH
Example: a developer runs /usage and sees their filesystem MCP server is eating 40% of their budget. Not the code generation. Not the reasoning. A tool that reads files.
Fix: scope it down. Point it at one directory instead of the whole project. Or check if it's being called more than you intended — sometimes the agent is re-reading context it already has.
Run /usage before you upgrade your plan. You might just need to trim one connection.
If you're on a Claude Code plan and burning through your limits faster than expected, run /usage.
Most people have never touched this command. It tells you exactly where your tokens and budget are going.
It breaks your usage down by:
Skill — the built-in capabilities Claude is using
Subagent — any agents it spun up to handle subtasks
Plugin — extensions you've added
MCP server — external tools connected via the Model Context Protocol
That last one is where surprises usually hide. An MCP server can be chatty in ways you never notice until you look.
One more thing: background sessions can go idle if you leave them too long.
Pin them to keep them alive. Most terminals and Claude Code setups let you pin or mark a session so it doesn't get cleaned up while you're focused elsewhere.
Next time you have more than one session open, pull up the agents view before you do anything else. Seriously. It changes how you work.
If you're running more than one Claude Code session, you're probably flying blind.
You forget which tab is stuck waiting for you. You lose track of what's still running. You close something that was almost done.
There's a built-in view that fixes this. Most people never open it.
When a session stalls, use /resume to pick it back up.
Find the blocked session in the agents view. Jump in. Type /resume and Claude picks up exactly where it stopped.
No re-explaining context. No starting over. Just continue.
That's the combo that makes parallel sessions actually manageable.