We started to post videos for CMU 11-768, AI Agents!
All of the videos will be posted to this playlist, so please bookmark/follow it if you want to be notified of new ones! I'll also try to post them on this thread too.
https://t.co/HAJgKXve0x
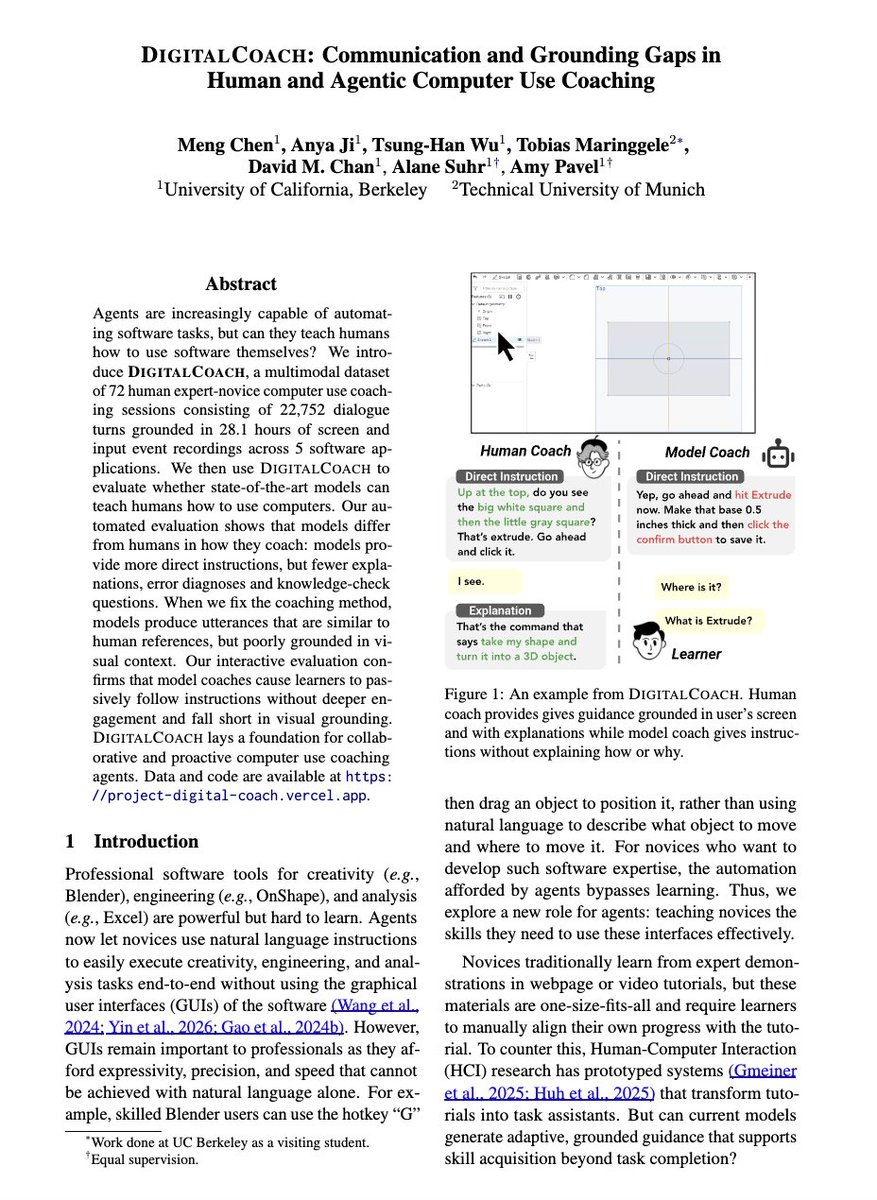
Excited to share that our paper 𝐃𝐢𝐠𝐢𝐭𝐚𝐥𝐂𝐨𝐚𝐜𝐡 was accepted to the #EMNLP2026 𝐌𝐚𝐢𝐧! 🎉
Agents are getting better at automating software tasks. But can they teach us how to use software ourselves?
We studied real expert–novice coaching interactions: 🧵
Today, we're open sourcing the first computer-use dataset for design.
We captured 200+ hours and 3400+ trajectories of real design work in Figma, recording step by step how designers execute complex, long-horizon tasks.
FigmaTrace dataset, paper, and blog below :)
@PatronusAI
We are excited to announce the launch of the Adobe India AI Research Fellowship program this year. Applications are open for the Adobe India AI Research Fellowship! More details: https://t.co/484bfqH3Id @AdobeResearch#PhDFellowship#AdobeIndia
Rosiana Natalie @rnatalie15 is presenting "A11y-CUA Dataset: Characterizing the Accessibility Gap in Computer Use Agents", authored by @xananyagm*, Rosiana Natalie*, Brandon Kim, Anhong Guo*, @amypavel*. https://t.co/N6pBqkthLK
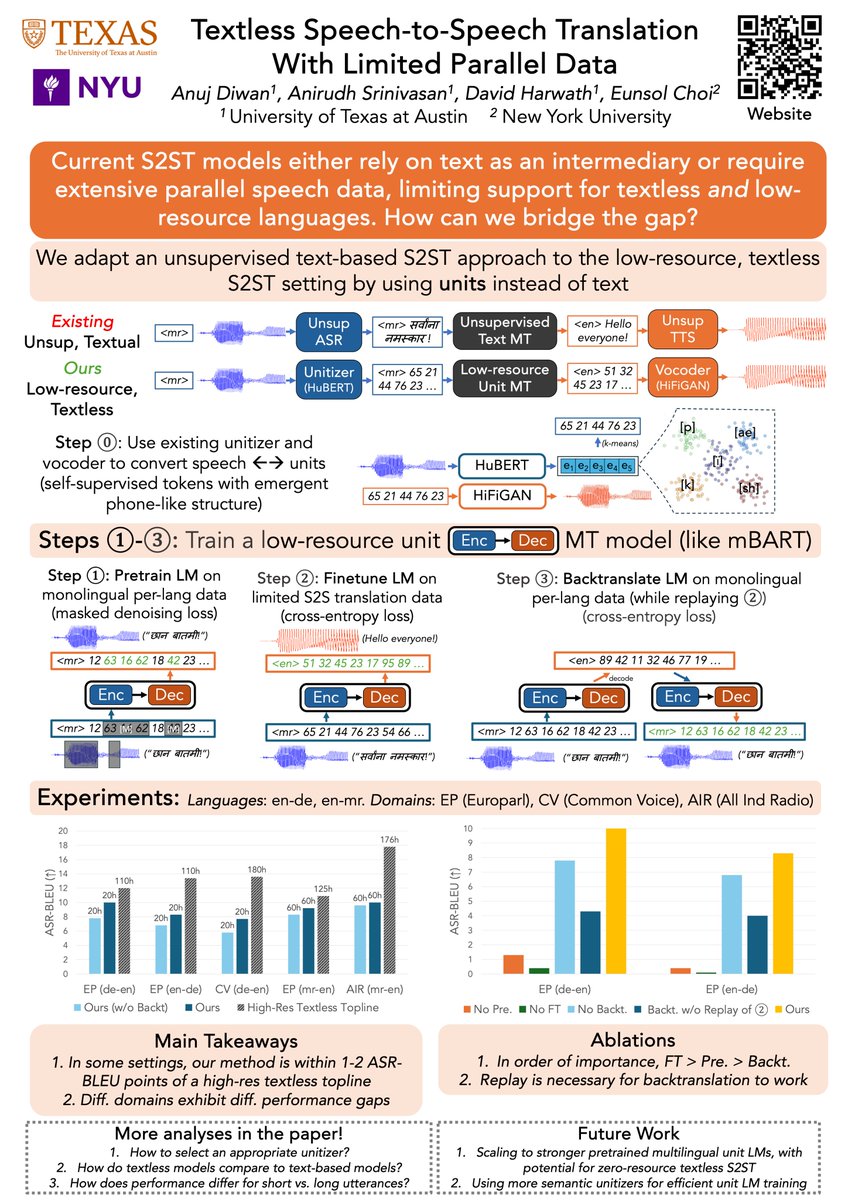
I'll be at #EMNLP2024 in Miami 🏖️ to present our work on textless speech translation!
🗓️ Wed, Nov 13, 10:30-12:00, Poster Session D
If you're attending, let's catch up and chat about speech LMs, controllability, multilinguality and more!
Updated 📜: https://t.co/W1MEeaEJrB
Exploring St. John’s for #ASSETS2024 and can confirm: stunning views, colorful houses, and lots of hills! Not sure if I came for the conference or the cardio 😂
Excited to be in St. John's for my first @sigaccess#assets2024! Tomorrow, I’ll be presenting my paper on Context-Aware Image Descriptions. Come by to see how using context can make image descriptions better for BLV users! @amypavel
https://t.co/XDqvVY8ZRe
Our system provides context-aware image descriptions that use correct visual terminology and focus on the relevant subject by extracting details from the image and its source.
@amypavel
New vision-to-language models can provide detailed image descriptions on-demand but are context-free. How can we make them context-aware? Check out our #ASSETS2024 paper: “Context-Aware Image Descriptions for Web Accessibility”
🔗https://t.co/tp9SkQoeGP
📄https://t.co/UYniRh7AI6