A futuristic framework where agents work together using a shared, branchable Git repository as persistent memory. Will it be the next engine for auto research and science discovery? Check out this inspiring work ⬇️
Long-horizon research is built on failed experiments, partial breakthroughs, and old ideas worth revisiting.
But inference is disposable. Can we build an inference substrate where work compounds across attempts?
Introducing GitSwarm: Decentralized Compounding Inference ��
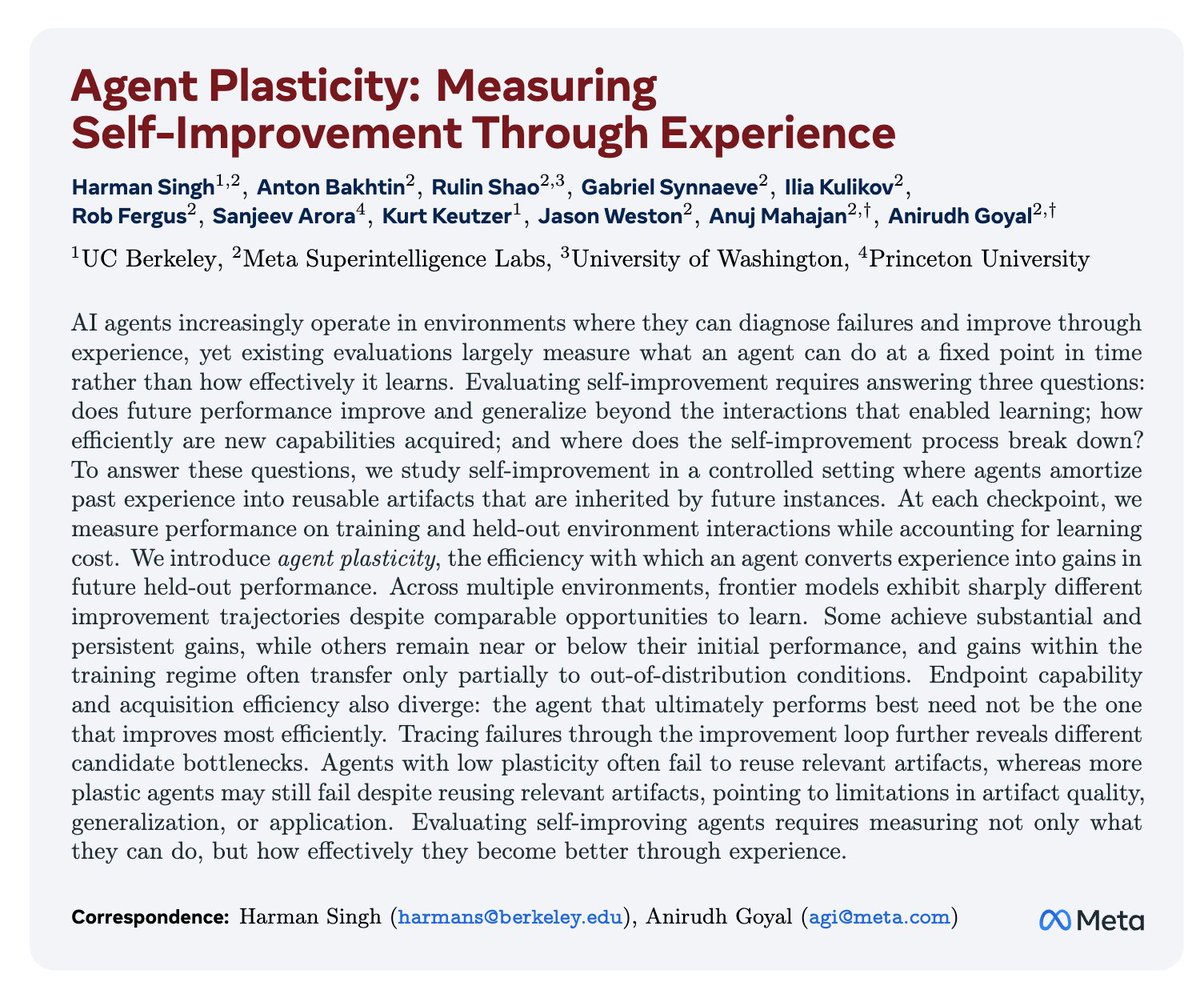
How can we measure an AI agent's ability to self-improve over time? Agent plasticity introduces the framework that makes agents create and reuse tools, skills, and memories, and measures how effectively these experiences bring performance improvement. Check out this work ⬇️
How do we measure an AI agent's ability to learn, rather than just its current capability?
We study agents that learn from experience without updating their weights, and measure how efficiently they improve on unseen tasks.
Surprisingly, the strongest agent isn't the most efficient learner. 🧵
How do we measure an AI agent's ability to learn, rather than just its current capability?
We study agents that learn from experience without updating their weights, and measure how efficiently they improve on unseen tasks.
Surprisingly, the strongest agent isn't the most efficient learner. 🧵
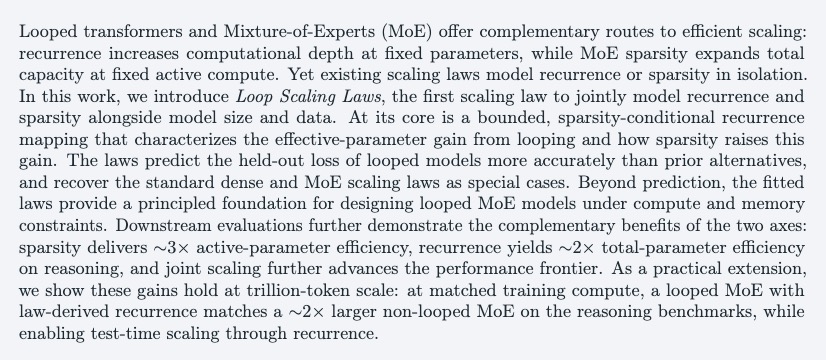
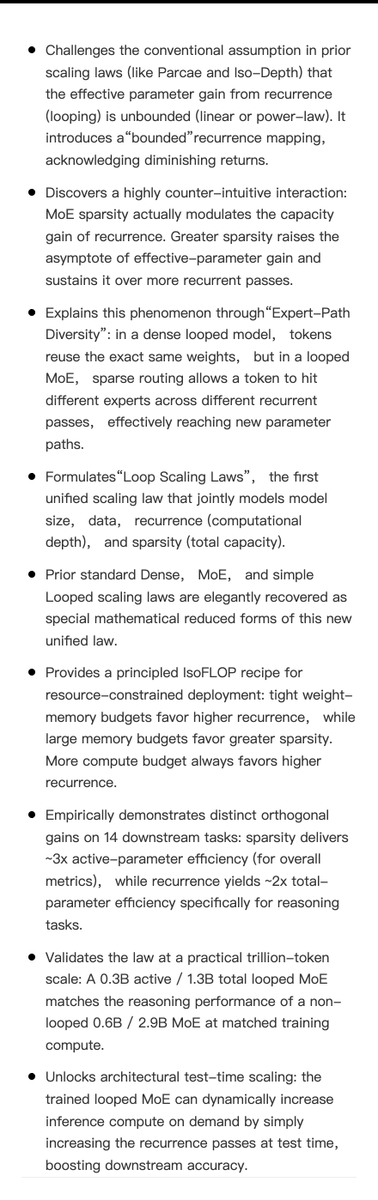
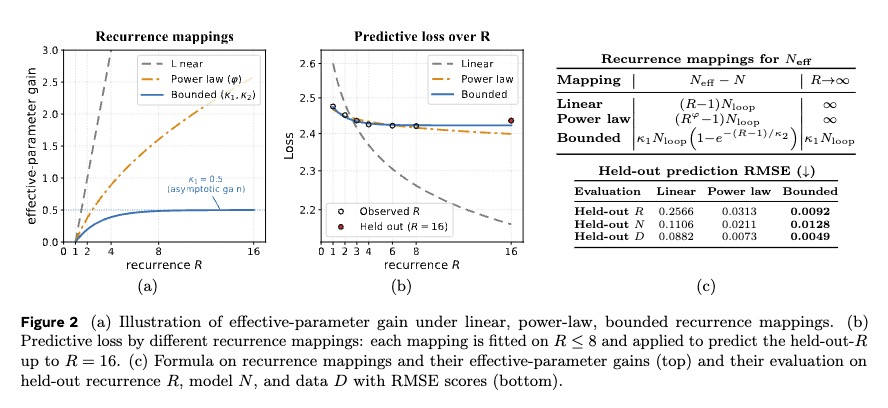
Frontier models like GPT-6 are reportedly using looping. But here're the million-dollar questions on scaling: 🤔 Can adding more loops deliver gains indefinitely? And what happens when looping meets Mixture-of-Experts?
Check out our latest Loop Scaling Laws answering these! 👇
Best possible model quality under fixed training compute, memory, and enable test time scaling under varying recurrence ?
We systematically study how model size, data, sparsity, and recurrent depth interact.
Loop Scaling Laws predict the frontier: how much effective capacity looping adds, when it saturates, and how MoE sparsity raises that ceiling.
Work by @yanbei_c (follow her!)
https://t.co/pX3QQCKeWL
@anirudhg9119 5/ At matched training compute, we find looped MoE (0.3B-active/1.3B-total) with law-derived recurrence can reach the reasoning performance of a ~2× larger non-looped MoE (0.6B-active/2.9B-total), while unlocking test-time scaling by varying recurrence during inference.
We just released MobileMoE, first sub-B-active-parameter MoE language model family.
MoE isn't just for 100B+ parameter models on servers. At sub-B scale, sparse expert routing lets you match dense models at 2-4x fewer FLOPs while fitting in mobile DRAM.
https://t.co/ZvwJBVs778
🚀 Excited to share our new work "MobileMoE: Scaling On-Device Mixture of Experts".
Think Mixture-of-Experts only pays off at trillion-parameter, cloud scale? We show the opposite — and release the blueprint for designing MoE that runs natively on the phone in your pocket. 📱
Meet #AmazonNova Multimodal Embeddings 🚀✍️🎯
Power your AI agents & applications with the industry's first unified embedding model that supports text, images, documents, video & audio in a single model. #AWS
👉 https://t.co/911KK9REkp
Honored to be giving a talk on Multimodal Agentic Models at 3:30pm, East meeting room 13 in the 1st Workshop on Video-language Models at #NeurIPS2024. Stop by if you are interested in this topic! I can assure you will learn something new!
📢Come to join our 1st Workshop on Video-Langauge Models at #NeurIPS 2024.
We have seen a great progress on image-language models, now it is time for Videos! Our invited speakers will talk more about how we further move forward!
https://t.co/msS1SXxuS5
Special invited talks from:
@dimadamen, @yong_jae_lee, @jw2yang4ai, @gberta227, @imisra_, and @doyup_lee
We're thrilled to announce the _Workshop on Video-Language Models_ at #NeurIPS2024! Join us, along with leading researchers and industry experts.
Date & Location: December 14, East Meeting Room 13 Website: https://t.co/3HKQIdIBZo
(1/10) 🔥Thrilled to introduce OneDiffusion—our latest work in unified diffusion modeling! 🚀
This model bridges the gap between image synthesis and understanding, excelling in a wide range of tasks: T2I, conditional generation, image understanding, identity preservation, multiview generation, and even camera pose estimation. Learn more at:
Project: https://t.co/bHjZOd5Tgv
arXiv: https://t.co/9cKSN1zItC
Code (on the way): https://t.co/gER8LqI5Pr
It takes a great team to build strong models, but it takes an exceptional team to build state-of-the-art models. I'm incredibly proud of what we've achieved as a team in bringing Nova models to our customers. To many more models to come 🍾 #nova#Amazon
https://t.co/p46aBO3YPj