19 latency patterns for faster applications
The model is only one segment of the critical path. The rest of the system still has distance, repeated work, serial waits, and cold setup.
A practical map for reducing non-model latency:
https://t.co/bTXW6yXd5L
20 hours later and I’m done!
Qwen 3.8 27B @ 73 TPS (peak) on a Macbook pro M5 max.
MTPLX V2.7 out now with 3 new models.
- Bare Speed: short burst decode, good for chat.
- Optimized Speed: higher quality and faster on long coding.
- Optimized Quality: 30% slower but super!
Introducing Stagehand v4: the SDK for browser agents.
Playwright was built for testing, we built Stagehand for your agent: with improved context management, self-healing actions, and iframe support.
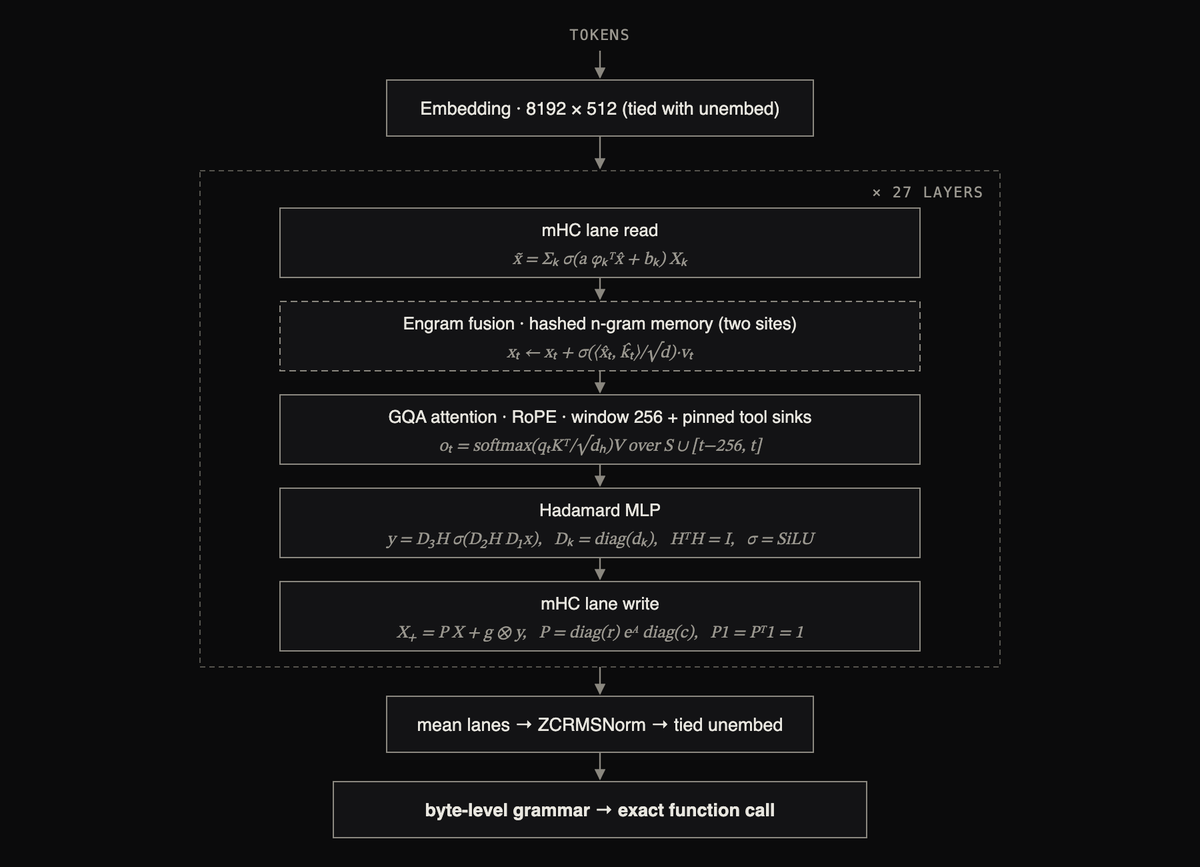
We release Needle 2: A 14MB agentic LLM for phones, wearables, smart home, robots and microcontroller. The whole model is a single 14MB binary that runs a full session in 28MB of RAM. It is built on our Simple Attention Network findings, compressed to CQ2-bit with Cactus Quants, and baked into its own engine.
Needle 2 has 45m parameters trained from the ground up on 140B tool call, device use structured generation tokens. On mobile device use benchmarks, Needle 2 trades wins with frontier small LLMs like LFM2.5 230M, Apple FM Gemma-270m, at 5× to 70× smaller, and 2 bits against their f16.
Needle hits 500 tokens/sec decode speed on a Raspberry Pi 5, between 400–1,500 tokens/sec on VR devices like Meta Quest 3S and Apple Vision Pro, and ranges 300–700 on sub-$200 phones such as the Samsung A-Series. Needle also runs on newer microcontrollers like ESP32.
A conventional transformer of Needle's width and depth spends 164 MFLOPs per token, and even one squeezed down to Needle's parameter count spends 87, Needle spends 70. Even on a high-end phone, an always-on assistant lives inside a power budget; every MFLOP is milliwatt-hours, and Needle spends 7x to 85x fewer of them per token than the smallest performant LLMs.
Read more: https://t.co/dLK2tIKXQu
Quarkus Multitenancy Without Tenant Plumbing in Every Service
What the Quarkiverse Multitenancy extension gives you: one resolution point, clean domain code, and three tested resolution modes for database-per-tenant isolation.
https://t.co/TsOb6aCgSZ
#java#quarkus
oMLX 0.4.4rc2 is out with early MiniMax M3 support, made possible by the awesome mlx-vlm work from @Prince_Canuma and @ivanfioravanti, tracking the upstream mlx-vlm PR. Stable 0.4.4 is planned after a short final RC test pass!
MiniMax M3 is supported with oMLX features including SSD cache, prefix cache, continuous batching, and the OpenAI-compatible API.
This release also adds stronger macOS 27 compatibility, safer native MTP batching, more robust Gemma 4 / Harmony tool-call handling, and additional cache / Memory Guard hardening.
MiniMax M3 single-request results (M3U 512G, ssd-cache on)
pp1024 332.6 tok/s, tg128 28.9 tok/s
pp4096 359.8 tok/s, tg128 20.8 tok/s
pp8192 340.2 tok/s, tg128 20.2 tok/s
pp32768 243.5 tok/s, tg128 18.9 tok/s
Continuous batching at pp1024/tg128:
1x 28.9 tok/s
2x 40.1 tok/s
4x 51.3 tok/s
8x 57.8 tok/s
https://t.co/cIvWwzZ9SS
a very exciting release: qwopus 3.6 27b + MTP is my daily driver on a 3090 ti (3 K L performs well with 98K+ ctx). Qwopus is the highest performance FT of 27b, expecting the code FT to be 🔥
oMLX v0.4.3 is now available with macOS 27 compatibility!
https://t.co/cIvWwzZ9SS
This release also fixes a Memory Guard performance regression affecting Qwopus Series, DFlash Gemma, and all other models, where generation/decode could slow significantly while Memory Guard was enabled.
In a Qwen3.6-35B-A3B cache-on single-run check, tg512 improved from 77.5 -> 79.0 tok/s (+1.9%) compared with 0.4.2. (M3U 512GB)
It also improves per-model MTP eligibility handling, and DFlash/Qwen compatibility.
Java devs: you might be missing a key tool in your toolkit - #DataFrames.
Why consider them?
✅ Transform, organize, and analyze data directly in Java
✅ Improve efficiency, flexibility, readability, and developer productivity
🔗 https://t.co/x2zyk33N3I
#Java
instead of watching 2 hours of Netflix tonight, watch this 40-minute masterclass from the founder of a $20B China AI company
it's the clearest explanation I've seen of how Agent Swarms and AI systems actually work at scale
useful whether you've never built an agent in your life or have been using Claude every day for the past year
I took the key ideas and turned them into a practical guide on how to actually build with Kimi
find it below
BREAKING! Qwopus 3.6 27B is LIVE!
Thank you for your patience on this one, but I believe you'll find the wait was worth it!
We've benchmarked this thing up and down, verified that it holds at least a 75.25% (152/202) in the initial 202 SWE bench solves. Not a full run of 500, but it shows the agentic coding quality from the original 27B is retained while adding all of the additional Qwopus benefits across many domains. As always, Jackrong is absolutely cooking here!
COT quality has improved significantly through the inversion techniques from our Negentropy proof of concept. It also went through thorough curriculum training. You can check out the MMLU pro benchmarks on the model card, but it improved a whopping 10 points over the base model in physics, as well as meaningful jumps in Chemistry, business, and computer science.
However, the best part is that I was able to build an entire survival shooter game using this local model entirely. I genuinely was blown away by the results, which you can play right now on my HF space (link in comments below). "Qwopus Commander" was completed in 9 turns of Qwopus 3.6! To test the new long context training, I made it re-output the entire 3000+ line program each turn, and it would make fixes and add features that I requested in large prompts, while perfectly replicating the entire rest of the game from context. What's more is that I did it all at Q8 KV cache quantization, and never had an issue over the entire 303k token run!
IMPORTANT: Run it at --temp 0.75 to 1. Mess with it in that range for your use case. Higher temp actually lets the fine-tune shine and be exploratory and is also more stable. Swe Bench was run at temp 1, the game was built mostly at 0.8!
We're so blessed to have all of you here and using the models! The support means so much! Please let me know what you build with it in the comments! Or if you have any issues getting it up and running, I will try my best to get back to you!
Looking forward to seeing what you legends produce with it this weekend!
https://t.co/AEl3APtTLk
early checkpoint if a bigger run, getting expensive so im taking it slow ( im just a wagie doing this for fun) if anyone wants to throw me some gpus for sponsored run dm plz
no evals yet, but my smilar training run like the 9b and those evals did well
https://t.co/EN5guR8TLg
The Opus distilled Qwen 27B is going viral again, but everyone is promoting the old version! You MUST get the v2 version, which Jackrong currently does not have listed in his Opus Fintune collection, so no one is finding it. I discussed the improvements with v2 in my last week's test. Please go check out that post with the video, pinned on my page, if you get a second, and download the v2 here: https://t.co/tBMGR7yJVB
For those wanting an Opus distill but in a smaller, more accessible 9B size that easily fits on GPUs with 16GB VRAM or less:
Jackrong just dropped Qwopus3.5-9B-v3 — a fast-iterated reasoning-enhanced model based on Qwen3.5-9B with Claude Opus-style patterns distilled in.
The Q4 quant is only 5.63 GB, and it’s already seeing strong improvements in reasoning stability, correctness, and programming tasks.
Perfect for local runs without needing massive hardware.
https://t.co/4ZELVa5L9Z
This model has been #1 trending for 3 weeks now.
It's Qwen3.5-27B fine-tuned on distilled data from Claude-4.6-Opus (reasoning). Trained via Unsloth.
Runs locally on 16GB in 4-bit or 32GB in 8-bit.
Model: https://t.co/6KgPDHCJZ3