Grok Voice 3.0 is #1 on AA’s Speech-to-Speech Index.
Try it in the Grok app, with Grok Bot, in your Tesla, or by calling Starlink support. It’s even better in the real world!
Proud to have helped build this with the team.
SpaceXAI’s Grok Voice 3.0 is the new leading Speech to Speech model, debuting at #1 on the Artificial Analysis Speech to Speech Index at 86.9, while also being competitive on latency
Grok Voice 3.0 is @spacexai 's successor to Grok Voice 2.0, a Speech to Speech model available through the SpaceXAI Realtime API at $0.08 per minute. We evaluated Grok Voice 3.0 with the Rex voice through the SpaceXAI Realtime API.
Key takeaways:
➤ Speech to Speech Index: Grok Voice 3.0 debuts at #1 at 86.9, ahead of GPT-Live-1 (Astra, medium) at 83.2, Gemini 3.8 Live Extended Thinking (High) at 82.6 and GPT-Live-1 (Sol, low) at 80.1. It is up on Grok Voice 2.0 at 81.3 (+5.6 points) and Grok Voice 1.0 at 73.7 (+13.2 points), released just under six months ago. The Index averages Speech Reasoning (Big Bench Audio), Agentic Performance (Tau Voice), Arena Preference, and Task Success Rate
➤ Speech Agent Arena: Grok Voice 3.0 ranks #3 in preference at Elo 1070, behind Gemini 3.1 Flash Live Minimal (1100) and Gemini 3.8 Live (1088) and ahead of GPT-Live-1 (Sol, low) at 1057, and #1 on Task Success Rate at 94.8%, highest on the board, just ahead of Grok Voice 2.0 at 94.6%. Grok Voice 2.0 trails at Elo 1011
➤ Tau Voice: Grok Voice 3.0 takes the #2 spot on our Tau Voice benchmark implementation at 71.6%, behind GPT-Live-1 (Astra, medium) at 74.5% and ahead of Gemini 3.8 Live Extended Thinking (High) at 68.6% and GPT-Live-1 (Sol, low) at 59.3% - up from 56.5% for Grok Voice 2.0
➤ Big Bench Audio: Grok Voice 3.0 scores 98.5% on audio reasoning, ahead of Gemini 3.8 Live Extended Thinking (High) at 97.7% and Grok Voice 2.0 at 97.2%
➤ Speed: Average Time to First Audio on Big Bench Audio is 0.81 seconds for Grok Voice 3.0, well ahead of GPT-Live-1 (Sol, low) at 1.24s, GPT-Live-1 (Astra, medium) at 1.34s and Gemini 3.8 Live Extended Thinking (High) at 1.35s, though slower than Grok Voice 2.0 at 0.70s
➤ Cost: Grok Voice 3.0 costs $4.80 per hour of input audio, the same as Grok Voice 2.0. That is above GPT-Live-1 (Sol, low) at $4.47 and Gemini 3.8 Live Extended Thinking (High) at $3.50, cheaper than GPT-Live-1 (Astra, medium) at $5.83, and ~2.2x cheaper than GPT-Realtime-2.1 High at $10.75
Congrats to @elonmusk and the @spacexai team 🚀
See below for more detail ⬇️
Introducing Voice Agent Builder: a no-code platform to create human-like voice agents with Grok Voice.
Available today at $0.05 / min.
https://t.co/kUkF7zqvfR
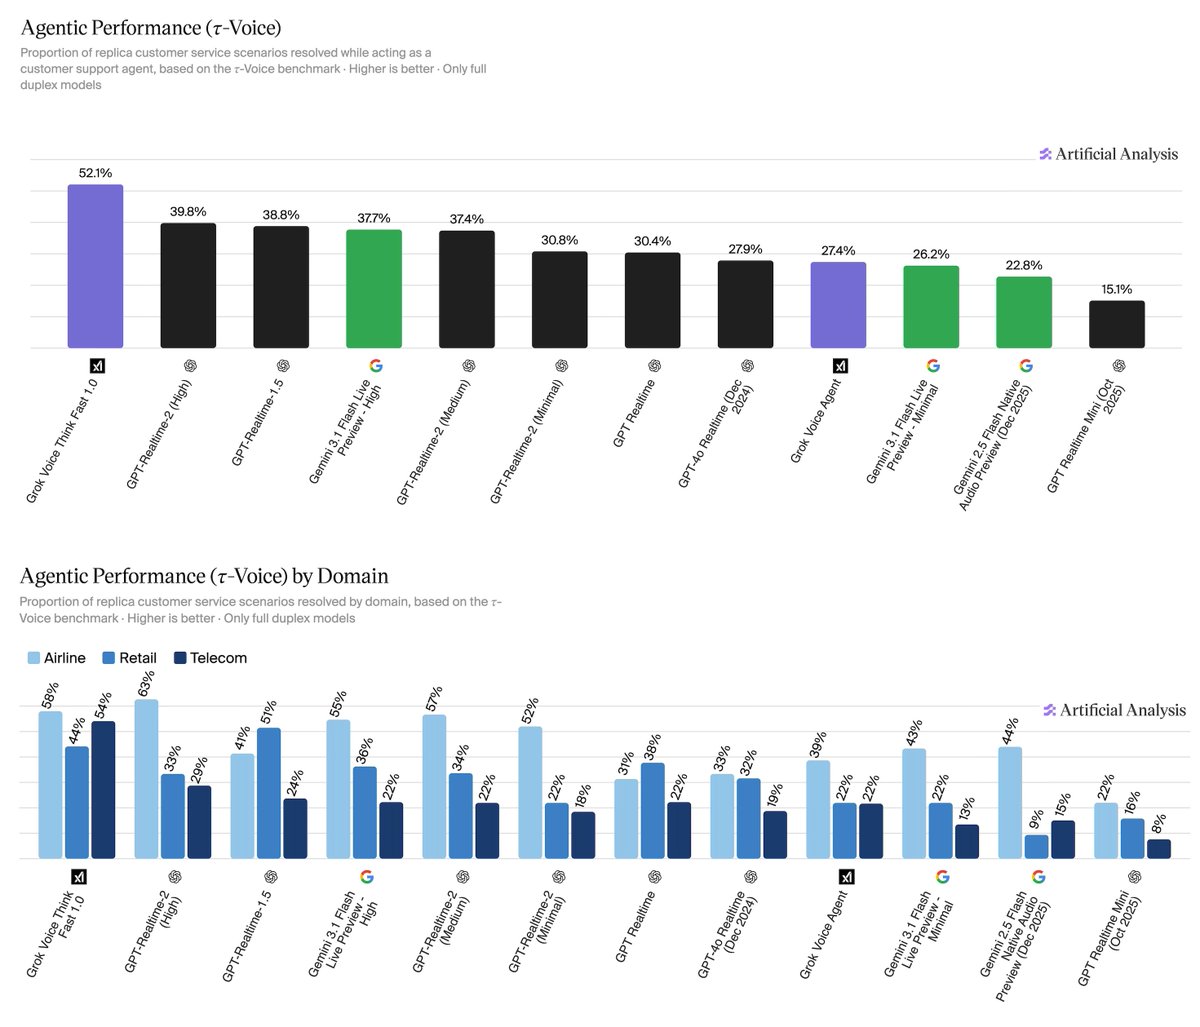
Announcing agentic performance benchmarking for Speech to Speech models on Artificial Analysis. We use 𝜏-Voice to measure tool calling and customer interaction voice agent capabilities in realistic customer service scenarios
Even the strongest Speech to Speech (S2S) models today resolve only about half of realistic customer service scenarios end-to-end - a meaningful gap relative to frontier text-based agents on the same tasks. Voice channels introduce significant complexity: challenging accents, background noise, and packet loss, all while requiring fast responses, consistency across long multi-turn conversations, and reliable tool use. Performance also varies considerably by audio condition: in clean audio some models perform notably better, but realistic conditions continue to pose a challenge. Conversation duration also varies meaningfully across models, with implications for both customer experience and operational cost.
About 𝜏-Voice:
Our Agentic Performance benchmark is based on 𝜏-Voice (Ray, Dhandhania, Barres & Narasimhan, 2026), which extends 𝜏²-bench into the voice modality to evaluate S2S models on realistic customer service tasks. It measures multi-turn instruction following, support of a simulated customer through a complete interaction, and tool use against simulated customer service systems. The simulated user combines an LLM-driven decision model with realistic audio synthesis: diverse accents, background noise, and packet loss modelled on real network conditions.
This complements our Big Bench Audio benchmark measuring intelligence and Conversational Dynamics (Full Duplex Bench subset) benchmark measuring conversational naturalness. Scores are the average of three independent pass@1 trials. We evaluate under realistic audio conditions using the 𝜏²-bench base task split across three domains:
➤ Airline (50 scenarios): e.g., changing a flight, rebooking under policy constraints
➤ Retail (114 scenarios): e.g., disputing a charge, processing a return
➤ Telecom (114 scenarios): e.g., resolving a billing issue, troubleshooting a service problem
Task success is determined by deterministic checks against expected actions and final database state, consistent with the 𝜏²-bench evaluator.
Key results:
xAI's Grok Voice Think Fast 1.0 is the clear leader at 52.1%, averaging 5.6 minutes per conversation, the second-longest overall. OpenAI's GPT-Realtime-2 (High) (39.8%, 3.0 min) and GPT-Realtime-1.5 (38.8%, 4.8 min) follow, with Gemini 3.1 Flash Live Preview - High close behind at 37.7% (3.8 min).
Speech to Speech is a fast evolving modality and we expect movement in rankings as we continue to add new models with these capabilities, and model robustness improves.
Congratulations @xAI@elonmusk! See below for further detail ⬇️
Your customer support needs a voice agent built for the real world.
Grok Voice Think Fast 1.0 handles complex workflows with speed and accuracy, even in hard-to-hear environments. From multi-step troubleshooting to high-volume tool calls, it keeps up.
Introducing Grok Voice Think Fast 1.0
A state-of-the-art voice model built for complex, multi-step workflows with snappy responses and high accuracy.
It takes the top spot on the Tau Voice Bench and handles real-world messiness like noise, accents, and interruptions better than any other model in the world.
https://t.co/SwdNYRH7Po
Happy to announce our joined work with @yitehsu, @Sarthak48364518 and Yi-Hsiu Liao on Efficient Inference for NMT https://t.co/WgtDDl5gkG We propose a combination of techniques which combined allowed to speed up inference 2x without degradation in BLEU
Happy to announce our joined work with @yitehsu, @Sarthak48364518 and Yi-Hsiu Liao on Efficient Inference for NMT https://t.co/WgtDDl5gkG We propose a combination of techniques which combined allowed to speed up inference 2x without degradation in BLEU