Qwen3.8-27B at 144 tok/s on an M5 Max MacBook Pro ⚡
Meet Inco Splash: our open-source inference engine, built around the model and around Apple silicon.
Up to 3× the decode speed of Ollama, 2× oMLX, and almost 4× when an agent fans out into sub-agents.
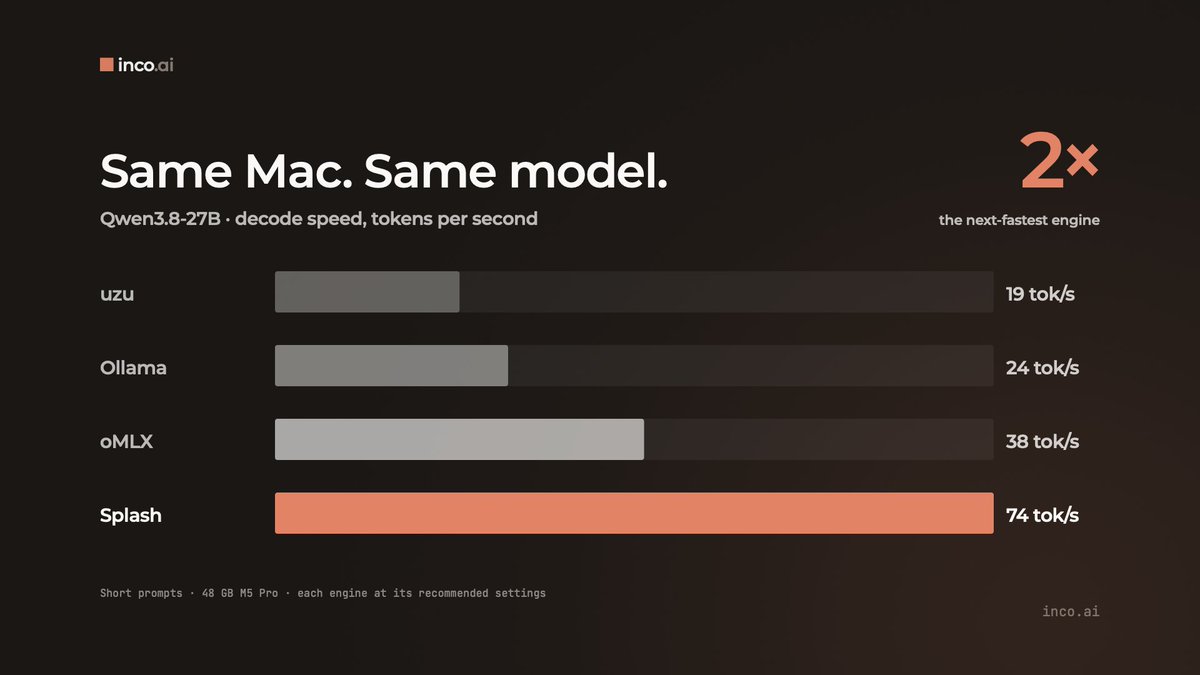
Same Mac. Same model. 2×.
Qwen3.8-27B decode on a 48 GB M5 Pro, short prompts:
Splash 74 tok/s · oMLX 38 · Ollama 24 · uzu 19
The lead holds to 32K, where Splash still does 54 tok/s, above every other engine's short-prompt best.
Four agents at once: 3.9×.