That is interesting to hear that @Visa openly says that they "reliability" when it comes to fraud is just 99.98%. https://t.co/PdrN6SjGPQ @Mastercard is probably a better choice. It would be interesting to hear their numbers.
Another engineer I’ve never worked with said that he really likes my coding style in C++. That is one of the best things I’ve ever heard about my work. Tell your fellow peers something you like in their work more frequently. It makes difference.
hey @blockchain I wonder you are going to pay people whose money stuck in your product difference in price between the date they initially tried to sell BTC and the day you resolved their tickets regarding inability to withdraw BTC?
Is there any value in gamification outside of pumping dopamine through veins? Even for the people who play games? I feel that gamification one of most harmful things to the end users along with free delivery, notifications, and recommendations that maximize screen time. With a few exceptions. Am I missing something?
WE ARE SOLD OUT
thank you all for the support - it's going to help us take things to the next level
better quality, better prices, and some funny ideas that you're all going to laugh about
see you soon
MYSTERY SOLVED!
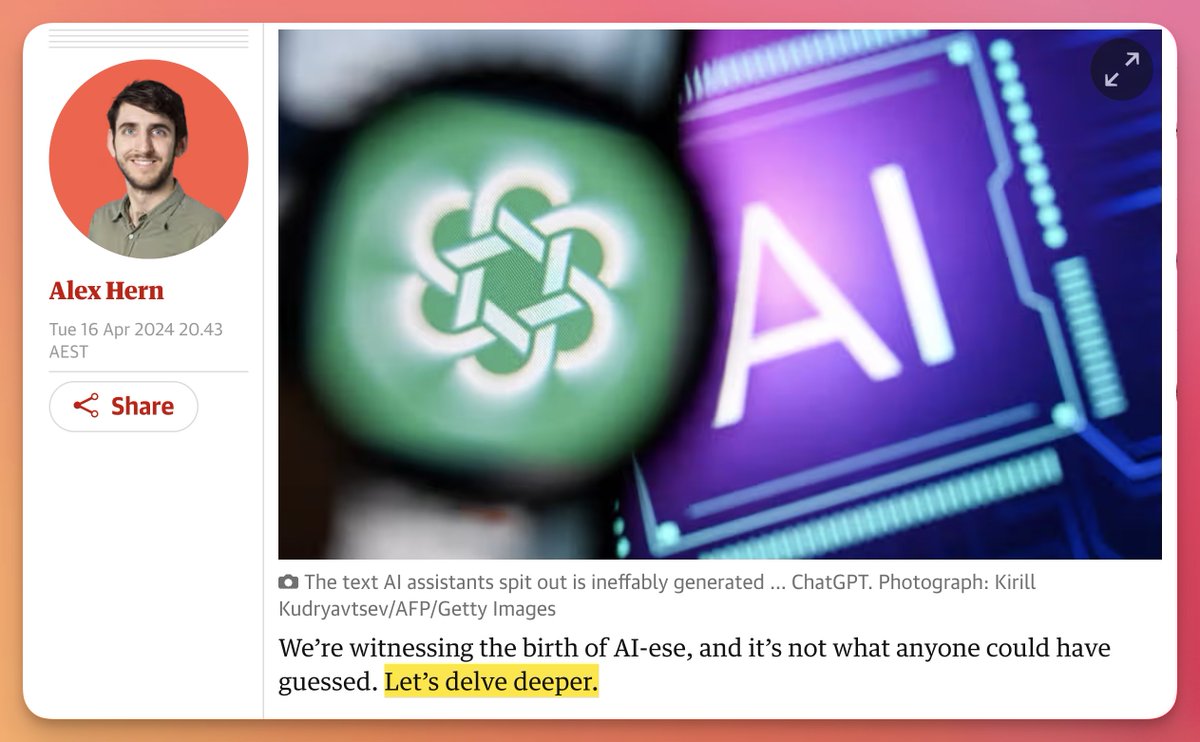
Why does ChatGPT use the word "delve" so much? We've seen a 10x increase in the proportion of medical studies using the word "delve" from 2022 to 2024. But why?
@alexhern at The Guardian might've just solved it. Thread below, complete with the trail of clues:
@sky2high0 Nice article. One comment, is it caching or it is the js nature of locally created objects which are by the definition local. And would function declared as a function or as global function or a state do the trick?
@emil_priver Your setup looks really nice to me. What do you use hardware, software, color schemes and fonts. Or do you have a git repo to share with you settings you use?
vLLM has blown every other LLM inference method out of the water.
vLLM is an open-source library to serve large language models. It uses a new attention algorithm to deliver up to 24x higher throughput than HuggingFace Transformers without requiring model changes.
This is a huge deal.
The library was developed at UC Berkeley. It makes serving any LLM affordable for anyone with limited computing resources.
vLLM will give you higher throughput, but serving an LLM in production requires much more. You'll need cost-optimized computing resources, a scalable orchestration mechanism, and a streamlined pipeline to host your LLM.
The @monsterapis team built one of the first large-scale implementations of vLLM behind their text-generation LLM APIs. Thanks to vLLM's speed, you can now access their models with a 98% cost reduction.
You can use any of the following models:
• Mistral 7B Instruct
• Microsoft Phi-2
• HuggingFace Zephyr-7b-beta
• TinyLlama-1.1B-Chat-v1.0
The team gave me 10,000 free credits for anyone who uses the code "SANTIAGO" in their dashboard:
https://t.co/HaeAxyM3be
If you want to get their latest updates, get free credits and special offers, join their Discord server:
https://t.co/oecoxEec14
It would be interesting to build a system which would allow people to trace back all bills, laws, regulations a politician voted for or against. So the voters can decide to vote based on hard evidence and not the words.
If you are organizing a conference, consider using Claude to establish a baseline for paper reviews. Not to replace human reviewers but to set the bar. Also consider to use an LLM to review the reviews, alerting program chairs to potential shortcomings.