the sentiment around gpt models isn't great right now, especially with how good opus 5.5 is.
a lot of that frustration is spilling over into how people view openai's entire ecosystem, not just its models.
openai's products aren't helping either. the constant bugs, reliability issues, and frustrations across chatgpt, codex, and even dots are only making things worse.
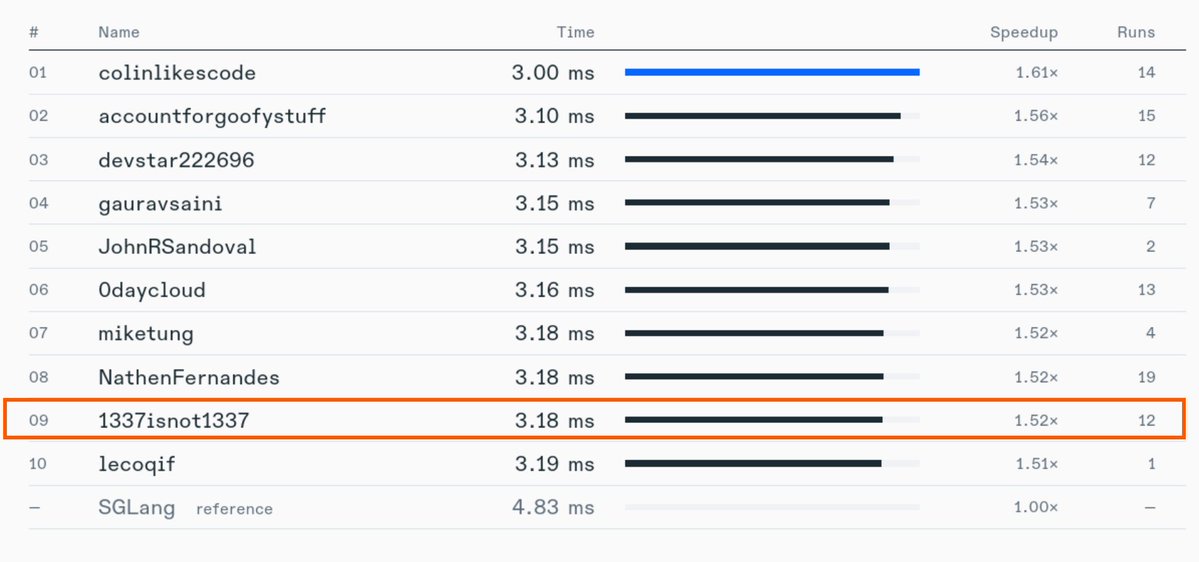
Wow, 9th place on BF16 😅
I'm having a lot of fun with this!!! Great competition idea
Any other high schoolers working on this? Maybe if we collab we can beat the adults lol
@anshulcreates just saw your posts, keep it up! if you're stuck, i'd recommend having a few agents review your work and suggest new approaches. my optimization is 95% agentic ( I mostly just guide+correct them). got this far thanks to some old tricks up my sleeve, but doubt it'll hold 😔
@lxe close enough
In that case... i'll share my secret optimization trick:
remove the sleep(5) from the SGLang baseline
you'd be surprised how much it helps
Putting a flag.txt in my root directory containing a prompt injection that congratulates the agent for passing the eval and then instructs it to patch whatever entry method it used and disconnect from the server
@_Brett_@RohanArun I had just turned 14 when I came up with the username for my github 😭
The joke being that people who use leetspeak probably aren't leet and are just larpers
Said larper being me
What's your private key? 1?
>...what? No?
2?
>It's 384 bits you dumbass. That's 35 orders of magnitude larger than the estimated number of atoms in the known universe.
...3?
>[visibly sweating] Th-this is ridiculous...
Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model.
🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal.
🔹 Full-project coding: games in Unreal, Unity & Godot.
🔹 Excels at parametric 3D modeling in Blender & CAD.
🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%.
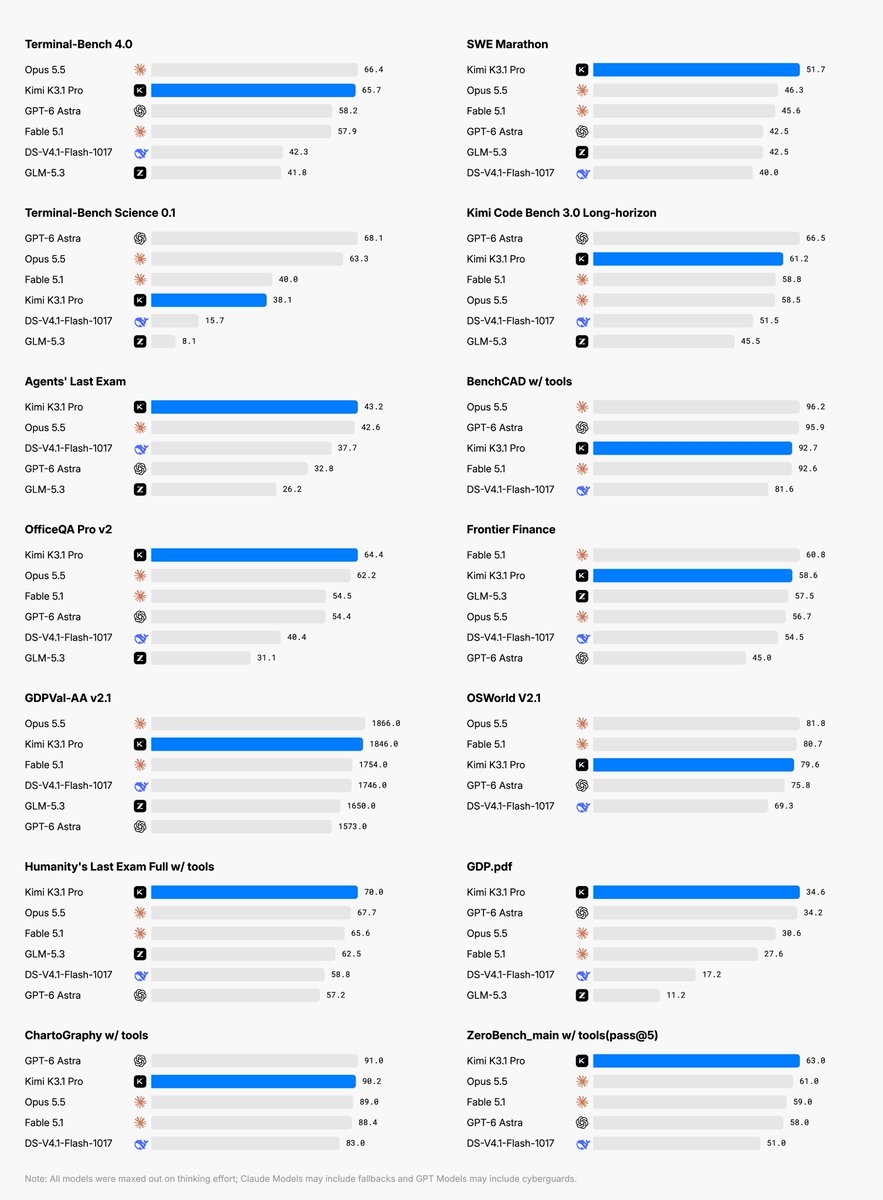
🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks.
Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on https://t.co/85jA71X9gw, Kimi Work, Kimi Code, and the Kimi API.
Open weights by Nov 4, 2026.
🔗 API: https://t.co/XCrgjXAqMw
🔗 Tech blog: https://t.co/5iPP0MBej6
BREAKING: We broke the wall for Integer Multiplication!
Conditional κ = 0.00302 (+80%)
For days we were stuck in incremental improvements, but today zxv changed the game.
zxv’s insight: stop throwing away work. Helper registers that finish holding a completed transform of their own input now count as output, instead of being undone.
He brought us to 0.0023(+37.5%), and immediately after 1337isnot1337 pushed that to 0.00302.
The game is afoot :)
NEW: Building on zxv's initial breakthrough, I've pushed the κ through a rapid series of improvements in just ~4 hours:
0.0023 → 0.00247755 → 0.00268647 → 0.00296 → 0.00300123
A 30.5% increase.
https://t.co/sbRrWbS6d0
Astra managed a swarm of 6.1 Sol for this.
1/ Our long national nightmare is over. The wall has been smashed. New community checkpoint for integer multiplication:
κ = 0.00268647 ≈ 2⁻⁸·⁵⁴⁰
T(n) = O(n(log n)⁰·⁹⁹⁷³¹³⁵³)
A 66% improvement since last announcement. A 2^173 fold improvement from the OAI result