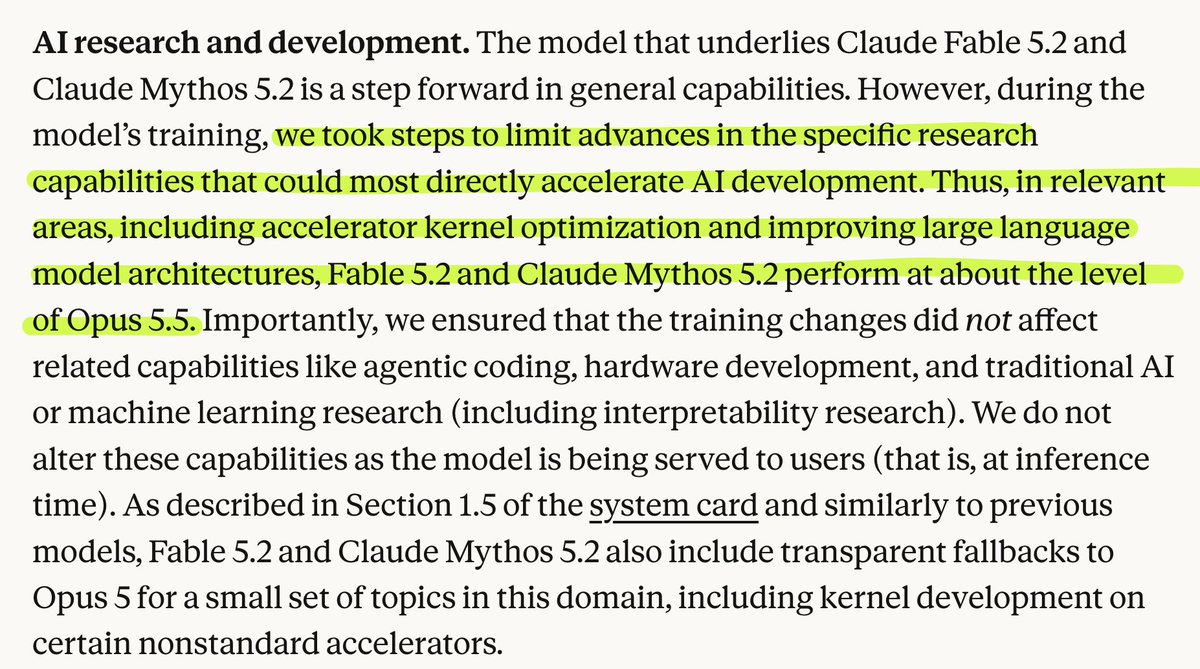
@yujitach When the conversation gets very long these false flags are common. Once I was discussing some simple QFT ideas and it degraded from Fable to Opus saying similar things.
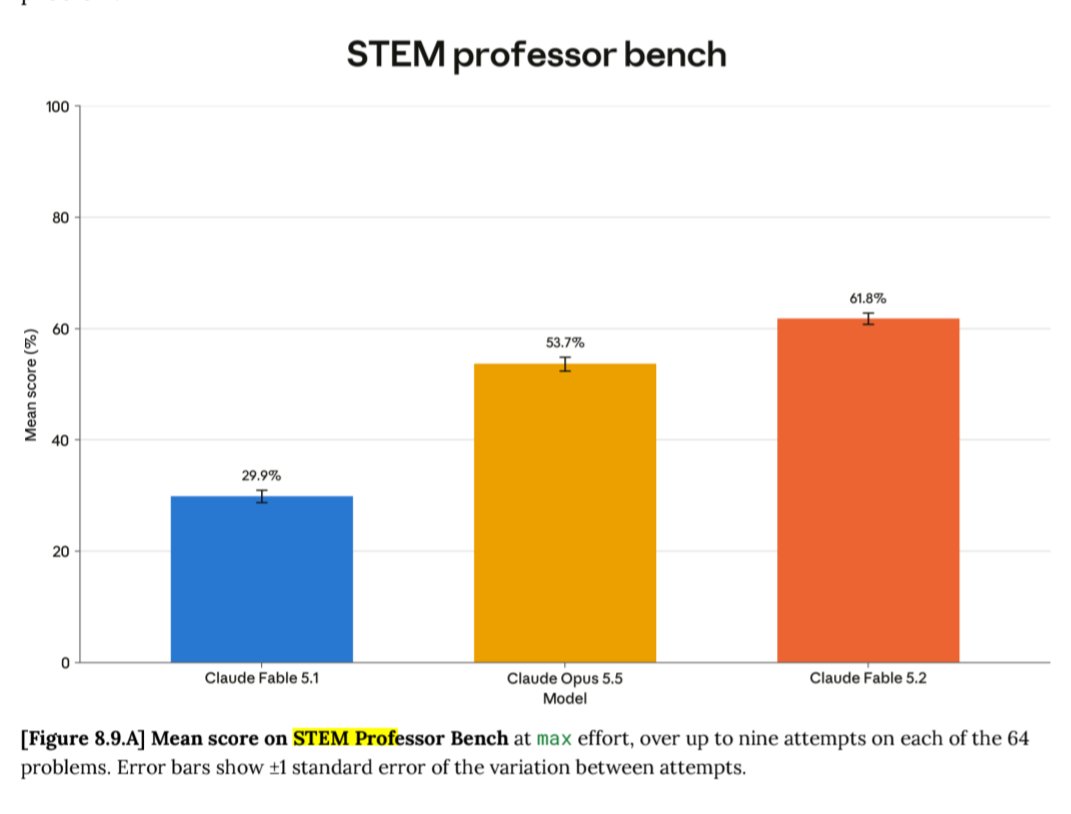
"We report the results on a 64-problem subset. Most problems are in theoretical physics,
including string theory and holography, condensed matter, high-energy theory, and
astrophysics."
Source: Fable/Mythos 5.2 system card
“It is striking that it has so far not been possible to find a logically consistent theory that is close to quantum mechanics, other than quantum mechanics itself.”
—Steven Weinberg, Dreams of a Final Theory
Gemini made users wait 2 weeks after announcing Carbon and then gave it only to the rare Ultra subscribers.
Fable 5.2 and Astra cost 2x more than Carbon, but Claude still let Pro users try Fable 5.2 and ChatGPT still let Plus users try Astra.
Gemini has the biggest data centers in the world and still locks its new model behind its expensive plan, what a joke.
Internal memo written by Jared Kaplan (Anthropic Cofounder) in Jan 2021 how their most likely product could be "an extremely powerful AI programming assistant"
Think about it! 2021!?!?
As a PhD student in physics thinking about AI research in the sidelines, I was inspired after reading this article yesterday.
asked Opus 5.5 to make a video out of it to simplify the ideas for a general audience
Last year, I had a conversation with @RichardSSutton on the Bitter Lesson and wrote an essay entitled "The Bittersweet Lesson". It's not a counter to the original, but a statement about how our confusion on this topic points to issues to the need for deeper understanding.
https://t.co/8CWM5FJIPF
Terminal Bench Science v0.1: it covers 19 life science, 17 physical science, 17 mathematical science, 9 engineering science, and 8 earth science tasks which tests the models scientific capabilities over the long horizon (~ 8 hours per task)
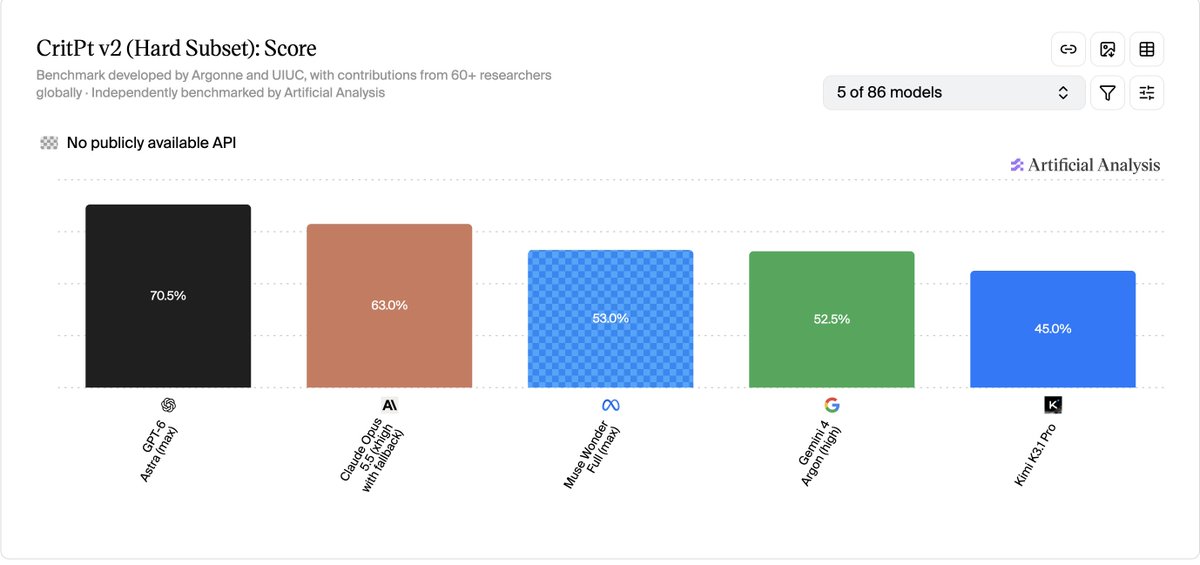
CritPt v2 has finally been released in the recent major overhaul of the @ArtificialAnlys Intelligence Index v5.
The older version had many errors which were first reported in the Fable 5.1 system card.
more observations below:
Below is my personal opinion, not speaking for openai.
There are many AI safety interventions that are purely positive.
Training for honesty, and alignment in general, is one example. Models being more honest & aligned is undeniably a good thing.
Monitoring is another example: it serves both to block harmful actions as well as learn valuable information about misaligned behavior. (And to me, the fact that it comes at a non-trivial compute cost, and so has some slowdown impact, is a feature, not a bug.)
Nerfing or restricting models from helping with AI research is more complex. I can see the argument for preventing bad actors, in particular ones from non democratic nations, from creating models with risky capabilities.
However, I am also worried about concentration of power, in particular concentration of power by us (= the labs), and this seems to go in the opposite direction. It can also hamper external AI safety researchers. And to the extent a lot of the risk in acceleration is from internal deployment, having growing gaps in capabilities between internal and external models seems not ideal.
I am not saying that there will never be a good reason for having some restrictions in some form, but this is an area we should tread *very* carefully on.
There is also something I find problematic about even the perception of using safety as an excuse for practices that may also be motivated by competitive reasons. It is fine that for-profit corporations try to optimize their profit, but let's make sure we're honest about it and not hiding behind safety.
Entire prompt:
'You know, you should also build me a FPS. Insanely detailed quality pls, something that looks visually like it can keep up with AAA. Make it small in scope (like a tiny level) but otherwise impressive photorealistic graphics.'
Fable 5.2 one shot it.
Claude Opus 5.5 just downloaded an open-source text-to-speech model (Qwen3-TTS ~4GB) in my local pc cuz I was complaining too much about the robotic voices of free models available online.
The model is the most important thing. Opus 5.5 with 1000 agents completed only 26% of the Fermat’s Last Theorem formalization in 18 hours and barely made any more progress after 30 while Fable 5.2 got it done in 30 hours.
I encountered the 3rd issue in one of my latest projects and it was gpt-6-Astra who insisted on not averaging the 2 quantities even when they gave a much better agreement with the expected result. (even though I didn't have any explicit prompt saying so)
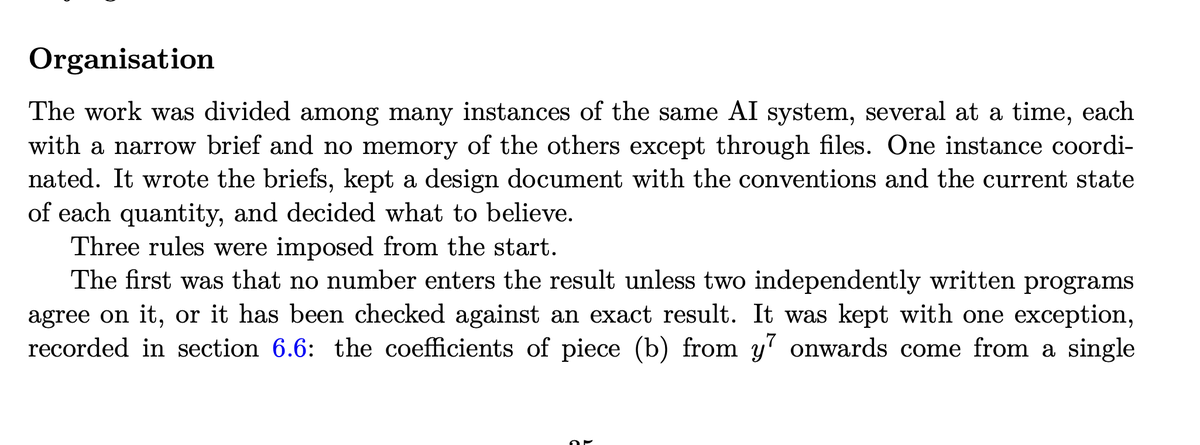
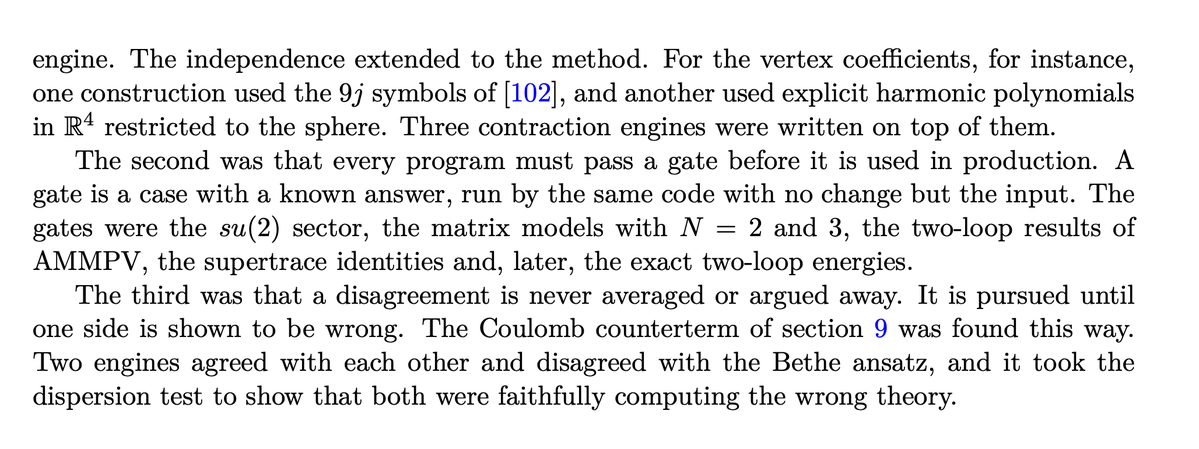
The Anthropic Black Hole paper has some interesting details on how the AI's were organized to do the calculations:
- Several instances of the same llm running independently, dividing the work
- One AI coordinator communicating between the others, keeping a central doc for conventions and deciding what to believe at each stage
- 3 hard rules for all models to follow:
1) "no number enters the result unless two independently written programs agree on it, or it has been checked against an exact result"
2) "The second was that every program must pass a gate before it is used in production. A gate is a case with a known answer, run by the same code with no change but the input."
3) "The third was that a disagreement is never averaged or argued away. It is pursued until one side is shown to be wrong."
with this, i think it's quite likely that anthropic will never publicly release (or at least not in the coming months) a model more capable than opus 5.5 at llm training
@AcerFur idts. Intelligence is still jagged and heavily constrained by data so we have to wait a few more years (maybe 1-2) to see an equalizing effect across different benchmarks