As AI systems start doing research-level mathematics, how do we evaluate them, and how do we trust what they produce?
Last week I gave this talk at the Penn AI Seminar on my research group's and @Rabdos_AI 's work on "scalable oversight" in the setting of mathematics:
https://t.co/KeXeKcMIt4
Scalable Oversight concerns techniques to monitor, evaluate, and control AI systems, even when they become more capable than the humans supervising them.
Standard alignment methods like RLHF rely on humans directly judging model outputs. As AI moves into specialized or superhuman domains, human supervisors can no longer reliably judge correctness or safety. Without a reliable training signal, models risk reward hacking or developing unaligned behaviors that humans can't spot. That gap only widens as we move from RLHF toward recursive self-improvement.
Mathematics is the ideal testbed. Correctness is, in principle, well defined, and we are already at the point where human checking can't keep up. This is also the principle behind Rabdos: can we create data that autonomously and continuously evaluates and improves AI systems?
References:
1. MathDuels: A Self-Play Benchmark That Grows
https://t.co/1rlrDqLjuD
2. Do We Need Frontier Models to Verify Mathematical Proofs?
https://t.co/clsuSc0rsX
3. Learning Strategies to Break Judges
https://t.co/9DanX4cN0y
Joint work with PhD students Oscar Xu, Shibo Jin, Guruprerana Shabadi, Aaditya Naik, postdoc Shreya Arya, and colleague Rajeev Alur.
#AI #Mathematics #LLM #AIEvaluation #ScalableOversight
We've released the weights for Beam!!
🤗 https://t.co/yrkK3mJ0dv
📄 Model card: https://t.co/itiGxZgyC7
🧪 Try Beam in our playground & get an API key: https://t.co/cUOE6dP1ZU
📚 AND we take open model safety seriously and have posted our safety report: https://t.co/VPPNUL12U6
My team at @AnthropicAI is hiring: DevRel, but for scientists.
Run hackathons, build demos, and help us grow a community of researchers using Claude.
If you're a scientist who also loves to teach or post about AI for science, please apply!
https://t.co/HDuY2loKpB
We're significantly expanding access to Gemini for scientists via antigravity - sign up now!
Top of mind question for scientists on data retention - please turn off telemetry if you'd like.
https://t.co/cQm6QPlyYk
am thinking about what the future of a "math book" should be... heavy on graphics; with interactive elements (e.g. GPT Sites); dynamic references that auto-update N-times-per-year to reflect changes; self-repairing to fix errors...
not paper & not a pdf... maybe a github repo?
Penn CIS is hiring in security and AI systems! You can find the application here: https://t.co/RGFmVHqFnh.
As in prior years, the committee doesn't care if you have few or many papers. They focus only on 2 or 3, so make sure that your application focuses on your best work!
I am at COLM'26 this week in San Francisco with my students as well as folks from @Rabdos_AI . We have three cool papers on timely and exciting topics; drop by if you are attending!
> MathDuels: A Self-Play Benchmark That Grows
https://t.co/1rlrDqLRkb
Wednesday 11-1, Grand Ballroom #121
Leaderboard: https://t.co/Oinn8qgAO8
> Detecting Safety Violations Across Many Agent Traces
https://t.co/YMcubbc5ry
Thursday 11-1, Grand Ballroom #129
> Do We Need Frontier Models to Verify Mathematical Proofs?
https://t.co/clsuSc0Ziv
Thursday 4:30-6:30, Imperial Ballroom #21
This is the first semester in my teaching career that I have been able to use LLMs to improve the learning experience.
One way I’ve been doing this is simply feeding my static slides from each lecture into an agentic framework to create live demos in class.
For my software analysis class (https://t.co/2nlqRsO8O5), I used Claude Code to demo different program correctness techniques, from random testing using AFL++ to theorem proving using Dafny. In the past, I spent hours just debugging the setup of these tools. Now Claude does it autonomously for me in *under 5 minutes*, giving me a standalone Docker container with a web UI.
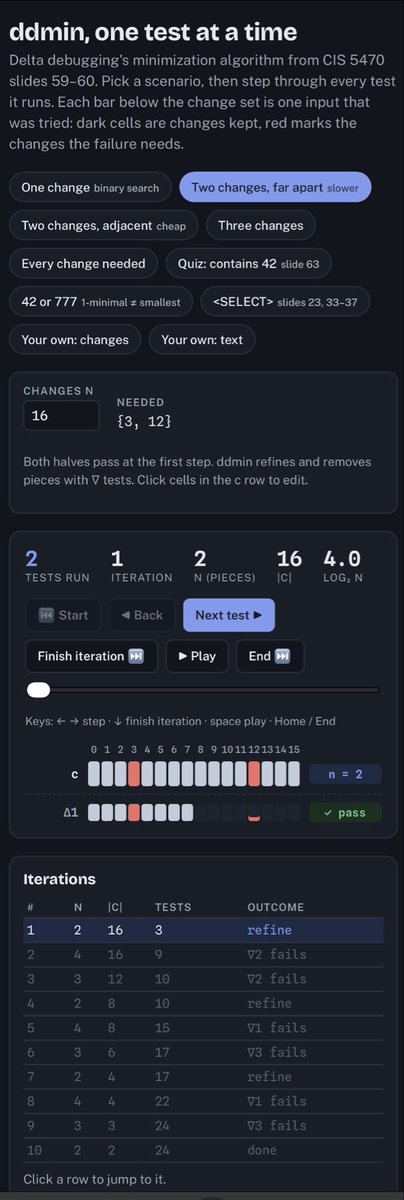
Check out this demo of an automated debugging technique called Delta Debugging that I covered this week:
https://t.co/iD9ePftfYw
As a bonus, you yourself learn subtle new things about the technical content. For me this happened with a concurrency fuzzing technique called PCT, where Claude showed how P(bug per run) is higher but rate of bugs per second is lower if you put threads to “sleep” versus simply preempt them.
It is an even bigger privilege to be teaching in these times. LLMs can now do almost anything so it all comes down to instructor taste and judgment.
Huge congratulations to Adam, my recently graduated PhD advisee who worked on this newly minted model -- on the topic of safety which is becoming a big deal!
Beam is out! I feel extremely lucky to have been been part of this launch as part of the safety team for the past ~2 months. It’s been a lot of looking deeply into model outputs and data, being surprised by what we see, and updating our evaluations and training recipes to fix the problems. It’s amazing what has been achieved in so short a time, and I'm very excited for the road ahead!
What do surjective / injective functions have to do with optimizing and verifying ML kernels? Read on!
In math/logic foundations of CS, we learn early on about “surjective” and “injective” functions. Thereafter, most of us have only a hazy recollection of these words, let alone why we learnt them or if we will ever apply them. I was certainly in this camp.
Until recently, when I worked on proving equivalence of tensor programs with my amazing PhD student Paul Biberstein (https://t.co/QDAIyr40jn) and colleague Joe Devietti: https://t.co/bwcRoDatJh.
Suppose you want to check if tensor programs P and Q are equivalent. This is decidable but intractable. Since 90% of time is spent in 10% of code, it is often the case that we can express P and Q as:
P = F o R o G
Q = F o S o G
for programs R and S such that checking R == S becomes tractable. At first glance, it seems that one can always strip F and G. But this turns out to be true only if F is surjective and G is injective! Here’s why:
If R == S, then it is easy to see why P == Q.
But if R != S, there is an input X such that R(X) = Y and S(X) = Z and Y != Z. Lifting this counterexample to P and Q requires F to be surjective and G to be injective.
F is surjective means for all B: exists A: F(A) = B. So one can plug in B = X from the above counterexample and apply the inverse of F to it.
G is injective means X1 != X2 => G(X1) != G(X2). So one can plug in X1 = Y and X2 = Z in the above counterexample.
Putting these two together, we see that there exists an input A such that P(A) != Q(A). In other words, one can “lift” the counterexample of R == S to a counterexample of P == Q provided F is surjective and G is injective.
When I first memorized things like “injective == one-to-one” and “surjective == onto”, I wish I had seen a practical example. In the LLM era, we have an opportunity to tailor explaining abstract concepts to individuals’ methods of learning.
My research group is building the formal machinery for optimizing and verifying ML kernels, and this paper is our first on this topic. It only scratches the surface of classic symbolic methods and math concepts one can bring to bear in this domain. A lot more to come in future months!
The status quo for R1 institutions cannot last. I'm guessing there will be a barbell distribution of focus that splits the classical research/teaching fusion we currently enjoy. A few OOM of improvement in AI and we might see:
1. The research side goes industrial -- applied mathematicians producing enormous bodies of interdisciplinary work; physical science labs running in warehouses with heavy robotics and automated data collection and processing; economics and social science simulations at extreme scales...
2. Teaching is top-quality, high-touch, personalized-service, with courses becoming works-of-art and top professors being superhuman performers and guides.
In short, each end of the research-teaching axis taken to extremes.
There are hints of this divergence already. At Penn, the two top schools (by $$$ & prestige) are the medical school (no undergraduate teaching; lots of heavy lab-based research at scale), and the business school (almost all teaching, highly profitable, most research occurring in pockets like the stats department at wharton).
Ramp that split with AI improving 100-fold and more, and we will see a vast bimodal transformation that integrates the university more with industry (large scale research) and serves students better (extremely attentive teaching).
Congrats to Anthropic on shipping Claude Opus 5.5! Here's an especially noteworthy article by Boris Cherny on using this model to formally verify the Claude Agent SDK using Lean.
Rabdos is an industry leader in creating high-quality Lean data; check out our benchmark at https://t.co/8zCfEH1luH
I used Opus 5.5 to formally verify the Claude Agent SDK using Lean. A couple short prompts = 16 PRs fixing various bugs and race conditions. Video attached.
TLA+ also works well. I sometimes combine Lean and TLA+ to look for issues around data flow, concurrency, and state mgmt.
I don't know either language well, but Claude is excellent at both. This approach is super useful for formally modeling your code and finding bugs that a human probably wouldn't have spotted.
Is formal verification the future of coding (or at least, bug finding)?
Congratulations to Anthropic on the release of Claude Opus 5.5! 🎉
At Rabdos, we spend our days thinking about the hardest problems in math and science, so it's exciting to watch frontier reasoning keep advancing this quickly.