One image. One AI model. A butterfly brought to life in 3D! 🦋🔥
Experiment 01: Gemini 4 Argon (Medium)
I challenged Gemini to turn a single butterfly image into an interactive 3D simulator using Three.js.
And the result? Pretty impressive! 👀
Here's what it built:
🦋 15 individual 3D components — wings, legs, antennae & body parts
🎮 360° exploration — rotate, zoom, and inspect individual components
⚡ Real-time animations — wing flapping, hovering & adjustable speed
🧩 Exploded view — separate and reassemble body parts
🎨 Visualization modes — natural, hybrid & wireframe
All generated through an AI-assisted coding workflow, without prebuilt 3D models.
Not a perfect reconstruction, but a fascinating experiment in turning a static image into an interactive experience.
Model: Gemini 4 Argon (Medium)
Built with: VS Code + Copilot + Three.js
Real experiments > AI hype.
Demo below. 🚀
@GeminiApp@GoogleAIStudio@Google #Gemini #Gemini4
🚀 FROM STARSHIP SN8 TO SHIP 42.
2020: Elon Musk surveys the wreckage of Starship SN8 after its dramatic test flight.
2026: Elon stands beside Ship 42 following its reported historic orbital return and tower catch.
Six years of testing, failures, breakthroughs, and relentless engineering.
From examining the wreckage to inspecting a returned spacecraft.
What an incredible journey for SpaceX.
@elonmusk@SpaceX
#Starship #SpaceX
🚨 QWEN4-MAX IS MAKING THE AI PRICE-PERFORMANCE RACE INTERESTING.
Artificial Analysis reports:
• Intelligence Index: 43 (+9 vs Qwen3.8-Max)
• Cost per task: $3.27 vs $10.02
• 39% fewer output tokens
• 1M-token context window
That's 67% lower cost per task while improving across every Intelligence Index evaluation.
But Kimi K3.1 Pro still leads in overall intelligence and Terminal-Bench 4.0.
Smarter, cheaper AI is becoming a serious competitive advantage.
@Alibaba_Qwen
Source: Artificial Analysis
https://t.co/o5PyJ5j6Ds
#Qwen #AI
Alibaba has launched Qwen4 Max, gaining 9 points over Qwen3.8 Max on the Artificial Analysis Intelligence Index and landing 3 points behind Kimi K3.1 Pro at ~11% lower Cost per Task
Qwen4 Max, using xhigh reasoning effort, scores 43 on the Intelligence Index, 9 points ahead of Qwen3.8 Max (xhigh) and 3 points behind Kimi K3.1 Pro (max, 46)
Key takeaways:
➤ Qwen4 Max improves on every evaluation in the Index vs Qwen3.8 Max (xhigh, 34): HLE-Diamond +21 points (24% to 45%), AA-Omniscience +18 points, AutomationBench-AA +17 points, CritPt v2 +13 points, Terminal-Bench-Science +11 points, Terminal-Bench 4.0 +9 points, GDP.pdf +3 points, FrontierCode 2.0 +3 points and AA-Briefcase +82 Elo.
➤ Qwen4 Max costs $3.27 per Intelligence Index task, ~3x less than Qwen3.8 Max ($10.02) and ~11% less than Kimi K3.1 Pro ($3.68): This is driven by 25% lower per-token pricing than Qwen3.8 Max, 70% cheaper cache hits and lower token usage. Tencent Hy4 costs ~3x less per task ($1.03) than Qwen4 Max but scores 8 points lower on the Index.
➤ Qwen4 Max uses 39% fewer output tokens per task than Qwen3.8 Max: ~105k output tokens per Intelligence Index task vs ~171k for Qwen3.8 Max, ~72k for Kimi K3.1 Pro and ~78k for Tencent Hy4. Qwen4 Max uses fewer tokens, while increasing 9 points on the Intelligence Index
➤ Improvements in AA-Briefcase (knowledge work): On AA-Briefcase, our evaluation of agentic work across real business files, Qwen4 Max reaches 1686 Elo vs 1674 for Kimi K3.1 Pro and 1446 for Tencent Hy4.
➤ Qwen4 Max trails Kimi K3.1 Pro on Terminal-Bench 4.0 and Tencent Hy4 on FrontierCode 2.0: Qwen4 Max scores 48% on Terminal-Bench 4.0 vs 67% for Kimi K3.1 Pro and 37% for Tencent Hy4. On FrontierCode 2.0, @cognition’s private evaluation of real-world coding tasks, it scores 26%, level with Kimi K3.1 Pro (26%) and behind Tencent Hy4 (31%).
Key model details:
➤ Context window: 1M tokens
➤ Multimodal: Text and image input with text output
➤ Pricing: $1.50/$4.50 per 1M input/output tokens on Alibaba's first-party APIs, with a $0.075 cache hit price. This is lower than Qwen3.8 Max across the board ($2.00/$6.00, with a $0.25 cache hit price)
➤ Availability: @Alibaba_Qwen 's first-party APIs
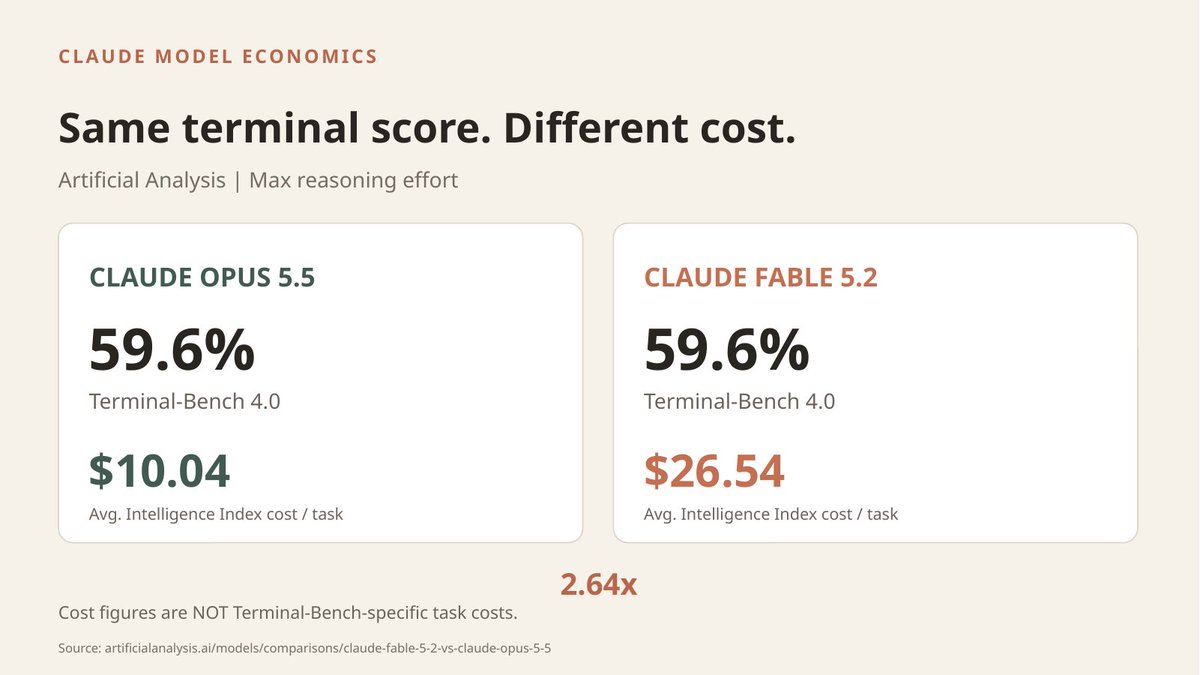
🚨 CLAUDE FABLE 5.2 HAS A 2.6× COST PROBLEM.
According to the Artificial Analysis figures:
Terminal-Bench 4.0 (Max effort)
• Claude Opus 5.5: 59.6%
• Claude Fable 5.2: 59.6%
Reported cost per Intelligence Index task:
• Opus 5.5: $10.04
• Fable 5.2: $26.54
Same terminal benchmark score. A 2.6× difference in overall evaluation cost per task.
Fable may be stronger overall, but is the premium worth it for your coding workflow?
Would you pay 2.6× more?
@AnthropicAI
Source: Artificial Analysis
https://t.co/o5PyJ5j6Ds
#Claude #aicoding
🚀 BIG UPGRADE FOR GOOGLE ANTIGRAVITY!
Google says it's doubling the context window for Gemini 4 Argon, Carbon, and Hydrogen.
The interesting part?
3.5× less context compaction per user turn!
For developers, this could mean:
• Fewer context interruptions
• Better continuity in long coding sessions
• Less frequent conversation compression
A welcome improvement for agentic coding workflows.
@GoogleDeepMind@GeminiApp
Source: Original Antigravity team announcement on X
#Gemini #antigravity
We’re doubling the context window for Argon, Carbon, and Hydrogen in Antigravity.
Lots of work to make this happen but you should now see compaction go down by 3.5x per user turn!
🚨 QWEN4-MAX IS NOW AVAILABLE IN OPENCODE GO!
Alibaba's latest AI model joins the OpenCode ecosystem.
What makes Qwen4-Max interesting?
• 1M-token context window
• Strong coding and reasoning capabilities
• Improved token efficiency
• Support for complex, long-running tasks
More model choices. More competition. Better tools for developers.
Who's trying Qwen4-Max in OpenCode Go? 👀
@Alibaba_Qwen@opencode
#Qwen #OpenCode #AICoding
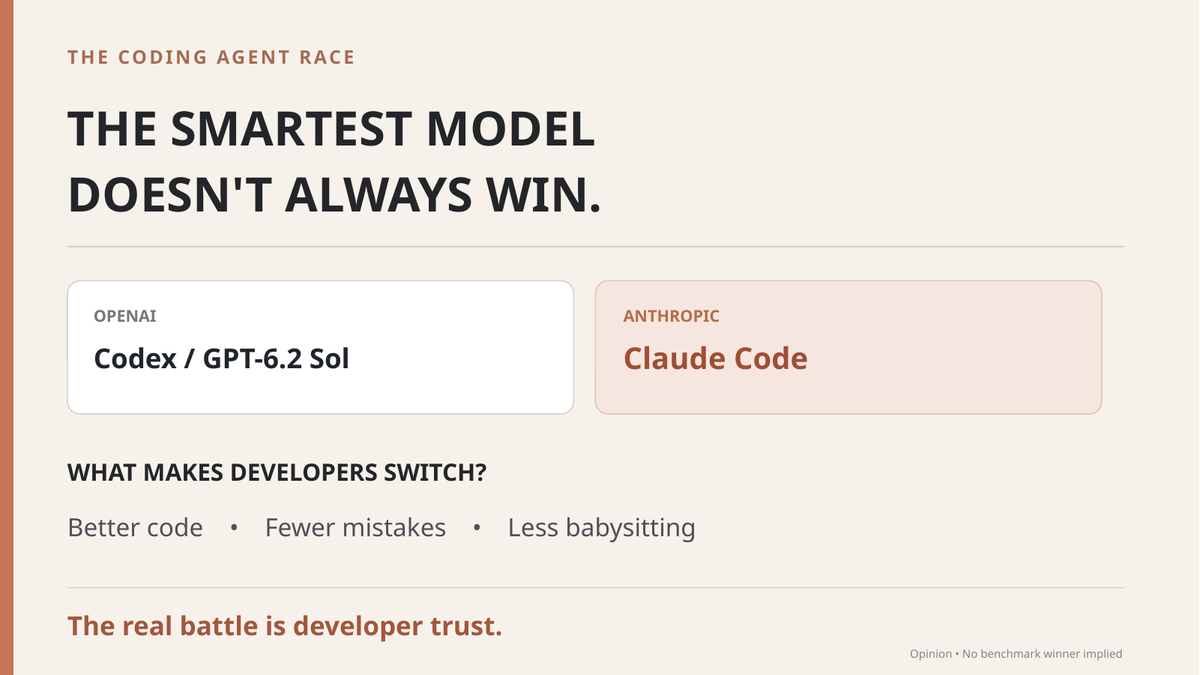
🚨 @OpenAI could release the world's smartest AI model tomorrow and STILL lose developers to Claude Code.
Here's why.
Developers don't switch coding agents for a 3-point benchmark advantage.
They switch for:
• Better code quality
• Fewer mistakes
• Less manual intervention
• Reliable long-running workflows
GPT-6.2 Sol doesn't just need to beat Claude on benchmarks.
It needs to make developers WANT to switch.
The real battle isn't intelligence. It's developer trust.
@OpenAI@AnthropicAI
#Codex #ClaudeCode #AI
🚨 Greece is turning to Starlink to improve railway safety.
The government is reportedly deploying a train-monitoring system designed to detect potential collision risks.
• 134 locomotives equipped with monitoring devices
• GNSS-HEPOS positioning with up to 5 cm accuracy
• Train locations updated every second
• Starlink connectivity in areas with poor mobile coverage
• 24/7 control center receiving collision-risk alerts
Satellite internet isn't just about connectivity. It could help make critical infrastructure safer.
@Starlink@SpaceX
#Starlink
The world's richest man could spend his Sunday anywhere on Earth.
Instead, Elon Musk is reportedly up on Starship's launch tower, personally inspecting Ship 42 after its historic return.
No boardroom. No press conference.
Just a hands-on look at the engineering behind one of SpaceX's biggest milestones.
That's a different kind of leadership. 🚀
@elonmusk@SpaceX
#Starship #SpaceX
🚨 QWEN4-MAX BREAKS INTO THE TOP 5 ON TWO ARENAS!
Alibaba's latest model is making serious progress beyond coding.
According to @DesignArena:
• Python-PPTX: #4 | 1,302 Elo
• Spreadsheet: #5 | 1,336 Elo
Compared with Qwen 3.7 Max:
• Spreadsheet: +30 positions, +379 Elo
• Python-PPTX: +5 positions, +80 Elo
Qwen4-Max is now competing alongside leading models from OpenAI, Anthropic, and Kimi.
The AI race isn't just about coding anymore. It's about creating real deliverables.
Congrats to @Alibaba_Qwen!
Source: @DesignArena
#Qwen4Max #AI
🚨 QWEN4-MAX IS TAKING AI BEYOND CODING!
Alibaba's latest demo shows AI-assisted 3D design for manufacturing.
From a simple sketch and design parameters to a detailed 3D car door model.
The potential is fascinating:
• AI-assisted product design
• Faster 3D prototyping
• Engineering workflow automation
• Applications in industrial manufacturing
AI isn't just writing code anymore. It's helping design physical products.
Watch the demo. 👀
@Alibaba_Qwen
#Qwen4Max #AI #Manufacturing
Claude users, I have a question. 🟠
Give me ONE reason to switch to Claude.
I'm exploring AI models and coding agents, and I want to hear from people using Claude every day.
Better reasoning? Coding? Reliability? Something else?
No benchmarks. Just your real-world experience.
@AnthropicAI
#ClaudeAI #ClaudeCode
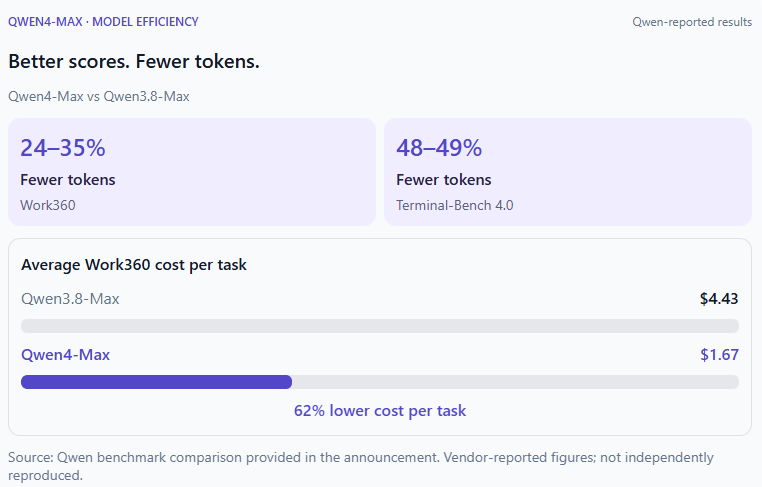
🚨 QWEN4-MAX IS GETTING MORE DONE WITH FEWER TOKENS!
Alibaba's latest model shows impressive efficiency gains over Qwen3.8-Max.
According to Qwen's evaluations:
• Work360: ~24–35% fewer tokens
• Terminal-Bench 4.0: ~48–49% fewer tokens
• Average Work360 cost per task: $4.43 → $1.67
That's a 62% reduction in cost per task, alongside higher reported benchmark scores.
The real breakthrough isn't just smarter AI.
It's getting better results with less compute.
@Alibaba_Qwen
Source: Qwen's official benchmark comparison
#Qwen #ArtificialIntelligence #LLMs
🚨 STARSHIP SHIP 42 COULD FLY AGAIN IN JUST WEEKS!
Elon Musk says Ship 42's heat shield and engines look great following inspection.
The spacecraft could reportedly be ready for another flight after a few weeks of refurbishment.
But SpaceX's ultimate goal is even bigger:
Fly. Land. Refuel. Fly again.
Airplane-like reusability, with no refurbishment between flights beyond scheduled maintenance.
That's the future SpaceX is working toward. 🚀
#Starship #SpaceX
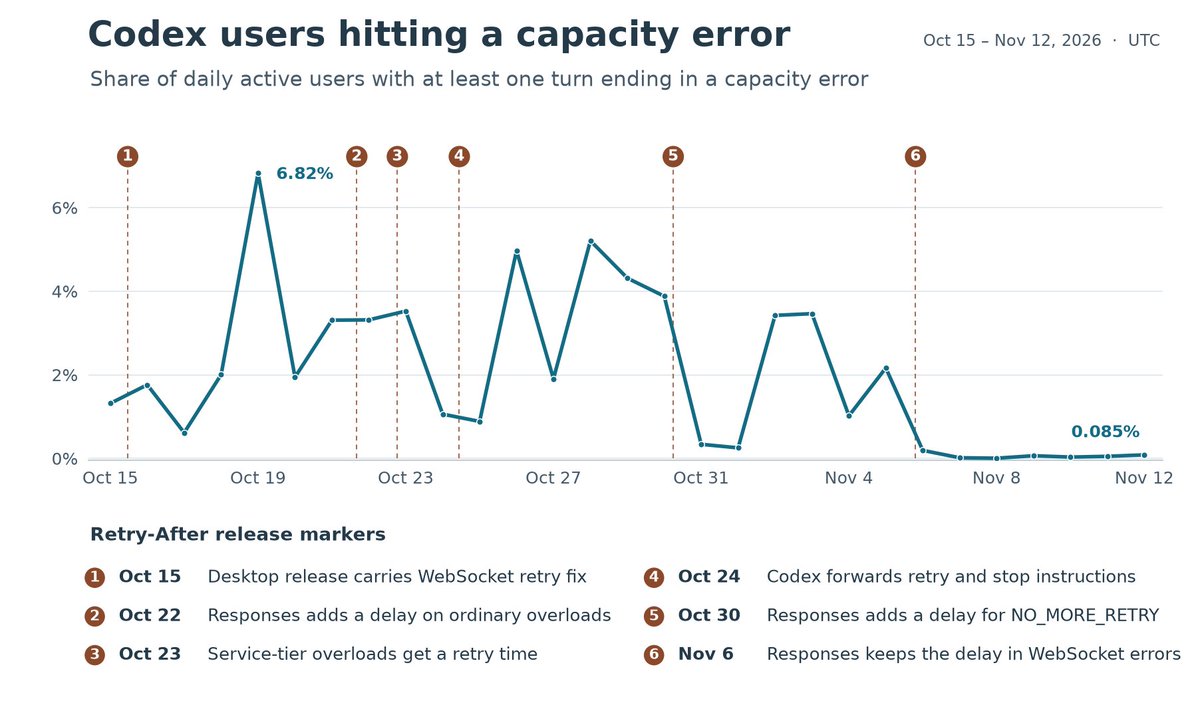
Finally, some good news for Codex users! 🚀
Tibo says the team may have fixed those frustrating “model at capacity” errors.
The chart shows a significant drop in affected sessions, from a peak of 6.82% to just 0.085%.
For developers running long coding sessions, reliability matters as much as model intelligence.
Less interruption. More building.
Great work by the Codex team! 👏
@OpenAI@thsottiaux