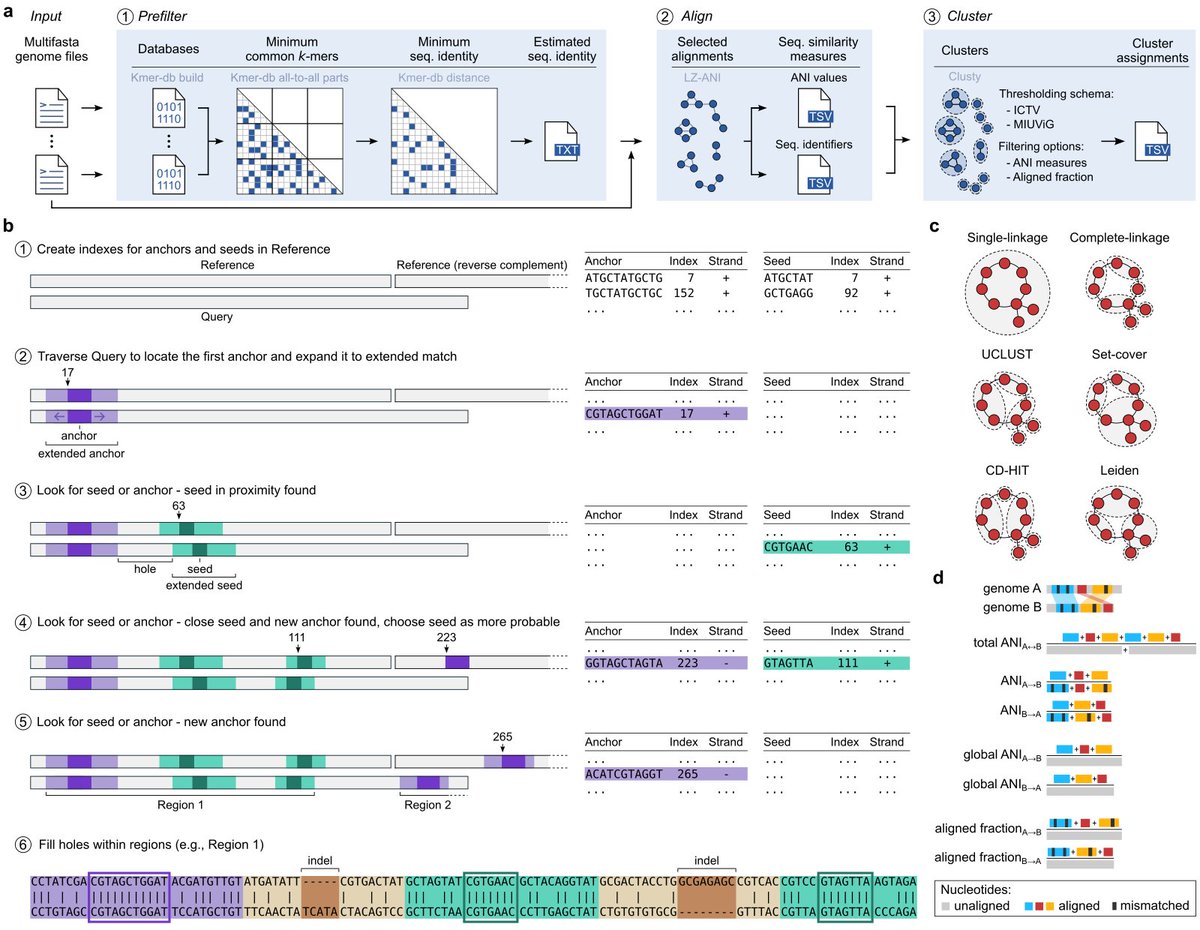
Vclust (the ultra-fast, high-accuracy tool for viral genome comparison & clustering) is now published:
https://t.co/Mytz2m8xGP
Great collaboration with @a_zielezinski, @AdamGudys, UAM guys, and Bas E.Dutilh
I am happy to announce that ProteStAr, our compressor of CIF/PDB files with 3D atom coordinates, is now published at Bioinformatics. With this, you can store the whole ESM Atlas or AlphaFold DB in a few files (rather than 200M+) with fast random access.
https://t.co/tUlwIbZ9HX
Excited to share Vclust! It's a fast and accurate tool for calculating intergenomic similarities (like ANI) and clustering virus/#phage genomes/contigs according to ICTV and MIUViG standards.
💻 Tool: https://t.co/vaP81tVp6T
📄 Preprint: https://t.co/PkUXLPhvsS
Thread! 1/6 ↓
After a few years of development, Kmer-db v.2, our tool for finding similar sequences in large collections of genomic data (even millions of viral genomes), is ready.
If interested, take a look at the GitHub repo and related paper. https://t.co/0Z81KBlcbw
https://t.co/WWLWlYiMeh
Clustering large datasets can be challenging. Fortunately, even slow methods can sprint for sparse similarity matrices. Clusty offers s-, c-link, uclust, set-cover, cd-hit, leiden. The paper shows an application for 15M+ sequences.
https://t.co/xOUUSotWoh
https://t.co/WWLWlYieoJ
Thinking of aligning a million of sequences? Take a look at our @COSB_CRSB review on ultra-scale protein sequence alignments. @SantusLuisa@edgano90@sdeorowicz and @cnotred - great pleasure to work with you!
https://t.co/sbVIztOxz9
NOMAD2 is an unsupervised, reference-free, ultra-fast next generation of NOMAD, revealing new insights into cancer transcriptomes. Joint work with @salzmanlab. Many thanks to all for great collab!
https://t.co/x25YvXXhdh