Introducing Gemini 3.8, our best reasoning & coding model yet.
By leveraging long-running agentic loops, we’re building on the momentum of 3.7 Flash from just three weeks ago to release two new 3.8 variants:
Meet Gemini 3.8 Flash and Gemini 3.8 Flash Cyber 🧵
Introducing GLM-5.3: Built to Code. Ready for Cyber Defense.
- Top-tier coding and agentic capabilities, achieved through post-training on the 743B base model
- A major leap in cybersecurity, setting a new standard among open models
Tech Blog: https://t.co/ekQkO83jCv
🧩 DeepSeek Harness v0.1 is now available in Developer Preview!
🔹 We’re opening it up to developers building agent harnesses worldwide and open-sourcing the codebase in MIT license.
🔹 Powered by the Cordis meta-framework, DeepSeek Harness is an agent harness built around one core idea: Everything is a plugin. Models, tools, skills, sessions, sandboxes, filesystems, loops, orchestration, and UI are ALL implemented as plugins, and can be mixed, matched, replaced, and extended.
Try it now!
https://t.co/2YWSvJHhKA
🚨 KIMI K4 LEAK: MOONSHOT IS ALREADY SCALING PAST K3.
Moonshot is reportedly already preparing something significantly larger.
• Moonshot is reportedly seeking more NVIDIA Blackwell capacity for K4 training
• Internal references to K4 have already surfaced
• New MoonEP infrastructure appears designed for scaling larger MoE systems
• Some reports speculate 5–6T parameters, but that's still unconfirmed
👀 Vepsi's Bet: 75% chance K4 ends up substantially larger than K3.
🧠 Reason: The Blackwell push and new infrastructure are stronger evidence than the speculative parameter number.
K3 barely arrived and Moonshot is already cooking K4.
📢Meet Qwen3.8-Max — our most capable model to date.
Next week, the open weights of Qwen3.8-Max will be released, and Qwen3.8-27B is also going open-weights to meet you all!🎉
Qwen3.8-Max, a new bar for coding and cowork at 2.4T parameters:
- Autonomous coding: 10+ days of self-evolving development, from empty folder to production without hand-holding, complete project trace in the GitHub:https://t.co/iVHZWQoeSo
- Real work, real results: Production-quality deliverables across hundreds of professions.
- Long-horizon mastery: System-level autonomous planning with closed-loop adaptive learning, driving 500+ turns of chip design optimization and 365 days of e-commerce strategy.
- Native multimodal intelligence: Vision isn't just input — it's a continuous feedback loop for planning, execution, and self-correction.
💰Pricing:
Input: $2.0 / M tokens
Output: $6.0 / M tokens
Implicit Caching: $0.25 / M tokens
Start building with Qwen3.8-Max! 🚀
📖 Blog: https://t.co/iwjmQxLBof
✅ Qwen Studio: https://t.co/4V2pFvDovG
⚡ API: https://t.co/gAGqaLQGbN
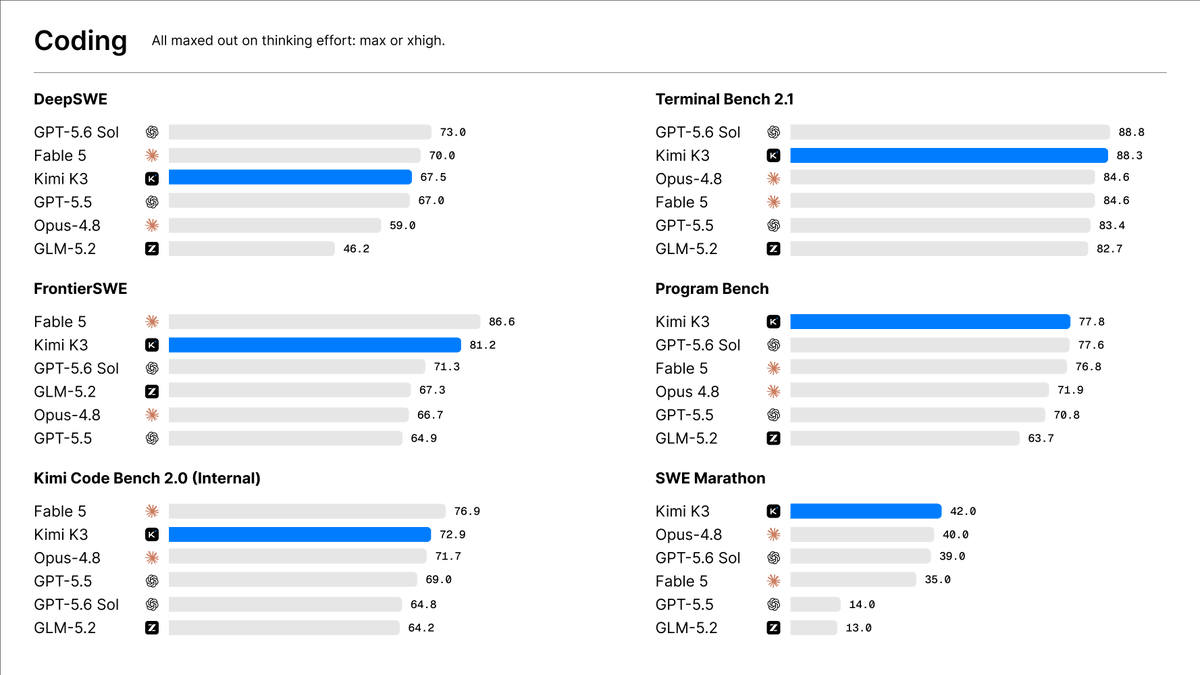
Releasing the model weights and technical report of Kimi K3.
Kimi K3 is our most capable model: a 2.8T MoE model with native visual understanding and a 1M-token context window.
New model architecture: 2.5x the intelligence per unit of compute, not just more params.
Alongside Kimi K3, we're opening up more of the stack behind it — high-performance attention kernels, MoE communication library, and infrastructure for running agent environments at scale.
Model weights: https://t.co/7m7eEg6Y0B
Tech report: https://t.co/yeu6cjpMCT
Tech blog: https://t.co/YTfiMSNM1f
Qwen3.8 is launching and going open-weight soon!🌐
With a massive 2.4T parameters, this model is continuously evolving. We believe it’s one of the most powerful model available today, compatible to leading frontier AI models , second only to Fable 5.
You don't have to wait to test it. Just now, the Qwen3.8-Max-Preview made its debut on Alibaba’s Token Plan, Qoder, and QoderWork. Be among the very first to try it out.
Can't wait to hear what you build. Stay tuned! 🚀
Token Plan
international:https://t.co/YRvcGdB9Bv
China:https://t.co/PKMUNwUuRp
Introducing Kimi K3: Open Frontier Intelligence
🔹 2.8 Trillion Parameters, 1 Million Context, Native Multimodal
🔹 Kimi Delta Attention enables up to 6.3x faster decoding in million-token contexts
🔹 Attention Residuals deliver ~25% higher training efficiency at <2% additional cost
🔹 Built for long-horizon agentic coding and self-evolving workflows
Kimi K3 is now live on on https://t.co/zrk6zZxZUo, Kimi Work, Kimi Code, and the Kimi API.
Open Weights by July 27, 2026.
🔗 API: https://t.co/XCrgjXAqMw
🔗 Tech blog: https://t.co/YTfiMSNM1f
Artifacts in Claude Code are now also available on Pro and Max plans.
Ask for an artifact, Claude writes the code, publishes it live to claude.ai, and updates it in real time while it keeps working. Pages are private to your account and fully self-contained.
Introducing GLM-5.2: Frontier Intelligence, Open Weights
- Significant improvements in coding and agentic tasks
- Strong long-horizon capabilities with a 1M context window
- Two levels of reasoning effort: GLM-5.2 (max) pushes the limits, while GLM-5.2 (high) strikes a strong balance between performance and token efficiency
- MIT-licensed open weights
- Same API pricing as GLM-5.1
Tech Blog: https://t.co/LAsxUdN0JZ
Weights: https://t.co/g0A1C4UWx4
API: https://t.co/Kc3E22cbN7
Coding Plan: https://t.co/Nk8Y98HNhU
Chat: https://t.co/WCqWT0qCQb
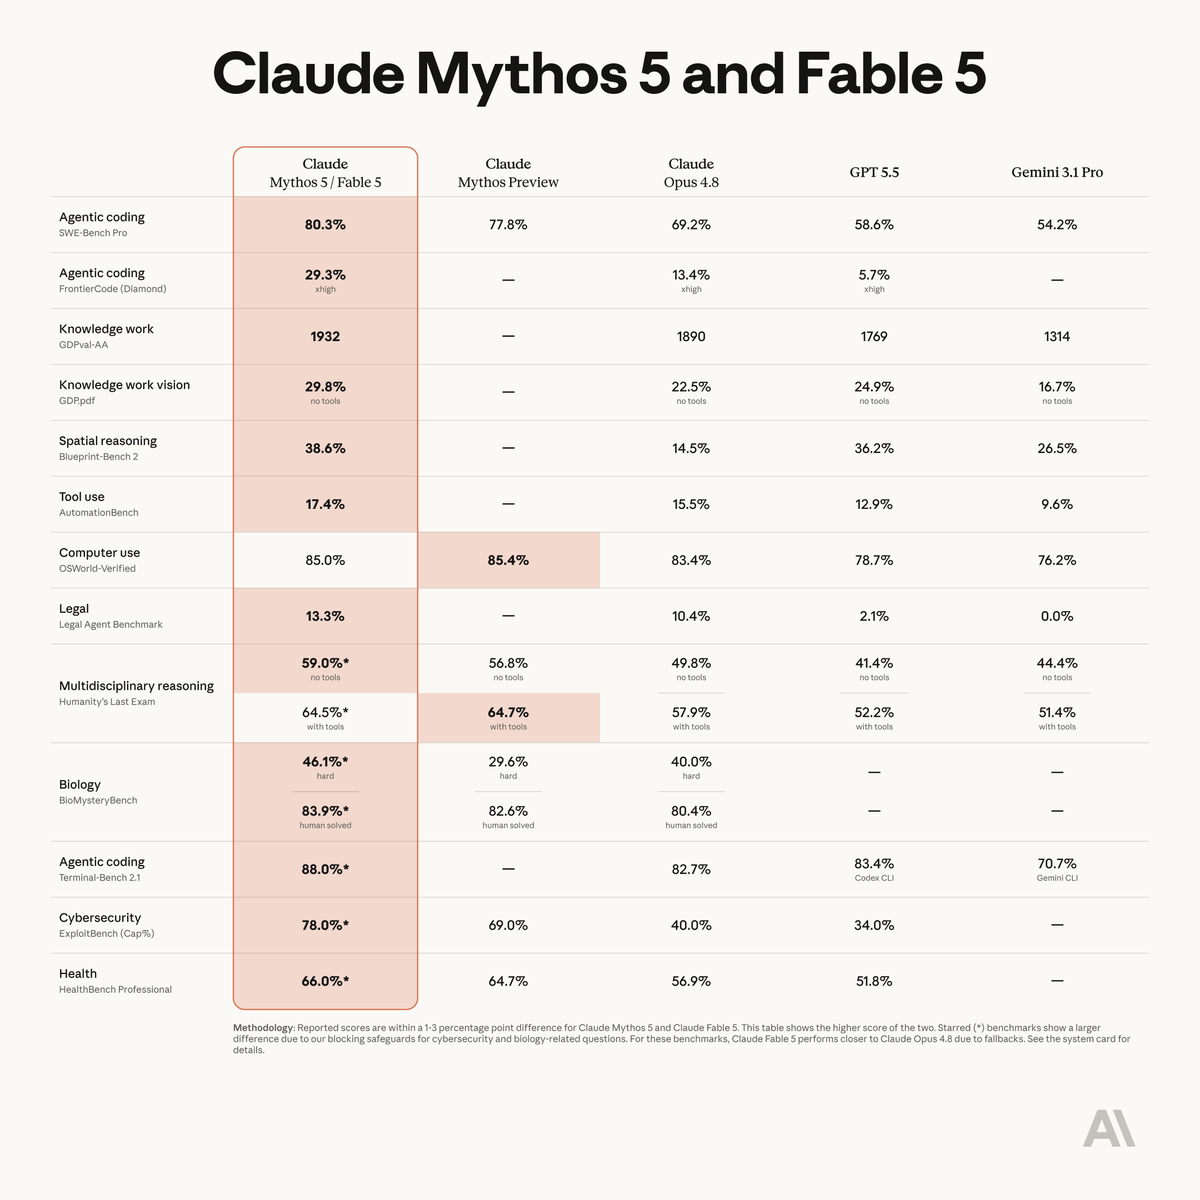
Introducing Claude Fable 5: a Mythos-class model that we’ve made safe for general use.
Its capabilities exceed those of any model we’ve ever made generally available.
Fable 5 is state-of-the-art on nearly all tested benchmarks, with exceptional performance in software engineering, knowledge work, scientific research, and vision.
The longer and more complex the task, the larger Fable 5’s lead over our other models.
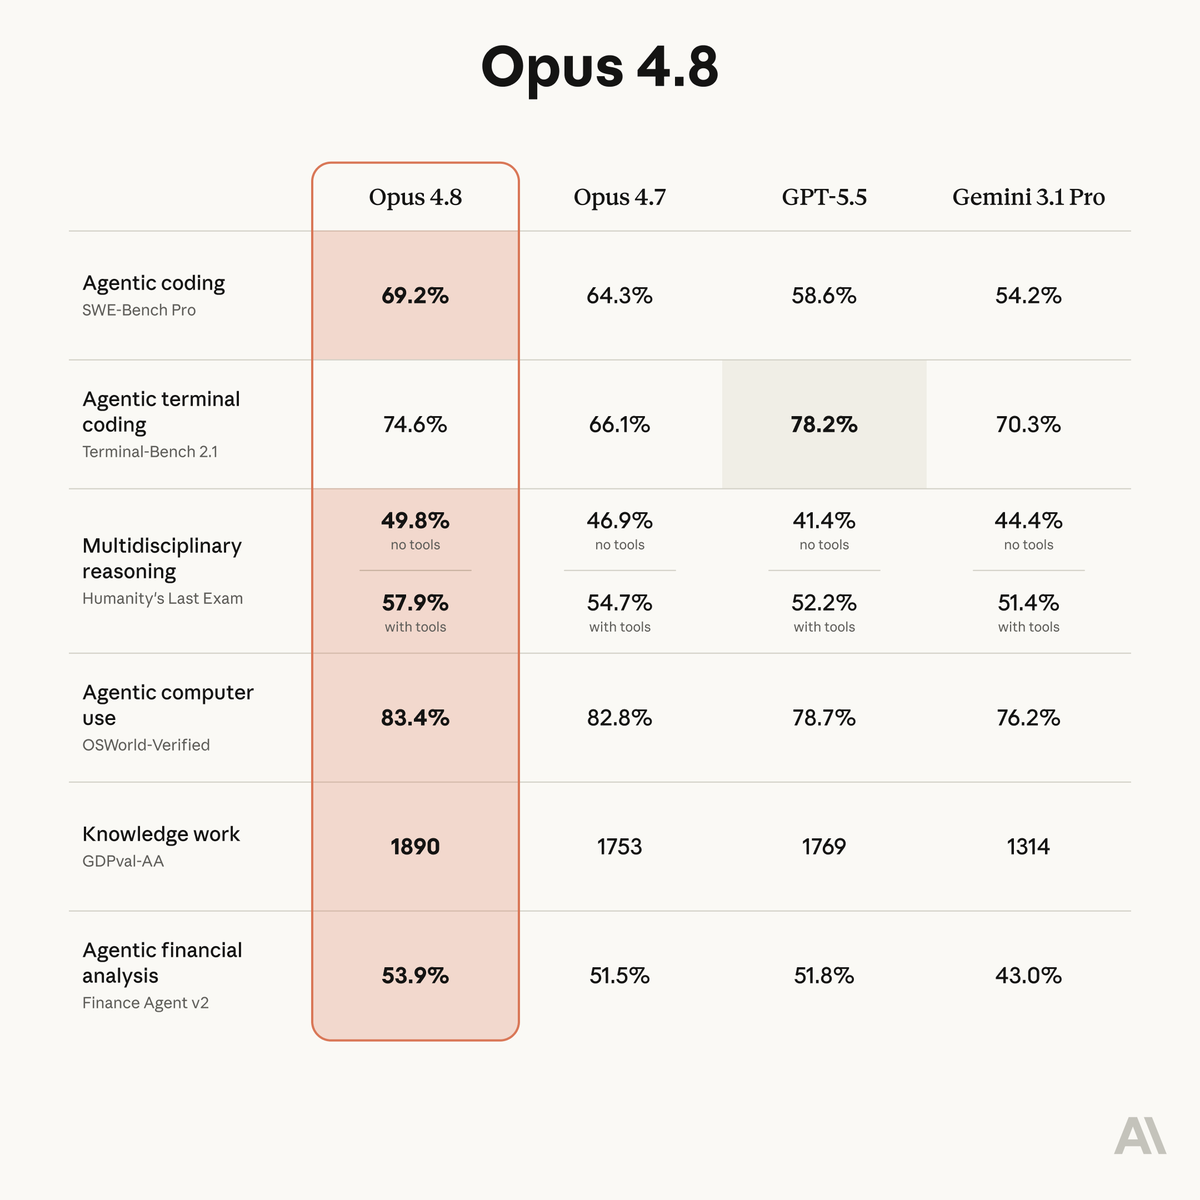
Introducing Claude Opus 4.8: it builds on Opus 4.7 with sharper judgment, more honesty about its own progress, and the ability to work independently for longer than its predecessors.
Available today at the same price.
🚀🚀Qwen3.7 Preview lands on Arena !
Here come Qwen3.7-Max-Preview & Qwen3.7-Plus-Preview. Alibaba now #6 lab in Text, #5 in Vision.⚡️⚡️
Can't wait to release Qwen3.7 series models!Stay tuned! @arena