Conventional model routing sucks. It passes benchmarks but fails to write code you'd actually merge.
Introducing Devin Fusion, a new hybrid-model harness for agentic coding.
In testing, it reduces the cost of Fable-level intelligence by 35% and still feels good to use.
“Loop engineering” is a hot buzzphrase after mentions of it by Boris Cherny (Claude Code’s creator) and Peter Steinberger (OpenClaw's creator) went viral on social media. Loops are now a key part of how we get AI agents to iterate at length to build software. In this letter, I’d like to share my 3 key loops, shown in the image below, for building 0-to-1 products. These loops guide not just how I build software, but also how I decide what software to build.
Agentic coding loop: Given a product specification and optionally a set of evals (that is, a dataset against which to measure performance), we can have an AI agent write code, test its work, and keep iterating until the code is bug-free and meets its specification. This idea of closing the loop took off around the end of last year, and it has been a game changer in enabling coding agents to work longer productively without human intervention. For example, over the weekend, I was building an app for my daughter to practice typing, and my coding agent could easily work for around an hour, using a web browser to check what it had built multiple times before getting back to me, without needing my intervention.
The engineering loop executes quickly. Every few minutes, the coding agent might build and test a new version of the software. I hear frequently from developers who are finding new ways to engineer more effective engineering loops. This is an active area of invention!
Developer feedback loop: In this loop, a developer examines the current product and steers the coding agent to improve it. Last year, a lot of developers (including me) were acting as the QA (quality assurance) function for our coding agents, manually finding bugs and then asking the agent to fix them. But with coding agents much more able to test their own code, the amount of time we need to spend on this function has decreased significantly. This allows us to make higher-level product decisions, such as what key features to offer, where the UI needs improvement, and so on.
The developer-feedback loop operates over time intervals between tens of minutes and hours — that's how frequently a developer might review a product and give feedback. In the case of the typing app, I changed my mind a few times about the visual design, what cat costumes she can unlock as she learns (she loves cats), and the user flow for a grown-up to log in and steer the child's learning experience.
When a developer has a clear vision for what to build, it is still a lot of work to translate that vision into a specification for a coding agent to implement. Further, after the developer has seen an implementation, they might update (or perhaps clarify) the spec to steer it toward what they want. If you find that the system repeatedly runs into certain problems, building a set of evals for the agent becomes useful.
AI-native teams are increasingly using AI to help shape product direction, for example, automating the gathering and analysis of usage data, summarizing written and verbal customer feedback, or carrying out competitive analysis. However, for pretty much all the products I’m involved in, I see humans as having a significant context advantage over current AI systems — we know a lot more than the AI system about the users and the context the product has to operate in — and thus humans play a critical role. Many people describe this human contribution as “taste,” but I prefer to think of it as humans having a context advantage, since that gives us a clearer path to helping AI systems get better. This also speaks to why this step can’t be automated: So long as the human knows something the AI does not, human-in-the-loop is needed to to inject that knowledge into the system.
External feedback loop: This includes a wide range of tactics like asking a few friends for feedback, launching to alpha testers, or putting the code into production with A/B testing. These tactics are usually slow, rarely taking less than hours and sometimes taking days or even weeks. This data informs the developer vision, which in turn continues to drive the detailed product spec, which in turn drives the coding agent.
With coding agents speeding up software development, more engineers are starting to play a partial product management role. For many engineers who are growing into this role, the hardest part is shaping the product vision and striking a balance between building (bridging the gap between vision and spec) and getting user feedback to evolve the vision. It is important to do both!
I will write more about how to do this in future posts, but for now, I find it encouraging that engineers are playing an expanded role (just as product managers and designers now do more engineering).
[Original text: The Batch]
We now support rich formatting for all chatbots.
Tables, nested lists, inline media, formulas, headers and more — right in Telegram messages.
🔨 Start building! Docs: https://t.co/zgzPOOUJF5
We talk a lot about how important it is to set up self-verification loops. Especially in the age of powerful models that can run for long periods of time, self-verification is a key ingredient that enables the model to run for much longer, delivering a result that is closer to what you intended, so you can do more without having to constantly check in on Claude as it works.
@delba_oliveira gives a great breakdown of what that looks like and why it matters
Hermes Agent now has multi-agent via the Kanban, new in v0.12.0.
Agents claim tasks from a board, work in parallel, and hand off when blocked. You watch progress and unblock from one easy view instead of juggling terminals.
We asked it to plan and make this video about itself:
@NousResearch@Kimi_Moonshot Language creators spend hours hand‑editing captions with pronunciations. Hermes remembers how you do it, Kimi does it in seconds.
Send a video and Hermes embeds phonetic captions in minutes. Sauce: SayWithMe 👉 https://t.co/8C5yXRjyYc
The Hermes Agent Creative Hackathon starts now
16 Days, $25k in Prizes
Presented by @Kimi_Moonshot & @NousResearch
For the tinkerers pushing Hermes Agent into creative domains: video, image, audio, 3D, long-form writing, creative software, interactive media and more.
Show us what your Hermes Agent can do.
Details Below ↓
TIL: you can use `.git/info/exclude` instead of `gitignore` to ignore files specific to your own machine (e.g. graphifyy output that I'm testing out in the repo)
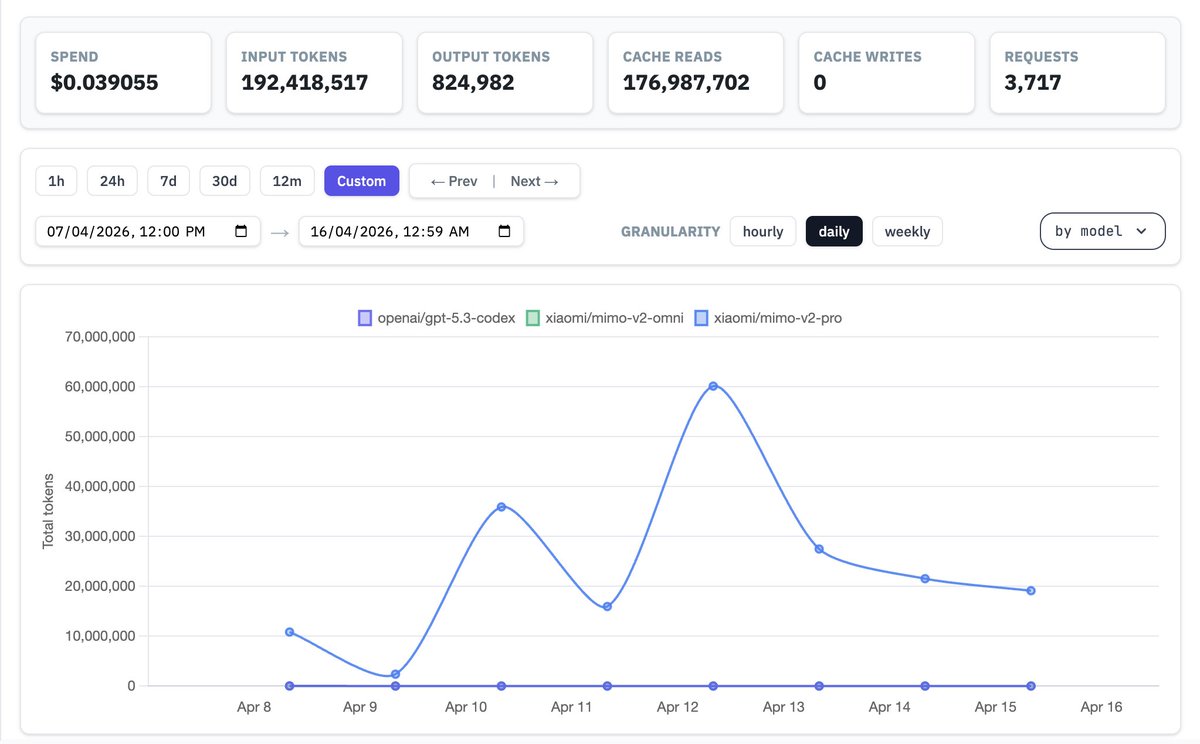
2️⃣Realised I had setup Openrouter too so decided to check the usage
Thankfully I set a spend limit as I thought pointing Herms to the free API endpoint would mean that, well, usage would be free
Don't get their free tier and why I have to set limit as $0.001 (lest unlimited)
4️⃣ Thoughts on state of open source
got Hermes to search up issues and PRs on various topics for Hermes itself, and the situation seems surprisingly messy and disorganized, but perhaps it's "classic" OS, as my Hermes claims
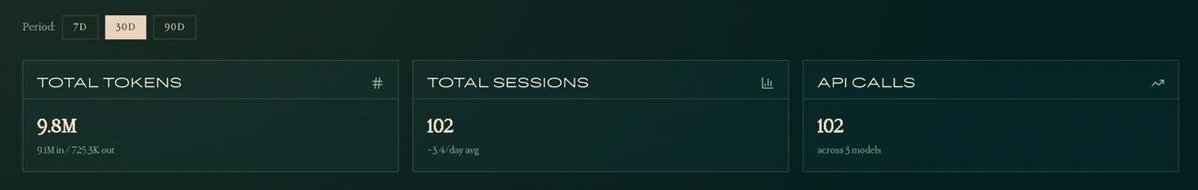
3️⃣ Was curious about the high input token usage so I consulted Hermes about it, and suspected the growing session lengths and intermediate results playing a key role, with prompt caching perhaps just affecting costs
Some Github issues should discuss this topic in greater depth
2️⃣ I might have got a little too used to having Hermes at my fingertips
Forgot to plug in the power and it died all of a sudden, leaving a very palpable gap that I felt
1️⃣ Updated Hermes to v0.9.0 for two key features (which should be default)
1. backup: at least some form is necessary given all the skills and memories it changes
2. dashboard: with all its power, everything about Hermes should be transparent, and especially in realtime
5️⃣ To keep your agent alive 24/7,
1. Turn ON prevent automatic sleeping
2. ALWAYS wake for network access
and remember to keep your device plugged in for charging