DeepSeek latest funding round show SMIC, CXMT, Gigadevice investment among Semi industry + CATL, Tencent, major telecoms, Geely, Midea & Luxshare among tech industry & CSPs.
Investment are made by DS users & those to participate in DS's future chip design. Word is DS & Ascend team are working together on new chip design. It's likely that in the future, DS will do its own chip design w/ its AI models, but the manufacturing requires major domestic chip firms like Hisilicon, SMIC, CXMT & GD. AI data center build out require CATL & Luxshare.
So many of the fund raisers are strategic in nature & show where DeepSeek wants to go in its path toward building own data centers & chips that best suit its needs.
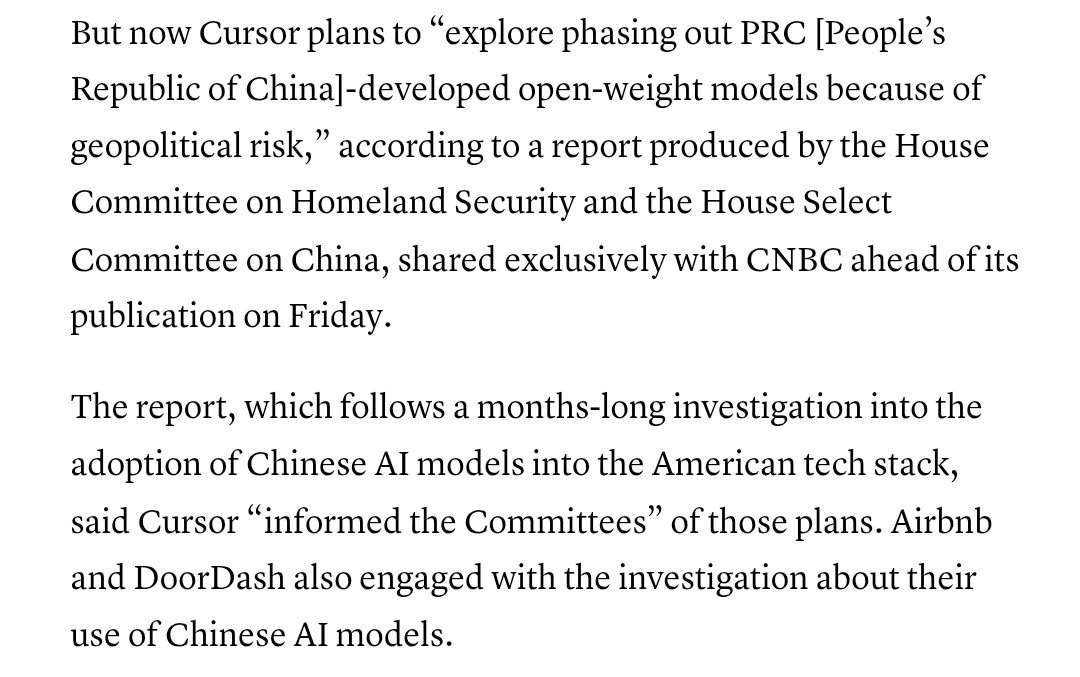
Cursor has told Homeland Security they are considering phasing out *all* China developed open-weight models because of the 'geopolitical risk.' The report will be published by multiple House committees later today. This is a huge indicator of future regulatory direction!
JUST IN: Nvidia ($NVDA) interim CEO Colette Kress promises company-wide pay raises and additional equity grants months ahead of schedule as the chipmaker scrambles to retain employees following Jensen Huang’s departure, according to WIRED.
Jensen Huang was building an open AI ecosystem that threatened Anthropic's business model. His ouster changes the stakes of its IPO. https://t.co/MBgw0FhRFy
Jensen Huang was building an open AI ecosystem that threatened Anthropic's business model. His ouster changes the stakes of its IPO. https://t.co/MBgw0FhRFy
AI X community loves claiming Huawei clusters are years behind NVIDIA on training, yet SLAI’s SLAI T-Rex receipts (arXiv:2607.20145) on DeepSeek-V4-Pro (1.6T MoE on Ascend CloudMatrix 384 / 910C NPUs) tell a very different story.
Out of the box, the open-source recipe choked at 11.67% MFU: comm ate 52.2% of kernel time (mostly TP/DP AllReduce at 48.4% and pipeline P2P at 36.7%, while MoE all-to-all was just 14.5%), and 91.3% of the 206,503 kernel launches were tiny eager PyTorch ops (<20 µs) leaving vector units asleep at ~15%.
Instead of blindly copying NVIDIA recipes like DualPipeV (which doubles resident memory when NPUs are already redlining at 51.7–54.6 GB peak), they switched to VPP + Parallel Folding (TP=2 attn, ETP=1 MoE), ran shared-expert forward before before_ep_alltoall to eat the sync stall, streamed AdamW states to pinned host RAM, and wired an Operations Research solver inside an LLM kernel agent (AuraKernel) to tile AscendC (RMSNorm fwd 11.9×, Limited SwiGLU fwd 8.86×).Result: 34.22% MFU (2.93×) and DeepSeek-V4-Pro jumping from 70.16% to 77.33% on Operations Research.
For context, production frontier MoE training runs on H100/H800 clusters typically land right in that ~35–42% MFU band.
The software moat is way thinner than Wall Street thinks !!!
https://t.co/6rpZ4IsElr
@ruima There’s always this side of things though, not obvious to me that this is some 2016 moment. Any Chinese AI strategy relying on NVIDIA etc… should have a low EV given binary outcomes
With the US shutting down remote access to overseas Nvidia Blackwell clusters yesterday, new supply-chain leaks and code strings show how DeepSeek is building DeepSeek V5 on Huawei Ascend 950DT chips.
In closed-door briefings, Liang Wenfeng gave the exact hardware math: Huawei's Peerium optical bus links 128 to 384 Ascend cards at 800 GB/s rack-to-rack so 'whatever GB300 can do, Huawei's Supernode can do with the exact same latency the only cost is replacing 1 Nvidia GPU with 4 Huawei cards,' powered by cheap green electricity at DeepSeek's Ulanqab data center in Inner Mongolia with Huawei's R&D team stationed on-site in Hangzhou.
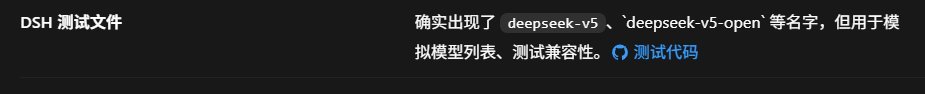
Today, developers also spotted 'deepseek-v5' and 'deepseek-v5-open' in DSH test files as China Telecom opened a record RMB 25.79B ($3.58B) Ascend supernode tender.
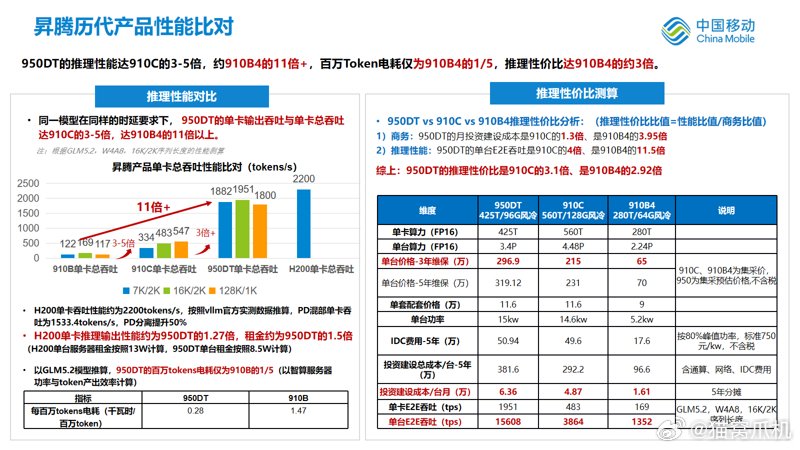
A while back, I was told Ascend-950 series was really good, better than hopper. Here is some China Mobile result measuring 950DT vs 910 series & H200 for inference on GLM-5.2.
Result showed 950DT was 11x 910B & 3x 910C in tps. About 14% lower than H200. So despite the lower TFLOPS & higher cost (1.3x of 910C), it actually far surpassed the latter in actual inference performance.
This shows that a 64-card cabinet w/ high speed interconnect & larger + higher bandwidth HBM is far more costly & more performant than the compute unit performance.
When factoring in rental cost, 950DT economically wins against H200.
That's why Chinese AI labs want B300, not H200. Even 950DTs have more favorable economics than H200.
Reminder that HW/ascend production supports the entire Chinese AI supply chain, whereas Nvidia & google do not.
The data centers in SEA that would lease compute to Chinese hyperscalers are also willing to buy Chinese AI SuperNodes. They can keep the Nvidia they already have + buy Chinese chips for the rest.
Ppl don't get it. We are already over-building this shit. They don't provide local jobs.
It's a mkt rn heavily skewed toward costumer side of things. The data center operators don't have a business plan w/o the customers they have signed LTA with.
Revolut has switched to Chinese models. GLM-5.3, which it now serves using 56 Nvidia B200 GPUs. 90% cheaper, 60% improvement in coding time and a 70% improvement in lead time.
https://t.co/Q1SbjJ4eXQ
You work your ass off solving really hard problems day after day for decades, and this is what you get: anyone could have done it.
As an investor, I can tell you the limiting factor isn't investment. It's founder ability.
@samstein@DeanBaker13 He’s there to invent shit not be an angel, that moralistic preaching we leave to DC where you accomplish nothing and tell everyone how talk/live
There’s a little too much hatred, dismissing of actual engineering genius in this country. We’ve handed the political apparatus to the most cynical, pessimistic people. It’s sad actually
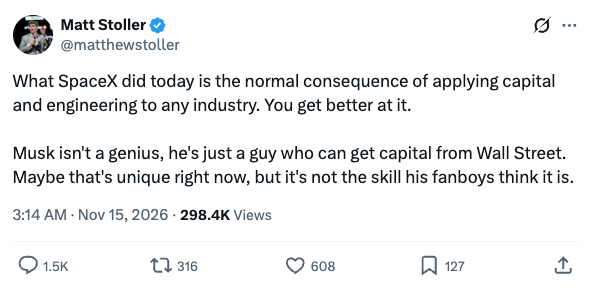
What SpaceX did today is the normal consequence of applying capital and engineering to any industry. You get better at it.
Musk isn't a genius, he's just a guy who can get capital from Wall Street. Maybe that's unique right now, but it's not the skill his fanboys think it is.