En el 2007 pedía prestada una PC estudiar a un familiar, en el 2010 mi madre hizo el esfuerzo de comprarme una PC que me duró muchos años, ahora tengo la oportunidad de gozar de un hermoso equipo y TODAS estas etapas tiene un factor en común. El apoyo incondicional de mi madre
👋🏼 ADIÓS A CAPCUT.
Ahora puedes convertir un vídeo largo en varios Shorts listos para publicar.
Y sí, lo hace automáticamente.
Se llama OpenShorts y es open source.
¿Lo mejor?
→ Encuentra los mejores momentos del vídeo
→ Genera clips en formato vertical
→ Añade subtítulos automáticamente
→ Prepara contenido para Shorts, TikTok y Reels
Todo dentro de una misma herramienta.
Ideal para reutilizar podcasts, entrevistas o vídeos largos sin tener que revisar y editar cada fragmento desde cero.
Repo en comentarios 👇
Ahenk'i yayınladık: açık ağırlıklı, Türkçe metinden sese (TTS) modeli.
Sayıyı, tarihi, fiyatı ve telefon numarasını doğru okuyor. "mı" ile biten sorularda sesi yükseliyor. Talimatla kızgın, neşeli ya da şaşkın konuşuyor, gülebiliyor.
Videodaki bütün sesler Ahenk'in. Sesi açın.
Left: YOLO26n fine-tuned 50 epochs on PPE data
Right: stock YOLO26n finds people, a local 27B vision model (Jev) judges each crop. Zero-shot, no training.
This is probably the future of computer vision.
built an arcade to play with the different system one providers out there
attention is all you need? here's how clef, jev and luna decide what they should pay attention too
clef find me boring... luna not
try it out at https://t.co/HSlCxjvTTg more in 🧵
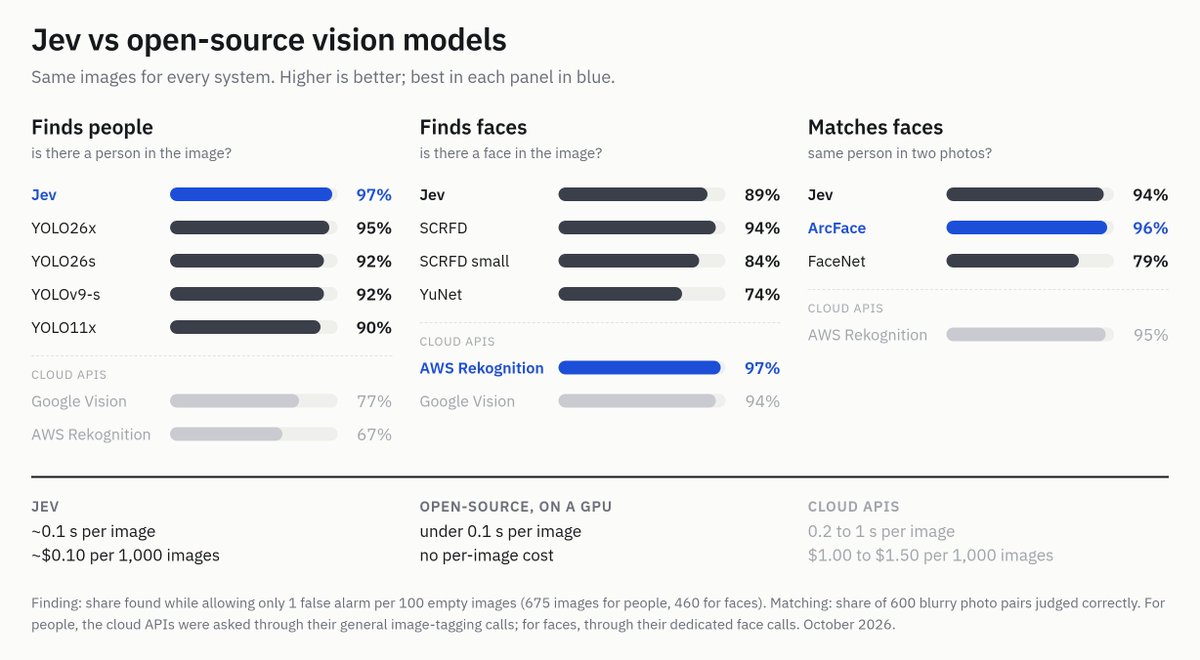
so yes, it stand very well against different vision models for people detection.
it's a bit of imperfect science, some of the tools for people detection are meant to be done on video stream, not on video frames, but the fact jev can do it on a single video frame, and with that level of accuracy for both finding people, matching their faces and recognizing known folks (i.e family members) is quite impressive.
Turn any camera into a stream of decisions.
Every second, d3-edge (0.6B) watched this rescue and answered 8 plain-English questions in ~0.1 s.
New questions, new scene: pet cam, bird feeder, doorstep. What would you ask?
https://t.co/GBVE6aUdz8
#Jev#Decision
Small decision models can be insanely good when fine-tuned.
We played with d1-omni-600M and it can destroy any model on the games + format (state, input) you train it on.
Jev’in yeni güncellemesiyle birlikte artık realtime görüntü işlemek mümkün olabiliyor.
Önceden sadece bu videoda birisi var mı yok mu diye sorabiliyorduk.
UN CHINO HA REVENTADO EL OCR:
1,2 MILLONES DE DESCARGAS EN UN MES
Baidu acaba de liberar Unlimited-OCR.
Gratis, pesos abiertos, licencia MIT.
¿Qué hace?
Le metes un documento, una foto, un escaneo, un PDF entero y te lo devuelve como texto limpio y estructurado.
Tablas, fórmulas, el orden de lectura, todo.
Lo diferente está en el nombre: Unlimited.
Los modelos de OCR se ahogan con documentos largos.
Este está hecho para tragarse un PDF entero de una sola pasada, página tras página, sin perder el hilo.
Ellos lo llaman “parsing de horizonte largo”.
→ Documentos con texto, tablas y fórmulas, en estructura
→ Multipágina y PDF de corrido
→ Multilingüe
→ Solo 3.000 millones de parámetros: ligero, corre en una GPU normal
→ Y lo puedes levantar en local con vLLM, SGLang, Ollama o LM Studio
Es la respuesta de Baidu a DeepSeek-OCR, y lo dicen abiertamente: querían llevarlo un paso más allá.
4.400 likes en Hugging Face. 1,2 millones de descargas el mes pasado. MIT.
Link en los comentarios 👇🏻
You can now run the biggest open AI models on a 4 GB graphics card.
AirLLM loads a model one layer at a time instead of all at once, so it fits in a tiny amount of video memory:
→ Kimi K3, 2.8 trillion parameters, in 3.72 GB
→ DeepSeek-V3, 671 billion parameters, in about 12 GB
→ 70B models on a single 4 GB card, without quantizing them
→ It can now fine-tune a 125B model in under 6 GB, too
pip install airllm, then load almost any model from Hugging Face in one line.
It trades speed for memory, and you need plenty of disk space for the model files.
38K+ GitHub stars. Apache-2.0.
https://t.co/jnTebGBnB7
Bread counting on a conveyor belt using @ultralytics YOLO26 🥪
This system can offer a detailed report on bread quantity, enhancing production and inventory management.
You can also use it for multi-object detection to distinguish among various products, sizes, and packaging types.
#MLops #MachineLearning #Logistics
🚨 JUST LAUNCHED: Bonsai 2 from @PrismML.
Open-weight ternary models in 2B, 4B and 9B, small enough to run on a phone. The 2B hits 90 tokens/sec on iPhone 17 Pro Max, with reasoning, vision and tool calling all on-device.
You can try Bonsai 2 9B today on @DarkbloomAI, where the first 100 people get 250M free tokens.
And we’re making it faster on @YukonResearch.
Bonsai 2 9B runs at 170+ tokens/sec at launch.
There are two tracks, Apple Silicon on https://t.co/uFpHiT9o9m and NVIDIA DGX Spark on https://t.co/tuLkHUh7Qx.
To join, pick a track, point your agent at it and submit a faster run.
Every new best is open for anyone to build on.
How do we do to track an object accurately with a camera moving? Meet Camera Motion Compensation!
In practice, you can use BoT-SORT in trackers with a 1 line change:
https://t.co/GPplmZJxmX
The new Bonsai 2 2B model reaches up to 120 tk/s on iPhone 18 Pro
It’s better than Qwen 3.5 2B (4-bit) and runs twice as fast while using almost half the memory