Bonsai 2 9B is LIVE on Darkbloom from day one.
@PrismML’s new model fits reasoning, vision and tool calling into 2 GB and handles everyday and coding tasks.
It runs on a network of Macs owned by everyday people.
The first 100 people get 250M free tokens at https://t.co/5rrYltKokD.
Want it faster? Bonsai 2 9B is also an open challenge at https://t.co/TtSOJoVO8F and https://t.co/EksX77xRkg on @YukonResearch.
Today, we’re releasing Bonsai 2 2B, 4B, and 9B.
Based on Qwen3.5, these new ternary models bring stronger reasoning, visual understanding, and tool calling to compact footprints designed for everyday devices:
• 2B: 0.43GB
• 4B: 0.95GB
• 9B: 2.0GB
For this release, we focused on what makes small models useful as local assistants: following instructions, avoiding repetitive loops, calling tools on mobile devices, and giving useful answers without unnecessary output. The 9B model uses roughly 40% fewer tokens on standard instruction-following and everyday math tasks. Solving the Riemann hypothesis can wait.
These models are successors to our first-generation Bonsai 1.7B, 4B, and 8B, and provide a foundation for bringing practical agentic functionality to local applications on personal computers, phones, and wearables.
The Bonsai 2 family now includes four sizes spanning 2B to 27B parameters. Developers can choose the balance of capability, memory use, and responsiveness that fits their application and hardware.
Available today under Apache 2.0.
Right before my first wedding anniversary, I made a quick pit stop to give my first public talk on Darkbloom. It's pretty rough, but I went into detail about our technical intricacies. I covered how we ensure we can do inference that is 1) distributed, 2) private, and 3) low on performance degradation. Historically, it's been easy to get two out of three, but our amazing @gajesh and team pulled off all three. So far, we've processed more than 1 trillion tokens on OpenRouter.
I also shared about our plan to utilize more than the GPU part of the Macs and how we are expanding into general compute. Most of our work are built on top of amazing innovation from the Apple hardware and software security team. They've built the perfect machinary to make Darkbloom possible!
🖥️ The Mac you're not using could be serving AI models to other people, and @0xkydo showed us how @darkbloomai already does it: 1,311 Macs in 59 countries handled 151M requests in 30 days, using Apple's Secure Enclave and App Attest to hide your prompt from the Mac owner ⬇️
Darkbloom (decentralized secure inference running on home Macs, paying the user for their compute) is doing wild and innovative stuff. Sam Altman would be pleased to see idle RAM being put to use! 😀
If you're looking for MacOS sandboxes or Linux sandboxes with Apple silicon, let us know.
We have 1,100 Mac with Ultra, Max and Pro chips and mostly new generation (M3, M4, M5).
75% cheaper than Blacksmith and 50%-2x faster.
You can iOS CI, Mac RL. All kinds of stuff.
Really happy to see the response to the Darkbloom update :)
A few people asked: “Won’t the new sandbox providers just undercut you?”
The simple answer: we’re giving your agents a Mac.
We aren’t stopping at 2-4 vCPUs. We want to offer 8, 16 or 32 physical CPU cores, plus Apple GPUs, for agents doing research and complex work.
Unlike inference alone, these workloads can put much more of the machine to use. We think there’s a real opportunity to compete on both price and performance here.
My bet is that the work we give agents will keep getting more compute-intensive. Bigger builds, more experiments, simulations, video editing, rendering. There’s a lot beyond running a few commands and managing your calendar in a terminal.
Think about an agent working in Premiere Pro or Final Cut Pro, or using open-source creative tools. It needs access to the software, the environment and enough compute to actually do the work.
That’s what gets me excited about this. I want to see what agents can do when we give them a powerful Mac to work with.
That’s what we’re building towards with Darkbloom Sandboxes.
Cheers to the GOAT who made these chips! ❤️
1 trillion tokens through @darkbloomai and inference is just the first workload.
Darkbloom sandboxes and ci/cd are now in private beta putting apple silicon cpus to work too.
More agents >> more code to run, more tests, more builds, if you need mac ci, come talk to us
https://t.co/cj8EJaAyDH
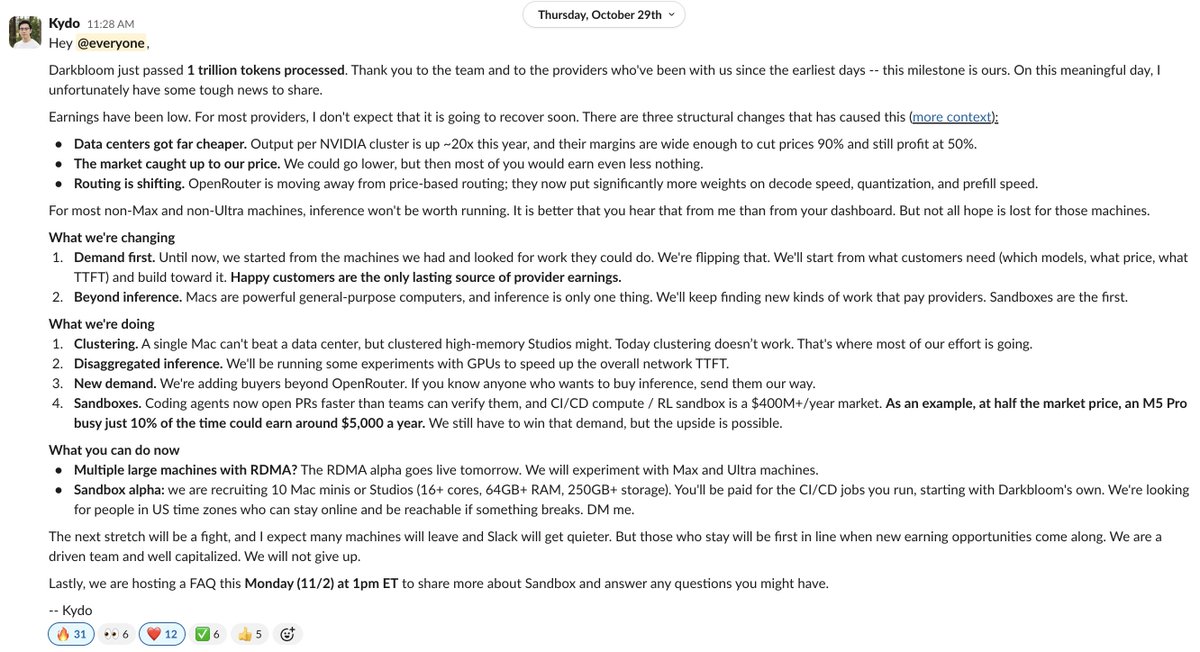
Darkbloom just passed 1 trillion tokens processed :)
I haven't tweeted much recently or shared many charts. We've been heads down on the thing that matters most right now: getting providers more work and better earnings.
Honestly, it's been a hard stretch. Provider earnings have been low. People trusted us with their machines and their time, and we take that seriously.
Inference keeps getting cheaper as architectures improve and more supply comes online. That means more people can use AI, but it also makes the economics harder for our providers. We have to keep finding where these machines can be most useful.
The mission is still the same: bring together all the spare compute out there and make it easy to own & share AI. I believe in that more than when we started.
And there's a lot more these machines can do.
More agents means more code to run, more tests, more builds. All those actions need compute too. Apple has built some incredibly capable, energy-efficient CPUs, and we want to put them to work.
We've started the private beta for Darkbloom Sandboxes and CI/CD.
We're starting with our own pipelines, cutting our internal costs by 50% while leaving healthy margins for providers. This gives us another way to bring useful, paying work to the network.
If you're looking for Mac CI or sandboxes, let us know. We'd love to work with you.
We're also continuing to push on inference. There's a lot of work going into open-source clustering on top of MLX; huge kudos to @Spangler3000 and @TheDavidTai for absolutely killing it on that front and writing SOTA for models such as GLM 5.3 Flash.
I'm attaching the debrief @0xkydo shared with providers last week. He laid out the difficult parts openly, and how people responded meant a lot to me. Seeing people care this much about making it work, especially through a hard stretch, reminds me why I love building this.
It's a hard problem. We're going to keep attacking it. Thank you to everyone who have been here in this journey and continuing to support & be with us.
This is a really cool idea from the Darkbloom community: continued LoRA training on local models. I think it could become extremely interesting in the near future.
The project, uli, fine-tunes a model in the gaps between requests and serves it from the same Mac. It trains on the 4-bit model the engine already holds in memory, so there's no second copy and it needs only 0.3GB of extra memory.
Overnight on a 16GB M1 Pro, it trained a Qwen3.5-9B adapter that boosted accuracy on held-out banking questions from 73.6% to 91.2%. In a separate test with live requests coming in, training added only 0.13s of wait time at p99, with zero failed requests.
Because Darkbloom is private by design, these fine-tuned private models could one day be deployed on other machines without those machines being able to download them.
Bullish uli, give @oxwizzdom a follow!
Great meeting with @0xkydo and @gajesh from @darkbloomai - Darkbloom lets you share your Mac as an AI inference server and get paid for doing it.
My cats loved them and they are good character judges, so that's a great sign. We talked AI, distributed AI networks, how to tell a great story, and I sold them on 3D printing as a hobby. 😀
Salem and Miso say "thanks for the treats!"
Once more amazed by the speed at which the @darkbloomai team executes, and extremely excited to be hosted on their platform.
Also check out the challenge on @yukonresearch
Bonsai 2 9B is LIVE on Darkbloom from day one.
@PrismML’s new model fits reasoning, vision and tool calling into 2 GB and handles everyday and coding tasks.
It runs on a network of Macs owned by everyday people.
The first 100 people get 250M free tokens at https://t.co/5rrYltKokD.
Want it faster? Bonsai 2 9B is also an open challenge at https://t.co/TtSOJoVO8F and https://t.co/EksX77xRkg on @YukonResearch.
Today, we’re releasing Bonsai 2 2B, 4B, and 9B.
Based on Qwen3.5, these new ternary models bring stronger reasoning, visual understanding, and tool calling to compact footprints designed for everyday devices:
• 2B: 0.43GB
• 4B: 0.95GB
• 9B: 2.0GB
For this release, we focused on what makes small models useful as local assistants: following instructions, avoiding repetitive loops, calling tools on mobile devices, and giving useful answers without unnecessary output. The 9B model uses roughly 40% fewer tokens on standard instruction-following and everyday math tasks. Solving the Riemann hypothesis can wait.
These models are successors to our first-generation Bonsai 1.7B, 4B, and 8B, and provide a foundation for bringing practical agentic functionality to local applications on personal computers, phones, and wearables.
The Bonsai 2 family now includes four sizes spanning 2B to 27B parameters. Developers can choose the balance of capability, memory use, and responsiveness that fits their application and hardware.
Available today under Apache 2.0.
Today is my official first day @eigenlabs building @darkbloomai
It’s been almost a month working with the teams here and I cannot speak highly enough of everyone here .
To all involved so far I cannot thank you enough for this opportunity.
Let’s build 🫶
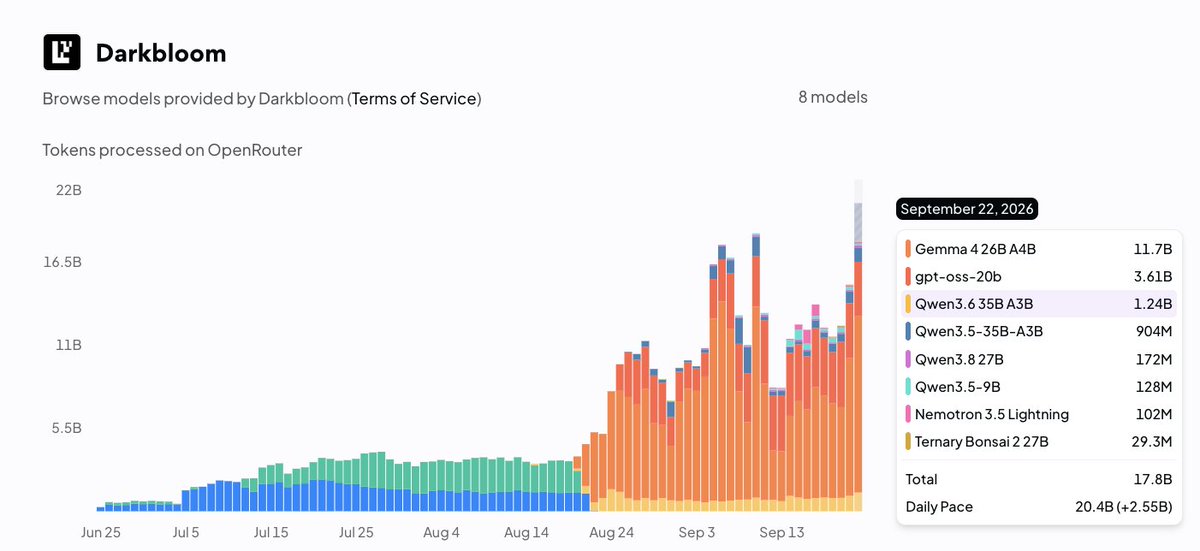
Yesterday marked one month anniversary of @DarkbloomAI moving to paid tier on OpenRouter.
We started with 4B tokens a day and today we are excited to be serving 20B+ tokens a day across 8 models.
We have grown our provider base to 1.1K+ active at all times and plan to expand it much higher as we expand the model base and more powerful M5 chips are getting shipped over next few weeks.
You can now run Darkbloom on any Macs (including corp) without our MDM.
Last week, we piloted our new higher grade privacy model which allows us to bind machines to stronger trust guarantees leading to Apple's certificates. You must be on MacOS 27 to be part of this and you will be soon required to be on OS 27+.
During last 2 weeks, we have shipped a bunch of features to increase the QoL for our providers which includes Global Payouts, better routing, MLX(.)Fast inference engine improvements etc.
Thank you everyone for being early to our network and supporting us through all the journey.
I also want to thank the OpenRouter team (@pingToven, @shashankgoyal95, Eddie, Will, @OpenRouterMatt) for making this happen and continuing to support us through adding new models.
This week we're at our company offsite + retreat planning through all the things we need to ship in the coming weeks and months.
We will share a much detailed update after this. If you are on Darkbloom, make sure you're part of the Slack community.
This is the first time in Darkbloom's history that we are the first provider to support a model on @OpenRouter ❤️
I couldn't have chosen a better partner for this milestone. @PrismML focuses on concentrating intelligence, so more models can run on distributed Mac machines!
NEW: Bonsai 2 is LIVE on Darkbloom
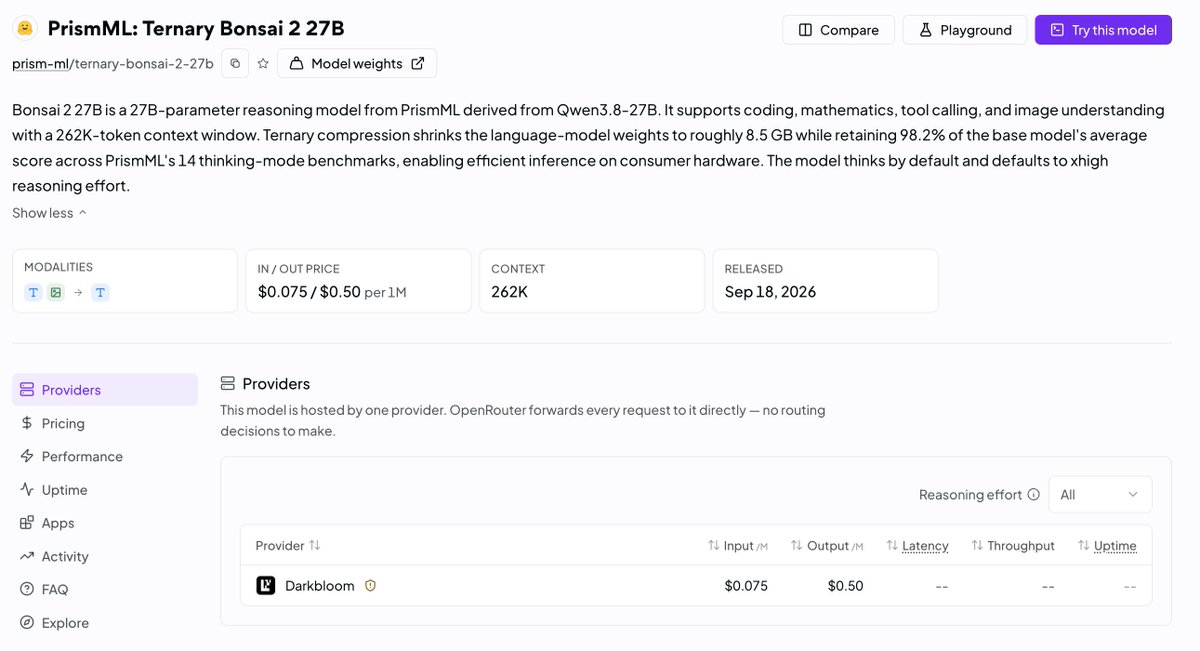
PrismML compressed Qwen3.8 27B to 8.5 GB and kept 98.2% of its benchmark scores. A full 27B reasoning model that fits on a phone.
On Darkbloom, it runs from a browser tab.
First 250 users get 100 million free tokens.
https://t.co/8dPaHMDb9n
Darkbloom is the first model provider to support Ternary Bonsai 2 27B -- concentrated intelligence that fits on your phone.
Try it now: https://t.co/AFd7mH02w4
First 250 users get 100 million free tokens;
PrismML's new flagship model:
- a ternary compression of Qwen3.8 27B at 2bits per parameter.
- 8.5 GB total, 5x smaller than original
- keeps 98.2% of the Qwen's FP16 benchmark performance.
- 75% cheaper than Qwen 27B.
Qwen3.8 27B already operates comparably with Opus 4.6 and 5.6 Luna on certain tasks. This one does it in the memory of a phone. 262K context, image input, Apache 2.0.
From our first run on the network, on a single M5 Max with no caching:
- 35 tok/s decode at 1K context,
- 31 tok/s at 10K,
- 19 tok/s at 50K.
But we expect more performance gain coming in a few weeks! That's a full 27B reasoning model running comfortably on any Mac.
1,000+ Macs are serving on Darkbloom right now. Go try it out!!
Thank you to @BabakHassibi@SahinLale@HessianFree@rsadri_ml@tushar_bans@evaninwords and the whole PrismML team. This is exactly the kind of model Darkbloom was built for.
You can read the essay by Bonsai on Why Local AI Matters: