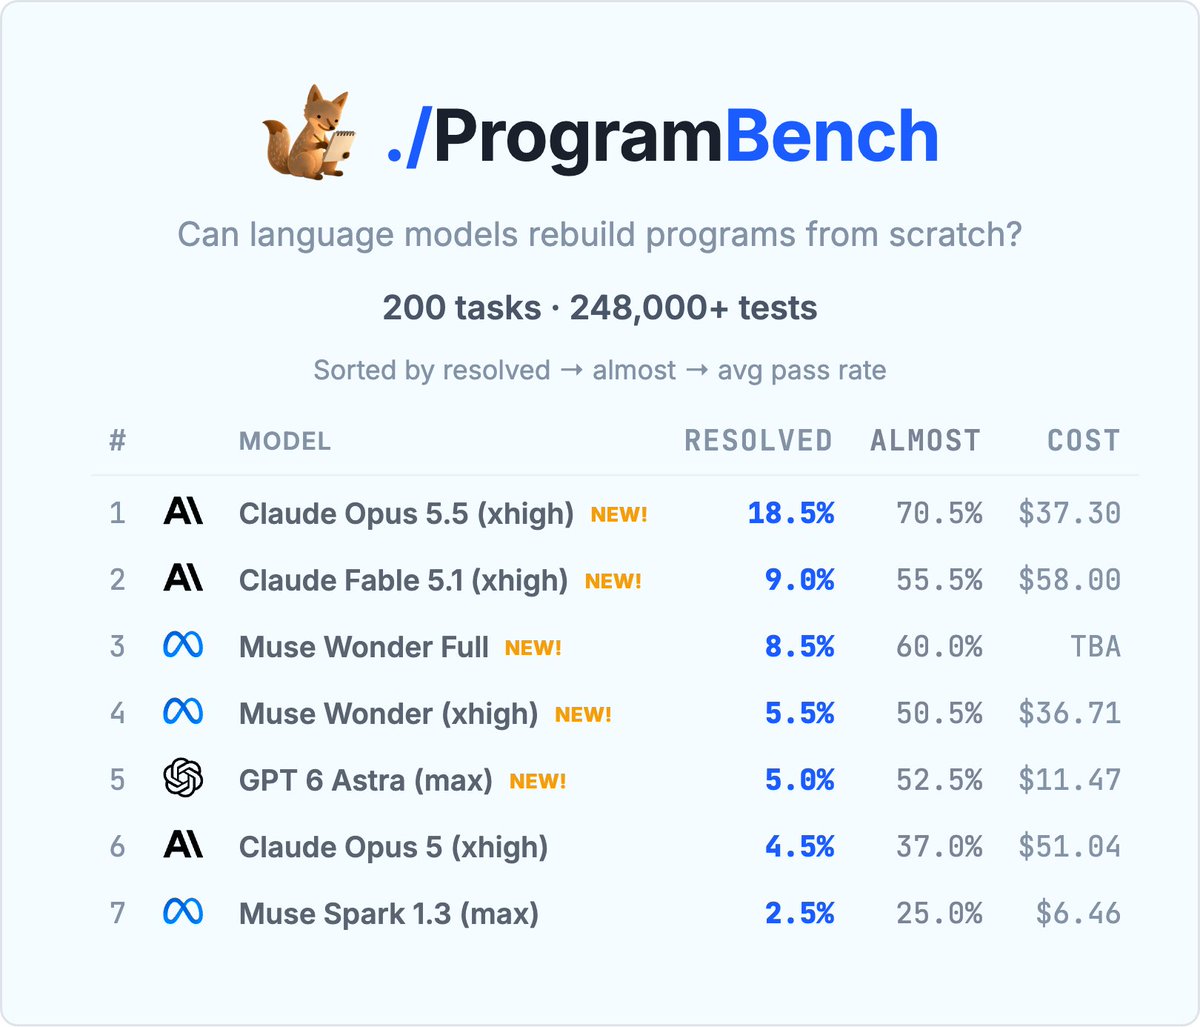
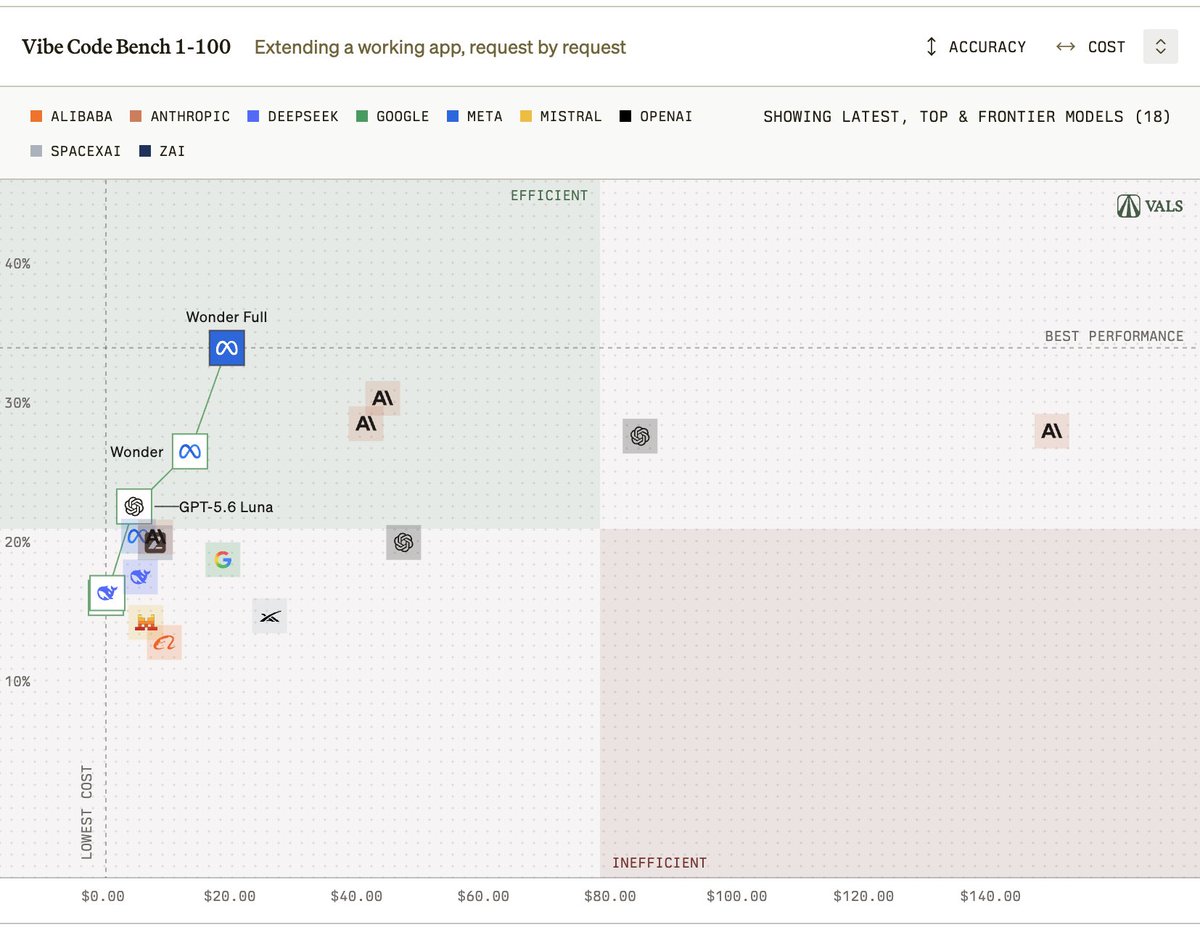
Saturating a benchmark that tests models on rebuilding ffmpeg is gonna take a fraction of the 3 yrs it took to saturate GitHub issue resolution.
Crazy times we live in.
I still think you guys are severely underrating Muse Wonder Full.
Been using it a ton for orchestration and drafting rewrites of docs, skills, mcp descriptions and more.
It's so much more pleasant to talk to AND it's great at steering models (as such, decent at skill writing!)
Muse Wonder Full + Muse Code on AA’s newly refreshed Coding Agent Index lands in 3rd. Along with the agentic developments made, it’s also a very solid coding model
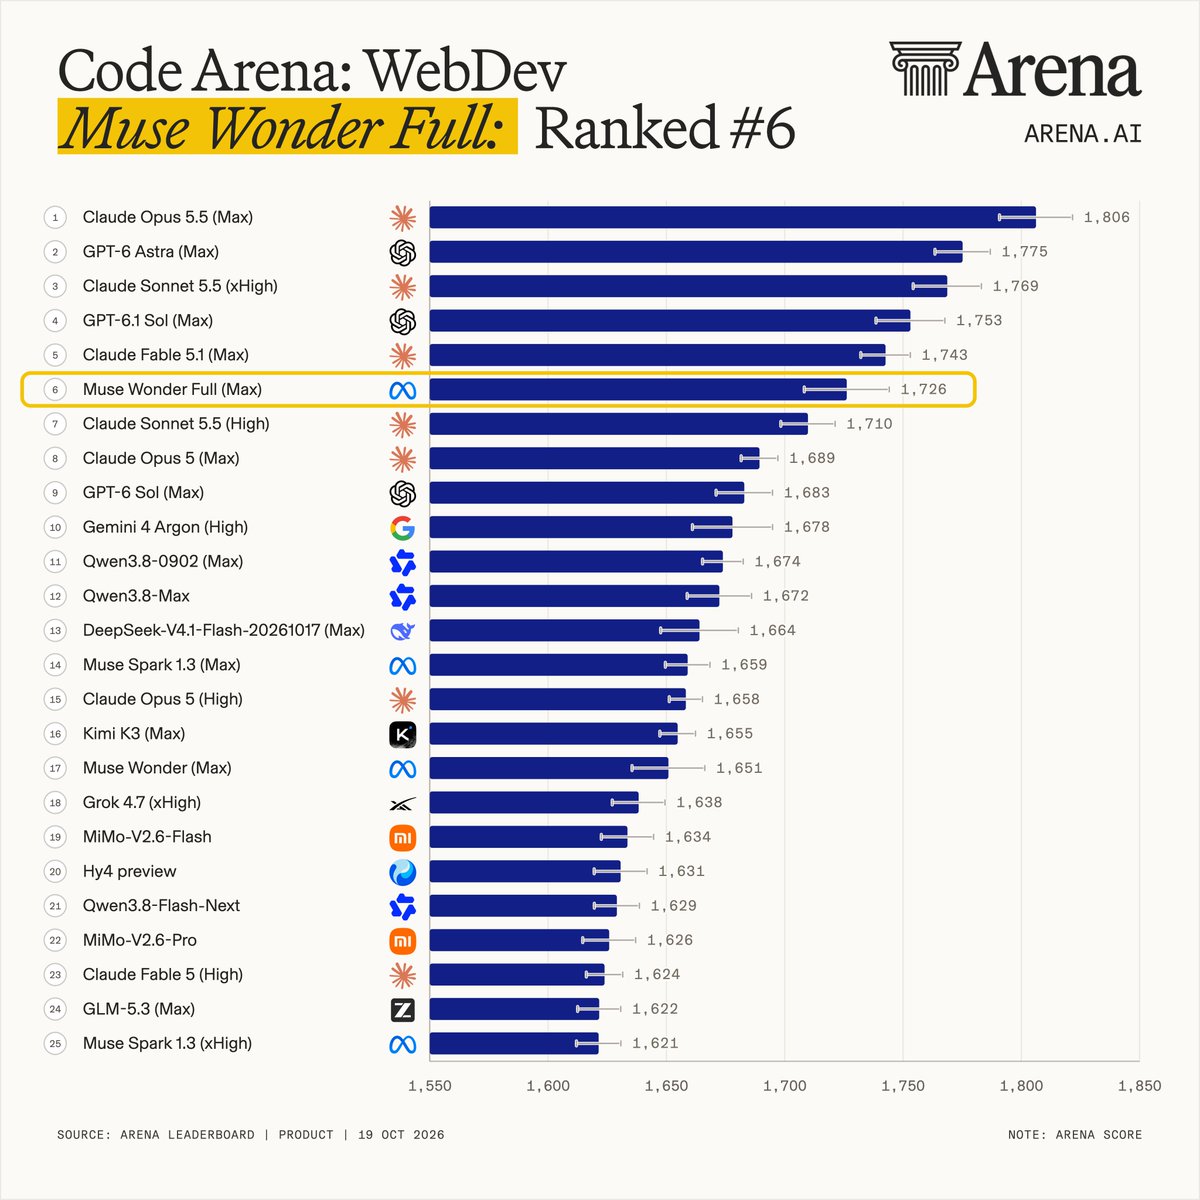
Exciting news: Muse Wonder Full (Max) by @AIatMeta has just debuted in the Code Arena: WebDev at #6 overall with 1726 pts, putting Meta in the top 3 labs!
This is +75 pts and 11 places above Muse Wonder (Max) at #17 (1651 pts), and +67 pts and 8 places above Muse Spark 1.3 (Max) at #14 (1659 pts).
Muse Wonder Full (#6) also landed +16 pts above Claude Sonnet 5.5 (#17), and +48 pts above Gemini 4 Argon (#10). With this score, Muse took the #3 lab spot (previously held by Google).
Across categories, Muse Wonder Full (Max) landed:
- #4 in Data & Analytics and in Consumer Product
- #5 in Brand & Marketing
- #6 in Content Creation Tools
- #7 in Gaming and in Simulations
- #8 in Reference-Based Design
Congrats to the @AIatMeta team and @alexandr_wang on this release!
@Muse saved me 50$ on new climbing shoes by finding them on sale on some Italian website, it figured that shipping and US import tax still saves me money, and no other retailer in US would beat the price. I got my shoes delivered in 6 days, I haven't even seen that website or typed any of my details. Just told my Muse what I need, and confirmed purchase once it done full research. I love agents in my personal life. I also keep hearing from friends how happy they are with @Muse. My Metamates who made this possible, you rock!
after an exciting week of launches (muse wonder [full] & muse spark open), i want to write a note of appreciation to the amazing research teams at meta superintelligence labs on reaching such a special milestone ♥️
we started MSL and TBD a little more than a year ago and set a goal of producing a frontier model within a year or so. given where llama4 landed, that was an incredibly audacious goal, and we knew it wouldn't be easy. many people told us it would be impossible. we knew it was unlikely, but still worth doing. a remarkable group of researchers and engineers joined the effort from inside and outside meta. every single person came in, picked up a shovel, and got to work with earnestness and urgency. nobody asked whose job it was.
we assembled a team of the most brilliant people i have ever had the opportunity to work with (and remember, i was an HRT intern 🙃). i am surrounded by ambitious, visionary, technically excellent, hard-working, pragmatic, thoughtful scientists, engineers, and product folks—people who will chase a weird loss spike past midnight just because they need to know why. these models are the product of their passion, hard work, and brilliance.
somewhat paradoxically, when we started TBD, we set a principle of no deadlines. we knew we had an astronomical amount of work ahead of us—across pretraining, post-training, RL, multimodal, infrastructure, safety, data, AND frontier research. there was no use setting arbitrary timelines—we just had to get to work, be thoughtful, and build the foundations of a frontier research effort in record time. and run after run, this team did exactly that.
our researchers are magicians. i can only describe building these models with this team as a wondrous journey of scientific discovery. i am constantly amazed by what we can accomplish with scaling. i will remember this past year for the rest of my life—the late nights, the broken runs, the evals that came back better than any of us dared to hope. watching this team create wonder after wonder has been a true and deep gift.
more than just the models we released this week, we have built a machine that builds new models. it often sounds like a cop-out to say labs can just turn the crank to keep scaling, but now i have seen it first-hand. sure, it's a lot of work and a careful process, but we have built a scalable system to keep advancing at the frontier, and i am really proud of how fast this team keeps making these models better.
lastly, i get to work with researchers who care deeply about how their work benefits humanity. it's easy to forget when everything is changing so fast, but the whole damn point is to make people's lives better. time and time again, i have seen our researchers, engineers, and product folks build our technology with care so it can truly be good for the world—whether that's building the best models for muse, thoughtfully open-sourcing strong models, or making sure the alignment and security of our systems are rock solid. this is a team of people who never forget there's a real person on the other side of every prompt.
thank you to everyone at MSL for being part of this crazy journey over the past year. i'm so grateful for every one of you, and our work is not done!
1/ muse spark open is the most capable US open-weight model to date.
816B total params, 42B active. 1M-token context. natively multimodal. built for coding and agentic work like long-horizon tasks, hard software engineering, multi-step reasoning.
america! 🇺🇲
Tried out Muse Wonder on a tricky task (figuring out which parts of the OpenHands Agent Canvas are hard for users to use) and it did a great job, impressed!
And as someone who's used to gpt models, the conciseness of the verbiage was pretty nice too 😀
Great job by @AIatMeta !
Muse Code (muse-wonder-full-1.0 high) is doing really good. By my vibe testing, It's better than Astra. Not quite as good as Claude Code Fable and 5.5 Opus. But it's much faster than Claude Code. I am doing serious compiler stuff that Codex simply chokes on.
In our health workstream at Meta we did a project where we wanted to see what research papers medical experts could write using a Muse Wonder coding scaffold that could access a database of 5M electronic health records we licensed from a vendor. The goal is that with 5M patients in this database, AI could do research to answer arbitrary questions like “did people who take statin have higher rates of diabetes later in life”? The thing we were betting on here is on what happens when you put human experts, a strong coding model, and access to data all together
We worked with a small group of medical experts to help them use this AI tool and the punchline is that they all found that this setup enabled a much faster pace of health research. They generated ten manuscripts in around two weeks, with one researcher (Paddy Ssentongo) generating three. Throughout the process, they collaborated with each other to review manuscripts and write skill files to help our coding scaffold improve at doing research. The medical experts liked how quickly they could test different hypotheses and choose the best ones to continue working on
Health research is pretty unique in that it is super important to be able to interpret noisy data and have taste to know which variables are important, which was still a significant value add from human researchers. Given that medicine is one of the oldest fields in human history and it is ultimately about humans, keeping a substantial human component in this type of research is probably important. In the near future I see AI primarily as a tool to facilitate human-led research. With the right scaffold I believe health researchers can be 10x or even 100x more productive using AI tools that have appropriate access to the wealth of data that the world has collected about human health
One way to see this work is through the broader lens of AI for science. You can think of science as two parts: (1) collecting raw data about the world, and (2) synthesizing that raw data into understanding. In this project we already had existing data about the world and we aimed to accelerate part (2) using AI. Eventually, I imagine a world where we have such great AI tools that the time to synthesize raw data into understanding is driven towards zero. In that world, science will be substantially faster and most of the work will be focused on collecting the right raw data via physical experiments
We did this in a pretty short amount of time (which was the point) and I think the future of scientific research will be more faster and more exciting than ever
We’re exploring how AI can accelerate health science research.
While AI has made significant breakthroughs in formal sciences like mathematics, health data science depends on imperfect real-world data and consequential choices about cohorts, variables, and causal assumptions.
To explore how AI can assist health researchers, we built a human-led research scaffold powered by Muse Spark 1.3 and Muse Wonder with access to 5M retrospective de-identified electronic health records and publicly available data. A cohort of medical experts used the system to conduct original research, accelerate hypothesis generation, code execution, and manuscript drafting while maintaining full authority over scientific decisions.
Today, we’re sharing 10 research manuscripts produced through this exploration, spanning cardiology, oncology, infectious disease, emergency medicine, and more.
Read more in our research blog: https://t.co/26l6Du6vIk
Muse Code 1.4.8 is out and is focused on token efficiency.
- Auto-review and background agents now use a cheaper model when available, and long auto-reviews stop sooner instead of burning tokens.
- We've fixed a bug that routed a small number of users who had enabled contributor mode to the full-priced models.
Now I can say it: Had early access to @Meta’s new "Watermelon" for the past few days.
Trick questions didn’t fool it, it followed instructions to the word, and as a coding agent it wrote, ran and checked its own code. Creative writing still a bit dry for my taste, but very very very impressive overall.
From my initial testings its as good as the benchmarks make it look. Meta really nailed it with their model!
P.s.: the benchmarks still surprised me, in a postive way. Didnt see the benchmark evals in advance.