your prompt cache is scoped to a workspace
split the same traffic across two of them, staging and production,
or two teams with their own keys, and you get two entries
each pays its own write, neither reads the other,
and the hit rate looks broken while both caches are perfectly healthy
on the two big cloud resellers the scope is the organisation instead,
and nothing is ever shared across organisations
check that before you go hunting for an invalidator in your prompt
the cheapest fix in this whole subject
is sending the same prefix from one place
you set effort per request, high for the hard ones
and low for the rest, which reads like good hygiene
changing effort or thinking invalidates the messages cache every time
so the turn after each switch rewrites the conversation instead of reading it,
at one and a quarter times input instead of a tenth
on some models that same change invalidates tools and system too,
because those settings render ahead of both
pin one value per route instead, and note that setting the model's own default explicitly costs nothing
the current opus defaults to medium, one level below everything else,
so pinning is also how you stop that surprise arriving silently
you were not tuning per request
you were rebuilding the prefix per request
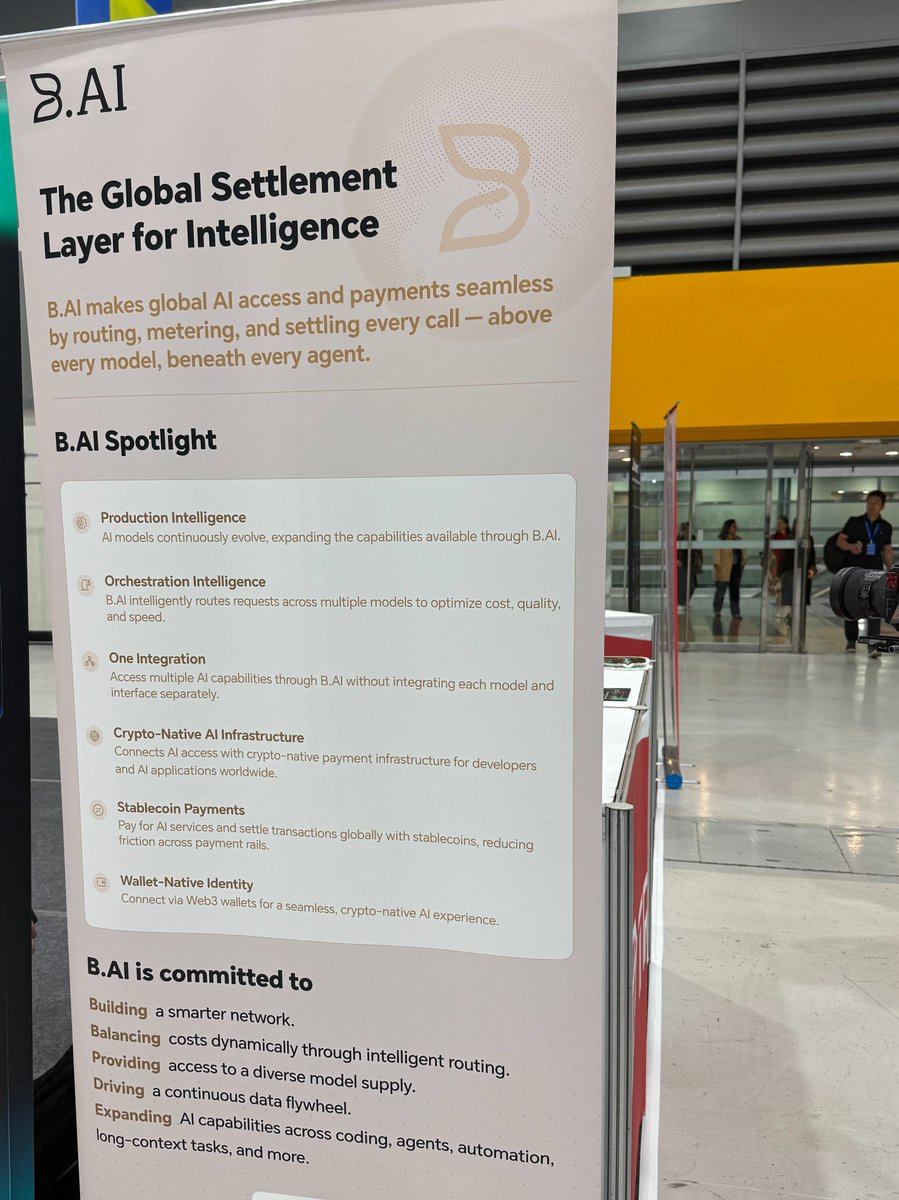
Seoul, we’re here! 🇰🇷👋
https://t.co/Yl2KG97Eb1 is at #GWDC2026KOREA. If you’re at the venue, come say hi, meet the https://t.co/Yl2KG97Eb1 team, and talk AI, Web3, Agents, and what’s next.
#BAI#GWDC2026#AI
Chỉ cần anh nói yêu, em sẽ bám theo anh suốt đời Cô gái đang muốn muốn bật đèn xanh đấy Cô nàng muốn gợi ý là mình chung thủy lắm đấy Anh cứ thử tỏ tình mà xem
Hôm nay anh có thể nói yêu em chứ? Nếu không, anh có thể hỏi em một lần nữa vào ngày mai? Ngày kia? Ngày sau đó nữa? Bởi vì anh yêu em mỗi ngày trong đời