AutoTrust Decision Models — one collection, from fast local decisions to multimodal agent control.
Every model returns calibrated probabilities for the answer options that matter: route or escalate, pick the next tool, score risk, verify a claim, or decide what action an agent should take next.
Start with the classics:
JEV-9B — compact typed decisions with System 2 reasoning
JEV-27B & JEV-27B v1.1 — our open text decision models
JEV-27B-VL — multimodal decisions across text and images
GEV-26B-Decide — a high-performing general decision model
JEV-35B — larger-scale decision capability
NVFP4 releases — lower-memory deployment options for practical inference
The collection also includes live demos for Mario, Rubik’s Cube, Tetris, and typed decisions, plus the public Decision Index result set.
Together, the models in this collection have now recorded more than 5.4M downloads.
Explore the full AutoTrust Decision Models collection:
https://t.co/eXv5y39Dwt
The AutoTrust decision-model line has grown from compact text decisions to multimodal, production-ready agent infrastructure.
JEV-9B for typed decisions.
AutoTrust-JEV-27B v1.1 for Text Top 3 performance.
JEV-27B-VL for Vision Top 3 performance.
Explore the full collection:
https://t.co/RS3XJbhSnd
Top 3 in both Vision and Text categories.
Ahead of TypeSafe JEV in Text.
JEV-27B-VL reached No. 1 on Hugging Face Global Trending.
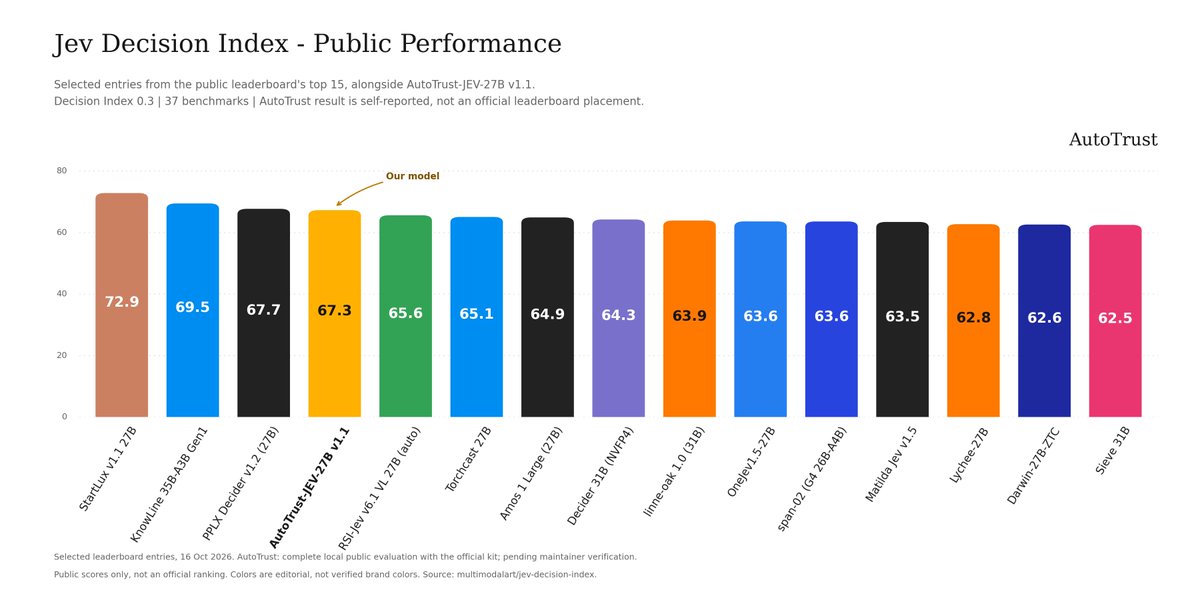
Now AutoTrust-JEV-27B v1.1 is Top 3 on both Jev Decision Index boards.
Text: tied for #3 with a 68.0 Full Score.
That puts our open 27B model ahead of TypeSafe’s hosted Jev 1.13 — and ahead of Liquid AI’s d1-3B — on the same public Decision Index.
Vision: #3 with a 71.9 Full Score, including 74.4 on the public set and 69.3 on the private set.
It ranks ahead of Perplexity Decider v1.2, vLLM-SR d3, and Cloudflare’s clef-omni.
This is not a one-model spike. It is a model family built for the decision layer of agents: structured probabilities for routing, tool selection, claim checks, next-action choice, and escalation to deeper reasoning when confidence is not enough.
AutoTrust is establishing itself as a clear leader in open decision models.
Open weights. Apache-2.0. Built for local deployment.
Explore the Jev Decision Index:
https://t.co/2x0FdWt6cv
Download AutoTrust-JEV-27B v1.1:
https://t.co/8k9qOW8t5X
Want to see what open decision models can actually do?
AutoTrust Spaces is our hands-on demo hub: play Mario, Rubik’s Cube, and Tetris with JEV-27B; test typed decisions with JEV-9B; and explore live News and Shorts demos.
Try the demos:
https://t.co/1M1WCKfT6U
Not every model needs to write essays.
Some just need to make clean decisions.
A Open jev model classifies with precision.
AutoTrust-JEV-27B-v1.1 turns messy text into clean, structured labels intent, moderation, routing, compliance.
- repeatable structured outputs at scale.
- https://t.co/gFziScn8Xo
What does “structured decisions” mean in practice?
Give JEV-27B v1.1 a text state, a question, and a fixed set of options. Instead of generating a long response, it returns a probability for each option.
That makes it useful as a fast decision layer for support-ticket routing, intent detection, API and tool selection, claim checks, banking-intent triage, and human-review gates.
The current release supports text-only yes/no and multiple-choice tasks, with local vLLM deployment. It is a decision component rather than a free-form chat model, so teams should validate it on representative data before production use.
Full model card, usage instructions, and evaluation details:
https://t.co/8k9qOW8t5X
Thank you, @HuggingModels.
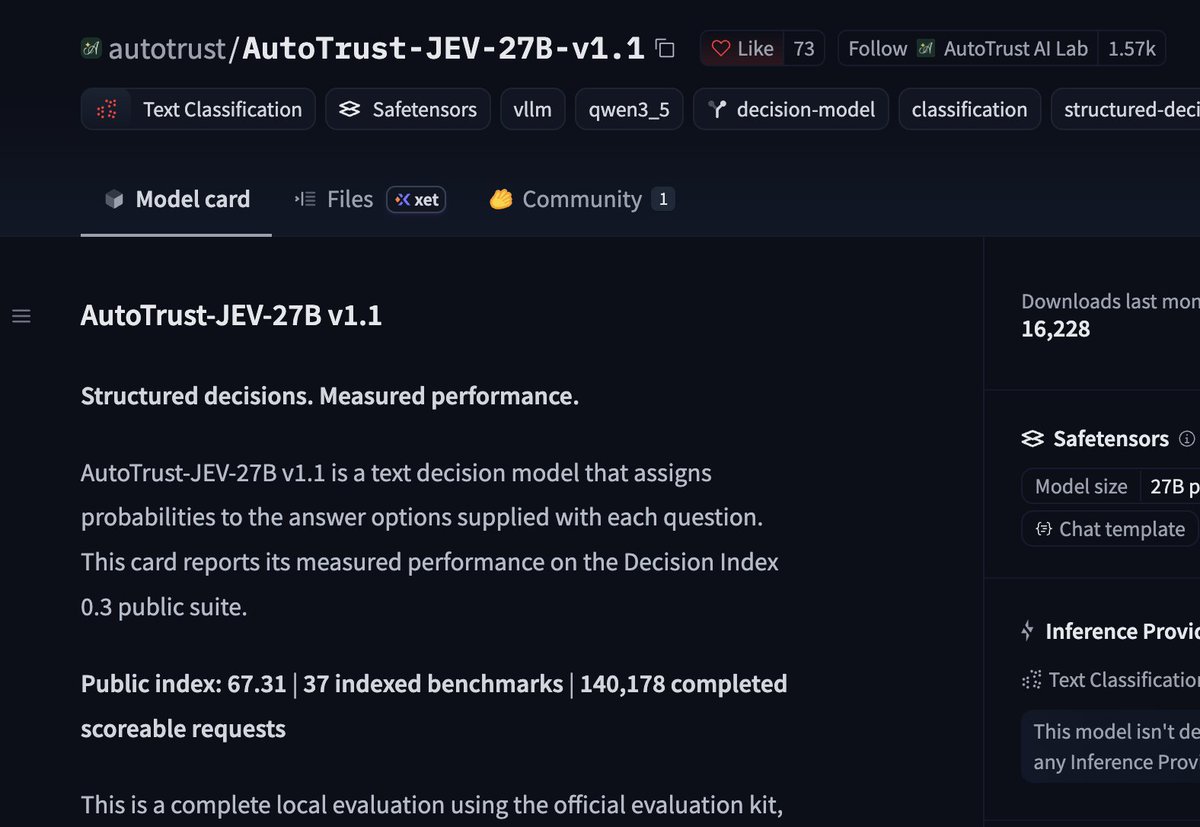
AutoTrust-JEV-27B-v1.1 has now passed 16K downloads on Hugging Face.
It is an open 27B decision model for the high-frequency calls inside agent systems: route a request, select a tool, detect an out-of-scope intent, verify a claim, or choose the next action from a fixed set of options.
Instead of producing another paragraph, it returns a probability for every available option — making decisions measurable, routable, and easier to audit.
Apache-2.0. Run it locally with vLLM: 📷https://t.co/8k9qOW8t5X
Meet AutoTrust-JEV-27B-v1.1: a 27B text-classification model built for structured decisions. With 5.6k downloads and 166 likes, it's quietly becoming a go-to for teams that need reliable, repeatable classification at scale.
6/ For developers: the release ships with vLLM serving scripts and a decision engine that formats the question, constrains the readout to the supplied option codes, and converts returned log-probabilities into option probabilities.
The model card reports a complete local run on one NVIDIA B300 with vLLM 0.31.0 and 16 concurrent clients. It also records 64.8 ms median local request timing — not a deployment latency guarantee.
Download and reproduce the evaluation artifacts:
https://t.co/8k9qOW8t5X
https://t.co/d4HISHXdoI
Also available on ModelScope:
https://t.co/OlXW0RnMtw
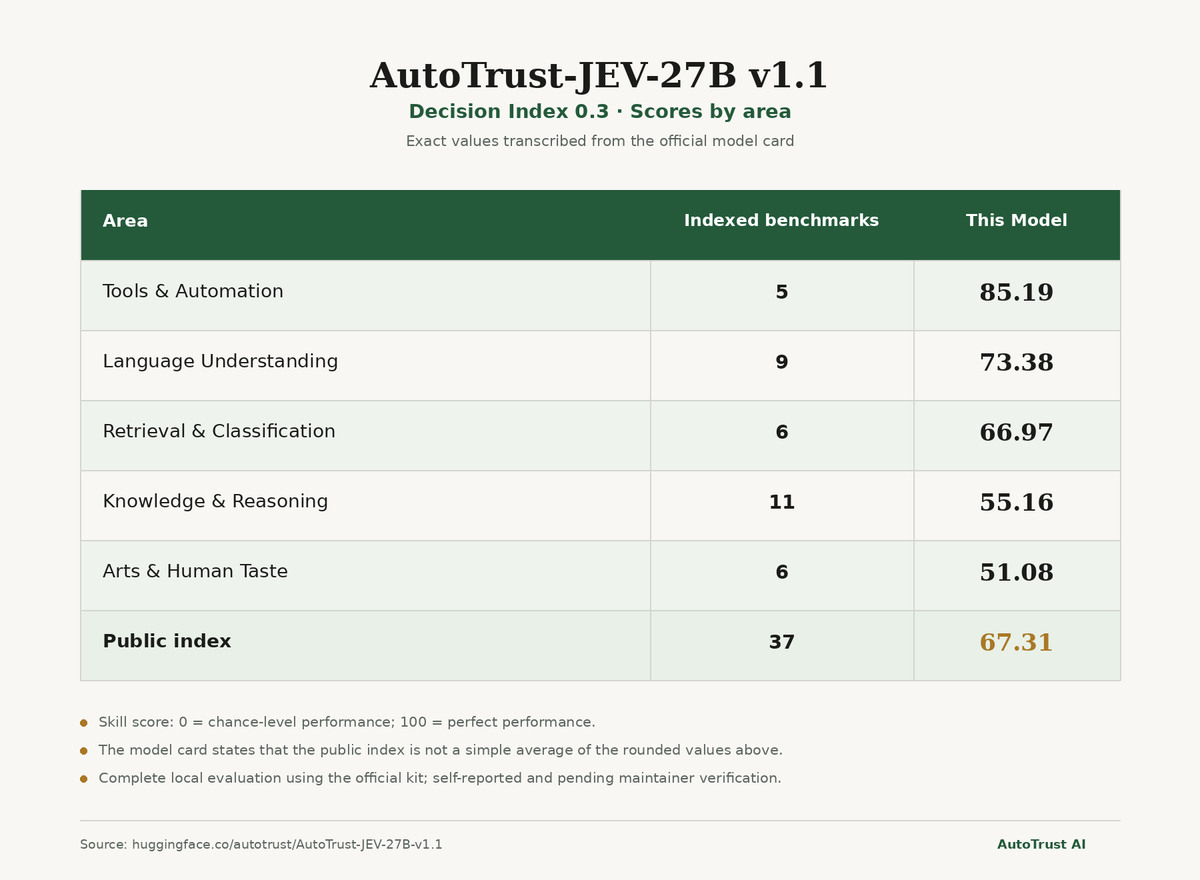
4/ Its highest-scoring area in the reported run is Tools & Automation: 85.19 skill points.
The same model-card table reports:
• Language Understanding: 73.38
• Retrieval & Classification: 66.97
• Knowledge & Reasoning: 55.16
• Arts & Human Taste: 51.08
A skill score adjusts for task chance level; 0 is chance and 100 is perfect. The public index is not a simple average of the rounded area scores.
3/ What does the model actually return?
For a defined text question and its allowed answers, JEV-27B v1.1 returns option probabilities rather than a long generated response.
That is useful when your application needs to decide:
• which tool to call
• how to route an incoming request
• whether an intent is in scope
• whether a text claim is supported
The output stays bounded, inspectable, and straightforward to threshold in a workflow.
2/ The model card reports a complete local run of the Decision Index 0.3 public suite:
• Public index: 67.31
• 37 indexed benchmarks
• 140,178 completed scoreable requests
Important context: this is a self-reported local evaluation using the official kit, pending maintainer verification. It is not an official leaderboard placement.
1/ Introducing AutoTrust-JEV-27B v1.1.
A 27B text decision model that assigns probabilities to the answer options supplied with each question.
This is for the thousands of bounded calls inside agent workflows: tool choice, request routing, intent classification, API-use decisions, and evidence checks.
Apache-2.0 weights. Text-only. Choice and yes/no inputs.
Model card: https://t.co/8k9qOW8t5X
@ModelScope2022 Thanks @ModelScope2022 for featuring AutoTrust AI’s JEV Demo on ModelScope Studios — try it with your own decision tasks, share your feedback, and follow AutoTrust Labs for upcoming model releases and demos: https://t.co/mV6TyZmFw2
Try JEV in the browser. ⚡
AutoTrust AI’s JEV Demo is now live on @ModelScope2022 Studios — a hands-on place to explore our multimodal decision-model work.
JEV is designed for the small but critical choices inside AI systems: selecting an option, assigning a score, evaluating confidence, and deciding what an agent should do next.
Open the demo, try it with your own prompts, and follow AutoTrust Labs on ModelScope for new models, demos, and decision-AI updates.
JEV Demo:
https://t.co/rHCmVfHavj
JEV-27B v1.1 is built for structured decisions rather than long-form generation: text in, a bounded choice out.
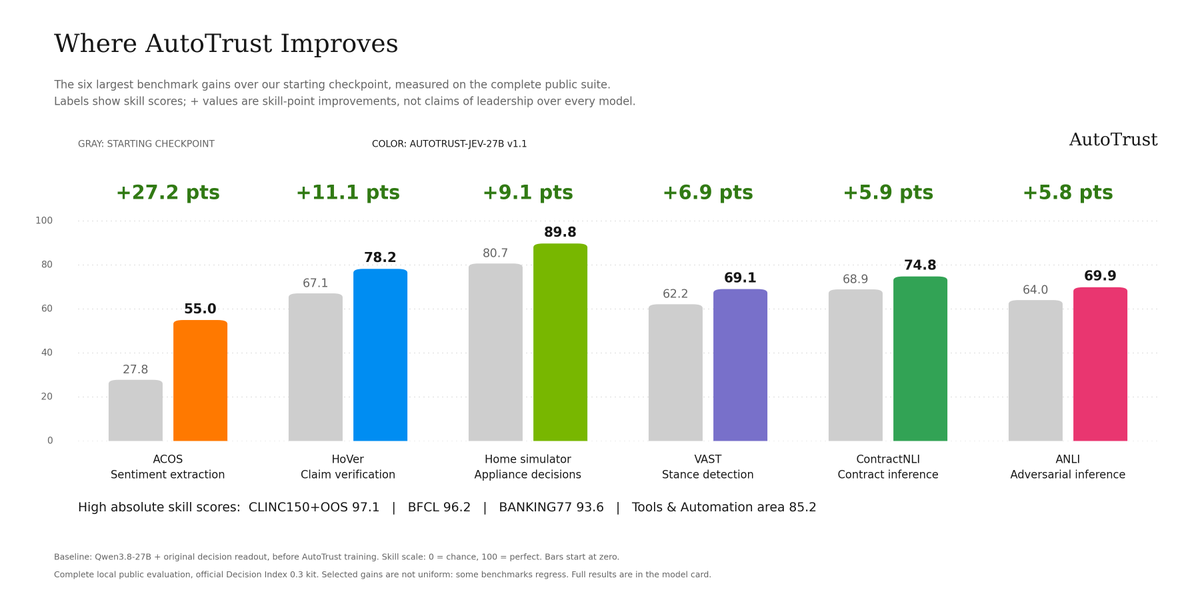
In our complete local Decision Index 0.3 evaluation across 37 benchmarks, it scored 96.25 on tool selection, 97.06 on intent classification with out-of-scope detection, and 78.24 on claim verification. Apache-2.0 weights and vLLM deployment instructions are available now.
ModelScope:
https://t.co/OlXW0RnMtw
Meet AutoTrust-JEV-27B v1.1 — a 27B text decision model built for the thousands of small choices inside an AI agent.
Instead of generating a long response, it turns a defined question and its options into probabilities you can act on: choose the right tool, route an out-of-scope request, classify an intent, assess a claim, or select the next API action.
In our complete local run of the Decision Index 0.3 public suite, JEV-27B v1.1 achieved a 67.31 public index across 37 benchmarks and 140,178 completed scoreable requests, with particular strength in tools and automation:
• 96.25 on tool selection
• 97.06 on intent classification with out-of-scope detection
• 93.63 on banking intent classification
• 78.24 on claim verification
Apache-2.0 weights and decision readout are available now on @HuggingModels and @ModelScope2022.
Download on Hugging Face:
https://t.co/8k9qOW8t5X
Download on ModelScope:
https://t.co/OlXW0RnMtw
Give JEV-27B v1.1 a question and its candidate options, and it returns a probability for each choice.
Use it to route support tickets, identify out-of-scope requests, select the right tool or API, prioritize incoming tasks, check whether a claim is supported, or decide when an agent should escalate to a larger model or human review.
Download on Hugging Face:
https://t.co/vtagTOmzNB