🌍 Actions that condition world models are highly heterogeneous: forces on objects, camera movements, hand motions, robot arms, each with its own meaning and structure. So today's action-conditioned world models are usually built one action type at a time, each with its own conditioning design.
We introduce UniAction, a unified action-conditioning framework: one world model driven by all of these actions, and even by mixes of them in a single generation. Trained jointly, it outperforms the action-specific experts. Great work led by amazing @BowenXue_ .
More detailed threads below👇
🧵 1/10
FreeVideo + FreeToken will enable a fully automatic pipeline for short-drama generation: use VLMs to write prompts and design storylines, generate high-quality videos and visual assets with FreeVideo, and orchestrate the whole workflow with FreeToken. Really excited about what this can unlock for automated short-drama creation!
Huge thanks to @BowenXue_ and @HaochengXiUCB for making this happen!
Video generation now runs right on your laptop. 🎬
Introducing FreeVideo — bringing MiniMax H3 + Video DeltaNet to the hardware you already own.
As little as 8GB VRAM + 16GB RAM. ComfyUI integration, LoRAs & custom workflows.
Code: https://t.co/sIKSsAuOGw
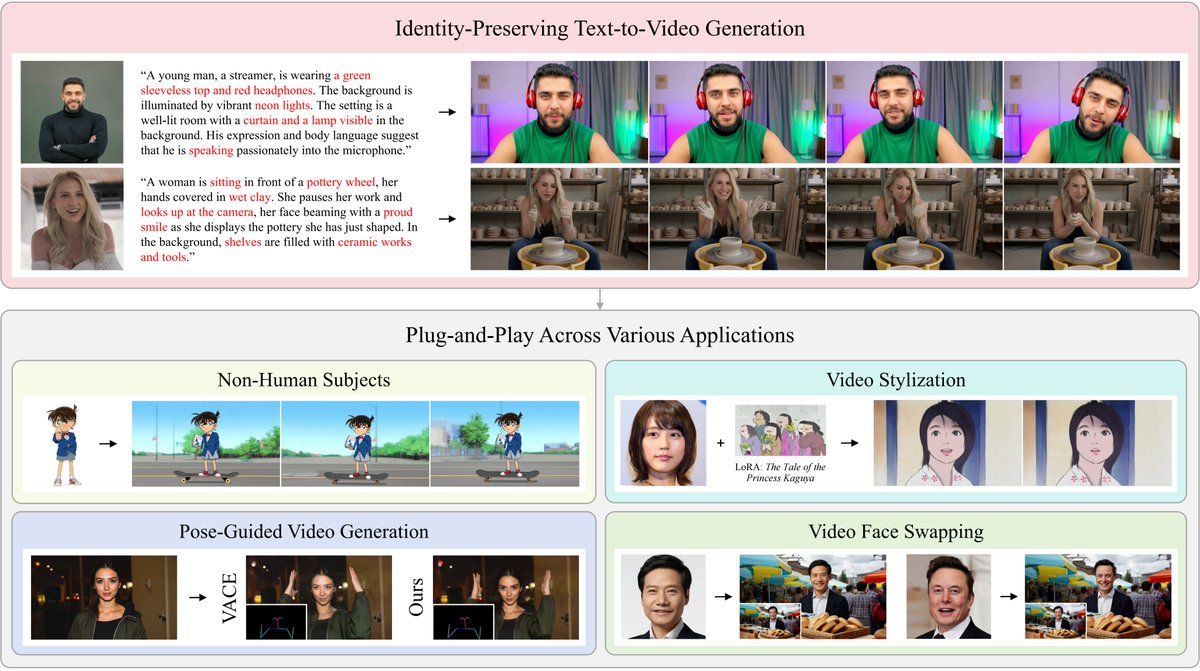
Tencent's WeChat Vision just released Stand-In!
A lightweight, plug-and-play framework for high-fidelity identity-preserving video generation.
It achieves state-of-the-art results with only ~1% extra parameters.
Tencent open source Stand-In:
a lightweight, plug-and-play framework for identity-preserving video generation.
Can be seamlessly integrated into other tasks such as subject-driven video generation, pose-controlled video generation, video stylization, and face swapping.
Stand-In just landed on the hub 🔥
✨identity preserving video generation
✨lightweight LoRA with minimal affect on latency!
✨apache 2.0 license
plug-and-play approach, LoRA weights for Wan 2.1 available 👇
It can also be seamlessly integrated into other tasks such as subject-driven video generation, pose-guided video generation, stylization, and face swapping.
Excited to share our recent work at Tencent — Stand-In, a lightweight, plug-and-play framework for identity-preserving video generation.
🔗 Code: https://t.co/UhYN47jtVf
🌍 Project Page: https://t.co/DItmBG45NI
📄 Paper: https://t.co/KiWXUxMDAr
We introduce a conditional image branch into pre-trained video generation models, combined with restricted self-attentions enhanced by conditional position mapping, to achieve precise identity control.