@flowerornament@sol_plunder And thanks for writing about your efforts, given your apparent hesitance. I spent some hours querying agents about PLAN, including exploring possible future softwares, but I never got close to something this imaginative so it'll be useful.
.@VolatilityQ is the first open source Quantitative Finance (algos if not code) account I've come across. I hope this is going where I hope it's going (democratisation of Cantillon effects or some such idea).
Disclosure: this is a shameless attempt to get @VolQTheta
Gemma 3 is a collection of lightweight, state-of-the-art open models built from the same research and technology that powers our Gemini 2.0 models. → https://t.co/lA6jOuri5d
🚀 Day 5 of #OpenSourceWeek: 3FS, Thruster for All DeepSeek Data Access
Fire-Flyer File System (3FS) - a parallel file system that utilizes the full bandwidth of modern SSDs and RDMA networks.
⚡ 6.6 TiB/s aggregate read throughput in a 180-node cluster
⚡ 3.66 TiB/min throughput on GraySort benchmark in a 25-node cluster
⚡ 40+ GiB/s peak throughput per client node for KVCache lookup
🧬 Disaggregated architecture with strong consistency semantics
✅ Training data preprocessing, dataset loading, checkpoint saving/reloading, embedding vector search & KVCache lookups for inference in V3/R1
📥 3FS → https://t.co/JRZ2eYk1aK
⛲ Smallpond - data processing framework on 3FS → https://t.co/BoUA6YNjZK
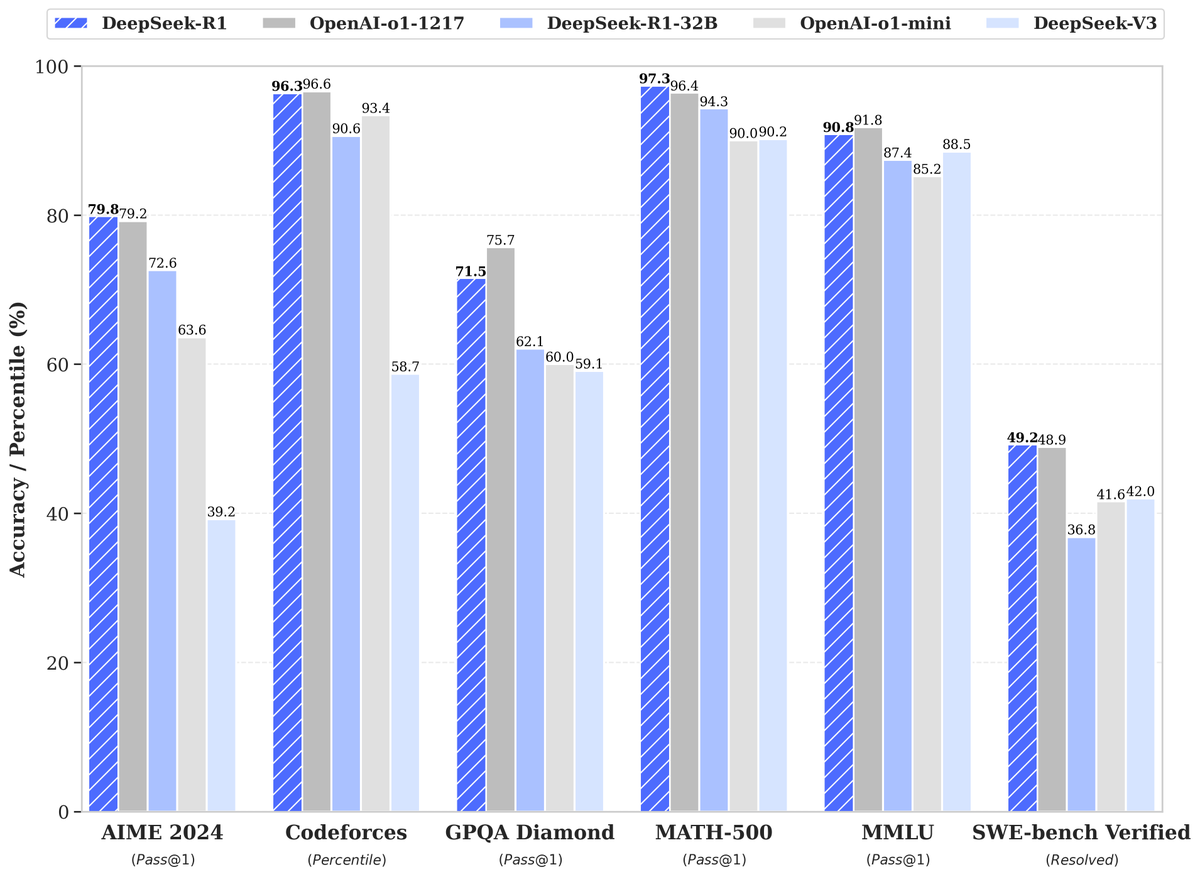
🚀 DeepSeek-R1 is here!
⚡ Performance on par with OpenAI-o1
📖 Fully open-source model & technical report
🏆 MIT licensed: Distill & commercialize freely!
🌐 Website & API are live now! Try DeepThink at https://t.co/v1TFy7LHNy today!
🐋 1/n
Gemini 2.0 Flash is here! 🎊
We're quite excited about this model. It's better than Gemini 1.5 Pro on most benchmarks, but comparable in speed and latency to Gemini 1.5 Flash. It has multilingual native audio output, native image output, native tool use, and a new multimodal live API for streaming audio and video. It's an awesome model for building all kinds of interesting agents, and we're excited to see what developers do with it!
Credit to the whole Gemini team: I'm so proud of everyone's work here!
https://t.co/ubIjrHyVi2
🪶We're releasing a preview of QwQ /kwju:/ — an open model designed to advance AI reasoning capabilities.
Blog: https://t.co/hIhKfgvWXt Model: https://t.co/sRGah9dkFw
Demo: https://t.co/X5HlvYfk1H
QwQ has preliminarily demonstrated remarkable capabilities, especially in solving some challenges in mathematics and coding. As a preview release, we acknowledge its limitations. We earnestly invite the open research community to collaborate with us to explore the boundaries of the unknown!
AlphaFold 3 model code and weights are now both available for academic use on GitHub.
The golden age of computational science is about to begin!
https://t.co/sKiQbSS1jM
🚀 DeepSeek-R1-Lite-Preview is now live: unleashing supercharged reasoning power!
🔍 o1-preview-level performance on AIME & MATH benchmarks.
💡 Transparent thought process in real-time.
🛠️ Open-source models & API coming soon!
🌐 Try it now at https://t.co/v1TFy7LHNy
#DeepSeek
🚀Now it is the time, Nov. 11 10:24! The perfect time for our best coder model ever! Qwen2.5-Coder-32B-Instruct!
Wait wait... it's more than a big coder! It is a family of coder models! Besides the 32B coder, we have coders of 0.5B / 1.5B / 3B / 7B / 14B! As usual, we not only share base and instruct models, we also provide quantized models in the format of GPTQ, AWQ, as well as the popular GGUF! 💖
👉🏻Blog: https://t.co/7FnV3SUHuD
👉🏻Tech Report: https://t.co/Y3JN2Ly7H6
👉🏻Hugging Face: https://t.co/GgfeNq0XML
👉🏻ModelScope: https://t.co/VJwMAvEaHN
👉🏻Kaggle: https://t.co/7GW9GZJYre
👉🏻GitHub: https://t.co/gMGC8b5Hwv
👉🏻Demo [chat]: https://t.co/JxAYwnLM9u
👉🏻 Demo [Artifacts]: https://t.co/cyJEHV30e1
The flagship model, Qwen2.5-Coder-32B-Instruct, reaches top-tier performance, highly competitive (or even surpassing) proprietary models like GPT-4o, in a series of benchmark evaluation, including HumanEval, MBPP, LiveCodeBench, BigCodeBench, McEval, Aider, etc. It reaches 92.7 in HumanEval, 90.2 in MBPP, 31.4 in LiveCodeBench, 73.7 in Aider, 85.1 in Spider, and 68.9 in CodeArena!
Claude 3.5 Haiku is now available on our API, Amazon Bedrock, and Google Cloud's Vertex AI.
Haiku is fast and particularly strong at coding. It outperforms state-of-the-art models—including GPT-4o—on SWE-bench Verified, which measures how models solve real software issues.
Introducing BitNet b1.58: 1.58-bit LLMs, in which every single parameter is ternary {-1, 0, 1}, that rival full-precision Transformer LLMs in performance while significantly boosting efficiency—paving the way for a new era of 1-bit LLMs. Learn more: https://t.co/NWeJHC5qex
We are also releasing a model checkpoint pre-trained on 20 TPU blocks, so our open-source method now has open-weights as well!
Open-source repo: https://t.co/im7seHD8om
Pre-training tutorial: https://t.co/ivLxSrmZNZ
Pre-trained checkpoint: https://t.co/PFwIG7BnDv
Our AI for chip design method AlphaChip has transformed the way we design microchips. ⚡
From helping to design state-of-the-art TPUs for building AI models to CPUs in data centers - its widespread impact can be seen across Alphabet and beyond.
Find out more → https://t.co/G3Hsk3mWU9