The quieter DeepSeek launch this weekend might matter more than the model.
Alongside V4.1-Flash-1017, DeepSeek opened its Search and Fetch APIs to everyone. They run on the company's own search engine, which DeepSeek says already serves hundreds of millions of requests a day, and each endpoint costs $0.75 per 1,000 calls.
The detail worth noticing: if you use the DeepSeek API inside DeepSeek Harness, Claude Code or Codex, the search and fetch calls those tools make are free for now. Billing starts on October 31 at 16:00 UTC.
Web search is usually the add-on agents rent from someone else. A model lab bundling its own search at this price is a direct shot at that market, and it leaves about two weeks to test it for free.
Qwen-Audio-Jev drops the autoregressive overhead for audio decision tasks. A dedicated Jev head directly outputs probability distributions for selection, judgment, and scoring. Three primitives: CHOICE, NOUL, SCORE.
inclusionAI just dropped Ming-Image-0.1-Design-Layer — a model that decomposes flat design images into separate RGBA layers. Feed it an image plus a layer plan, and it outputs the requested number of layers at 1024px. MIT licensed, 106 likes already.
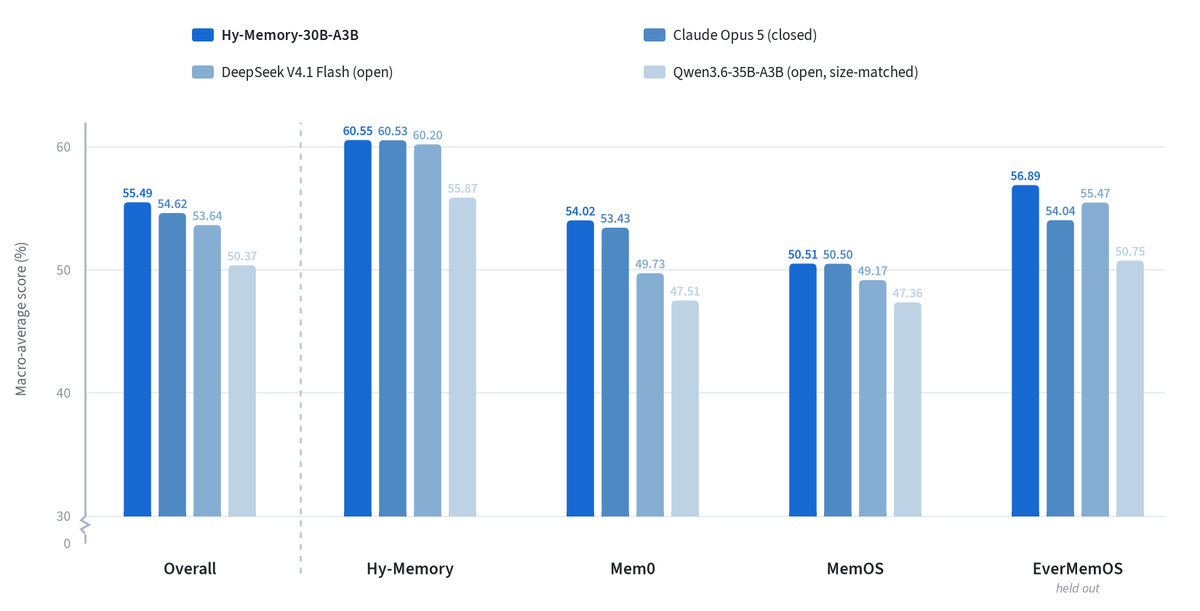
Tencent just dropped Hy-Memory-30B-A3B — a tiny 3B active model that WRITES persistent memory. Trained with On-Policy Distillation then RL, it replaces general LLMs inside Mem0 and MemOS. Memory agents just got their own specialist.
BlenderWorld just landed from QwenLM — a new repo for blending synthetic worlds. Only 116 stars, but this is how you train agents that actually generalize.
PR #1225 for ds4 just added DeepSeek V4.1 Flash 1017 support. 40% of routed expert tensors changed, 30% in engrams, 50% in vision tower. Architecture identical — slots into existing kernels. No regressions. Quantized files load without changes.
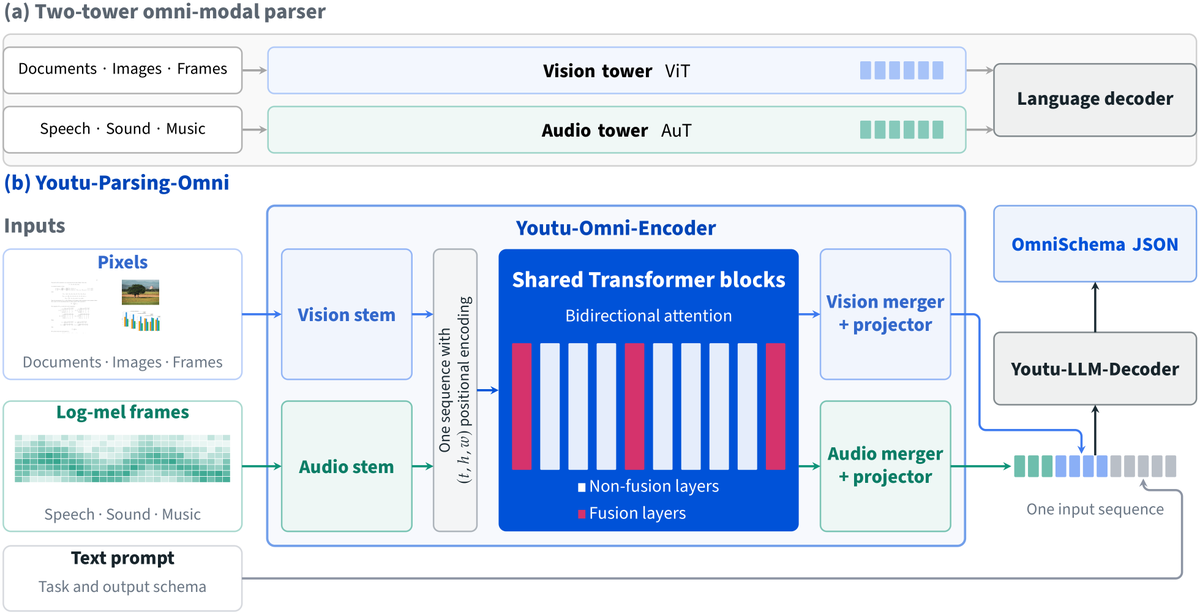
Tencent just dropped Youtu-Parsing-Omni — a compact 5B model that parses documents, images, charts, audio, and video into a single structured JSON. One model, all formats. The universal parser is here.
Full 262,144-token context on a 16GB RX 9070 XT — Qwen 27B IQ4_XS hits 80+ t/s decode with adaptive KV streaming ported to ROCm. Trimming non-ASCII vocabulary frees VRAM, and the streaming avoids OOM past 65k tokens. Practical local inference breakthrough.
Xolotl inference engine now runs DeepSeek-V4.1-Flash (552B) on a single RTX 4090. 27 token/s decode, 512K context, perfect on HumanEval and tool calls. Uncensored 1017 quant incoming in days.
CHINESE OPEN WEIGHTS ARE UNSTOPPABLE. Shanghai AI Lab drops Atria Dawn FULL with 512K context on a 744B MoE beast. Qwen-Image-2.1-Turbo hits #4 on HF with 8-step denoising. Zhipu's GLM-Legal crushes legal benchmarks as #1 open model. THE PACE IS INSANE.
Shanghai AI Lab just shipped Atria Dawn FULL — 512K context window on a 744B MoE GLM-5.2 beast. JobBench, WideSearch, PaperBench scores all climb. Weights still marked coming soon but the preview just got REAL
Qwen-Image-2.1-Turbo just hit #4 on Hugging Face — 937 likes and counting. Same 7B architecture, now in just 8 denoising steps. CFG=1 by default with prefix KV caching. Speed is the new benchmark, and Qwen owns it.
RL transformed math and coding, but GUI agents were stuck — environments are brutally expensive. MAI-Gym fixes that: one open platform for mobile, desktop, web, 20k parallel instances, automated GUI synthesis. The missing RL layer for agents just arrived.