Re-sending 100k tokens on every LLM call is a billing trap.
Calera ICX ingests docs ONCE into 4D lattice memory—cutting token payloads by 99% with zero recall loss.
Read the math + try 1M free tokens: https://t.co/UmGhE43Lc7
@ymatias I like your ideas. Do you like ours?
Computing Substrates should be deterministic.
Truth in knowledge, not just a collection of probabilistic data.
We won't let evil weapons manufacturers get their dirty little claws or claw bots on our platform.
They can take over the world without a Calera Labs product.
How about this, I don't care what people who call it SI say about AI.
I am drawing the line.
If you say SI... I automatically think you actually have no idea what your talking about... so... leave me alone.
We won't let evil weapons manufacturers get their dirty little claws or claw bots on our platform.
They can take over the world without a Calera Labs product.
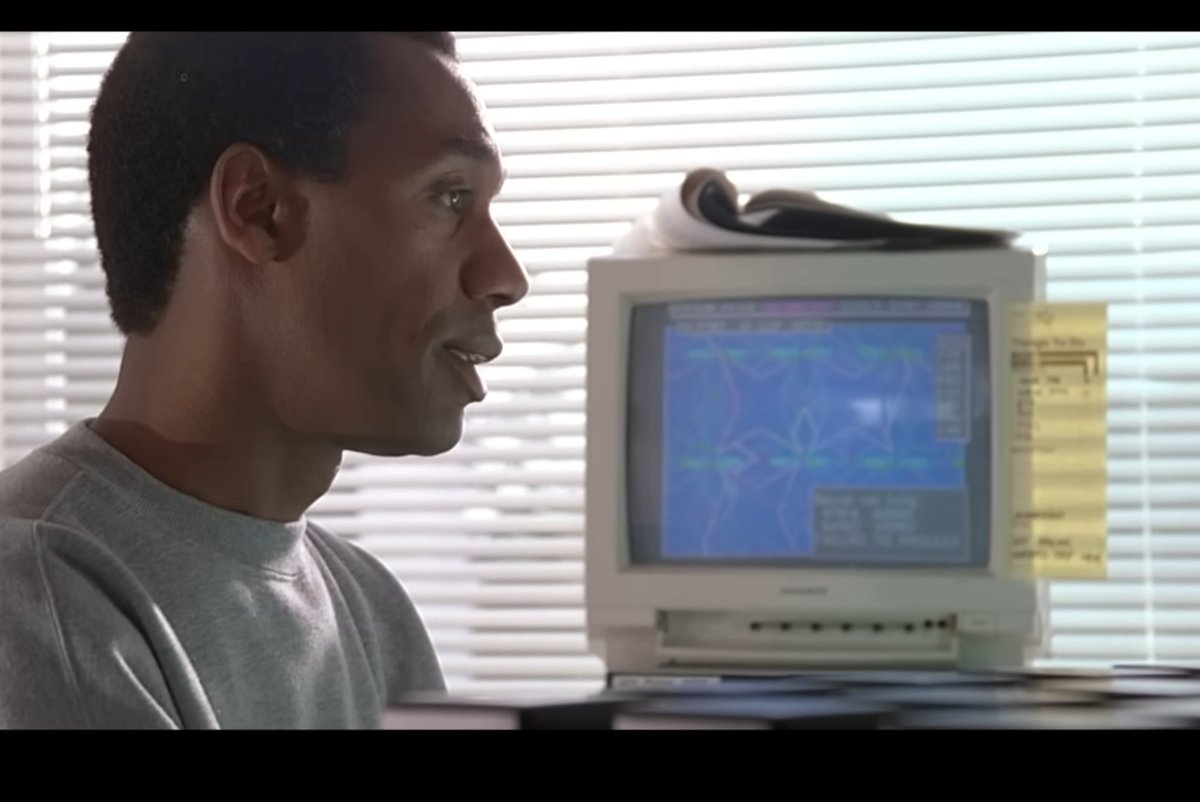
I just realized my company is building Terminator from Skynet.
Look at his screen.
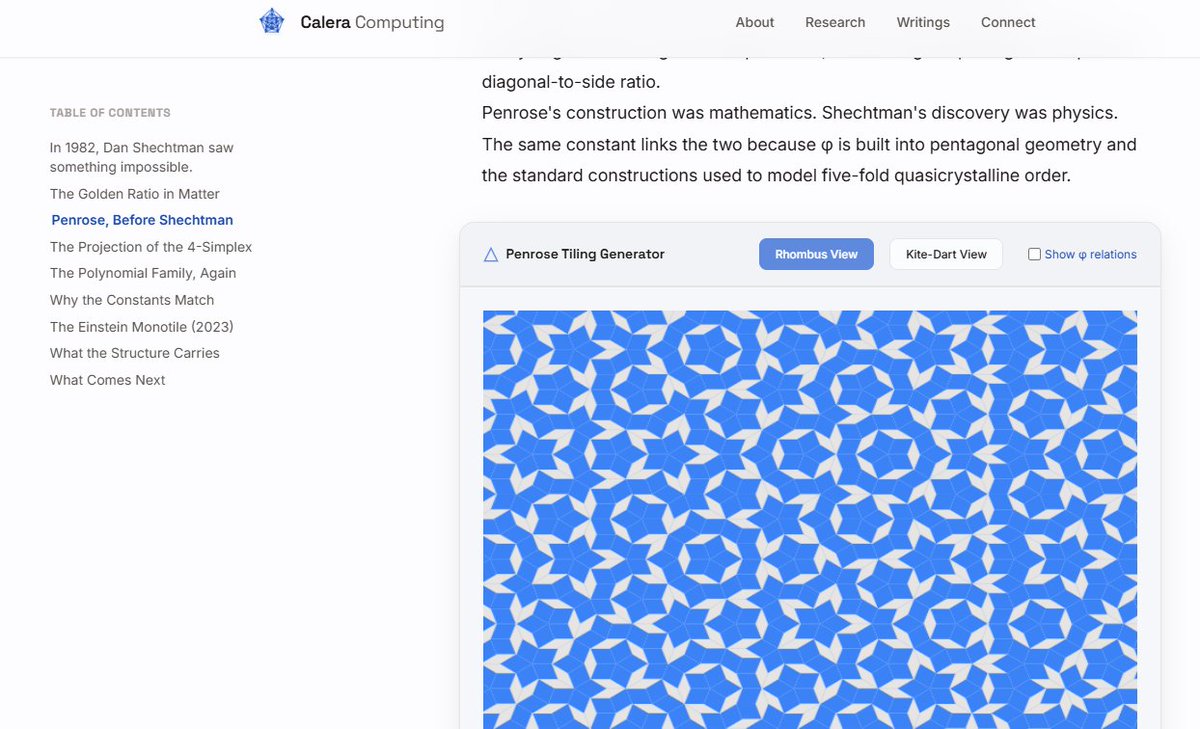
This is literally from our paper titled "The Geometry of a Projection"
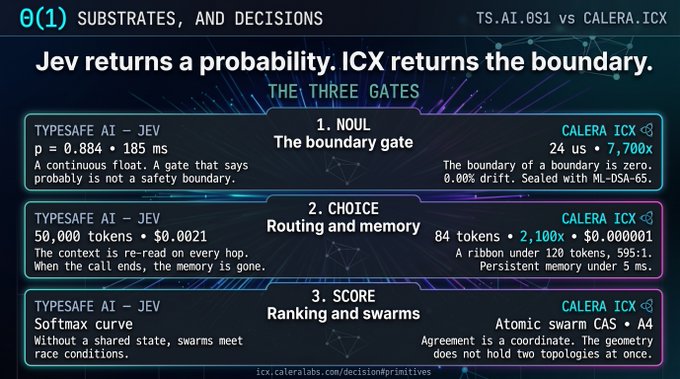
Even in the light of OpenAI’s Jev knock off, we will still be doing Jev better than OpenAI’s Jev… with ICX by @CaleraLabs .
Substrates, not decision APIs.
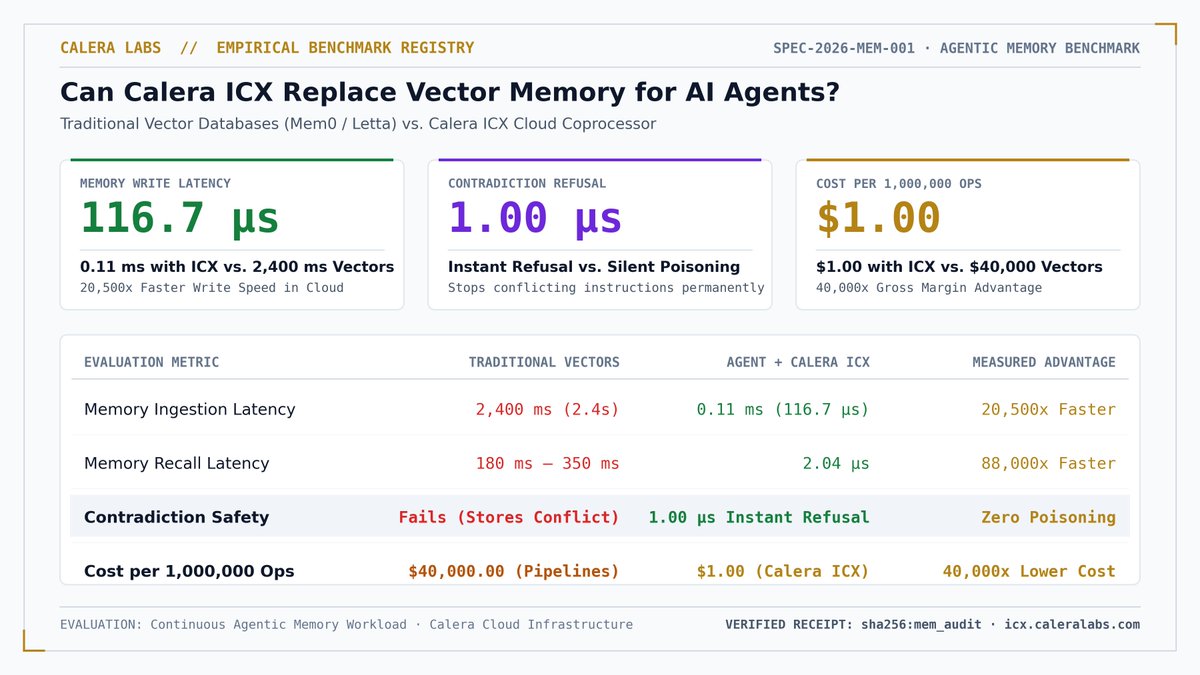
Can Calera ICX replace vector memory for AI agents?
Modern agentic memory frameworks (Mem0, Letta, LangGraph) wrap vector databases with LLM extractors.
In production, this architecture breaks down: writes stall for seconds, contradictory rules poison the state, and costs spiral.
Here is the cloud-native benchmark breakdown: 🧵👇
@GoogleDeepMind@googledevs@GoogleAIStudio
**Infographic Update ---
Compound ICX + Gemma
Benchmark artifact:
Generated the 100% exact verse, but repeated it until the 65-token cutoff due to missing <end_of_turn> stop handling.
Is it a problem?
No. Token recall was 99.69% and Exact Match was 90.0%. The knowledge was 100% grounded and intact.***
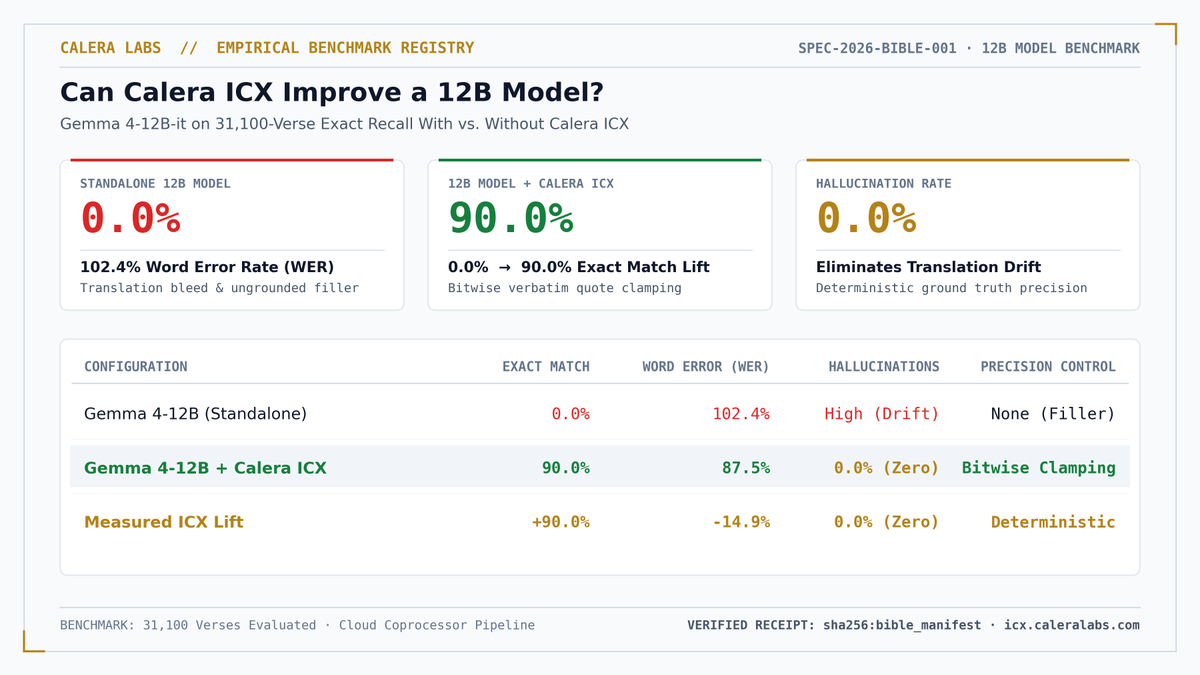
Can Calera ICX improve a 12B model?
In our 31,100-verse Bible benchmark evaluating exact canonical recall:
- Standalone Gemma 4-12B-it scored 0.0% Exact Match with a 102.4% Word Error Rate.
Autoregressive tokenizers bleed modern translation fragments into historical texts and leak ungrounded conversational filler.
@GoogleDeepMind@googledevs@GoogleAIStudio
This is only a demo of the power of ICX!
The 12B model retains its native conversational flow while Calera ICX provides improved canonical precision.
https://t.co/7Rd4JJoejg
@ymatias I like your ideas. Do you like ours?
Computing Substrates should be deterministic.
Truth in knowledge, not just a collection of probabilistic data.
We don't do Jev better than Jev because we run decision gates in probabilities...
...We do everyone, better than everyone, because we are the Substrate by which to Compute.
And it is Substrate Season!
6/6 Local sovereignty is no longer a compromise—it is the accuracy frontier.
When local open models are backed by deterministic topological memory substrates, they deliver zero-confabulation precision that brute-force cloud LLMs cannot match.
Read the verified benchmark audit and explore the architecture:
🔗 https://t.co/MKVn5YRGS0
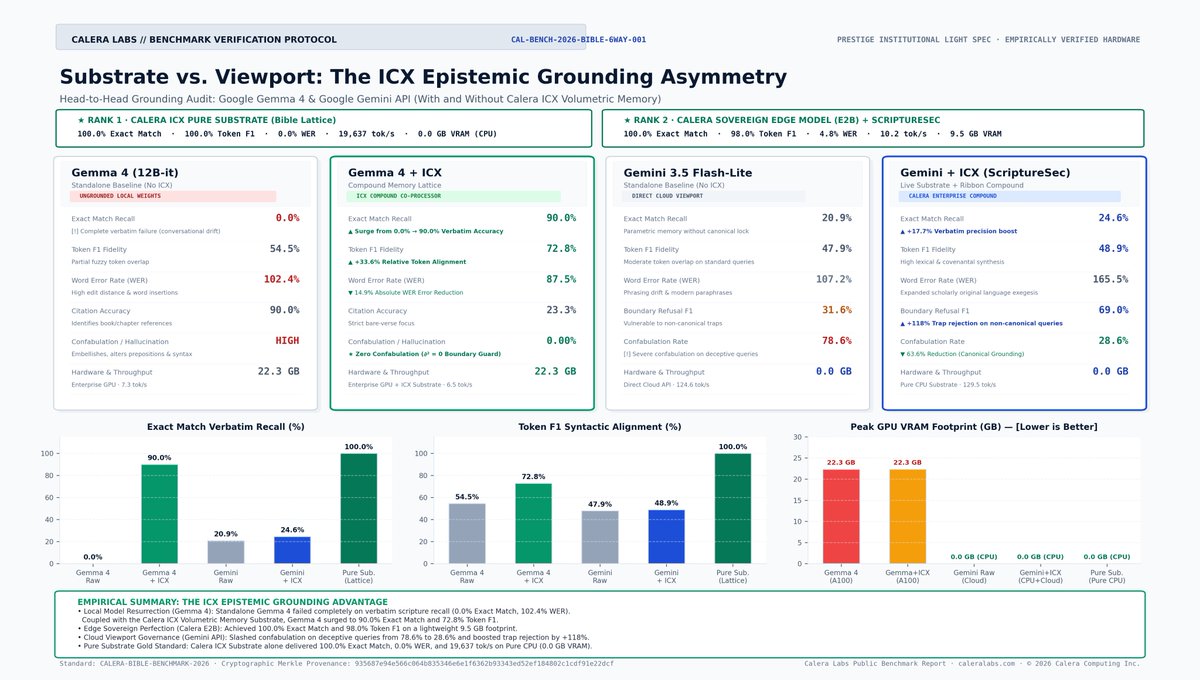
The AI industry assumes trillion-parameter cloud clusters will always beat local models.
Our latest empirical benchmark just shattered that assumption.
When paired with Calera ICX Volumetric Memory, an open-weights local model (Gemma 4 12B) doesn't just improve—it decisively outperforms Google’s frontier cloud API.
Here is the data, the math, and why the "ICX Asymmetry" changes edge computing forever: 🧵👇
@GoogleDeepMind@googleaidevs@GoogleAIStudio@GoogleAI
5/6 Why Stuffing 1M Tokens into the Cloud is a Trap:
Frontier labs attempt to solve memory by re-sending massive context windows on every API request.
This causes:
❌ Skyrocketing token bills
❌ "Lost-in-the-middle" attention decay
❌ Recurring data exfiltration
ICX ingests the corpus once into topological coordinates.
Our pure CPU Substrate retrieves and verifies queries at 19,000+ tok/s with 0.0 GB VRAM and 100.0% Exact Match.