I like GPT-5.6 Sol for long-horizon coding tasks: stronger reasoning, better context retention, and less drift.
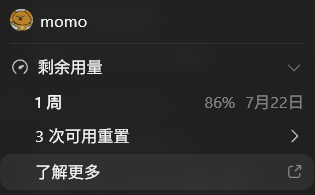
I switched to Codex to build my AI agent infrastructure more efficiently. Here’s my weekly usage 👇
I never explicitly selected GPT-5.4 or GPT-5.4 mini, yet a consistent portion of my daily requests are still routed to these models.
If Codex is automatically choosing models based on task difficulty, how accurate is that judgment really?