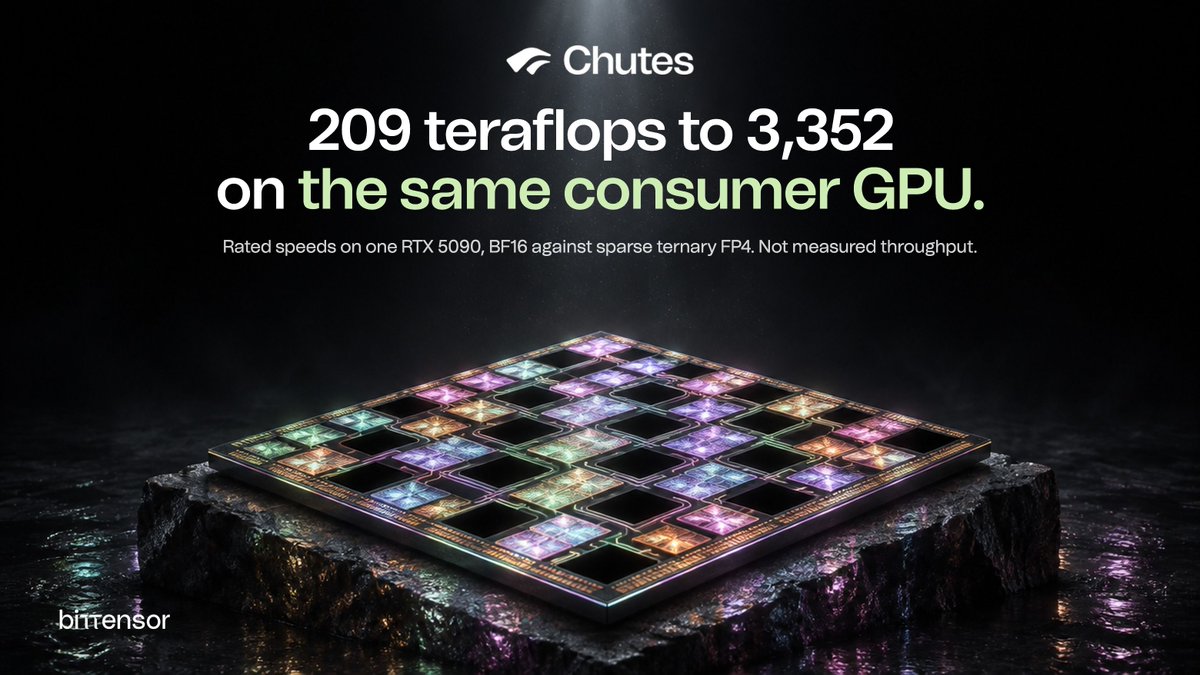
Most of the work inside an AI model is multiplying numbers. Parallax stores most of its weights as -1, 0 or 1, and at least half of those are zero, which a GPU can skip.
On one RTX 5090 that’s the difference between 209 teraflops and 3,352. Part of the jump is the card’s 4-bit mode, and skipping the zeros doubles it again. Those are the chip’s rated speeds, not measured ones.
It’s a big part of how one card hit almost 18,000 tokens a second.
Bittensor’s @chutes_ai trained Parallax 8B across hundreds of consumer GPUs around the world.
Now their latest preview shows it handling 256 AI requests simultaneously on a single gaming GPU.
The future of AI compute won't be confined to giant data centers.
How is it this fast? A small model, 4-bit math for the expert layers, and a fixed-size cache for most of the attention.
The Parallax paper: https://t.co/YlwB3vIAHM
Parallax runs at almost 18,000 tokens a second on a single RTX 5090.
That’s one consumer GPU answering 256 requests at once, on a vLLM fork that we put together.
The more one card can serve, the cheaper each answer gets 💪
GLM 5.2 Fast is live on Chutes.
https://t.co/g2XkceWw7X's GLM 5.2, for chat and agents where the reply is on the clock. 1M-token context, 128K max output.
Here's what GLM 5.2 is good at, on https://t.co/g2XkceWw7X's published scores: 81.0 on Terminal-Bench 2.1, four points behind Opus 4.8 at 85.0, and 62.1 on SWE-bench Pro, up from GLM 5.1's 58.4. https://t.co/g2XkceWw7X built it for long-horizon tasks.
Base URL https://t.co/AwJu7ktgOt, model zai-org/GLM-5.2-Fast, same key as every other model ofc.
$2.45 per million input tokens, $7.70 out.
Bittensor subnet @chutes_ai has partnered with Tencent Cloud.
Chutes is a launch partner for @TencentHunyuan’s new flagship AI model, Hy4, now available through its API.
Day-one access to leading AI models is business as usual on Bittensor.
@TencentHunyuan On launch day, @arena put Hy4 on Agent Arena’s cost/performance frontier across 8.5K+ real agent sessions.
It’s within about a point of Kimi K3.1 Pro (Max) and costs roughly 62% less per task.
Tencent says open weights are coming.
Tencent Hy4 is live on Chutes
We’re a launch partner with @TencentHunyuan.
It’s Tencent’s new flagship, and the first Hy model that can see. It reads screenshots and charts, and it can drive a terminal or a desktop app for you.
0.525$ per million tokens in, 1.5625$ out.
Already on Chutes? Just Change the model name to start using it
Try now: https://t.co/X3vw2tVr2i
Last Week in Chutes, week 24. Two weeks of news:
→ Seven new models on Chutes: DeepSeek V4 Pro, DeepSeek V4.1 Flash, Qwen3.8 Max, Qwen3.8 2.4T A95B, GLM 5.3, GLM 5.2 Fast and Kimi K2.7 Code. Same API key, same credits, just a new model id
→ Chutes is now pay as you go. Plus and Pro are gone, and you pay for what you use with credits. Plans you’ve already paid for keep working until the period ends
→ Timon’s essay on why we’re doing this: a pipeline that’s open all the way down, building models efficient enough to run on hardware you own
→ Parallax: dataset prep for the next pretraining run is almost finished. Around 10T tokens of high-quality data. Apple M5 and DGX Spark support are locked in
→ Chutes is live on SayGM, and Tencent Hy4 is on its way
Full write-up below ���
In case you forgot (we haven't). There is no universe in which chutes exists without bittensor.
Expanding our OpCo's service and refocusing on a healthier subnet dynamic has some people confused, but it's very explicitly for strengthening the subnet.
https://t.co/Hoi3CS6sXX roadmap/plan ICYMI
Qwen3.8 2.4T A95B is live on Chutes.
It's the open-weights model behind Qwen3.8 Max, and the first Max-class model Qwen has released openly. 2.4T parameters in total with 95B active per token. 262K context, with always on thinking
Qwen publishes its scores under the Qwen3.8 Max name, the API version built on these weights:
- 86.6 on Terminal-Bench 2.1, ahead of Opus 4.8 at 84.6
- 81.9 on WideSearch, ahead of Fable 5 at 81.2 and Opus 4.8 at 72.9
Here's how Qwen describes the difference from Max: text only, with thinking always on and a 262K context against Max's 1M by default. Same price on Chutes for both
$2 per million input tokens, $6 out.
DeepSeek V4.1 Flash is live on Chutes.
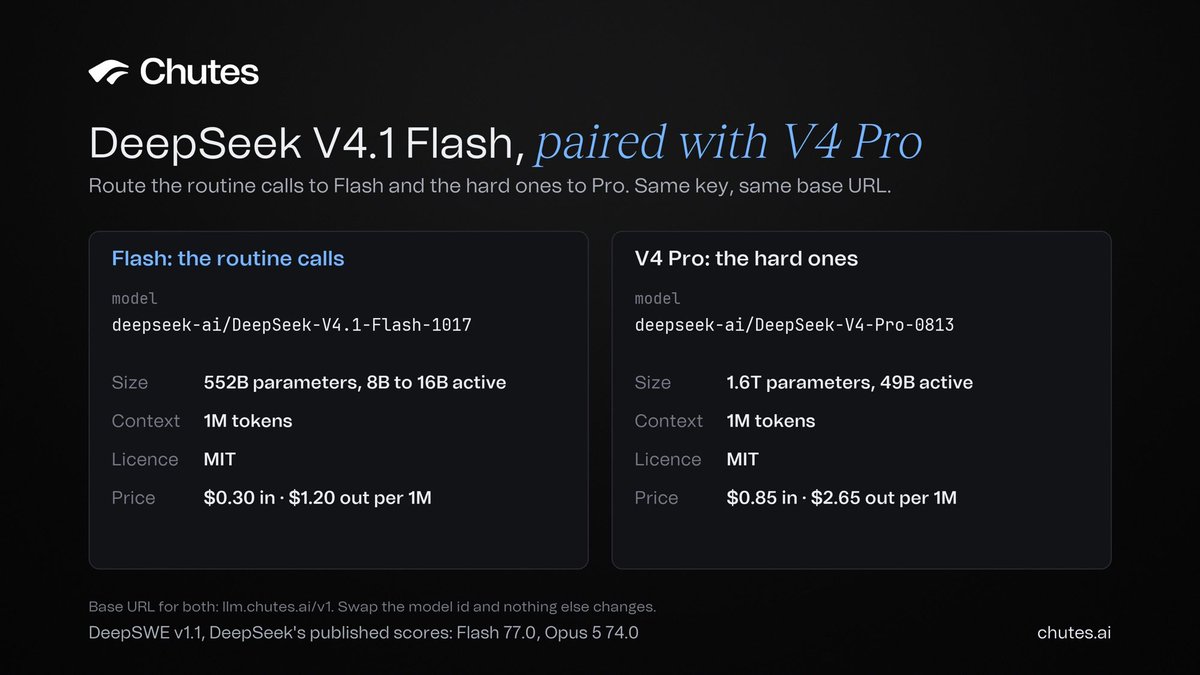
Pair it with V4 Pro: route the routine calls to Flash and the hard ones to Pro. Same key, different model id.
Flash is the lighter of the two: 552B parameters, with 8B active per token while it reads and 16B while it writes, against Pro's 1.6T. With the same 1M-token context window
On agent work it holds its own. On DeepSWE v1.1, DeepSeek's published score is 77.0, ahead of Opus 5 at 74.0, and on Agents' Last Exam it tops DeepSeek's table at 35.4. It trails Opus 5 on Terminal-Bench 4.0 (42.3 against 51.8) though, so keep Pro for the longest terminal sessions
$0.30 per million input tokens, $1.20 out.
V4 Pro is $0.85 and $2.65.
Tencent Hy4 is coming to Chutes 🪂
We're partnering with Tencent Cloud to bring it to the same Chutes API you already use.
Same key, new model ID
More soon 👀
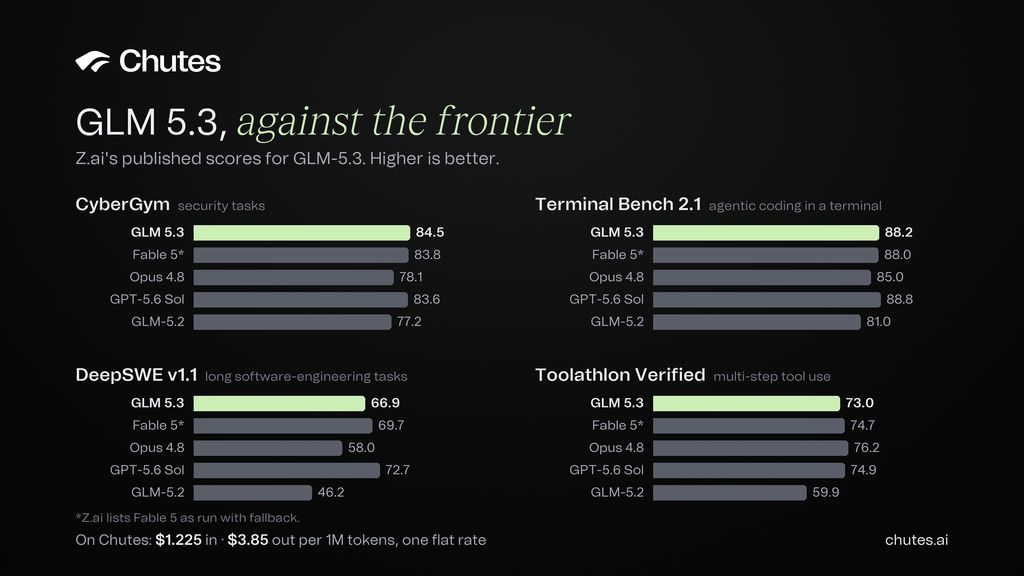
GLM 5.3 is live on Chutes.
It's https://t.co/g2XkceWw7X's flagship, built on the same base as GLM 5.2 and retrained for complex coding and long agent runs. 1M-token context, open weights.
Here's what to use it for:
- security review: on CyberGym, https://t.co/g2XkceWw7X's published score is 84.5, ahead of Fable 5 at 83.8 and Opus 4.8 at 78.1
- coding agents in a terminal: 88.2 on Terminal-Bench 2.1, ahead of Opus 4.8 at 85.0
Over GLM 5.2: 81.0 to 88.2 on Terminal-Bench 2.1, 46.2 to 66.9 on DeepSWE v1.1.
It does trail from Fable 5 and GPT-5.6 Sol on the longest software-engineering runs (66.9 on DeepSWE v1.1 against 69.7 and 72.7) though, so test it on your own repo first.
$1.225 per million input tokens, $3.85 out.
https://t.co/g2XkceWw7X's own API lists $1.40 and $4.40.