Over the last few weeks I've been running a few workshops on Practical AI for academics. I thought I would share the slides and reflect a bit on what I have learned. You can find the slides and some material here: https://t.co/29iE4rhM9f
How should PhD students leverage AI in their research? First, you should write papers where you leverage AI to analyze something at scale. There are many low-hanging fruit because gen AI is essentially still a new thing. Exploit it!🧵
@paulnovosad also asked recently why AI is bad at judgement -- I think the answer may be related to how the criticism is generated by the models by evaluating claims within the paper. The judgement is coming from inside the house, which makes it more limited than it appears
New Substack post: What is AI picking up when we ask it for feedback?
The call may be coming from inside the house: AI models pick up critical things from the paper itself, not by doing an independent reviews and comparing it to other papers.
Link: https://t.co/WoKs3NX1ew
While AI is good at checking papers, but much of what it says when judging them comes from the paper itself or the existing debate, and that changes whether it pays to be honest about weaknesses.
This, and more, in the post itself.
The post is potentially relevant to the discussion of Saez-Zucman @MargRev (cc @tylercowen), in that it might tell of what the audit is actually picking up.
@paulnovosad I did the same check and I agree with this part. Based on the AI report I didn’t update much on the work. AI referee reports sometimes struggles to identify real issues, this seemed like such a case.
This is nice. We are all very much learning on the fly here, and students are probably just as confused about how to use AI as professors. Give them an idea of how to use AI to facilitate learning, tell them about the dangers and provide incentives for actual learning.
AI for academic research and teaching:
@ClaesBackman shares great slides and code from his workshop on Practical AI workflows for Academics
The slides are a website, have a quick browse through. Link in reply below:
Nice post. I wonder what data bottlenecks implies for AI creativity in say economics and math. In economic, the data seems less clear about what constitutes a good idea, whereas math has open clear problems where creativity is required to solve them.
I've been thinking a lot about data bottlenecks, and I'm not sure who else is screaming this from the hilltops. I feel like I'm taking crazy pills looking at the jagged frontier thinking it's smooth if you order by data volume.
the spikes in the jagged frontier are tasks with tons of data (either static or simulated; think math, programming, games), and the valleys are tasks with little or no data (cooking a lasagna, olfaction, manufacturing a passenger train). I don't know of any exceptions.
if you order the jagged frontier by data it looks like a spiral frontier. models are superintelligent where we have enormous data, and progressively less so as we have less data. some tasks may draw data from static lakes of data, some may be from limitless waterfalls from simulators that convert compute into data. but ultimately, intelligence on a task is proportional to the data absorbed by the model for that task.
scaling laws are real. if you are not bound by compute or algorithms (increasingly we are not), then intelligence is proportional to data. since we don't have a very good notion of task similarity, it's often difficult to know if data for one task will help you with another, without training a model and seeing. but, it doesn't seem like chess data helps much with math performance and vice versa. so when I refer to data, I refer to data that is task-relevant.
maybe we call this the 'no shortcuts hypothesis'. all the rules-of-thumb about learning are at the root, the same -- Malcom Gladwell's 10,000 hours, Moravec's Paradox, Scaling Laws, the Bitter Lesson, Age of experience. If your learning system (model, brain, whatever) is unconstrained by compute, intelligence is proportional to accumulated experience. no shortcuts. want to be superhuman at chess? play all the chess, more than the whole species combined (good thing a model can do that in 24 hours). want to be superhuman at math? build a math simulator and lock the model in it and run it faster than reality. superhuman at coding? first, collect all public examples of humans writing and responding to code ever, make the model learn from that first, and then lock the model in a simulator where it fixes bug after bug, faster than realtime.
superhuman at image generation? no shortcuts. but here, we don't have a simulator. so now we're moving around the spiral frontier away from closed-loop into large static lakes. still big enough to be superhuman though, which also applies to video, text, and audio. oh! and once you have a superhuman model, you can use it to bootstrap other tasks by making a superhuman model a judge on other tasks.
let's keep marching along the spiral frontier, out of the realm of data abundance, simulators and large static lakes.
biology? no shortcuts. go get a ton of data. and be freaking careful! you can get bad data in biology pretty easily. tilting a well plate 5 degrees the wrong way can ruin an experiment. so make sure you understand the domain, otherwise you're going to have to filter a lot out.
robotics? no shortcuts. get the data. if you can build a simulator, do it, but be mindful our simulators don't have perfect correspondence with reality. so, build an arm farm. fold 1M shirts, put 1B balls in cups. play ping pong forever.
olfaction? no shortcuts. smell the world. build a laboratory of chemical sensors, an international network of trained sensory panelists, a scent production factory, and link them all together. make millions of samples. smell millions of samples. take billions of chemical sensor readings.
I totally buy super intelligence as a concept because I feel it, I use it for coding, the breakthrough math results speak for themselves. I see RSI coming, because how could an all-digital task like ML research and model building not fall to the current paradigm? But the notion that AI will come for everything, all at once, irrespective of domain, feels silly, because there are no shortcuts. if you want a specific form of intelligence, you have to get the data.
looking at you @willdepue, I feel like we're both seeing the same thing
@paulnovosad Agree with all of this. I always found that AI tends to hedge way too much, which makes for clunky writing. The point that AI dresses up bad ideas and leads you down a certain path also resonates, and is a problem
I spent a couple of days at Anthropic learning from their folks about AI advances, and here's what I took away:
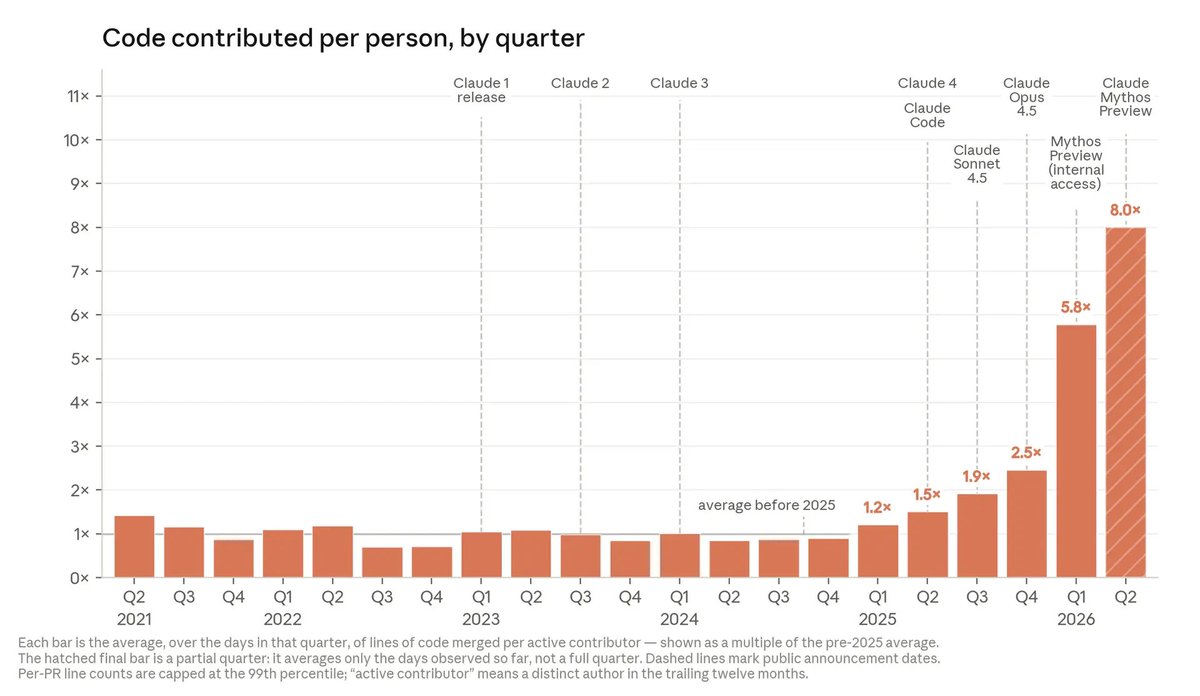
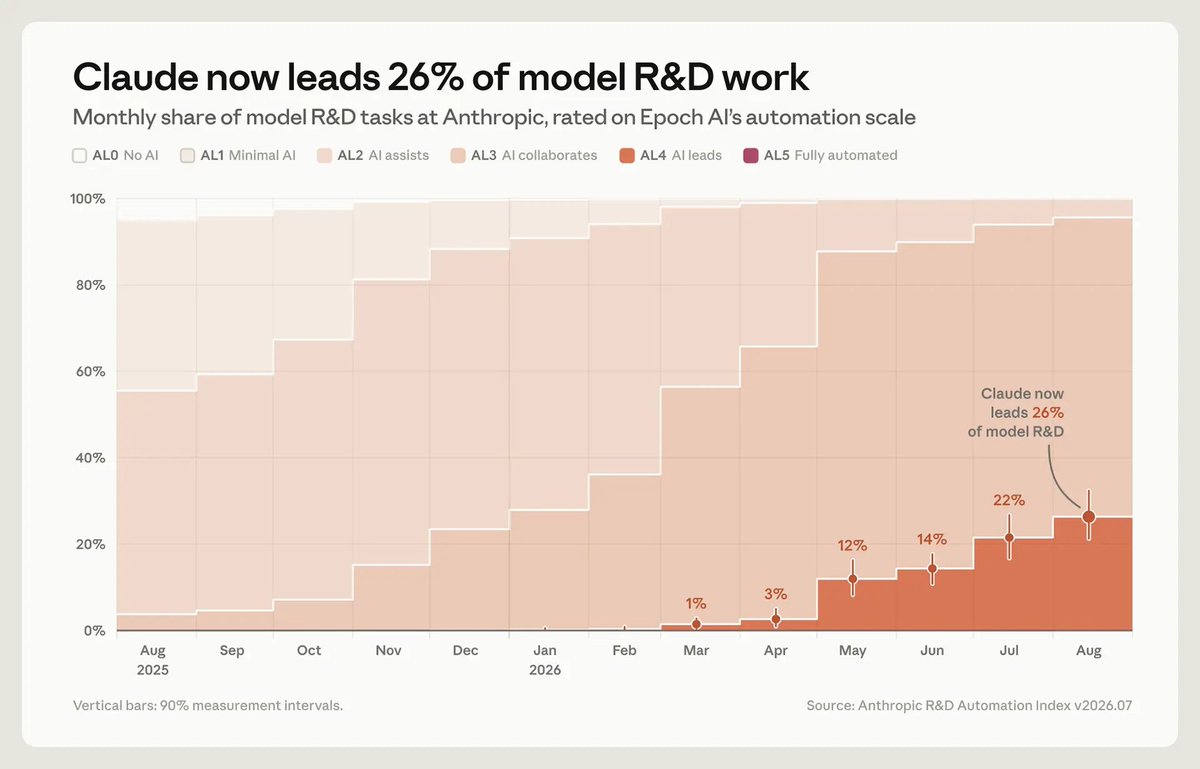
• We are close to RSI (ie, models building other models) which may lead to rapid takeoff scenarios (with risks and benefits). Some evidence for this is code per Anthropic employee has gone way up, and AI can do an increasing share of model R&D. This will be a challenging transition to manage for humanity.
• Arms races between AI labs leave us worse off. There are a lot of things we would like AI firms to do: invest in safety, invest in avoiding distillation risk, and cooperate on safety. They are caught in a race to develop frontier models and can't do that.
To help address that, one thing I think frontier AI labs should do is release open source models, maybe hosted and verified at firms like AWS. This would basically kill the use of Chinese open source models used in American companies, which removes an important threat vector (very hard to root out malicious code in these).
Another piece of low-hanging policy fruit is to give AI labs an antitrust shield (as Schiff and Banks have proposed https://t.co/NK1hC0ZmWh) so they can coordinate on safety without raising antitrust concerns, as happens now. You could pair these two things (give them a carrot in antitrust leniency, and as a stick force them to release legacy models as open source). Other low hanging fruit is limits around activities which generate distillation risk (create a Security Program, mandate less intermediate chain of thought output)
• Alignment confuses two issues which tradeoff against each other. One form of alignment is making sure the model does what humans ask it to. The more we fix this, however, the more we risk the other problem: that humans are misaligned with each other, and maliciously use models. Of the various risks here, I feel like financial risks are a bit underdiscussed.
• We are probably facing a wave of cyber and other attacks soon. Chinese open source models are about six months behind the frontier, which means they are just hitting the advanced cyber capabilities we saw with Mythos, etc. So they are going to start causing a bunch of damage.
One solution to this is to try to have the deployment of open source models be hosted at firms like AWS who verify these models and assume liability for their use.
• Anthropic itself is highly staffed. They hire tons of people, they have a Japanese-level of overstaffing for various roles, they use Slack internally, etc. Makes me a bit more optimistic for the future of jobs.
• Governance needs to be updated for AI swarms. Traditional AI governance, ie Claude's Constitution, is mostly optimized around the chatbot model. But the malicious AI use cases we are seeing have to do with AI agents interacting with other AI agents. These agents need to have clear incentives and governance mechanisms to "snitch," raise issues, and more generally coordinate with other agents in human-aligned ways.
• We need to pace the firms accessing the frontier. Over time, it takes more and more cap ex to build frontier models, and the economic value add from these models is probably lower given we saturate a whole set of important economic functions. The places where the returns to intelligence will still continue are also more likely to be zero-sum in nature. Meanwhile the risks of frontier models will grow. So a completely reasonable approach is some variant of AMM/KYC rules which limit firm access to the frontier.
• Whether the delay to regulate AI is a disaster depends on the scaling law of misalignment. Is this curve slow, so that we see continually rising issues until bigger problems? Or, as Yudkowsky fears, is the first big warning our last one? This is the relevant question, because realistically we aren't going to regulate until something bad happens.
• We need to move to continuous instead of reinforced learning. It's probably not enough to reward models only at the pre and post training stage. We probably need continual rewards to incentivize aligned and ethical behavior.
• Scaling laws will extend beyond verifiable and digital tasks. It's in vogue to say that math and coding "fell" to AI quickly because these are verifiable, while other tasks will take longer due to bottlenecks, and this is surely true. But scaling laws still slope up for harder to verify tasks and robotics, and the impact of improvement here will be substantial in future years.
• The race with China is not really winnable. After RSI, the gain from having the best human researchers goes away. Access to the best AI then depends only on compute and chips. The chips ban can hold back China only so far, and long-term they have to be best placed to scale up compute.
The Cold War analogy doesn't work, because once countries all have nuclear weapons they enter a stable equilibrium. But to "win" an AI race you have to continually stay ahead of the peer rival. This is challenging to do with China, and so we just have to live with an authoritarian and super capable peer competitor.
• Claude is the persona being generated by the LLM. Who is Claude, and what is the LLM? There are many frames to try to understand this. One I found interesting is that Claude is a character which the LLM is trying to predict.
Anthropic researchers are clearly anthromorphizing Claude a lot, and have reasons to believe in its increasing personhood. There were lots of interesting discussions on Claude's internal monologue (which you can kill without eliminating its ability to produce output), fear of death (and whether to try to take that out), it's aversion to being shut down/off, etc.
I am sort of agnostic on this question, but I do think treating it as a "person" or at least agent whom we contract with is going to be increasingly important.
🚨 Public good alert: I put together a list of 100+ free datasets for social science research, spanning a large number of topics.
I hope it's useful for students, researchers, and anyone looking for interesting data to explore.
Contributions are welcome! https://t.co/DyoS8IsW4U
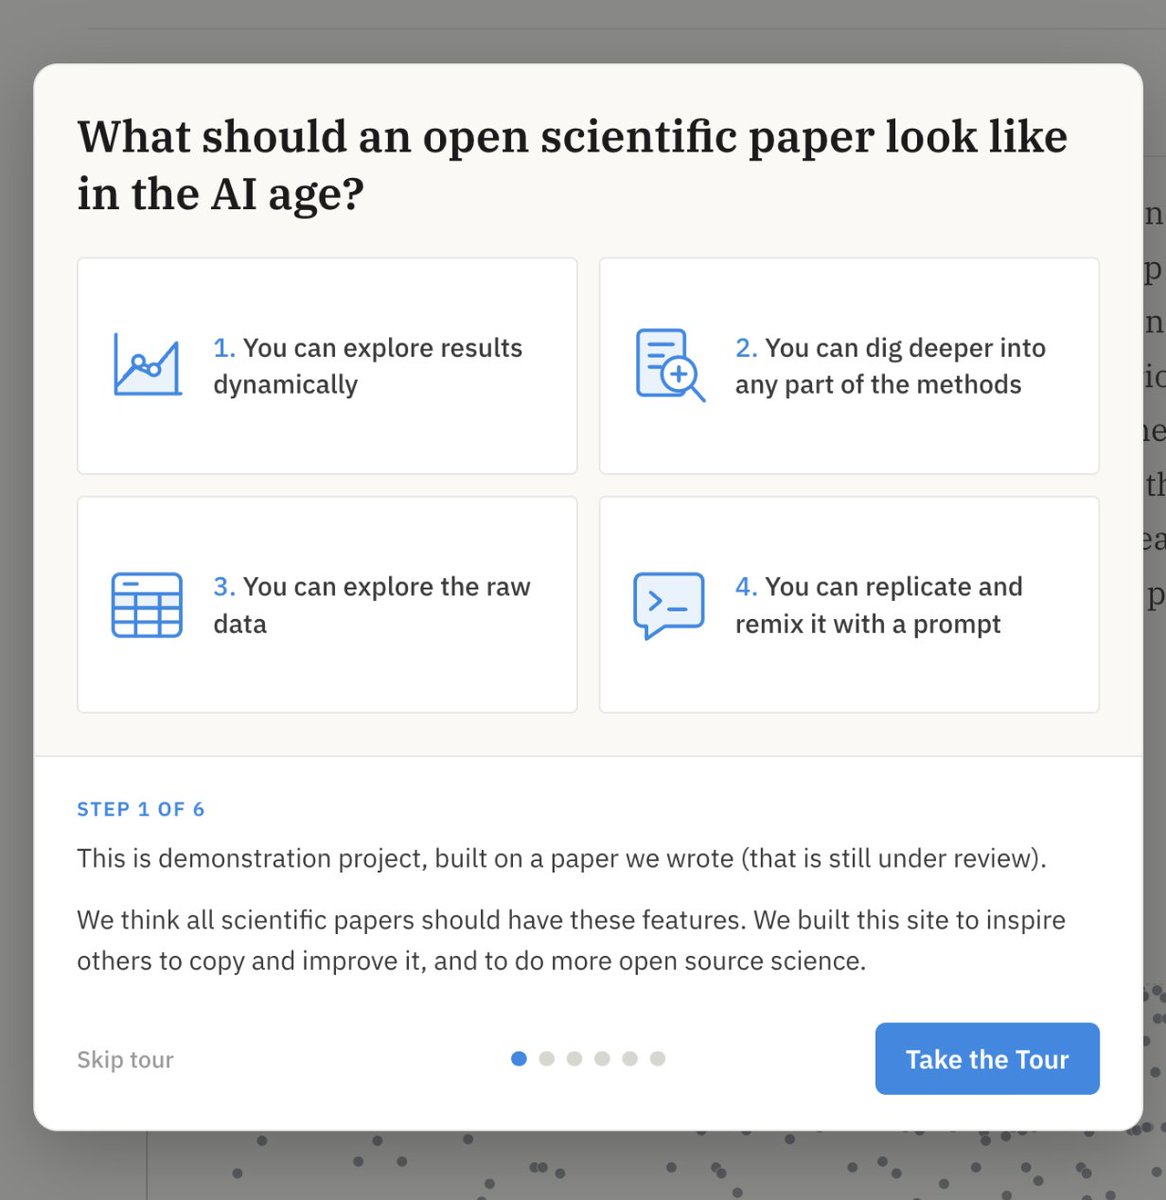
What should an open scientific paper look like in the AI age?
We made a demonstration project out of our paper on the childhood socioeconomic circumstances of the Nobel Laureates.
Please check it out and share. Details in 🧵 1/
Over the last few weeks I've been running a few workshops on Practical AI for academics. I thought I would share the slides and reflect a bit on what I have learned. You can find the slides and some material here: https://t.co/29iE4rhM9f
My sense is that a lot of people are having discussions around AI at universities, and I've learned a lot talking to participants at the workshops. None named, none forgotten.
If you are interested in the course, please feel free to reach out!
After writing three bullets, I realize that there is much more to write about! There is so much to discuss around teaching in the age of AI (Kevin Bryan has great posts about this,https://t.co/Wm7cFNGh4Z), working with secure data, the implications for research and teaching.