@piotr_minkowski Worth adding a rule that agents never edit applied Flyway/Liquibase migrations, only add new ones. Rewriting V12 passes locally on a fresh DB and then fails checksum validation on every env that already ran it. Easy thing for an agent to "fix".
@askalphaxiv Same pattern as long-lived services leaking state. The fix there is checkpoint + restart, and it maps well: persist only distilled findings and open hypotheses to a store, then start a fresh context from that. Forgetting becomes a deliberate write path, not truncation.
@SciFi The failure mode with compaction is silent: the summary drops a constraint like "don't touch the migration" and the agent violates it 40 steps later. Keep commitments in a separate pinned list that never gets summarized, and diff it before and after each compaction.
@tpschmidt_ One org bus also means one shared blast radius. PutEvents throttling from a noisy account now hits everyone, and a sloppy rule pattern can match events from accounts it was never meant to see. Pin every rule on account + source, and keep a DLQ per target.
Fix: send Cache-Control: private, no-store on anything per-user.
Check CDN rules that override origin headers. Keep public and per-user data on separate paths. Test with two accounts and watch the cache status header (CF-Cache-Status, X-Cache).
Mechanism:
/api/me went out with Cache-Control: public, max-age=60, or a CDN "cache everything" rule matched the path.
The cache key is the URL. Your session cookie isn't part of it.
The first user's response gets stored. Everyone after that gets a HIT.
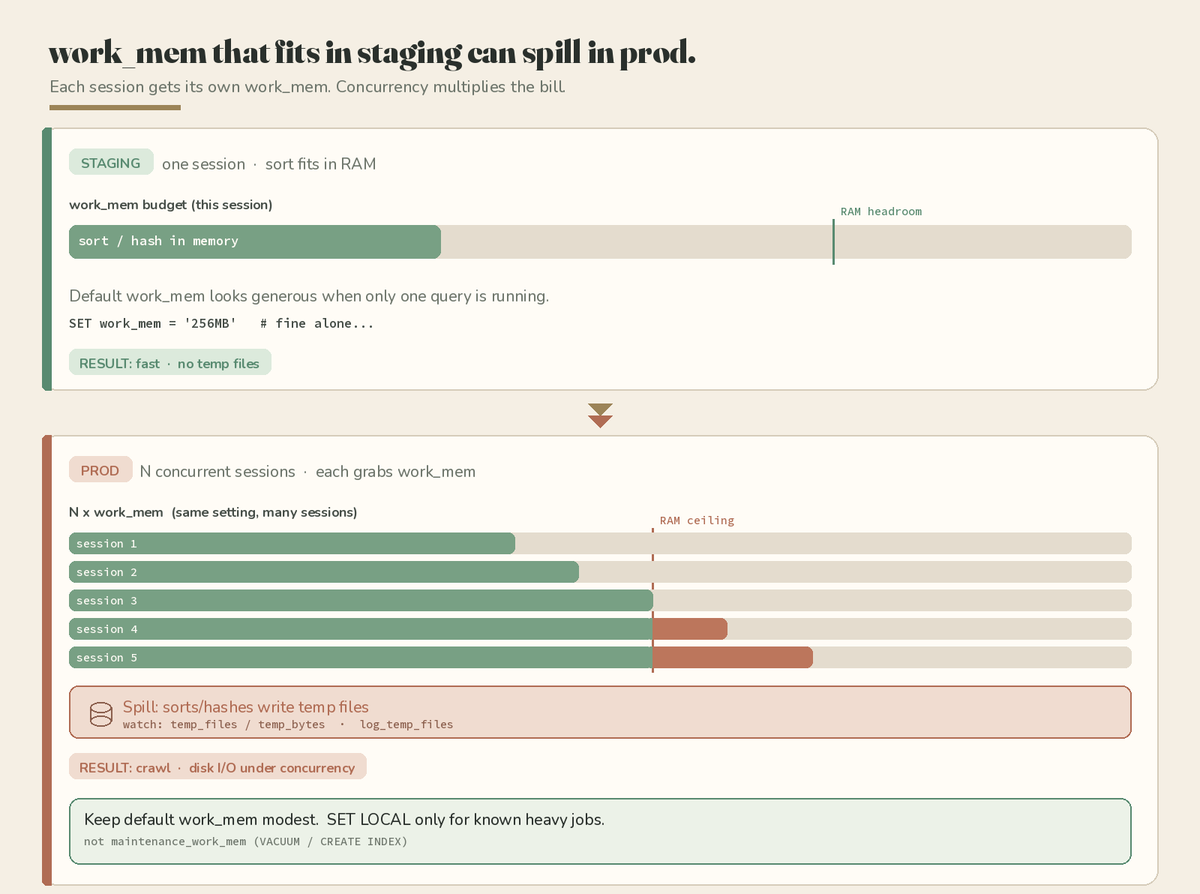
Fix: keep the default work_mem modest.
Raise it only for known heavy jobs with SET LOCAL. Watch temp_files / temp_bytes (or log_temp_files). Shrink sorted row width. Don't confuse this with maintenance_work_mem (VACUUM / CREATE INDEX).
Mechanism:
Postgres gives every session its own work_mem for sorts and hashes.
Staging: one query, the sort fits in RAM.
Prod: N concurrent queries each try to grab work_mem. Pressure, then temp files on disk.