Comprehension Labs is an expert research team building datasets and RL environments from how people learn, reason, speak, and work.
Starting with 6,000+ hours of judged debate.
Request a sample or license your data at
https://t.co/0cGRGOb7l2
AI needs the full path to human capability.
Introducing @ComprehensionAI, an expert research team building datasets on how people learn, reason, speak, and work. Not just outputs. The attempts, feedback, and judgments behind them.
Starting with 6,000+ hours of judged debate.
An expert corrects one mistake. The real question is whether that correction carries into the next problem.
That's longitudinal data, and it's what we're building at Comprehension Labs. Here's what one connected trace looks like.
Buying or collecting this data? DM me.
An expert corrects a mistake. What happens on the next attempt?
At Comprehension Labs, we're interested in how feedback changes work and whether that change carries into a different problem.
Take a code review. An engineer submits an implementation. A reviewer identifies an edge case, explains the issue and requests a change. The engineer revises the code and adds a test. Together, the task context, original version, review, correction and result form a production trace with human judgment attached.
Now connect that record to the engineer's next task. Do they catch a similar issue before review? Can they apply the feedback when the requirements change? Does the same mistake recur?
That connection is the longitudinal part. It lets us examine how decisions and approaches change across repeated work. A successful edit shows that a correction was made. Later attempts give us evidence to investigate whether the feedback carried forward.
For that evidence to be useful, the details need to stay connected. Feedback belongs with the version it addressed. An approval needs its criteria. An outcome needs its context. Expert checks and recorded explanations help make those decisions interpretable.
This is what we're building around: production traces organized into connected histories of attempts, feedback, revisions and outcomes. Our goal is to make these records useful for AI training and evaluation while preserving the context that gives them meaning.
If you're buying or collecting this kind of data, or your company captures these traces in its workflows, we'd love to chat. DM us or book a call at https://t.co/wqLtKRqO1d
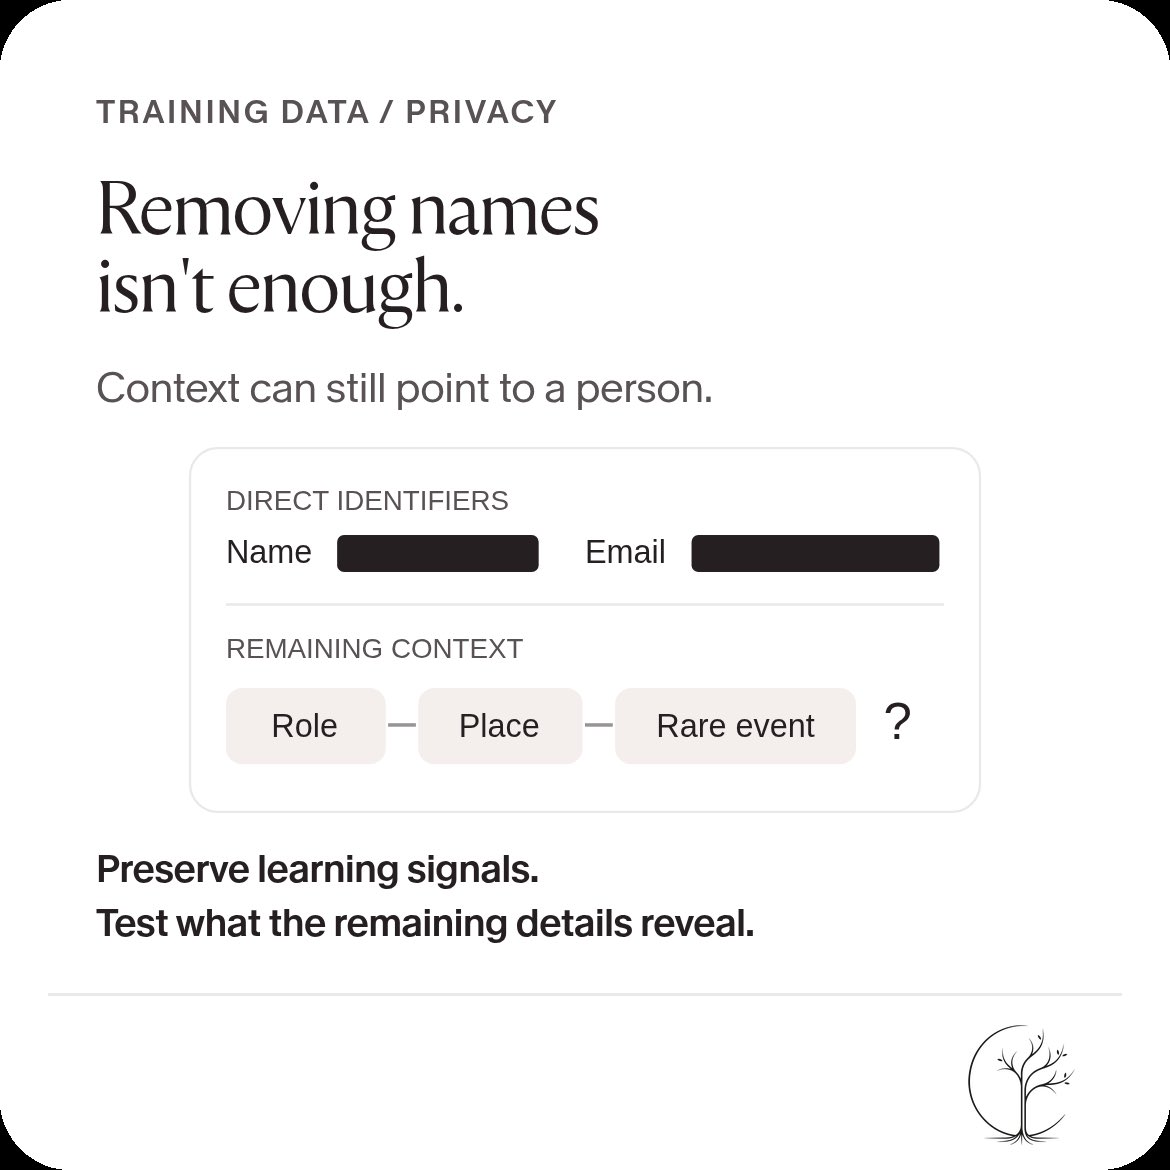
PII scrubbing is more than removing names. Context and combinations of details can still identify someone. For training data, the challenge is to preserve useful learning signals while testing what the remaining details could reveal.