AI needs the full path to human capability.
Introducing @ComprehensionAI, an expert research team building datasets on how people learn, reason, speak, and work. Not just outputs. The attempts, feedback, and judgments behind them.
Starting with 6,000+ hours of judged debate.
An expert corrects one mistake. The real question is whether that correction carries into the next problem.
That's longitudinal data, and it's what we're building at Comprehension Labs. Here's what one connected trace looks like.
Buying or collecting this data? DM me.
An expert corrects a mistake. What happens on the next attempt?
At Comprehension Labs, we're interested in how feedback changes work and whether that change carries into a different problem.
Take a code review. An engineer submits an implementation. A reviewer identifies an edge case, explains the issue and requests a change. The engineer revises the code and adds a test. Together, the task context, original version, review, correction and result form a production trace with human judgment attached.
Now connect that record to the engineer's next task. Do they catch a similar issue before review? Can they apply the feedback when the requirements change? Does the same mistake recur?
That connection is the longitudinal part. It lets us examine how decisions and approaches change across repeated work. A successful edit shows that a correction was made. Later attempts give us evidence to investigate whether the feedback carried forward.
For that evidence to be useful, the details need to stay connected. Feedback belongs with the version it addressed. An approval needs its criteria. An outcome needs its context. Expert checks and recorded explanations help make those decisions interpretable.
This is what we're building around: production traces organized into connected histories of attempts, feedback, revisions and outcomes. Our goal is to make these records useful for AI training and evaluation while preserving the context that gives them meaning.
If you're buying or collecting this kind of data, or your company captures these traces in its workflows, we'd love to chat. DM us or book a call at https://t.co/wqLtKRqO1d
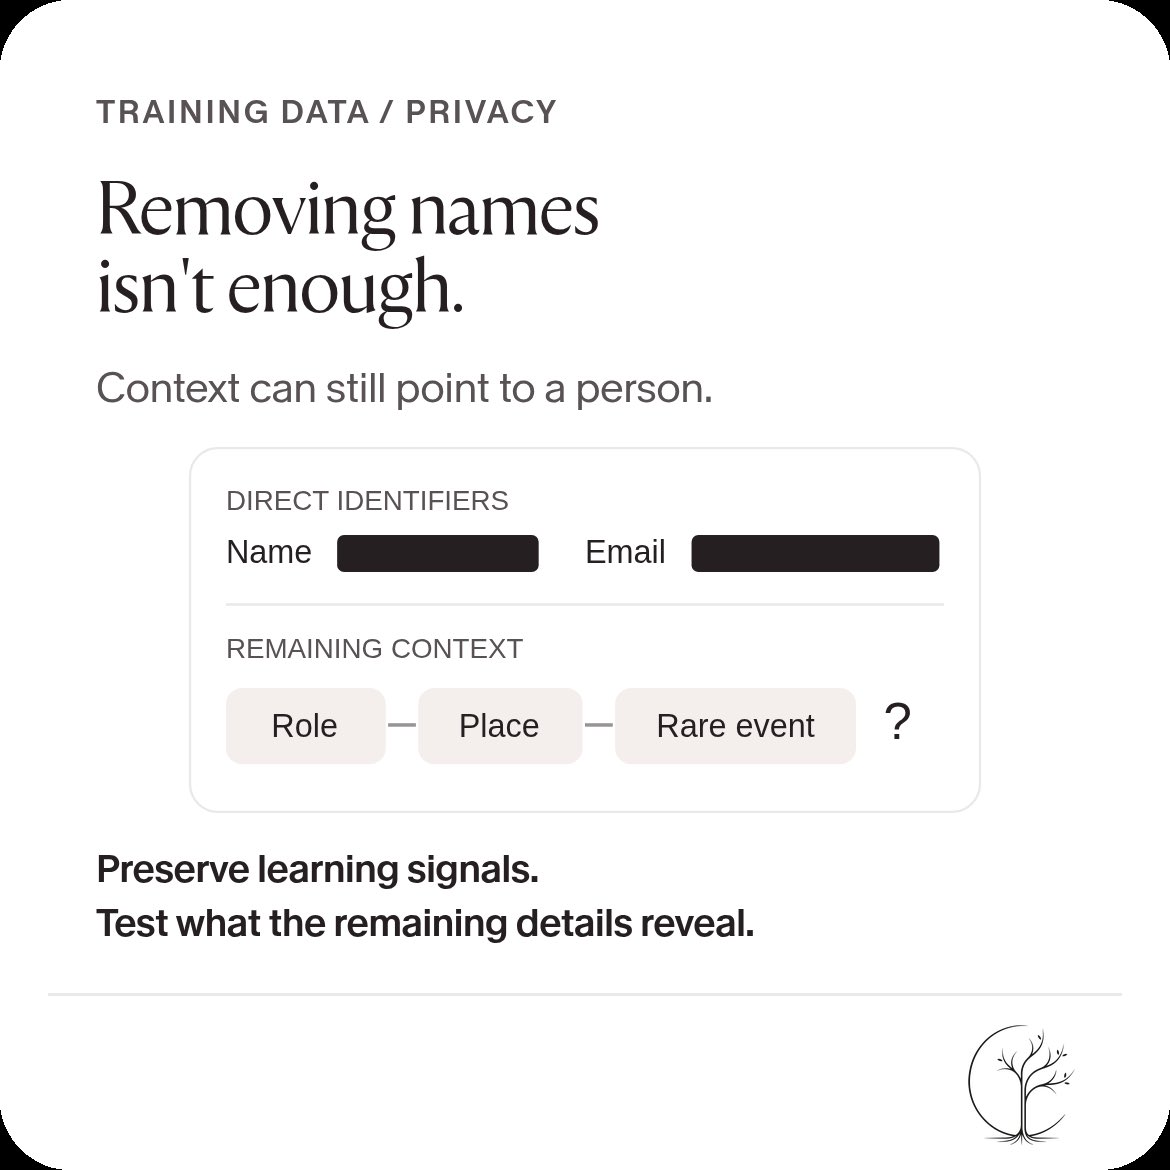
PII scrubbing is more than removing names. Context and combinations of details can still identify someone. For training data, the challenge is to preserve useful learning signals while testing what the remaining details could reveal.
Unique data only matters if it's tasked correctly. A lab can't price a pile of data, but it can price a task where models fail in a measurable way, and that holds when the seed is real human judgment.
Generic data brokers will fail. High quality tasks will always be the moat.
So bearish on all these new data brokerage companies with zero domain expertise in RL, no lab is going to assume the risk of purchasing your dataset without the providing the training ready environment and calibrated tasks to prove difficulty. The reality is 99% of the value comes from task creation on top of the seed data
Built at Berkeley by an expert research team from BAIR, Berkeley EECS, Amazon Alexa, Meta, AppLovin, and Alation.
Need a custom dataset, or have learning data to license? [email protected] or https://t.co/YTQ8nhfZ6W
AI needs the full path to human capability.
Introducing @ComprehensionAI, an expert research team building datasets on how people learn, reason, speak, and work. Not just outputs. The attempts, feedback, and judgments behind them.
Starting with 6,000+ hours of judged debate.
We're starting with debate, building the largest debate and discernment dataset. 6,000+ hours of rights-cleared rounds with judge verdicts and written reasons.
Why it matters. AI increasingly judges AI, and several models can confidently share the same mistake.
Most data companies organize the world by modality. We organize it by how capability develops, from attempt to feedback, revision, judgment, and outcome.
Four branches:
Reasoning and judgment
Multilingual speech and TTS
Longitudinal learning
Expert work and computer use
AI made us 100x engineers. But outside code, we're still copying context between 6 chat threads and explaining ourselves from scratch.
So we built Turnstone: a free AI workspace for running persistent agents that actually know your work, powered by a second brain that lives on your machine.
Don't just be a 100x engineer. Be 100x at everything.
https://t.co/wc2cXoggSQ
Most evenings I just end up at the gym
People call it discipline. It doesn't feel like discipline
I think I finally understood why. Put some thoughts in this article https://t.co/lt1pUJXOAL
This Independence Day 🇮🇳, I asked, "What will the next century of young Indians look like?"
$0.01 Drone Deliveries. UAVs that never land. Groceries in under 10 minutes.
Meet The 22nd Century Indian. A Documentary on a New India.
Just took time watching @shaurya_sinha7’s 22nd Century Indian while waiting to board my plane back to SFO and I feel motivated to fly and take my next leap while building.
Oftentimes, I’ve been worried or scared to try new ideas or put myself out there because it’s not “perfect”.
And I think in this pursuit of perfection, what does get lost is the ability to put out incomplete ideas and eventually the motivation to build.
This is what I have been doing subconsciously and after watching this film did it strike me that goal of taking risks to not worry abt falling.
So, I am going to be more active socially and @buildinpublic.
Thanks Shaurya for reminding us that “For even if you fall, the greater fear is not never fly at all”.
Highly recommend taking time to sit and watch the 22nd Century Indian 🙌
This Independence Day 🇮🇳, I asked, "What will the next century of young Indians look like?"
$0.01 Drone Deliveries. UAVs that never land. Groceries in under 10 minutes.
Meet The 22nd Century Indian. A Documentary on a New India.