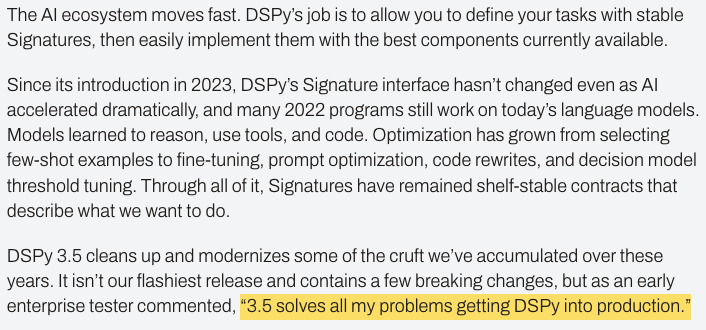
Nice section in this AWS post on ShipStation Global’s AI IT help desk.
A dspy.RLM module holds their entire Slack history as a variable, and mines it into a knowledge base of resolved issues.
https://t.co/tlFE0RiCho
we showed how @DSPyOSS improves our extraction quality substantially (measured by our own expert-curated ground truth released on HF https://t.co/niQOORPdNK, together with a metric to measure this "as humans would" judged on another expertly judged dataset on HF https://t.co/SFd8UEhQSF)
Diane shows that a big model can continually RL a tiny retriever model, allowing a 0.4B parameter model to match or crush an 8B parameter, over time.
I am super interested in this pattern for agent memories, addressing "memory rot" and constantly evolving personalized search.
Never felt closer to a fundamental change in how we build retrievers, and a different kind of memory for agents.
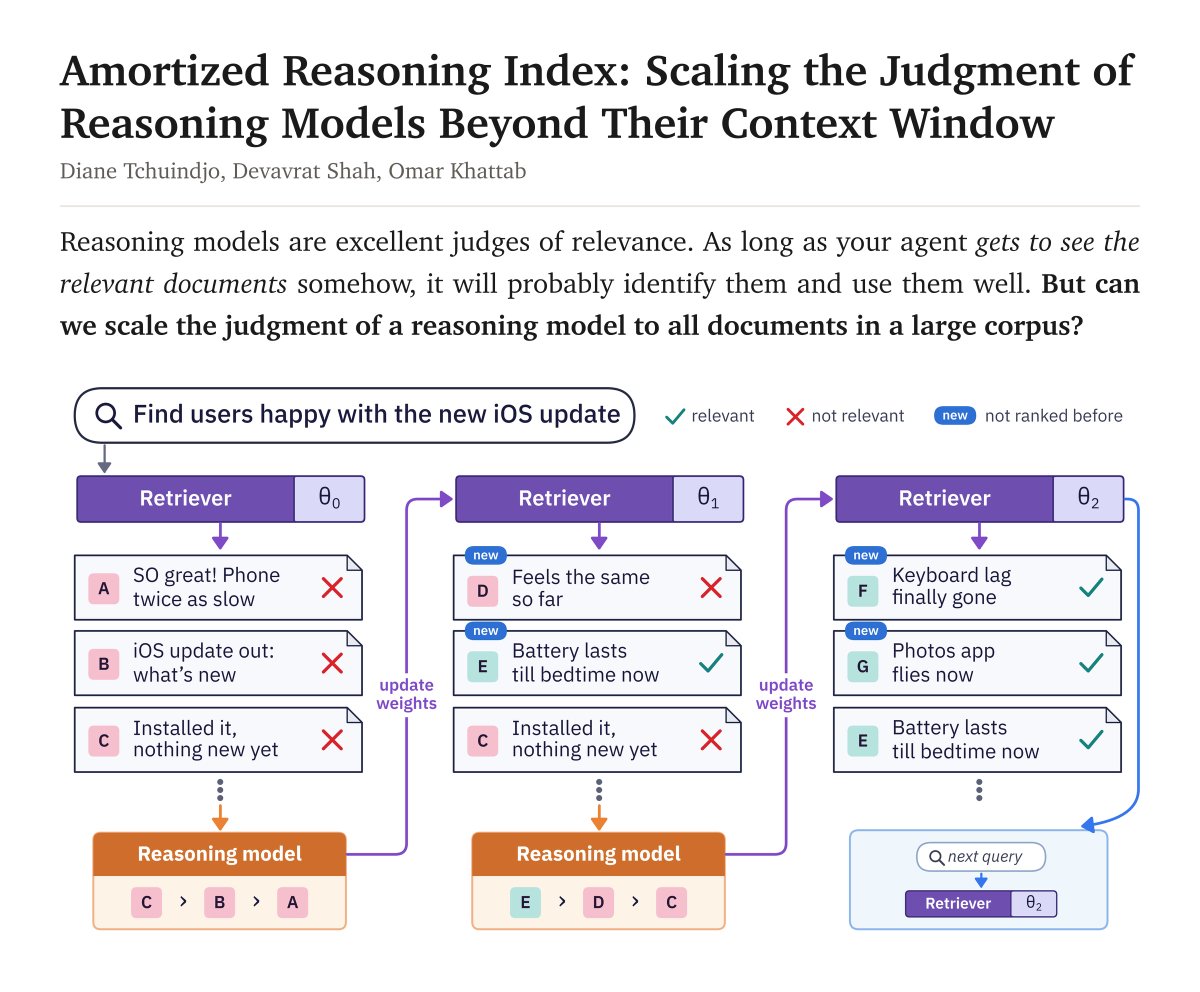
ARI is basically test-time training for retrievers, where gradients derived from a reasoning model's preferences teach the retriever where to look *at search time*.
Lots more to do here to get oblique search queries as manageable as non-oblique ones, and that will include first figuring out sub-linear (late-interaction-esque) search.
But the path ahead has never been clearer. Read @dianetc_'s blog!
Is there a way to scale a reasoning model’s judgment for searching a massive corpus?
We introduce the Amortized Reasoning Index (ARI), a new kind of retriever that updates its weights during search, using gradients derived at inference time from the ranking preferences of a reasoning model.
Every session, current agents spend lots of reasoning deciding which search results matter, and then throw all of that judgment away upon compaction. ARI is our attempt to “amortize” that judgment, so that reasoning spent on past queries keeps improving search on future ones.
With no relevance labels, ARI takes a 400M cross-encoder that starts out weak and grows its Recall@100 on held-out queries by up to 7×, ending above Qwen3-Embedding-8B on various oblique/reasoning-intensive search tasks.
Read our blogpost: https://t.co/UEPpEpw22d
Preliminary results and discussions are below!
Very cool work from @rikiyatakehi and @lateinteraction's lab at MIT.
They show GPT-6 Astra can read the weights of a Qwen model and update them directly to improve performance.
In early results MATH-500 jumped from 7.9% to 48.1% and it even wrote a Breakout policy from scratch.
The two research questions I'm most excited about are whether this scales from billion-parameter models to trillion-parameter models and which stages of a modern post-training pipeline it could replace.
Today the largest open models are post-trained in several stages. Kimi K3 and DeepSeek-V4 train RL specialists and distill them into one model while GLM-5 and MiniMax-M3 run a chain of RL stages.
We're proud to support Omar's lab and to be working with them to scale this up to larger models and test it on LAB.
you thought LLMs can only do text optimization and discovery for prompts, harnesses, and code?
turns out they’re starting to be good at natively reasoning about and writing out neural network weights directly too
in the limit, where does this leave symbolic local optimization heuristics like gradient descent…??
We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: https://t.co/bOWCcFhCVq
I'm jumping on with @dbreunig and @isaacbmiller1 to talk about context engineering and dspy, including demo'ing an example from my new book! https://t.co/WYbAOLW3d2
Free for everybody not just @every subs (will be on YT).
What should 24/7, "always on" agents actually be doing when nobody is asking them for anything? 👾♻️
I am SUPER EXCITED to publish the 148th episode of the Weaviate Podcast featuring Jacob X. Li (@jacobli99), a Ph.D. student @MIT_CSAIL! 🔥
Jacob's paper frames the answer as Machine Studying. Similarly to how a student prepares for an exam they haven't seen, an agent studies a corpus (code base, drug discovery papers, system logs, ....) without knowing the downstream task! 📚📝
Instead of leaning entirely on inference-time compute, can an agent build arbitrarily deep understanding ahead of time?
I loved the paper's definition of expertise. An expert efficiently uses inference-time compute, measured as the area under the performance-vs-compute curve of a ReAct agent loop. Studying intelligence! 📐
Jacob lays out three bets every studying method makes: synthetic data, weight updates (LoRA, KV-cache cartridges, a trained retriever), and amortized context like notes and cheat sheets. 🛠️
We also discussed why evaluation as a science matters once recursive self-improvement happens in domains with no benchmark at all. 🧪
This was a super fun conversation, I learned so much from Jacob, and I really hope you find it interesting!
YouTube: https://t.co/5ss91feRZR
Spotify: https://t.co/MoQVmouuUQ