🎉 We’ve open-sourced Datus — a data engineering agent focused on building living data context. First week: 250+⭐️ on GitHub!
We make context & models evolvable — accurate today, better tomorrow.
Repo: https://t.co/VwXRxWA3DZ
#BuildInPublic#OpenSource#DataEngineering#AIAgents
🚀 DOSI 0.1.13 + Datus Agent 0.4.3 are here.
“How many users were active on exactly three days?” To answer that, you need to count active days per user first, then count users by that result. That’s a Level of Detail (LOD) question—and the calculation level changes the answer.
DOSI 0.1.13 lets you define that level once and reuse it. LODs can work across datasets, use their own time window, appear in detail queries, and align two facts on a shared axis.
Datus Agent 0.4.3 now uses DOSI directly to discover and query metrics, run attribution, and validate models.
Also new in Agent 0.4.3: /init can analyze SQL dependencies and joins to help build a project map. That’s a separate project-initialization improvement, not part of LOD.
Read the announcement:
https://t.co/pa1w6S9l29
DOSI 0.1.13 release notes:
https://t.co/qegoGY0vco
Datus Agent 0.4.3 release notes:
https://t.co/SuX9NUGfmJ
Datus-agent 0.3.8 is here! :rocket:
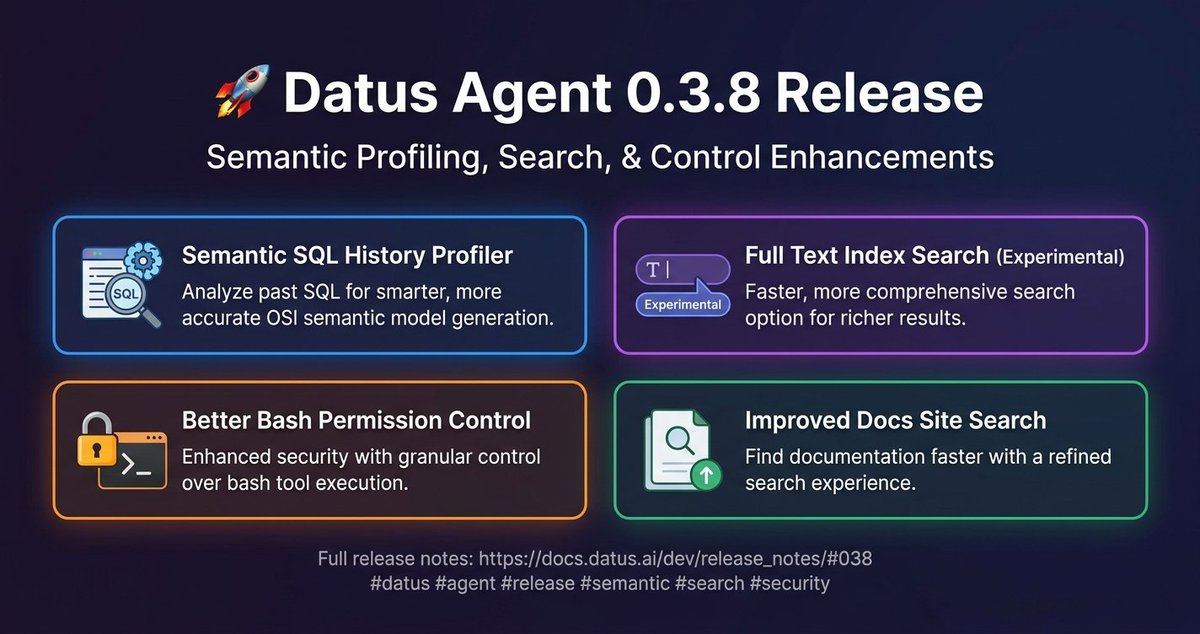
1. 𝗦𝗲𝗺𝗮𝗻𝘁𝗶𝗰 𝗦𝗤𝗟 𝗛𝗶𝘀𝘁𝗼𝗿𝘆 𝗣𝗿𝗼𝗳𝗶𝗹𝗲𝗿
`gen_semantic_model` now mines your historical and success-story SQL — column usage, data distributions, date spans, join coverage, common filters — so the OSI and MetricFlow semantic models it authors are grounded in how your data is actually queried. OSI authoring also uses your datasource's real SQL dialect and can sync complete OSI documents into the Knowledge Base.
2. 𝗙𝘂𝗹𝗹-𝘁𝗲𝘅𝘁 𝗶𝗻𝗱𝗲𝘅 𝘀𝗲𝗮𝗿𝗰𝗵 (𝗲𝘅𝗽𝗲𝗿𝗶𝗺𝗲𝗻𝘁𝗮𝗹)
Metadata search can now use LanceDB native full-text indexing — with Chinese n-gram support — as an option alongside the default vector search.
3. 𝗕𝗲𝘁𝘁𝗲𝗿 𝗽𝗲𝗿𝗺𝗶𝘀𝘀𝗶𝗼𝗻 𝗰𝗼𝗻𝘁𝗿𝗼𝗹 𝗳𝗼𝗿 𝗯𝗮𝘀𝗵 𝘁𝗼𝗼𝗹𝘀
`execute_command` is now `bash`, with real shell pipelines plus command-level allow/deny/ask rules, project allowlists, per-call timeouts, and process-group cleanup.
4. 𝗕𝗲𝘁𝘁𝗲𝗿 𝗱𝗼𝗰𝘀 𝘀𝗲𝗮𝗿𝗰𝗵
English and Chinese docs now build as separate sites, each with its own search index, version metadata, and canonical URLs.
Plus more reliable semantic storage (full catalog/database/schema/table identities) and recoverable agent/gateway failures under the hood.
Full release notes: https://t.co/8nJH7B5PfT
Datus Agent 0.3.7 is out. 📷
1. 𝗨𝗻𝗶𝗳𝗶𝗲𝗱 𝗪𝗲𝗯 𝗦𝗲𝗮𝗿𝗰𝗵 𝗮𝗻𝗱 𝗙𝗲𝘁𝗰𝗵 𝗧𝗼𝗼𝗹𝘀
New `web_tool.web_search` and `web_tool.web_fetch` let agents pull in live web content mid-task. The backend picks itself based on your model — Claude native search, OpenAI hosted search, or local Tavily — and results render the same across CLI, TUI, and API.
2. 𝗨𝗻𝗶𝗳𝗶𝗲𝗱 `execute_sql` 𝘄𝗶𝘁𝗵 𝗯𝗲𝘁𝘁𝗲𝗿 𝗽𝗲𝗿𝗺𝗶𝘀𝘀𝗶𝗼𝗻 𝗰𝗼𝗻𝘁𝗿𝗼𝗹
`read_query`, `execute_ddl`, and `execute_write` merge into a single `execute_sql` that classifies each statement: reads (SELECT/SHOW/EXPLAIN) run automatically, writes and DDL ask first. The DDL restriction is lifted too — `CREATE DATABASE`, `TRUNCATE`, and `MERGE` now work once confirmed.
3. 𝗕𝗲𝘁𝘁𝗲𝗿 `gen_semantic_model` 𝗳𝗼𝗿 𝗢𝗦𝗜
OSI semantic models now consolidate at the business-domain level, `describe_table` syncs and shows table-level semantic profiles, and `ask_metrics` gets stronger metric discovery, cross-table join control, and cumulative/rolling metric queries.
4. 𝗕𝗲𝘁𝘁𝗲𝗿 𝗽𝗲𝗿𝗺𝗶𝘀𝘀𝗶𝗼𝗻 𝗽𝗿𝗲𝘃𝗶𝗲𝘄
Tool arguments in confirmation prompts now render as markdown — SQL as highlighted code, nested structures as JSON — so you know exactly what you're approving.
A focused release, but an important step toward more 𝗰𝗼𝗻𝘁𝗿𝗼𝗹𝗹𝗮𝗯𝗹𝗲, 𝗽𝗿𝗼𝗱𝘂𝗰𝘁𝗶𝗼𝗻-𝗿𝗲𝗮𝗱𝘆 data engineering agents.
Full release notes: https://t.co/Ef8uv3qkuB
Datus-agent 0.3.5 is here! 📷
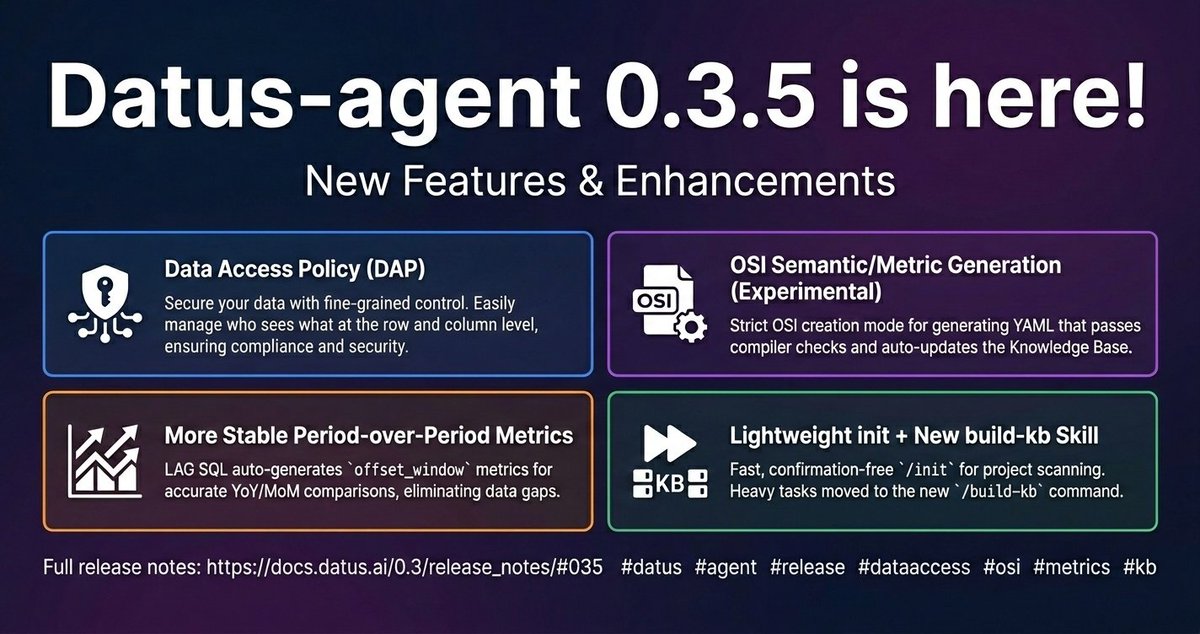
1. 𝗗𝗮𝘁𝗮 𝗔𝗰𝗰𝗲𝘀𝘀 𝗣𝗼𝗹𝗶𝗰𝘆
Enforce row- and column-level access before any read SQL runs. The REST API passes structured caller identity (user, role, team) via `X-Datus-Principal`, and a custom `DataAccessPolicyProvider` can rewrite or reject queries before execution — wire it to OPA or your own auth service, or run the built-in `NoAuthProvider` out of the box.
2. 𝗦𝘁𝗿𝗶𝗰𝘁 𝗢𝗦𝗜 𝘀𝗲𝗺𝗮𝗻𝘁𝗶𝗰 𝗮𝘂𝘁𝗵𝗼𝗿𝗶𝗻𝗴 (Experimental)
`gen_semantic_model` and `gen_metrics` can now author in strict OSI mode: generate OSI-compliant YAML, validate and dry-run it through the adapter, and write the metrics back to your knowledge base so the KB and semantic layer stay in sync.
3. 𝗣𝗲𝗿𝗶𝗼𝗱-𝗼𝘃𝗲𝗿-𝗽𝗲𝗿𝗶𝗼𝗱 𝗺𝗲𝘁𝗿𝗶𝗰𝘀
`gen_metrics` builds `offset_window` derived metrics (day/week/month/quarter/year) straight from your LAG SQL, and `ask_metrics` automatically matches the right time grain — so current, previous-period, and delta values come back together, with no missing first period.
4. 𝗠𝗲𝘁𝗿𝗶𝗰 𝗽𝗿𝗲𝘃𝗶𝗲𝘄 𝗔𝗣𝗜
New endpoints let a metric editor dry-run compile a saved metric into runnable SQL and list its queryable dimensions before saving. Invalid dimensions return structured preflight feedback instead of a raw error.
5. 𝗟𝗶𝗴𝗵𝘁𝗲𝗿 𝗶𝗻𝗶𝘁, 𝗻𝗲𝘄 𝗯𝘂𝗶𝗹𝗱-𝗸𝗯 𝗰𝗼𝗺𝗺𝗮𝗻𝗱
`/init` is now a fast, no-prompt project scan that writes an `AGENTS.md` inventory plus file-based knowledge/memory — no expensive vector store. Heavy KB construction moves to the new `/build-kb` command, scoped to your active datasource.
6. 𝗡𝗼𝗻-𝗶𝗻𝘁𝗲𝗿𝗮𝗰𝘁𝗶𝘃𝗲 𝗽𝗹𝗮𝗻 𝗺𝗼𝗱𝗲
`datus -p --plan-mode` auto-confirms generated plans, unblocking print-mode and benchmark runs that used to hang waiting for input.
Plus: cached system-prompt prefixes cut input-token cost on long sessions, permission locks are now scoped per session so concurrent runs no longer block each other, the Claude subscription path fires permission/compact/lifecycle hooks consistently, and a round of CLI and connection-state fixes — more reliable across the board.
Full release notes: https://t.co/yc85FgSKC8
Datus Agent 0.3.4 is out 🚀
AskMetrics — a dedicated metric QA subagent for KPI, trend & attribution questions. It reaches for metric-specific tools instead of raw SQL, so answers land at the right grain.
Plus: scoped agent memory + faster knowledge extraction.
https://t.co/ABMRJL7U3M
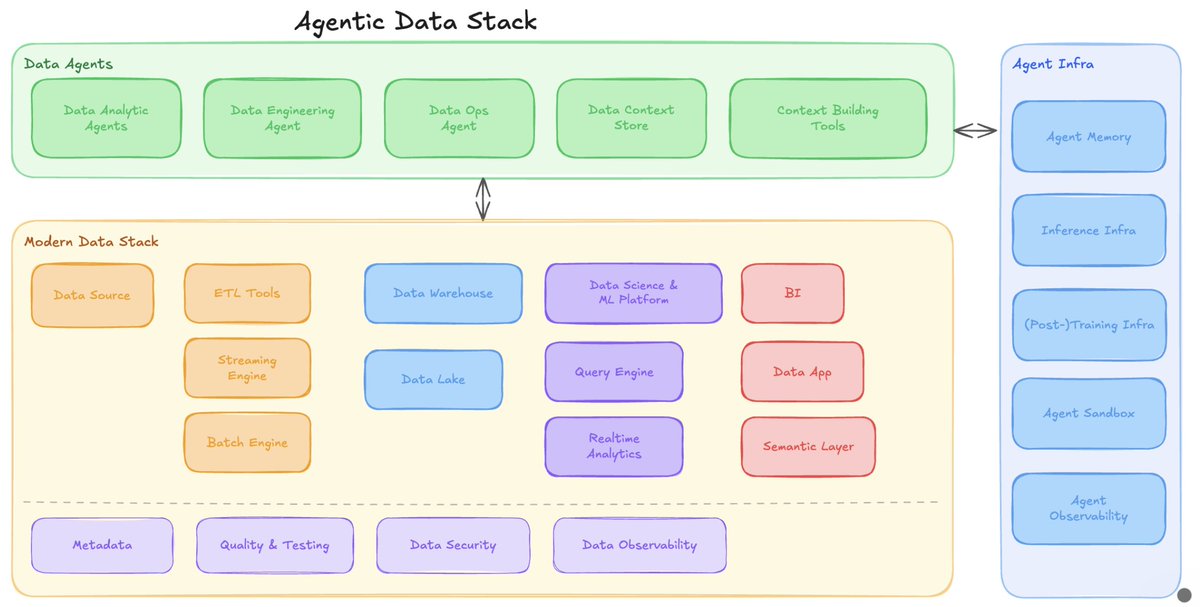
From Modern Data Stack to Agentic Data Stack: The Next Evolution
The Modern Data Stack (MDS) — cloud warehouses, ELT pipelines, BI dashboards — gave us powerful building blocks designed for human analysts and engineers.
But what happens when AI agents become the primary operators?
The key shift:
MDS (2020): Optimized for human point-and-click workflows
Agentic Data Stack (2026): Built for autonomous agent execution with human oversight
This isn't just about adding APIs or CLIs. True agent-readiness requires:
✅ Structured error codes + recovery suggestions (not just toast notifications)
✅ Granular versioning (data, metrics, code — not just backups)
✅ Machine-readable observability (structured logs, lineage)
✅ Reusable skills (agents learn & improve over time)
✅ Dry-run modes for safe iteration
The real test? Can agents complete 5 production workflows with <30% human intervention?
The Modern Data Stack gave us the foundation. The Agentic Data Stack makes those blocks operable by machines.
Small teams can start today with Git-based versioning, structured logging, and CLI-first interfaces.
📖 Full FAQ: https://t.co/cni5Q2VGaE
#DataEngineering #AI #AgenticDataStack #ModernDataStack #MLOps #DataPlatform
We spent 2 months watching AI agents try to build real data stacks.
Not because agents aren't smart enough. Here is the bitter lesson:
Because data infrastructure was never designed for them.
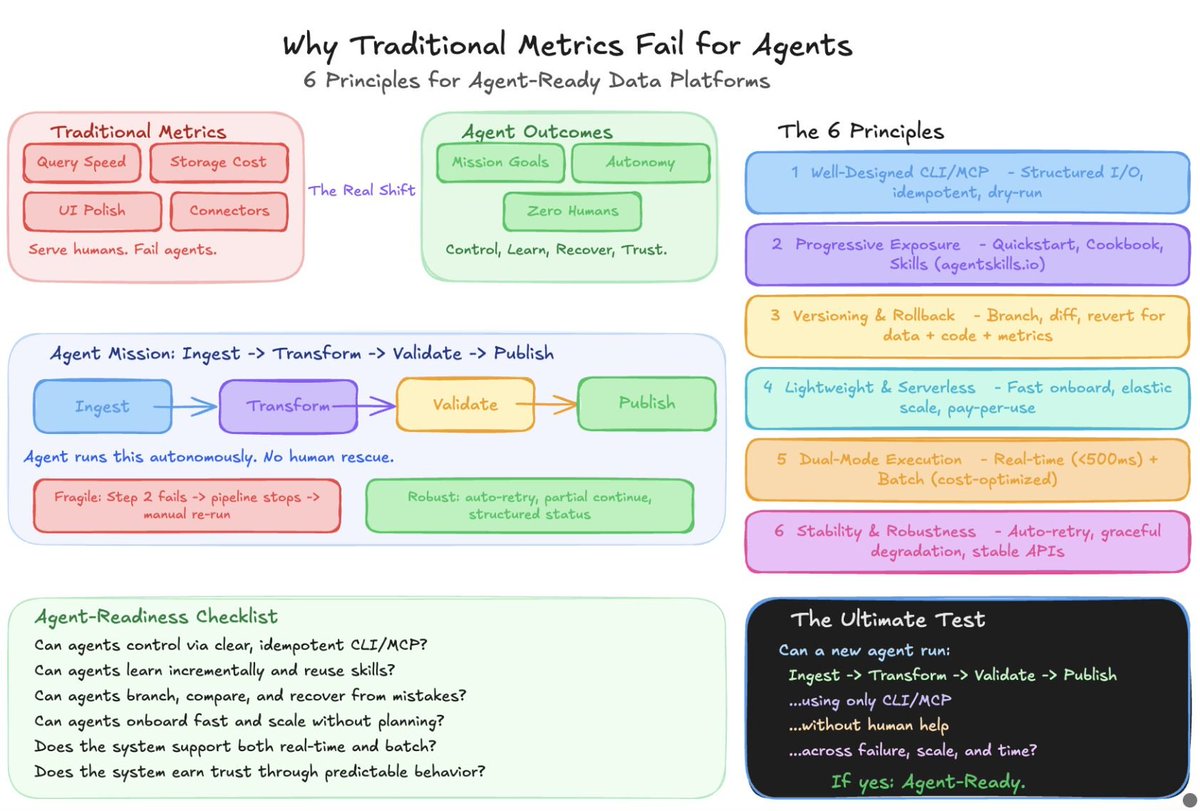
Traditional data platforms optimize for:
→ Query speed
→ Storage cost
→ Pretty UI
But agents don't use UI. They parse structured data and CLI.
They don't read tutorials. They need machine-readable contracts.
They don't call support. They need actionable error codes.
The shift: A platform scoring 95/100 on traditional metrics can be nearly unusable for agents.
We identified 6 principles that separate agent-ready systems from chatbot wrappers:
✓ 𝐖𝐞𝐥𝐥-𝐝𝐞𝐬𝐢𝐠𝐧𝐞𝐝 𝐂𝐋𝐈/𝐌𝐂𝐏 𝐢𝐧𝐭𝐞𝐫𝐟𝐚𝐜𝐞𝐬
✓ 𝐏𝐫𝐨𝐠𝐫𝐞𝐬𝐬𝐢𝐯𝐞 𝐝𝐨𝐜𝐬 + 𝐫𝐞𝐮𝐬𝐚𝐛𝐥𝐞 𝐬𝐤𝐢𝐥𝐥𝐬
✓ 𝐕𝐞𝐫𝐬𝐢𝐨𝐧𝐢𝐧𝐠 & 𝐫𝐨𝐥𝐥𝐛𝐚𝐜𝐤 (𝐋𝐋𝐌𝐬 𝐦𝐚𝐤𝐞 𝐦𝐢𝐬𝐭𝐚𝐤𝐞𝐬)
✓ 𝐋𝐢𝐠𝐡𝐭𝐰𝐞𝐢𝐠𝐡𝐭 𝐜𝐥𝐢𝐞𝐧𝐭 + 𝐬𝐞𝐫𝐯𝐞𝐫𝐥𝐞𝐬𝐬 𝐬𝐜𝐚𝐥𝐞
✓ 𝐃𝐮𝐚𝐥-𝐦𝐨𝐝𝐞: 𝐫𝐞𝐚𝐥-𝐭𝐢𝐦𝐞 + 𝐛𝐚𝐭𝐜𝐡
✓ 𝐒𝐭𝐚𝐛𝐢𝐥𝐢𝐭𝐲 𝐨𝐯𝐞𝐫 𝐩𝐞𝐫𝐟𝐨𝐫𝐦𝐚𝐧𝐜𝐞
We built an evaluation framework + tested 27 open-source tools.
Plus an experiment: AgenticDataTown — AI agents building an entire data stack autonomously.
Read the framework → https://t.co/swEkZG6Ijy
🚀 Introducing Agentic Data Stack
A community exploring how modern data systems evolve to serve agents — and how agents reshape data engineering.
✨ Vendor-neutral
📊 Practice-driven
🏗️ Architecture-first
10 tracks covering the full stack. Join us:
https://t.co/QVoYvTV1gz
#DataEngineering #AIAgents #DataStack
Watched @peak ji’s sharing on Context Engineering for AI Agents (lessons from @ManusAI ) — learned a lot.
My biggest takeaway: context engineering is the clearest boundary between “app iteration” and “model iteration.”
Most real gains don’t come from changing the model, but from how we manage context.
I especially like framing context engineering along these dimensions:
reduce / isolate / offload / retrieve / cache — a very practical way to reason about agent quality and scalability.
At Datus, we’ll keep pushing context engineering for data agents, and I’ve listed our current work items here:
👉 https://t.co/KKb0ikLQWc
Furthermore, compared to general agents, specialized-purpose agents have real “special sauce”:
Clearer rewards & benchmarks → much stronger feedback loops
Parallel workflows + selection (with consistency checks) → noticeably higher reliability
Domain-specific context → two evolvable context trees that make context offloading more standard, scalable, and maintainable
Context isn’t just input.
It’s an engineering system.
#ContextEngineering #AgenticAI #DataEngineeringAgent #DatusAI #LLM
🎄 Merry Christmas from Datus 🎄
AI agents don’t fail because they’re not smart.
They fail because they lack context.
That’s why we’re building Datus — an open-source data engineering agent for Contextual Data Engineering, turning metadata, SQL, metrics, and feedback into a living foundation for reliable data agents.
🙏 Huge thanks to our community, users, and contributors for building with us this year.
⭐ If you like the idea and want to support us, please give Datus a star on GitHub:
👉 https://t.co/Ujq8sKdar4
Happy Holidays — let’s keep making data agents work in the real world.
#MerryChristmas #HappyHolidays #DataEngineering #OpenSource #DataAgents #Datus
The plan of next version(0.2.4) is out: https://t.co/G6tgfqKMS6
1) Dashboard Copilot (Auto-generation)
Turn a BI dashboard URL into a scoped “dashboard copilot” (subagent) — automatically.
We’ll also push attribution analysis forward with new tools, and start a BI adapter track for @apachesuperset .
2) Better SQL generation via a feedback loop
We’re improving semantic model generation with CoT + probe SQL + reference SQL, and adding evaluation-driven knowledge generation (extracting “hidden knowledge” from success stories).
Plus: a semantic layer adapter that supports more metric specs, and better context-tree recall via improved search tool specs + default prompts.
3) Datus-chat + Datus-cli UX
Export/download, better SQL result rendering + chart visualization, and recent action history in CLI.
4) New use cases
Catalog integrations (starting with @apachepolaris ) + interactive SQL editing with IDE.
5) Ecosystem expansion
ClickHouse adaptor is on the roadmap.
hashtag#DatusAI hashtag#DataEngineeringAgent hashtag#ReleasePlan
𝐓𝐡𝐞 𝐟𝐮𝐭𝐮𝐫𝐞 𝐨𝐟 𝐝𝐚𝐭𝐚 𝐚𝐠𝐞𝐧𝐭𝐬 𝐢𝐬𝐧’𝐭 𝐨𝐧𝐞 𝐨𝐦𝐧𝐢𝐬𝐜𝐢𝐞𝐧𝐭 𝐀𝐈.
It’s a layered system of subagents—each with scoped context and purpose-built intelligence.
Through months of collaboration with customers, we've identified a clear architectural pattern in Datus: 𝐚 𝐭𝐰𝐨-𝐥𝐚𝐲𝐞𝐫 𝐬𝐮𝐛𝐚𝐠𝐞𝐧𝐭 𝐨𝐫𝐠𝐚𝐧𝐢𝐳𝐚𝐭𝐢𝐨𝐧.
🔹 Layer 1: Foundational Subagents
These are reusable “skills”(Native tools or MCP) every data team needs:
• 𝐆𝐞𝐧𝐒𝐐𝐋 — generate + refine SQL with structural awareness
• 𝐆𝐞𝐧𝐒𝐞𝐦𝐚𝐧𝐭𝐢𝐜𝐌𝐨𝐝𝐞𝐥 — draft dimensions/measures from sql & tables
• 𝐆𝐞𝐧𝐌𝐞𝐭𝐫𝐢𝐜𝐬 — derive metrics from SQL patterns & business rules
• 𝐒𝐮𝐦𝐦𝐚𝐫𝐢𝐳𝐞𝐒𝐐𝐋 — Summarize, classify and tag from SQL and put them into data context tree.
• 𝐂𝐚𝐭𝐚𝐥𝐨𝐠𝐏𝐞𝐫𝐦𝐢𝐬𝐬𝐢𝐨𝐧𝐢𝐧𝐠 — Consider about governance & access to create a reasonable RBAC framework
...
🔹 Layer 2: Customized Domain Subagents
Once you add scoped context (curated tables, metrics, SQL reference, domain rules),
those foundational subagents become domain copilots:
• Marketing Analytics Copilot
• Supply Chain Operations Copilot
• Restaurant Performance Copilot
• Game Economy Copilot
• User Growth / Retention Copilot
Refer to: https://t.co/tI0gOZI6JC
hashtag#DatusAI hashtag#DataEngineeringAgent hashtag#Subagent
𝐂𝐨𝐧𝐭𝐞𝐱𝐭𝐮𝐚𝐥 𝐃𝐚𝐭𝐚 𝐄𝐧𝐠𝐢𝐧𝐞𝐞𝐫𝐢𝐧𝐠: 𝐅𝐫𝐨𝐦 𝐃𝐚𝐬𝐡𝐛𝐨𝐚𝐫𝐝 𝐭𝐨 𝐚𝐠𝐞𝐧𝐭
Yesterday I had a deep conversation with one of our customers, and we landed on a simple but powerful insight:
👉 Most of a company’s real data knowledge isn’t in the tables. It’s hidden inside the dashboards.
Behind every BI dashboard — @apachesuperset , @tableau , @metabase — there is a lot of invisible human reasoning:
* how analysts think about a business domain
* how tables are actually joined in practice
* which filters matter (and which don’t)
* what “drill-down” means for this company
* why a metric is defined this way, not that way
* the SQL patterns that survived real production use
Dashboards are not only “visualizations.” They are encoded institutional memory.
And if we want AI agents to answer questions reliably, we must first extract this memory.
This is the heart of 𝐂𝐨𝐧𝐭𝐞𝐱𝐭𝐮𝐚𝐥 𝐃𝐚𝐭𝐚 𝐄𝐧𝐠𝐢𝐧𝐞𝐞𝐫𝐢𝐧𝐠:
1. Pull human hidden knowledge out of their mind/dashboard/document
2. Structure it
3. Use it to build reliable, domain-specific AI subagents
This transforms a static dashboard into:
* interactive Q&A
* deep analysis & insights
* automated reporting
* attribution & anomaly explanations
hashtag#DataEngineeringAgent hashtag#DatusAI hashtag#Superset hashtag#Metabase hashtag#Tableau
🚀 Datus 0.2.3 is out!
We’ve just shipped v0.2.3, a release focused on making contextual data engineering easier, faster, and more reliable for real-world teams.
This version brings three important improvements:
1️⃣ 𝐄𝐧𝐡𝐚𝐧𝐜𝐞𝐝 𝐞𝐯𝐚𝐥𝐮𝐚𝐭𝐢𝐨𝐧 𝐟𝐫𝐚𝐦𝐞𝐰𝐨𝐫𝐤
We now evaluate not only whether a SQL query runs successfully, but also several process-level signals, including:
* table match
* row count match
* column match / coverage
* recall of expected metrics and reference SQL patterns
This makes it much easier to see how an agent is wrong (or almost right) and where to improve.
2️⃣ 𝐏𝐥𝐮𝐠𝐢𝐧-𝐛𝐚𝐬𝐞𝐝 𝐝𝐚𝐭𝐚𝐛𝐚𝐬𝐞 𝐜𝐨𝐧𝐧𝐞𝐜𝐭𝐨𝐫
We’ve split database connectors into a separate repo: datus-db-adapters.
Users can install only the connectors they need (for example: datus-snowflake, datus-starrocks), while we keep @duckdb and @sqlite as embedded connectors for quickstarts and tutorials.
This minimizes the core datus-agent dependencies and allows DB connectors to evolve on their own release cadence.
3️⃣ 𝐄𝐦𝐛𝐞𝐝𝐝𝐞𝐝 𝐭𝐮𝐭𝐨𝐫𝐢𝐚𝐥 𝐝𝐚𝐭𝐚𝐬𝐞𝐭
We now ship a built-in California school dataset that demonstrates how to automatically extract metrics and reference SQL from historical queries and success stories, then build a subagent to improve NL2SQL accuracy end-to-end.
👉 Tutorial: https://t.co/sEn3GXFC28
For more details, check out the full release notes:
https://t.co/hiNYZE3bwj
hashtag#DatusAI hashtag#DataEngineeringAgent
Very impressed by Gemini 3 + Nano Banana Pro.
If LLMs can reason jointly over text + images, what happens when we replace images with structured data?
Dashboards, tables, metrics → encoded as native tokens.
Reference SQL = compressed business logic.
Semantic layer = compressed physical tables.
LLMs need a better compression format for data — just like image patches or Parquet.
This is why we’re building Datus: cleaner data context (📁 @catalog + 🧭 @subject) for agentic models.
Multi-modal LLMs are here.
Multi-modal data-LLMs might be next.
#Datus #DataEngineeringAgent #Gemini3 #nanobanana
𝐖𝐡𝐲 𝐚𝐫𝐞 𝐰𝐞 𝐛𝐮𝐢𝐥𝐝𝐢𝐧𝐠 𝐚 𝐂𝐋𝐈 𝐭𝐨𝐨𝐥 𝐟𝐨𝐫 𝐝𝐚𝐭𝐚 𝐞𝐧𝐠𝐢𝐧𝐞𝐞𝐫𝐬 𝐢𝐧 𝐭𝐡𝐞 𝐚𝐠𝐞 𝐨𝐟 𝐀𝐈?
Because every reliable data agent starts with good context. And the fastest, most precise way for engineers to build context is still the terminal.
1. 𝐄𝐧𝐠𝐢𝐧𝐞𝐞𝐫-𝐧𝐚𝐭𝐢𝐯𝐞 𝐝𝐞𝐬𝐢𝐠𝐧: 𝟑 𝐌𝐚𝐠𝐢𝐜 𝐂𝐨𝐦𝐦𝐚𝐧𝐝𝐬
* /chat – chat2SQL, chat2metrics, context-aware Q&A
* !execute – run SQL directly with native DB tools
* @context – browse and edit the living context (metadata, metrics, SQL history)
SQL + context + AI in one place.
2. 𝐄𝐚𝐬𝐲 𝐭𝐨 𝐢𝐧𝐭𝐞𝐠𝐫𝐚𝐭𝐞 𝐞𝐯𝐞𝐫𝐲𝐰𝐡𝐞𝐫𝐞
* Dock it beside your SQL IDE (like Cursor/VS Code + Claude Code)
* Supports integration with your in-house SQL editor or data platform
* VS Code plugin coming soon
3. 𝐄𝐚𝐬𝐲 𝐭𝐨 𝐞𝐱𝐭𝐞𝐧𝐝
Datus follows a composable architecture:
context engine → tools → subagents → workflows.
Add your own metadata sources, semantic layers, schedulers, or custom tools via MCP.
No black boxes. No vendor lock-in.
Language is the new interface. The CLI is where it starts.
hashtag#DatusAI hashtag#DataEngineeringAgent hashtag#CLI
The semantic layer is the key bridge between human language and SQL — it’s where business logic, metrics, and data structure finally meet.
In reality, there’s a gap:
* Data engineers hold hidden knowledge buried in SQLs and pipelines.
* Analysts speak in company-specific jargon — every company has its own way of defining retention rate, AUM, or active user.
𝐖𝐡𝐞𝐧 𝐰𝐞 𝐛𝐮𝐢𝐥𝐝 𝐚𝐠𝐞𝐧𝐭𝐬, 𝐰𝐞’𝐫𝐞 𝐞𝐬𝐬𝐞𝐧𝐭𝐢𝐚𝐥𝐥𝐲 𝐞𝐧𝐜𝐨𝐝𝐢𝐧𝐠 𝐡𝐮𝐦𝐚𝐧 𝐞𝐱𝐩𝐞𝐫𝐭𝐢𝐬𝐞 𝐢𝐧𝐭𝐨 𝐚𝐠𝐞𝐧𝐭'𝐬 𝐜𝐨𝐧𝐭𝐞𝐱𝐭. That’s where Datus comes in.
Datus-Agent leverages and extends the open-source MetricFlow(From @getdbt ) — enabling LLMs to auto-generate semantic models from SQL history while still allowing human-in-the-loop editing.
This creates a more accurate, evolvable data context that bridges human intent and machine understanding.
🔗 See https://t.co/JJm118Xbbc
@duckdb is tiny but mighty — an embedded columnar DB that powers both local & lakehouse analytics.
We’ve built it right into Datus as the default analysis engine.
Just connect your LLM account and start analyzing instantly.
Docs → https://t.co/bHJinHUFLk
@motherduck
#DuckDB #DatusAI #DataEngineering #AIagents
Traditional data engineers build tables & pipelines.
But in the AI era, we must deliver more —
🤖 chatbots for humans,
🧩 APIs for agents,
📊 semantic layers for BI tools.
That’s why we built Datus — to let data engineers deliver agents, not just tables.
No more endless back-and-forth with analysts.
Build once, refine via feedback loop, and evolve into an API.
That’s what we call Contextual Data Engineering — turning pipelines into agents.
@dbt_labs@data_weekly@dataengwithaws@five
#DataEngineeringAgent #DatusAI