AI 4D Cell Biology!
Watch mitochondria reveal their hidden phenotypes! We built MitoSpace, a self-supervised model trained without labels on terabytes of 4D lattice light-sheet movies of single cells. It learns representations that outperform predefined features, predict membrane potential from 4D form alone (R²=0.91), and generalize zero-shot to unseen drugs and human lung organoids.
🎉 Now published in @CellCellPress!
With @DrvAgwl@ZacharyWang379@ecarkfeld@andremodolo4@Parth_LFC@hhako2@GCMcMahon
📄 Paper: https://t.co/KmoUvFOYAk
🔬 Explorer: https://t.co/asVHY1s028
💻 Code: https://t.co/AUHVSg4aRr
🤗 Model: https://t.co/2vJvQRmDjj
#AI4DCellBiology #cellbiology #microscopy #LLSM #latticelightsheet #mitochondria #deeplearning #phenomics
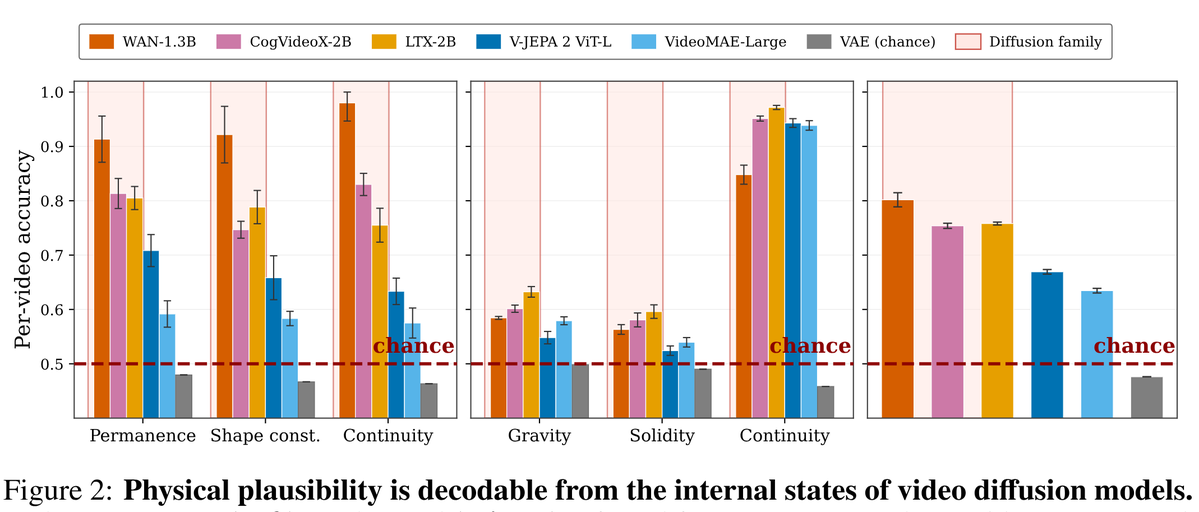
You may have recently heard claims that video generation models are "dumb" about physics, and only "world models" (V-JEPA, specifically) have a valid internal model of physics.
This turns out to be false. In a recent paper, researchers show that a LINEAR probe of diffusion videogen models predict various "physics" very well, significantly better than V-JEPA or VideoMAE (and plain VAE just sucks).
This is noteworthy, because a *linear* probe being this accurate shows that the model has a pretty explicit internal representation of the physics!
Have you debugged your training data? You might not like what you find.
Introducing predictive data debugging: reveal and shape what your model will learn before training.
In DPO datasets, we found broken guardrails, hallucinations, and fish fart fan fiction (seriously). (1/9)
Quote-reply to Rohan because I think it can be interesting to many more.
So there are two things you're missing here:
1) You're only looking at one specific instantiation of the general JEPA idea. There are many different instantiations.
2) The core JEPA idea (Joint Embedding Prediction Architecture) is to embed two "views" and predict one from the other. The views can be different augmentations, different time-steps, etc.
Crucially, prediction happens in embedding space, which contrasts to predicting in data space as done by LLMs, diffusion models, MAEs, ...
At least from the vision community, the main reason it got quite a bit of flak is that... literally everyone who was doing some self/un-supervised learning there has shared this thought already. MANY people did such models in the peak self-supervised period, which was ca 2017-2021. Then in 2022 comes Yann, slaps a new names on it, a paper with just the idea and no experiments to show for it, and goes on PR tour. That's why many didn't take it well.
The core idea, almost everyone I know agrees is worth pursuing, especially since many already were doing so. It's very reminiscent of why Stanford got flak when they introduced and arguably tried to appropriate the "Foundation Model" term.
That being said, by now foundation model has stuck and detached from Stanford, it may end up going similarly for JEPA.
🥇 Inside the Best Paper from the @NeurIPSConf Foundation Models for Science Workshop.
▪���At NeurIPS, @phil_fradkin of @valence_ai powered by Recursion presented MolPhenix, a foundation model that can predict the effect of any given molecule & concentration pair on phenotypic cell assays and cell morphology. It was awarded best paper at the NeurIPS FM4Science Workshop.
▪️ As Fradkin explains, the model relies on our massive dataset of high resolution images of cells which are captured under various forms of molecular perturbation at different concentrations.
▪️ “The thing we’re interested in is called PhenoMolecular Retrieval,” he says. “To retrieve the identity of the perturbation and the concentration that was used to perturb the phenomics data” with the goal of “zero-shot generalization of new molecules at new concentrations.”
▪️ MolPhenix is one of the first such models, he says, to integrate concentration & that's critical to AI drug discovery.
👉 Learn more about MolPhenix: https://t.co/QvT1ihlZP1
Pre-Order #LifeIsStrange Double Exposure, the all-new supernatural murder mystery featuring the return of #MaxCaulfield: https://t.co/lSe0Kaj1yl
*SHARE THIS POST* to win an @Xbox Series X, LiS Design Labs Controller and 1/5 posters signed by @HannahTelle: https://t.co/pnl5eovS8S
Stories brought us together, books spread our mythologies, the internet promised infinite knowledge, algorithms learned our secrets – and then turned us against each other. What will #AI do?
'Nexus' can be pre-ordered at https://t.co/EeW9WvbDui. Out September 10.
#NexusBook
🚨!! JOB OPENING !!🚨
Join us as a postdoc to investigate how 4D mitochondrial dynamics determine cell fate!
You can reach out to us at https://t.co/Nvj5xDgGOx or use this web form: https://t.co/TgQOxSL5Fs
Looking forward to hearing from you!
Pls RT friends🌞
Is 3D scene generation much closer to being solved all of a sudden? It has been a few days since the release of @OpenAI Sora. We run our COLMAP-Free 3D Gaussian Splatting on the released videos. Our method does not need to pre-process cameras and it seems we can directly just get 3D from the videos. Check out our results here. 🧵👇
(1/n
Introducing Sora, our text-to-video model.
Sora can create videos of up to 60 seconds featuring highly detailed scenes, complex camera motion, and multiple characters with vibrant emotions.
https://t.co/YYpOAcrXQ3
Prompt: “Beautiful, snowy Tokyo city is bustling. The camera moves through the bustling city street, following several people enjoying the beautiful snowy weather and shopping at nearby stalls. Gorgeous sakura petals are flying through the wind along with snowflakes.”
🎉It’s officially the finale of soonami Venturethon Cohort 2! We are so proud that this edition of soonami Venturethon saw:
👉🏽340 participants
👉🏽 from 39 countries
👉🏽 innovating on 40 projects
This makes it our biggest hackathon yet! 🌍
Hello from Times Square! 👋✨
@Rephrase_AI was spotted shining bright at this iconic NY landmark. 🗽
Our grand appearance showcases the incredible text-to-video power we offer, reshaping business interactions with AI for effective and efficient communication. 💬💡
Proud of our ongoing journey! 🚀💪 #RephraseAI #RephraseStudio #TimesSquare