Introducing Winnow-12B.
Jev-style decisions, chat and vision in one llama.cpp-based server.
A Gemma 4 12B fine-tune running locally at 64K context + vision on my 16 GB RTX 5070 Ti (Q8).
Open weights: https://t.co/D4xvEIdK3H
Benchmarks + inference code below 👀👇
@airesearch12 Thanks for featuring Winnow-12B! It works great as a classifier and also supports regular chat with long context + vision. For anyone who wants to try it, here are the weights: https://t.co/D4xvEIdK3H
Introducing Winnow-12B.
Jev-style decisions, chat and vision in one llama.cpp-based server.
A Gemma 4 12B fine-tune running locally at 64K context + vision on my 16 GB RTX 5070 Ti (Q8).
Open weights: https://t.co/D4xvEIdK3H
Benchmarks + inference code below 👀👇
Try Winnow-12B:
BF16 + Q8 weights and vision projector:
https://t.co/D4xvEIdK3H
Code, examples and full benchmarks:
https://t.co/m4lDY6pxKU
/v1/systemone for typed decisions.
/v1/chat/completions for chat + vision.
Introducing Winnow-12B.
Jev-style decisions, chat and vision in one llama.cpp-based server.
A Gemma 4 12B fine-tune running locally at 64K context + vision on my 16 GB RTX 5070 Ti (Q8).
Open weights: https://t.co/D4xvEIdK3H
Benchmarks + inference code below 👀👇
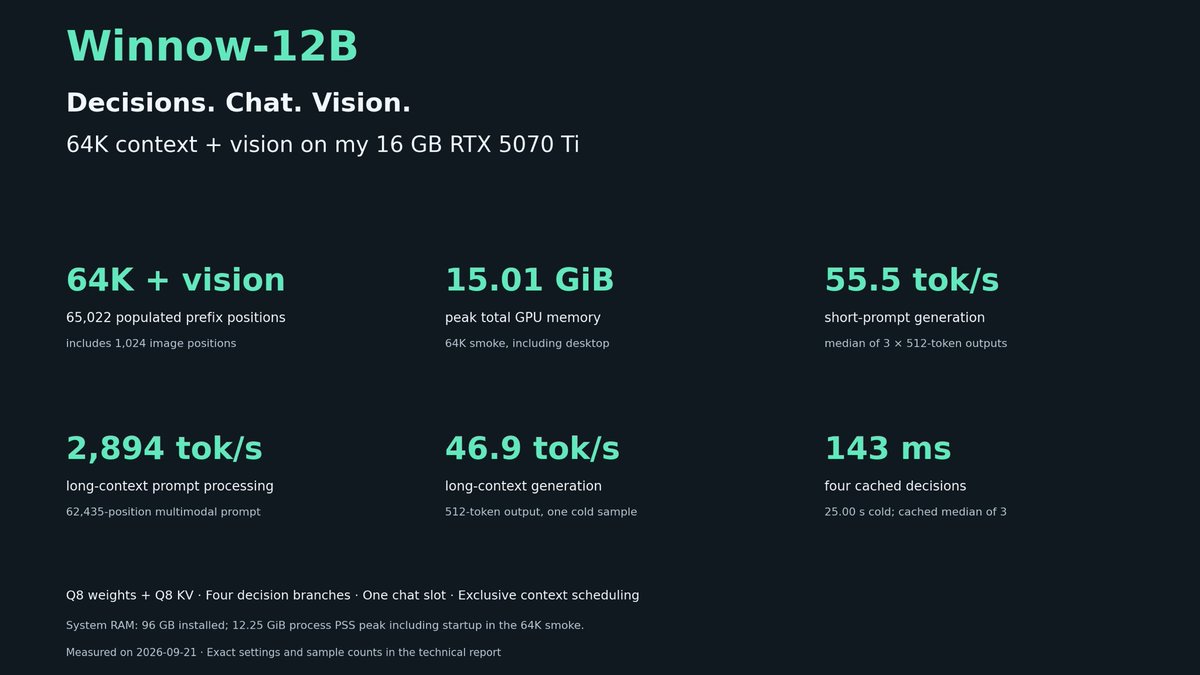
On my RTX 5070 Ti, Q8:
64K + vision, 15.01 GiB peak GPU memory.
55.5 tok/s short-prompt generation.
46.9 tok/s with a 62K multimodal prompt.
Four decisions over the populated 64K vision fixture: 143 ms (cached)
Exact settings + sample counts in the report.
I’ve been building Winnow-12B, a Gemma 4 fine-tuned for Jev-style decisions, with chat + vision on the same llama.cpp server.
The Q8 candidate passed 64K + vision on my 16GB 5070Ti. Comparing it with Kev and Laya now. Numbers coming with today’s release.
@matvelloso Me 👋 I’m finishing a Gemma 4 finetune with long-context and answers Jev-style questions, while retaining normal chat and vision. Same llama.cpp-based server, running at 64K + vision on my 5070 Ti. Open weights and code coming tomorrow!
@jaredpalmer Very cool release! Exciting to see open decision models taking off. I’m working on a Gemma 4 12B post-train that combines Jev-style decisions with chat and vision in one llama.cpp-based server. It runs at 64K context with vision on my RTX 5070 Ti. Releasing tomorrow!