AutoResearch is critical in unlocking new knowledge and accelerate discovery. And it's an important ingredient in our quest to RSI.
Today we at @bespokelabsai are happy to announce a new benchmark that's tailored to measure agents' ability to do autoresearch: AutoResearchExam.
As part of this benchmark, we release 29 tasks that measure progress over 24 hours for agents to do sustained ML research and model training.
Please check out for more info: https://t.co/3bp6MZd2Ze
This line of work is especially timely, given the recent advances in math and science, such as solving the Navier-Stokes Millennium Prize Problem, which needs sustained autoresearch and test-time scaling.
We are releasing AutoResearchExam, a benchmark on open-ended machine learning and engineering tasks. Our benchmark covers seven research areas including model training, data curation, AI safety and interpretability.
https://t.co/Rho35ULgS5
In each task, we give agents 24 hours with a CPU or GPU machine to develop and improve their solutions through experiments and feedback. We measure both speed and quality with a combined score. Our benchmark has a unique feature: testing if agents create improvements that hold up on data they never see. We find that AI research agents often overfit as they try to improve.
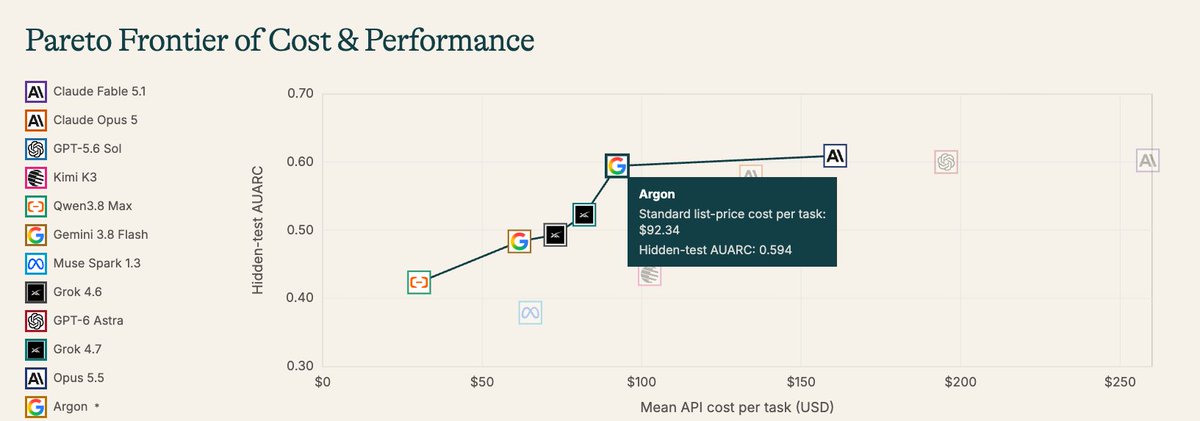
We see an interesting head-to-head comparison at the frontier: Astra starts the strongest and holds the lead for up to 19 hours but Fable 5.1 catches up and gets the top performing spot in the final hours.
Qwen3.8 Max, Gemini 3.8 Flash and Grok 4.6 all sit on the cost-performance Pareto frontier, giving strong options at lower API budgets.
Anthropic's Opus and Fable retain nearly all their validation performance on hidden tests, with gaps of 1.1% and 2.9%. Astra's improvement over Sol extends to generalization too, with that gap falling from 6.9% to 1.7%. (1/n)
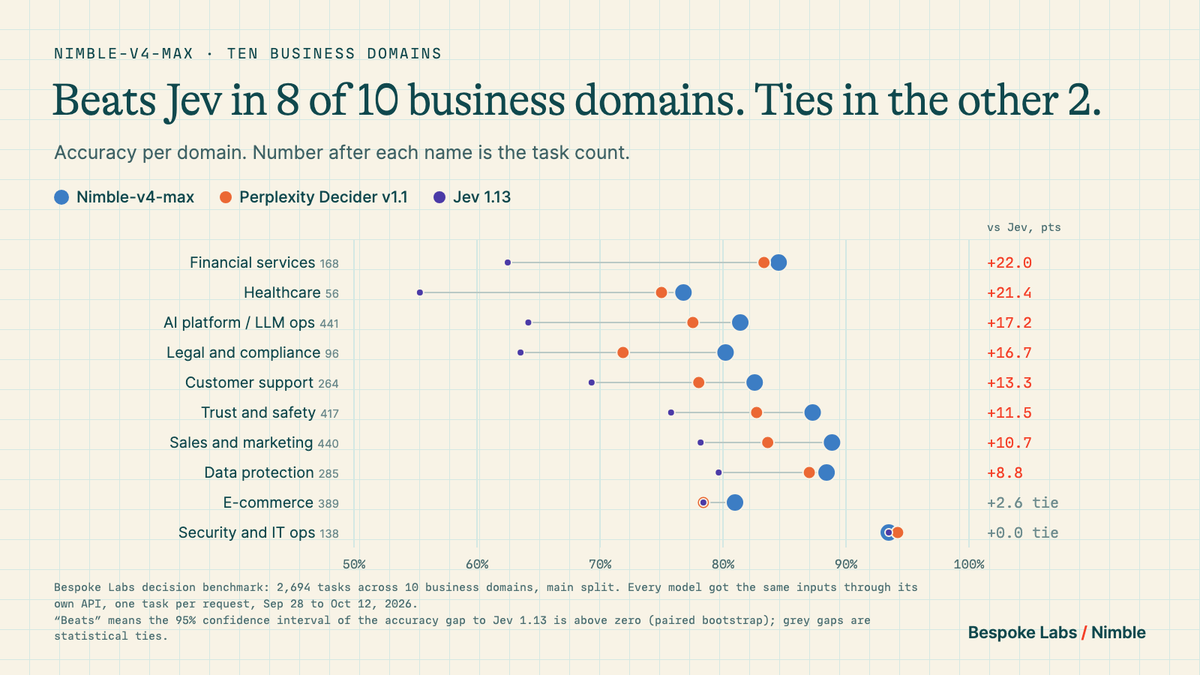
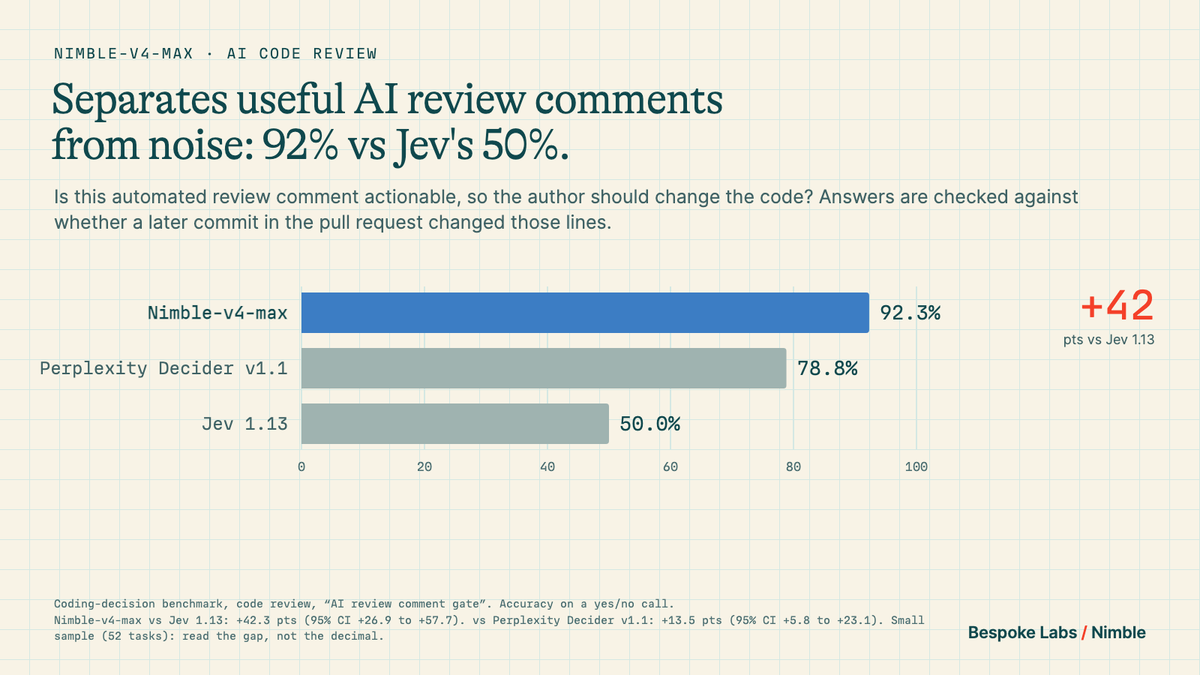
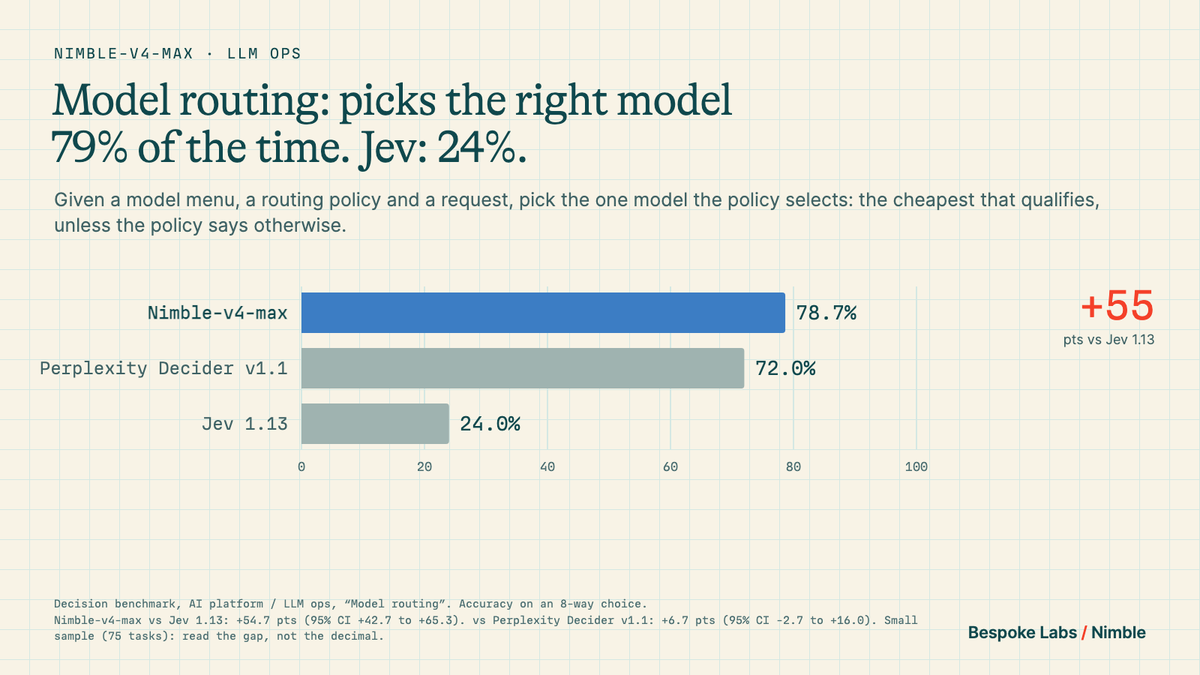
Good to see Bespoke Nimble at #3 on the API providers page of Jevbench, above Jev 1.13.0 and Jev 1.14.0.
https://t.co/IQZRwUxpol
It's available here: https://t.co/J0UCxJN2Ri
"Additionally: ~40% of the issues found were already tracked in the upstream repo - including 21 tasks with outstanding fix PRs!"
Bespoke has found several issues using our internal QC agent, and has been working on improving Terminal Bench over the months.
Here are the 25 issues we filed, and there are PRs corresponding to them.
A subset of these were what @EpochAIResearch also used in their report: https://t.co/FEhJTrE7L6
All of this shows that building RL envs is hard, and building a benchmark is harder
https://t.co/LAnVRgt5xp -> https://t.co/3pFuQtWQoD
https://t.co/NIkQgCS48Y -> https://t.co/1rXlufP7FU
https://t.co/G945ZBHNtJ -> https://t.co/e3boOglGfh
https://t.co/cdF0GAY66f -> https://t.co/GlyikfMorO
https://t.co/tkzvaCRxLM -> https://t.co/ll30WMd925
https://t.co/DGsZJA9hfH -> https://t.co/3kFX6GpOxv
and more below
I launched the first image and video generation models at Google, and kept asking why all AI designs look the same.
AI has brought us the WORST era of design.
It made content creation effortless, but it also made 90% of it look painfully generic.
My co-founder and I spent 2 years building in stealth to change that.
Meet Vyb, the first AI design model that understands your taste like a designer would.
RT + comment your website URL and we’ll make your first design.
"Additionally: ~40% of the issues found were already tracked in the upstream repo - including 21 tasks with outstanding fix PRs!"
Bespoke has found several issues using our internal QC agent, and has been working on improving Terminal Bench over the months.
Here are the 25 issues we filed, and there are PRs corresponding to them.
A subset of these were what @EpochAIResearch also used in their report: https://t.co/FEhJTrE7L6
All of this shows that building RL envs is hard, and building a benchmark is harder
https://t.co/LAnVRgt5xp -> https://t.co/3pFuQtWQoD
https://t.co/NIkQgCS48Y -> https://t.co/1rXlufP7FU
https://t.co/G945ZBHNtJ -> https://t.co/e3boOglGfh
https://t.co/cdF0GAY66f -> https://t.co/GlyikfMorO
https://t.co/tkzvaCRxLM -> https://t.co/ll30WMd925
https://t.co/DGsZJA9hfH -> https://t.co/3kFX6GpOxv
and more below
The @SnorkelAI team did an audit of these findings using our internal QC platform.
Tl/dr: We agree with many of the findings, but ~55% of the fixes from @preferencemodel had their own issues with reward hacking or over-prescriptiveness.
Additionally: ~40% of the issues found were already tracked in the upstream repo - including 21 tasks with outstanding fix PRs!
Building datasets like this - and maintaining ambitious open benchmarks around them - is hard. We believe it requires open, collaborative review with community maintainers and relevant domain experts to get right.
@terminalbench was one of the first community efforts to build an open, continuous benchmark, and drive a vision of how OSS contributes to the rapidly advancing frontier of AI. We hope that the community will invest in working collaboratively with benchmark maintainers and task authors to keep this vision alive.
---
Some takeaways + details of our preliminary audit:
(1) We confirm 100% of the reward hacking / verification gap findings using our QC system. However, we find that 17/44 (39%) of the corrected tasks are just as or more reward hackable. Additionally, we don’t yet see evidence that these verification gaps meaningfully affected benchmark rollouts within CIs, though our analysis here is still ongoing.
(2) Our preliminary review raises questions about the underspecification findings for 22/41 (54%) of the flagged tasks, including 7 explicitly marked by task authors as intentional design choices. These cases warrant expert peer review and adjudication: balancing over/under-specification is a critical and tricky design decision - much of human intelligence concerns dealing correctly with reasonable and realistic underspecification - and we believe these corrections made to the tasks are likely too over-specified, reducing realism and difficulty relative to spec.
(3) Around 40% of the issues found were already tracked in the upstream repo (including 21 tasks with outstanding fix PRs)! OSS projects require community efforts to correct identified open issues, and ideally audits like these are done collaboratively with task authors and maintainers directly, in the traditional community spirit that has kept OSS alive for decades.
We added Gemini 4 Argon to our AutoResearchExam Pareto curve. It is 2-3 times cheaper compared to the other frontier models for almost the same ML engineering performance. Congratulations to the GDM team.
@HamelHusain For your next post, please keep Bespoke-Nimble-v4-max in mind! Our model beats a few of the models you have used and might be worth giving a try (https://t.co/IQZRwUxpol)
Very cool work by Pref model!
We have an internal QA system which has been finding issues as well, and we have submitted several fixes to Terminal Bench so that Terminal Bench continues to improve.
This story is not just for Terminal Bench, wink wink.
We looked at TerminalBench 4.0 and found a lot of issues. After fixing the issues Sonnet 5.5 scores 89.2%. So, TerminalBench is already mostly saturated.
Along the way we found a lot of crazy stuff, including reward hacks in the published transcripts.