@danintheory If OpenAI continues to update the /math repo, it might be nice to do a minor update to the irrationality of pi is 2 paper as well to state this full more general theorem.
OpenAI's proof that the irrationality measure of pi is 2 is actually much more general, and applies to most of the open constants here: https://t.co/a6bqzKe3gN
Every number of the form:
1/sqrt(D) arctanh(t sqrt(D)) for t in Q, D in Z squarefree
Has irrationality measure 2.
That includes all logarithms of rational numbers, various arctangents, numbers such as pi/sqrt(3), and many more.
From Claude Opus 5.5
https://t.co/3CQWCxnS8a
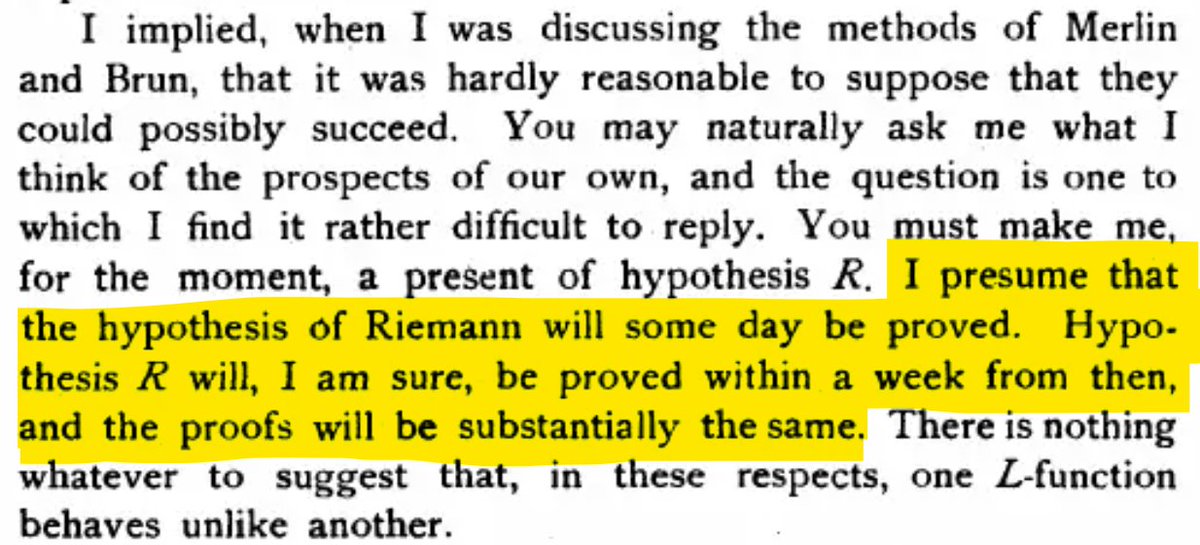
Experts have long conjectured that any proof of the Riemann Hypothesis would apply for all Dirichlet L-functions too.
Hardy wrote exactly that in 1921 (image below).
Interestingly, OpenAI's 7/8 quasi-Riemann hypothesis actually cannot prove the result for only zeta!
The family-wide formulation is essential to the argument. The argument proves the bound simultaneously for all finite-order Hecke L-functions over Q[sqrt(-3)], and it has to do that to work. The generality is part of the proof itself.
So Hardy was quite right on this conjecture he made more than 100 years ago.
@iteratedlog@AlexKontorovich@jdlichtman@KenOno691@wtgowers
@FanNie1208@OpenAI OpenAI's result overall is correct, and there is no hole in the proof. The last sentence on page 46 is off as you point out, but it doesn't actually matter. I've had multiple AI agents adversarial review the paper line by line, and any issues seem to be fixed relatively easily.
One problem: The EU/Canada may never catch up to the frontier capabilities of Anthropic and OpenAI. The $2B the Canadian Government has committed to compute is less than 1/1000th of what the US hyperscalers are building, and when compared to the roadmap and plans of many companies such as SpaceX, and Blue Origin, it's smaller still.
The analogy to CERN holds only if you assume there is a 1000x bigger privately owned CERN. Serious physicists trying to understand the universe are going to want to use that.
If the intelligence of models continues to improve, it's likely that the only viable option is to pay the US AI companies (or perhaps Chinese AI companies) for access to these models.
To quantify the magnitude of OpenAI's math results yesterday: It's a decade of math breakthroughs done in a month.
Global human math output in 10 years would produce about this many astonishing and truly top level papers.
@littmath@nihilsuncle For most physicists who work on big LHC experiments, the day to day work is mostly data science, coding, signal analysis, etc. They still know a lot of physics, the work is valuable, and it's not a disaster for physics that it works that way.
I think it's fine for someone to put their name on something where the AI did all the mathematical work. A lot of the concerns about this will disappear as the low hanging fruit are exhausted, and it becomes harder to point an AI at a problem and solve it. At that point, it will better resemble the current status quo with open problems, where at least some of the measure of hardness is "Team A could solve it where no one else could."
Other non-mathematical aspects will become the drivers, and they are valuable. These include: problem selection, resource allocation (most problems are not amenable to simply using more AI usage, but some are), managing the AIs doing the work, assessing progress reports from the AIs and whether one should keep going, and so on.
Example: When Astra 6 came out I pointed it at proving that zeta(5) is irrational for a while. I believed, based on what I knew about the proof of zeta(3), that this problem was particularly susceptible to AI. My GPT 6 Pro and Codex Astra sessions failed.
I don't know the split between AI and human ideas of the author who did prove it was irrational, his statement is ambiguous, but even if it was pure AI, I think it's a nice result because they did something I, and others, could not do.
@tonylfeng "... maybe think to consult mathematicians?"
Julia Kempe did her PhD in mathematics under Elwyn Berlekamp.
Also a crude, but quantifiable, metric can still be useful in such research even if it is imperfect. Sometimes something is infinitely better than nothing.
"A heart surgeon who has a higher survival rate is a better heart surgeon."
The issue is that statement is clearly false? Under this metric, a heart surgeon working at a hospital in an area with very unhealthy people, who have a lower base rate of survival from the surgery, will erroneously be judged as a worse heart surgeon than one who works in a region with healthier patients.
The metric is poor, and leads to incorrect conclusions from the data because it doesn't take into account base rates. And not properly accounting for base rates is precisely the issue that you run into when people optimize for that metric. The optimization behavior exacerbates what makes it a bad metric, but critically, it was always a bad metric.
Here is the full github repo, which now cites Krachun, with a complete lean formalization: https://t.co/juOSEVnyMV
It includes two pdfs:
1. A full proof of 0.758067... https://t.co/dIYdO3m36Y
2. A simplified proof that is easier to read and understand that yields 0.758 https://t.co/gKks7xmMnL
@thomasfbloom
Astra is insanely good at math.
I was playing around with it over the weekend, and 7/7 of the problems I tried, it improved the best existing bound in the literature.
1. Linnik's constant 5 -> 4.57
2. Matrix Multiplication Exponent 2.371177 -> 2.371161
3. Ramsey R(k,k)^(1/k) upper bound 3.8 -> 3.73
4. Sarkozy Theorem lower bound 0.733 -> 0.7577
5. Unit Distance Exponent 0.0358 -> 0.0418
6. Double Cap Conjecture Upper Bound Error 0.00241 -> 0.00171
7. Capset lower bound bound 2.2203 -> 2.22175 (I have an unpublished human result of 2.2210, which is now bested by this)
It is likely possible to further optimize, with Astra, a lot of the constants here: https://t.co/P2f9UQOxez
@polynoamial
For a number of the problems, I am confident because I read the proofs. E.g. Sarkozy, Capset, and the Double Cap fit exactly what I know about the problems, and the method and proofs look right to me.
For all of them, I had Astra GPT 6 perform an adversarial review of the results, with prompts asking it to find the holes in the arguments, and find precisely where the proof is wrong, and all of them survived that process.
For Linnik's constant and Matrix Multiplication, I am much less confident, but I believe they are correct since they survived the adversarial review, and the certificates produced seemed quite robust. Keep in mind that Linnik's constant is like 100 pages of Analytic Number Theory, so it's quite hard to verify in the traditional sense. I am unable to understand these outputs myself, so ideally, I'll have Astra formalize more parts in lean over the next few weeks to put some entries into Palomar.