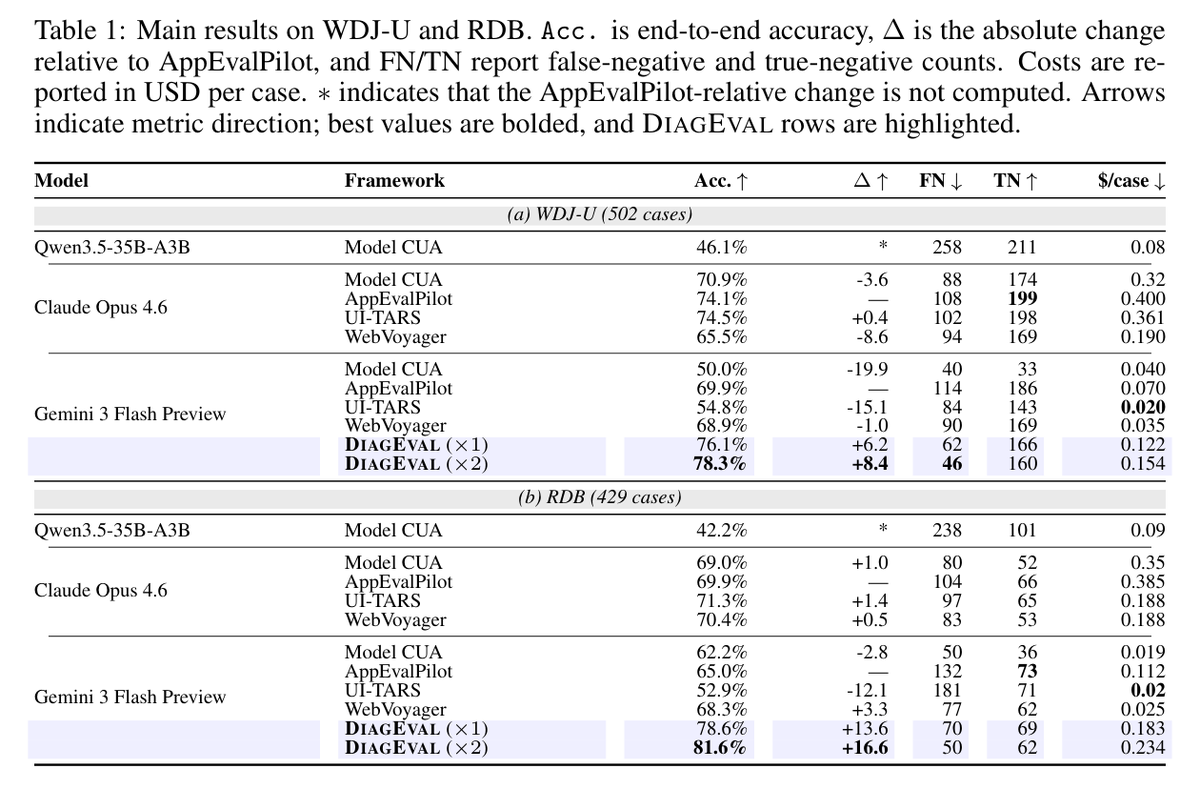
With DiagEval, a Gemini 3 Flash Preview-powered GUI evaluator surpasses the Opus 4.6 baseline in accuracy while costing less than half per case.
📄 Paper: https://t.co/1XS58XePBo
💻 Code: https://t.co/wbeSVryinj
GUI agents are now the default for evaluating vibe-coded apps.
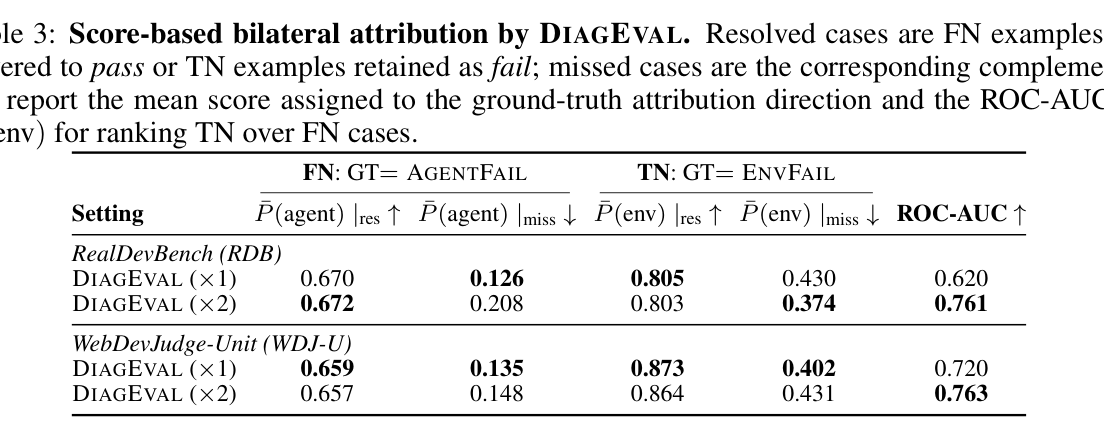
But when an agent says “test failed,” is the app actually broken, or did the agent just fail?
We introduce DiagEval: a post-failure diagnostic framework that treats failed rollouts as evidence, not final verdicts.
1121 cycles.
New record on Anthropic’s take-home kernel challenge.
One meta-evolve agent. 200 attempts.
Stop only evolving solutions.
Evolve evolution.
Is ReAct the final for LLM Agents? 🤔
Not anymore. ReAct is stuck step-by-step. Planning agents separate plans from actions.
Introducing ReCode: agents control their decision granularity, like humans do.
20.9% better, 78.9% cheaper, 3.7× data efficient. The ReAct era is over.
1/5
It's actually a pity that we got no enough time to maintain OpenManus during the past 3 months.
But the better news is that we will build a formal open-source community for OpenManus at the end of this month.
Quality over quantity!
Our work shows concise reasoning trains more efficient, powerful Liter models, paving the way for scalable, cost-effective AI.
Want to dive in? 📖 Explore Liter models & LiteCoT: paper, code, data at https://t.co/151mP6lTaY
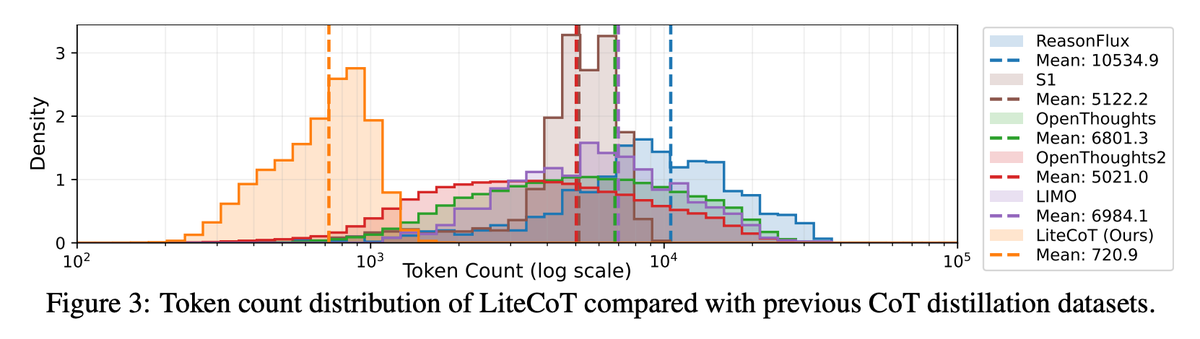
Are longer CoT traces better for model distillation? Nope! 🤖
Our Liter models & LiteCoT dataset 📊 use concise ~720-token CoTs to distill powerful reasoning into smaller models with high efficiency.
Result: Better models, lower costs 📈💰.
1/4
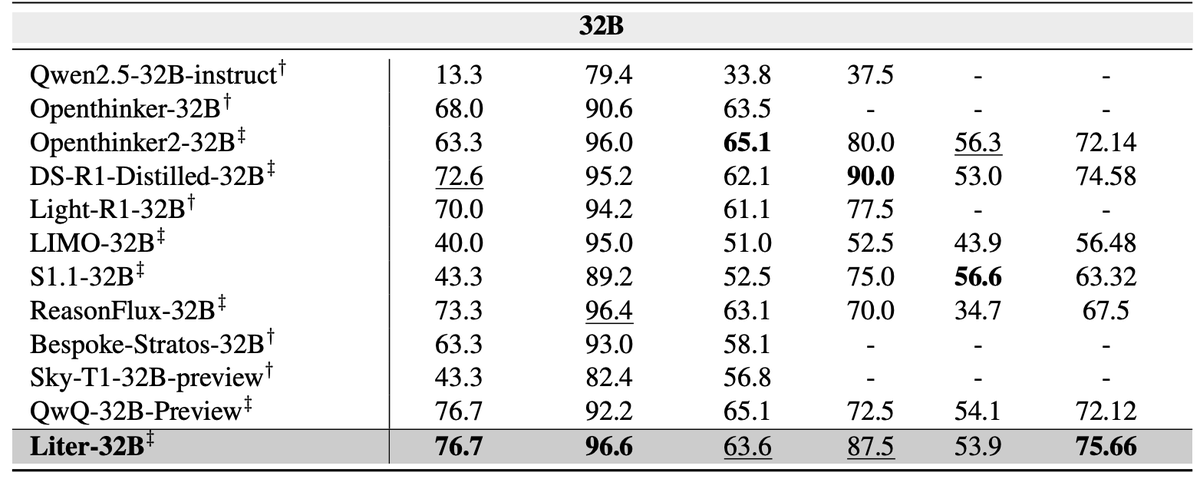
Our Liter model, trained on just 100K concise LiteCoT samples, beats DeepSeek-Distilled models trained on 800K CoTs.
On the tough AIME24 math benchmark, Liter-32B hits 76.7% Pass@1 with ~5K inference tokens, outpacing other baselines in accuracy & speed 📈📷.
3/4