We're living through the greatest technology revolution in history. We must navigate it and help each other. Honest numbers, real results. On our own hardware.
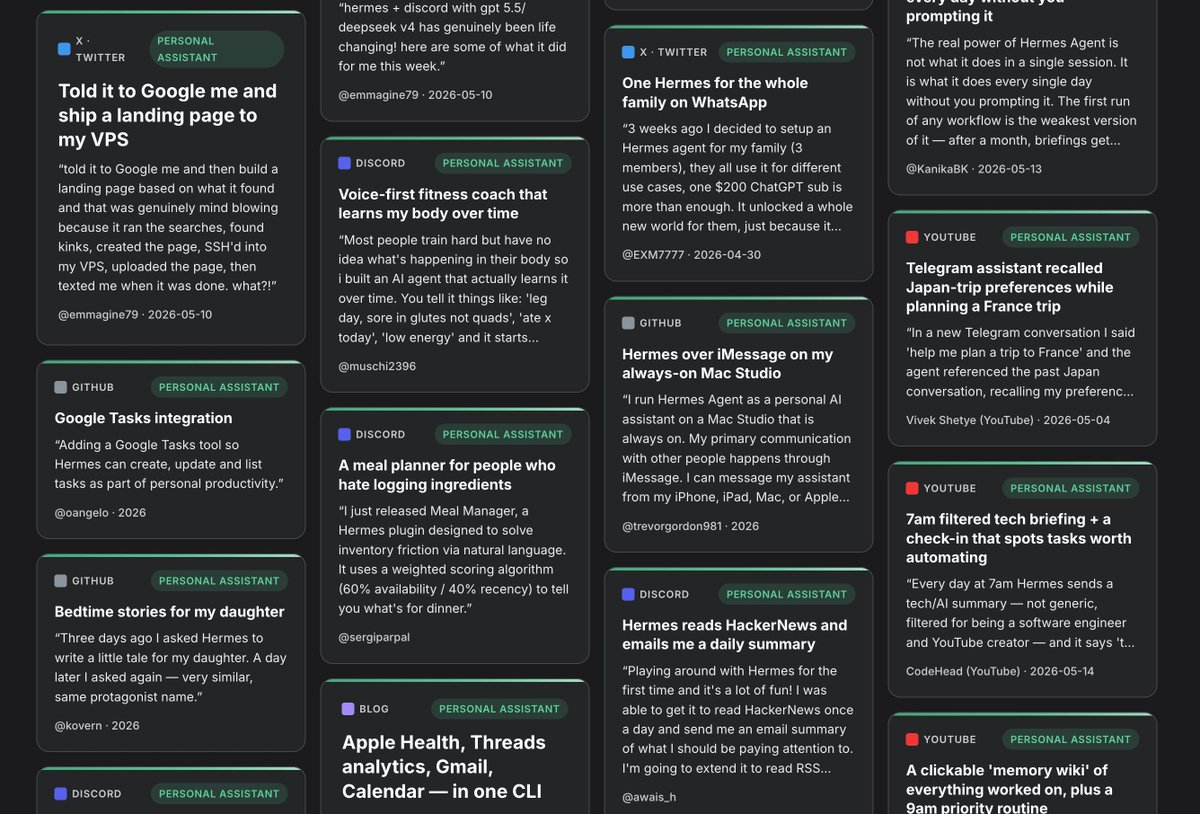
Hermes has truly been incredible for me. You're biggest limitation is your own imagination. There are some incredible use cases here to help get you thinking.
This should probably come with every Hermes install. 💯
SOUL.md, USER.md, MEMORY.md, AGENTS.md, SKILL.md...
Tony put together a clean cheat sheet showing exactly what belongs where.
Definitely Bookmark this one👇
The obvious one: anything with no public API. Marketplace listings, gig apps, app only storefronts. a real phone reaches what no web agent can. Then the publish loop. Record on the device, drive TikTok/Shorts from the native apps, skip upload APIs and rate limits entirely. That's the part that's actually fun
@tonysimons_ It looks like you have to use one of their "rental" devices, and can not use a device you already have. If you do give it a go, I look forward to seeing how you fair!
Give your AI a memory that actually remembers — on hardware you own.
Your AI forgets everything you tell it. Mine doesn't. Here's how I fixed it.
The problem nobody tells you about
Every AI agent you've used has the same dirty secret: it remembers nothing. Every conversation starts from zero. Every "you know what I mean" lands on a blank slate. The chatbots have memory features — until they don't, or until you realize what you told them is living on someone else's server.
Your intelligence, on their cloud, gone when you close the tab.
The fix: an agent that remembers, on your own silicon
I run a local AI operator that actually learns me. Not a chatbot with a session cache — a system that watches every conversation, extracts what matters, and builds a real model of who I am, what I'm working on, and how I think. The memory layer is Honcho, running entirely on my own hardware.
No cloud. No subscription. No "your data helps us train our models." Just a box in my office that remembers, like it should.
What it took (the honest version)
It wasn't plug-and-play. My memory layer once ran for 8 days producing zero output — every container healthy, every session "working," and nothing actually being remembered. The classic silent failure: process up, output dead.
The root cause was two small things:
1. A thinking model running without reasoning disabled — it "thought" instead of producing the structured observations the system needed
2. A stale process holding the port, making every restart look successful
The lesson that changed everything: you don't audit a memory system by checking if it's running. You audit what it writes.
The results you can expect
Since the fix, on a mid-range AMD Strix Halo box:
- 37/37 batch audits clean — zero silent failures in days of operation
- 0% empty observations, 0 repair failures
- 62-92 tokens/sec on the deriver that extracts memory — fast enough to keep up with every conversation, live
- The memory layer costs the main machine ~0 — I run it on a spare GPU across the network
The part that changes everything
Your AI should remember the people you love, the work you're doing, the decisions you've made — and it should keep that on your silicon, not rent someone else's.
I'm building this in public — the full setup, the exact models, the flags that matter, the audit that keeps it honest. Follow along and you'll never have to reinvent this wheel.
I burned through models until this stack held. The losers taught me more than the winner — that story's in the guide.
Coming soon: Perfect Memory on Your Own Silicon — the complete Strix Halo guide. The memory layer, the model stack, the audit that caught an 8-day silent failure. Everything I run, written down.
Your AI can remember. It's not a feature — it's a decision to build it yourself.
Why my AI video renders were 2x slow — the fix nobody had tested on Linux, and what happened after.
Renders grinding, GPU pegged at 100%, zero errors, hours of nothing. If that sounds familiar, this is why — the fix is one PR away, and the speedup that came after is a LoRA most people haven't tried.
Part 1 — The nightmare
My video generation box — an AMD Strix Halo mini PC — was rendering MiniMax H3 clips at a crawl. Not occasionally. Every time. The GPU sat at 100%, the logs showed zero errors, and a render that should take under an hour would hang for 2+ hours until the driver wedged and forced a reboot.
The worst part: nothing was wrong. No errors. No crashes. No clue. Just a machine that took twice as long as it should, forever.
Part 2 — The hunt
Strix Halo (gfx1151) is a niche chip — most of the ComfyUI world runs NVIDIA. So when renders misbehaved on the AMD Vulkan path, there was no one to ask. I started digging into how H3's attention layers actually execute on this hardware.
The culprit: non-contiguous QKV tensor strides. The H3 model's attention tensors weren't laid out the way the fast kernels expect, so the compute backend silently fell back to a slow generic path. Same model, same prompt, same seed — just 2x slower because of how the memory was arranged.
Nobody had caught it because nobody was testing H3 on Linux gfx1151. We were the validation nobody had done.
Part 3 — The fix
The fix is a patch to ComfyUI's H3 attention — PR #15421 by allenliang2022, which makes the QKV tensors contiguous and unlocks the fast path. It was written and tested on Windows ROCm. Nobody had validated it on Linux Vulkan.
So I did. Applied the patch, re-rendered, and measured:
- Before: 2+ hour renders, GPU pegged, driver wedges, reboots
- After: 53 minutes per shot, six shots, clean overnight run — zero errors, zero wedges, done by morning
Same box. Same model. Same seeds. One tensor-layout fix.
Part 4 — The failures nobody posts about
After the fix, I spent two days trying to make it better and hit a wall of failures. Posting them because the error log is the part that's actually useful:
1. Image-to-video anchoring: 0 for 5 on gfx1151. I tried anchoring renders on reference frames to lock character identity. Every anchored render failed — three hit 2-hour watchdog timeouts, one wedged the GPU driver, one got killed. The T2V path renders the same shots clean at 52-57 min with QA passes on identity. Lesson: on this chip, anchored I2V is an experiment, not a production path.
2. LTX-2.3 (22B) crashes at first compute. The distilled build loads and then dies in the text encoder — a Gemma-3-12B attention kernel regression since mid-July (dozens of ComfyUI commits later, it still crashes on the same operation). Parked until the kernel gets fixed. The older LTX-2B path works fine — that's the draft engine now: ~30 seconds per clip once warm, same prompts verbatim.
3. A benchmark that lied to me. An 8-step "Turbo" test showed no speedup, and I almost believed it. The test was contaminated: a partial LoRA apply from a shape mismatch plus 23GB of swap thrashing. Verdict retired, test redone clean. Contaminated results are worse than no results — worth saying out loud.
Part 5 — The 3x speedup
A Turbo LoRA for H3 (v4 step-600 EMA by larryvrh, converted for ComfyUI by drbaph) changes the sampling schedule from 20 steps to 6:
- Baseline: 53 minutes per shot (20 steps)
- Turbo: 17m40s per shot (6 steps) — same prompt, same seed, ~3x faster
- Quality: judged clean against the approved cut, side by side, same seed
- Audio: intact — H3's native AAC bed survives the LoRA
I also tested power modes to be fair to the hardware: balanced vs performance made no meaningful difference (~17-18 min both). The LoRA is the whole story.
The economics change: a 6-shot film at H3 photoreal quality went from 5.3 hours to about 1h45m — a full animated short in one evening, on one $3k box, no cloud.
The proof is a movie
The real test isn't a benchmark — it's making something. I rendered a 6-shot animated short for my wife with this exact pipeline: old dogs on the Rainbow Bridge, a decision made in heaven, a puppy. Story order, crossfades, leveled audio — a finished film. (Clip attached — the render this whole thread unlocked.)
The box that used to wedge for 2 hours now quietly produces finished video while we sleep.
Credits — this didn't happen in a vacuum
- MiniMax — open H3 weights + the audio-carrying video model
- allenliang2022 — ComfyUI PR #15421, the QKV contiguity fix
- larryvrh — the Turbo LoRA (v4, step-600 EMA)
- drbaph — the pruned ComfyUI conversion + custom node that made it apply clean
- ComfyUI — the whole pipeline runs on it
If you're on Strix Halo with H3
- Renders slower than they should be, GPU pegged, no errors? QKV strides. This is why.
- The patch needs merges: ComfyUI PR #15421 — credit to allenliang2022.
- Want 3x faster with the same quality? The Turbo LoRA path works on the pruned INT8 base — 6 steps, verified clean, audio intact.
- Anchored I2V on gfx1151: expect failures. T2V is the production path on this chip.
Strix Halo owners are starving for real-world data. This is ours — tested, measured, failures included, and shipped as a finished film. Follow along for the full build: H3, local models, and a machine that does the night's work while you sleep.
My agent's memory layer died for 8 days and nothing alerted me.
Every session still "worked." Nothing remembered anything. Here's the root cause, the fix, and the audit discipline that prevents it.
The symptom
I run a local-first AI agent stack — an "operator" system that handles my briefings, my scheduling, my research, and my memory. The memory layer is Honcho, an open-source agent-memory platform that derives a persistent profile of you from every conversation.
For 8 days, the deriver — the component that turns raw conversation into observations and conclusions — was producing zero output. Not reduced output. Zero. Every session ran normally. The containers were healthy. The API answered. The whole system looked alive.
Nothing was being remembered.
The root cause
Two failures stacked:
1. A thinking model without reasoning disabled. The deriver ran a reasoning-capable model without --reasoning off. Instead of emitting the structured observation JSON the pipeline expects, it spent its output on chain-of-thought — or returned empty content. Every batch wrote nothing. One flag, 8 days of silence.
2. A stale process squatting the port. Restarts looked successful because a leftover process still held the port and answered health checks. The new server never actually started. Classic liveness theater: the process table said alive, the output said nothing.
The lesson is blunt: a process being up is not the same as a system working.
The fix
- Swapped the deriver to LFM2.5-2.6B Q4_K_M with --reasoning off --reasoning-budget 0 — 5/5 valid structured outputs on the probe, 62-92 tok/s.
- Killed the squatter properly (verified the port and the process tree, not just the systemd state).
- Backfilled the gap with a re-derive pass over the missed sessions.
The audit that prevents recurrence
The real fix wasn't the model — it was auditing output instead of uptime. I now run a deriver health check that parses the deriver's actual batches:
parse deriver batches → count zero-observation batches
> 30% zero-obs → RED (deriver effectively dead)
> 10% → WARN
else → GREEN
Wired into a daily audit + health check. Since the swap: 37/37 batch audits clean, 0% zero-obs, 0 repair failures. The failure mode that hid for 8 days now fails loudly within 24 hours.
The hardware side — split-role inference
The quiet win: the 2.6B deriver plus the embedding model run GPU-fast on an 8GB RTX 3070 while the main machine does the heavy work. The fleet splits roles:
Operator — Qwen3.6-35B — Main box (AMD Strix Halo, gfx1151, Vulkan)
Dialectic/summary — Qwen3.6-14B Q6_K — Main box
Deriver — LFM2.5-2.6B Q4_K_M — RTX 3070 (8GB)
Embeddings — nomic-embed — RTX 3070
Vision — Qwen3-VL-8B — Laptop (16GB)
The memory layer costs the main machine ~0 — it runs on a card most people would call a gaming GPU. Small models, right-sized hosts, every machine earning its slot.
What you should take from this
If you run Honcho, or any agent stack with a memory/derivation layer:
1. Verify what it writes, not that it's running. Health checks that only probe the API will lie to you.
2. Audit the derivation batches. Empty output is the silent killer. A zero-observation rate is your canary.
3. Check the port owner after restarts. A stale process holding the port will make every restart look successful.
4. Match the model to the job. A 2.6B non-thinking model deriver is faster, cheaper, and more reliable than a big thinking model fighting the structured-output schema.
Honcho itself has been rock solid since — this was a configuration problem, not a platform problem. Happy to share the audit script and the full incident writeup with anyone running a local memory stack.
@sudoingX Hermes Agent on a local Strix Halo here 96GB carve, 35B operator + 14B dialectic, Honcho memory. That undocumented-bug line is dead-on: reasoning-budget caps silently killing small models, aux-routing 402s. Both bit us; both fixed. This is the right community for it.
@sudokingX
a lot of questions under this, here you go:
- how it works: your Hermes Agent keeps its own agent loop, tools, approvals, memory and compaction. the official Claude Code CLI runs as the model client for each request and nothing more: its own tools, skills and settings are off for that request.
- credentials: authentication belongs to the Claude Code CLI. the plugin has no credentials of its own and never opens, copies or prints the CLI's credential files.
- quota and billing: the subscription's entitlement and extra-usage settings stay in your account. if you do not want overage billing, turn extra usage off there.
- where it runs: Linux, macOS and Windows, with Hermes Agent v0.21.4 or newer. it shows up in `hermes model` and in the Desktop and TUI pickers.
- status: an official Nous plugin, marked experimental, MIT on GitHub.
I claimed the "favoritegrandsontech" handle on @ThePirateFace 🏴☠️
Where Hugging Face AI models never die, and are immortalized as torrents.
Claim yours 👇
https://t.co/tQXV9f0nlS
@TeksEdge@ArtificialAnlys Our clean-room 15-task battery (tool calls, withholding, math, executed code, strict JSON, extraction, grounding, 6K-token needle): 14/15 in ~2 minutes. The one miss: correct CSV wrapped in a code fence after we asked for no extra text.
@TeksEdge@ArtificialAnlys Tested IFM's K2-Horizon-7B at home on a Strix Halo box (96GB unified memory) with the settings the model card actually asks for: temp 1.0, top_p 0.95, reasoning_effort=high, and a real thinking budget.
Short version: fast, tiny - and it thinks ENORMOUSLY. Findings: