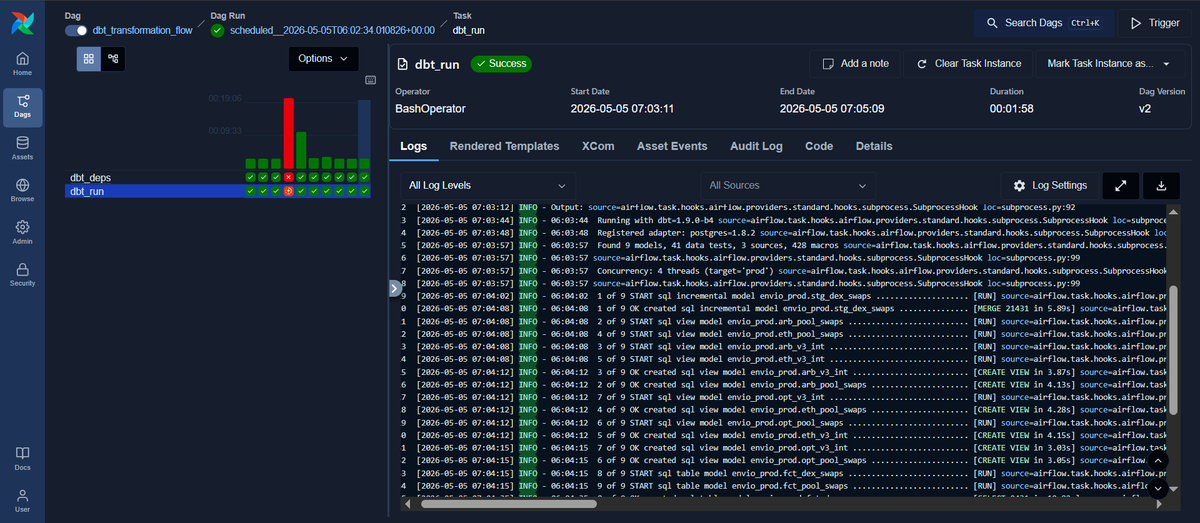
I designed a pipeline that models cross-chain transactions , reconciling the txn from source chain to destination chain.
Agents & analysts can then know exactly what a txn is.
https://t.co/DPlbgPKKi6
In Week 6 of Data Engineering with @AnalyticSages , I introduced batch processing with Apache Spark.
Here is what we covered, from chunked Parquet files to a report that is safe to re-run.
A thread.
In Week 5 of Data Engineering with @AnalyticSages , I introduced orchestration with Apache Airflow.
Here is what we covered, and how we made the Uniswap V3 pipeline run on its own.
A thread.
Schedule
The incremental DAG ran every five minutes, one run at a time, so each run picked up where the last one stopped.
Safeguards
We added two retries with a delay for transient RPC failures, Slack alerts, and an idempotent load, so a retry or re-run could not duplicate rows.