A new frontier for on-device speech.
We're open-sourcing Phonon, a suite of TTS models under 50m parameters, setting a new standard for naturalness and accuracy across languages, with the broadest inference support to date.
Phonon-31m is available under Apache 2.0.
https://t.co/d3qa9qmnzY🧵
Our launch partners at @autonomous_labs gave Lamp, their personal robot with an open-source OS, a voice that it generates on the robot itself.
Lamp runs on an OrangePi 4 Pro, and Phonon shares its CPU with the robot’s OS and local AI models.
The team designed Lamp’s wizard-hat character voice in Gradium Voice Designer.
Our launch partner @modal built an open-source @pipecat_ai voice agent on Modal with Phonon running on the agent’s own CPU, right next to the conversation logic.
Modal runs AI workloads in containers that scale with demand.
A fresh agent container starts in under 2 seconds with Phonon already loaded.
https://t.co/PlWvzeqBtv
A new frontier for on-device speech.
We're open-sourcing Phonon, a suite of TTS models under 50m parameters, setting a new standard for naturalness and accuracy across languages, with the broadest inference support to date.
Phonon-31m is available under Apache 2.0.
https://t.co/d3qa9qmnzY🧵
A new frontier for on-device speech.
We're open-sourcing Phonon, a suite of TTS models under 50m parameters, setting a new standard for naturalness and accuracy across languages, with the broadest inference support to date.
Phonon-31m is available under Apache 2.0.
https://t.co/d3qa9qmnzY🧵
Phonon from @GradiumAI is a fantastic release. It is tiny (31M params), runs on-device with low latency, and the voice is super clear for something this small.
🔊 Hear it yourself: full precision vs 8-bit vs 4-bit below.
Now available in pipecat-local-tts-server v0.6.0: https://t.co/NiQKDv5c4B
Bonus: supporting it meant bumping mlx-audio, which also sped up the other models by 14–20%.. h/t @Prince_Canuma + MLX team 🙏
Announcing Phonon in Say It — private, local text-to-speech for macOS
Open models 100% on-device, speak text from any app with a hotkey.
Get it now at https://t.co/SmmeOVW17r
Listen to the video 🔊
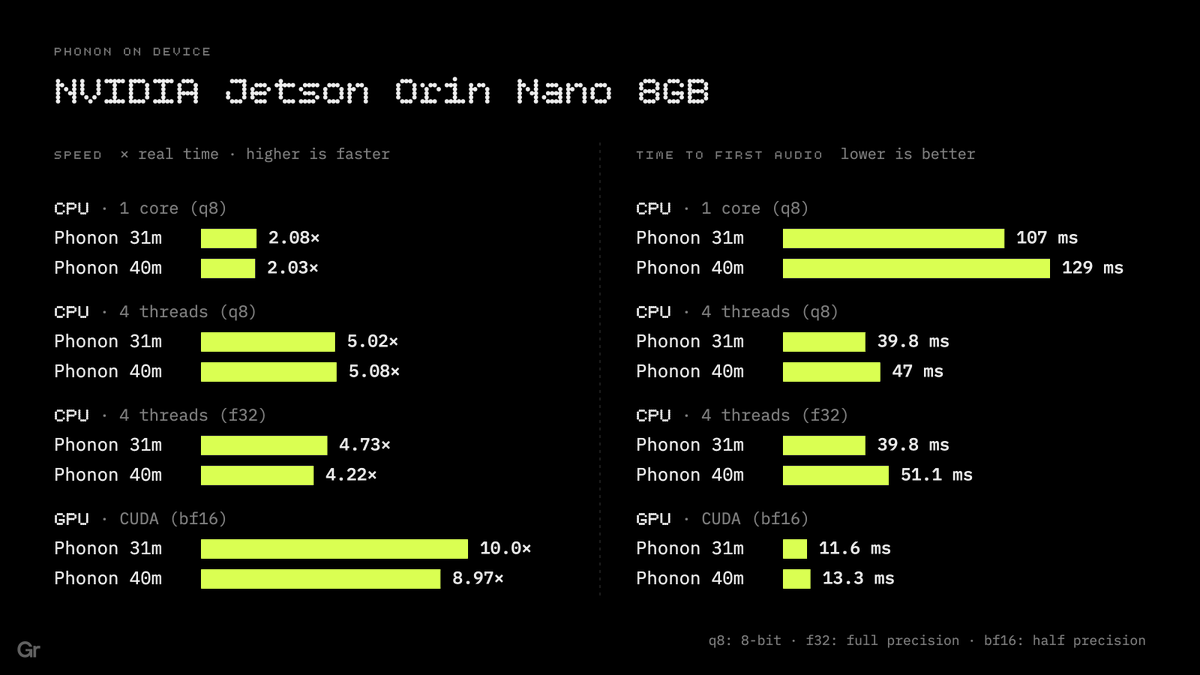
Robots kept coming up at @NVIDIAGTC Berlin this week. Phonon runs on the Jetson Orin Nano 8GB: local speech, no network. Any robot can have its own voice.
A new frontier for on-device speech.
We're open-sourcing Phonon, a suite of TTS models under 50m parameters, setting a new standard for naturalness and accuracy across languages, with the broadest inference support to date.
Phonon-31m is available under Apache 2.0.
https://t.co/d3qa9qmnzY🧵
The team at @distil_labs post-trained a model on their docs in under 6 hours and built a voice agent with Phonon.
If your voice agent works within one product or one knowledge base, fine-tuned models can perform well and help cut down latency and cost.
We dropped by the @GradiumAI booth at GTC Berlin and let Tim quiz our agent. It answered in their new Phonon voice.
The agent is a small model we post-trained on our docs in under 6 hours.
Build your own: ask your coding agent "get started with https://t.co/yEabN5SABx"
First game built on Phonon.
The @xybrid_ai team built Space Jarv, a 3D game where Phonon runs inside the game on a 16GB M1 Pro MacBook.
Phonon voices every line live on the player’s device.
If your game has talking characters, give them Phonon.
https://t.co/2YpIsrivv1
A new frontier for on-device speech.
We're open-sourcing Phonon, a suite of TTS models under 50m parameters, setting a new standard for naturalness and accuracy across languages, with the broadest inference support to date.
Phonon-31m is available under Apache 2.0.
https://t.co/d3qa9qmnzY🧵
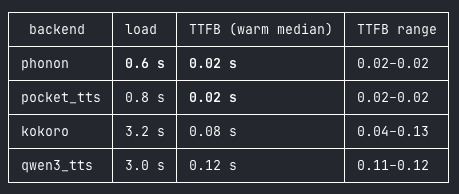
Gradium just released Phonon, an open weights TTS model small enough for a CPU.
Micdrop now runs it inside your Node voice agent, with no API key, no GPU and no audio leaving the machine. First words in under 100 ms.
Five languages, 102 voices 👇
https://t.co/Ex2mhDvE2e
@GradiumAI Congrats on the launch, Gradium team! 🎉
We shipped the Micdrop integration today, so Phonon now runs inside a Node voice agent, on the CPU, with no API key. First audio in 30 to 100 ms on a single M2 core, incredible!
https://t.co/Ex2mhDvE2e
Phonon is now the default voice in Nativ.
Nativ is the free, open-source app from @Prince_Canuma and the Neywa Labs team for running AI models locally, built on MLX-Audio.
A new frontier for on-device speech.
We're open-sourcing Phonon, a suite of TTS models under 50m parameters, setting a new standard for naturalness and accuracy across languages, with the broadest inference support to date.
Phonon-31m is available under Apache 2.0.
https://t.co/d3qa9qmnzY🧵
🤗 transformers serve now speaks 🔊
We just added an OpenAI-compatible `/v1/audio/speech` endpoint.
And we couldn't have picked a better model to launch it
with than Phonon, @GradiumAI brand-new on-device TTS: tiny, fast and multilingual.
Run with:
transformers serve gradium/phonon-40m-en
On-device voice agents are ready to ship with Phonon and @pipecat_ai.
Pipecat runs inside the IOS app and directs the conversation, deciding who speaks and when.
Phonon 31m gives each character its own voice and drives the lip sync on their animated faces.
https://t.co/1rO4jwtrp4
A new frontier for on-device speech.
We're open-sourcing Phonon, a suite of TTS models under 50m parameters, setting a new standard for naturalness and accuracy across languages, with the broadest inference support to date.
Phonon-31m is available under Apache 2.0.
https://t.co/d3qa9qmnzY🧵
I told you it was not finished!
Banger release from the goated french speech team, aka @GradiumAI
day0 transformers 🤗 support, have fun building with it!
Yesterday we open-sourced Phonon, and today we’re at NVIDIA GTC Berlin.
Phonon’s inference stack includes an NVIDIA CUDA backend, so it runs on professional and gaming GPUs and on embedded hardware with Jetson.
Today we’re announcing it with @nvidia: https://t.co/9zzrbhZegW
A new frontier for on-device speech.
We're open-sourcing Phonon, a suite of TTS models under 50m parameters, setting a new standard for naturalness and accuracy across languages, with the broadest inference support to date.
Phonon-31m is available under Apache 2.0.
https://t.co/d3qa9qmnzY🧵
And if you want to scale even smaller than Phonon, @Manu__Orsini leads the way towards building the smallest possible TTS models that stay accurate and natural.
Pocket TTS has been getting updates those last few days. While it was ~100M parameters, we release smaller versions, down to 1.9M: an 18.2M model with the quality of the original, a 6.9M model, and a 1.9M model that runs 103x faster than real time on one CPU core. All with voice cloning.