Print Screen on Windows.
For decades this was 'take the screen and put it in the clipboard'.
Now it's 'wait 5 seconds, hope your screen hasn't changed, launch some over-complex snipping tool'.
UX people don't know how to just leave stuff that works alone.
if you've been using latest frontier LLMs, it's almost certain that you would have noticed by now the newer models have become worse to talk to
they're more robotic, they speak jargons, they spits out verbose text, and do stuff you didn't ask for
how did that happen? well, i'm not the person who trained those models so i can't speak for certain, but i've known enough evidence that gives me a well-educated guess, and i thought it's interesting to share as a crash course of modern LLM training pipelines
so here we go
let's wind back to 2020. GPT-2 and GPT-3 already came out and were widely available, but they could only predict one token at a time - that's what LLMs are at their core
token prediction was offered via API, but there was nothing you could "talk to". so while it generated a lot of excitement in the academic field due to the emergent intelligence, it didn't have any wide adoption
in 2022, ChatGPT changed all that. the research work that led to ChatGPT was a model initially named "InstructGPT". it took GPT-3 as the intelligent base, and used reinforcement learning with human feedback (RLHF) to teach the models how to "chat"
the core idea of RLHF is that you ask the model to generate a few responses, and then let real humans pick which one they like. do this over and over again, and you get a model that knows how to talk
worth noting even as early as InstructGPT, research found that making the model more pleasant to talk to will reduce their pure academic capabilities. this was called "alignment tax", which is an interesting thing we'll come back to in a bit
there were various techniques done to minimize the reliance on humans, but ultimately the reward is modeled after human preference, making these AI assistants easy to talk to
so remember this: RLHF = training the model to be likable by humans
in 2024, there was an inflection point introduced by claude sonnet 3.5 which was the first model that can kind of autonomously finish coding tasks. it led to the first wave of viable "coding agents"
the way sonnet 3.5 achieved this was by training the model with a harness (now it's called an agent) that has bash and file editing tools, throw the agent into a virtual machine, give it a task, and let it try to complete it. these tasks all have a machine-verifiable outcome predefined, mostly via test cases, that can validate whether the model really finished the task or not
then you let the model do billions and billions of attempts in such virtual environments, and some of them would succeed by chance. you keep the successful agent sessions, and use reinforcement learning to teach the model to do that more, and boom - you get a coding agent
that is called reinforcement learning with verifiable rewards (RLVR). if you look closely, you'll see that in this RLVR process, the final text response from the model doesn't matter AT ALL, as long as the code written by the agent could pass the test. it could talk like a jerk and it would still be rewarded
so remember this: RLVR = training the model to be accepted by machines
late 2024 and early 2025, we saw o1 and deepseek R1 came out as the first wave of "reasoning models". this article is getting long so i'm not diving into reasoning models now, but just know that reasoning models also relied heavily on RLVR to scale the training process - let the model think before taking action, and if the thinking led to a machine verifiable outcome, reward the thinking trace and teach the model to think like that more often
the biggest difference between RLVR and RLHF is that RLVR is more scalable. human feedback is expensive to get, especially in domains where only an expert can have a valid opinion on which result is good
with RLHF, if we let the model generate 100 responses, then a human has to review all 100 responses to pick which is good
with RLVR, the human (or sometimes an AI) would define a task and verifier only once, and the model can generate a million responses - the machine verifier will pick which responses are good in an automated way
so as a result, RLVR is becoming more and more dominant in newer models' training pipeline
if you put all these things together:
- RLHF = training the model to be likable by humans
- RLVR = training the model to be accepted by machines
- RLVR is more scalable
- "alignment tax" says "likable by humans" makes the model do worse on verifiable tasks
now you see why the newer models are becoming less and less likable?
this is not just a "frontier labs screwed up their model training" problem - this is a war between machines and humanity, and humanity is losing
we chased after benchmarks, when none of the benchmarks measure whether humans actually enjoy working with the model
we use machines to decide which AI response is better because that's easier and cheaper, when we have no way of making sure those machines actually represent what we humans want
we let AI go dark in a virtual environment on its own and complete predefined tasks at all costs, when in reality we often cannot define a verifiable outcome upfront, and need AI to work with us along the way
i don't have a good solution to this, but i want to call for awareness that we're starting to witness a failure in aligning super intelligence right in front of our eyes
this war between machines vs humanity is one we really can't afford to lose
@jack Very intriguing. Focus on making it extensible. All these systems like OpenClaw and Hermes are opinionated, you end up needing to replace core bits of them once you differ in needs.
"If you hold a gun and I hold a gun, we can talk about the law. If you hold a knife and I hold a knife, we can talk about rules. If you come empty-handed, and I come empty-handed, we can talk about reason. But if you hold a gun and I only have a knife, then the truth lies in your hand. If you have a gun and I have nothing, then what you hold in your hands isn’t just a weapon, it’s my life."
Local AI is worse in almost every way compared to GPT-5.4 ridiculously difficult to manage and expensive.
But I shill it anyway.
It's been 4 years since this started. In that time:
1. the US government is using AI to bomb countries
2. we have mass layoffs all around us
3. people are getting pushed into psychosis
4. people are using this technology to scam at scale
5. people can't distinguish reality from fiction
6. Peter Thiel is running around yapping about the antichrist
7. self driving cars are entering into the European markets
8. Robots can now be driven by LLMs
9. Ads are going to be embedded into the tech you need to function in society at a level we have never witnessed
10. Education systems have officially snapped in half.
11. The LLMs are building better versions of themselves.
12. Claude has committed to 4% of public github repos.
I have no problem with anyone from OpenAI, Anthropic, xAI etc.. I respect and appreciate many of them.
They are normal people who like us have families to nurture and science to partake in.
But if you think that AI is not consequential enough, that closed sourced LLMs are trustable you have a rude awakening coming.
AI is power.
@discord "which in most cases means it's deleted immediately"
That 'most' is really reassuring. Your systems lied. Your posts lied. You implemented intrusive measures no other equivalent product requires.
Why would anyone stick around?
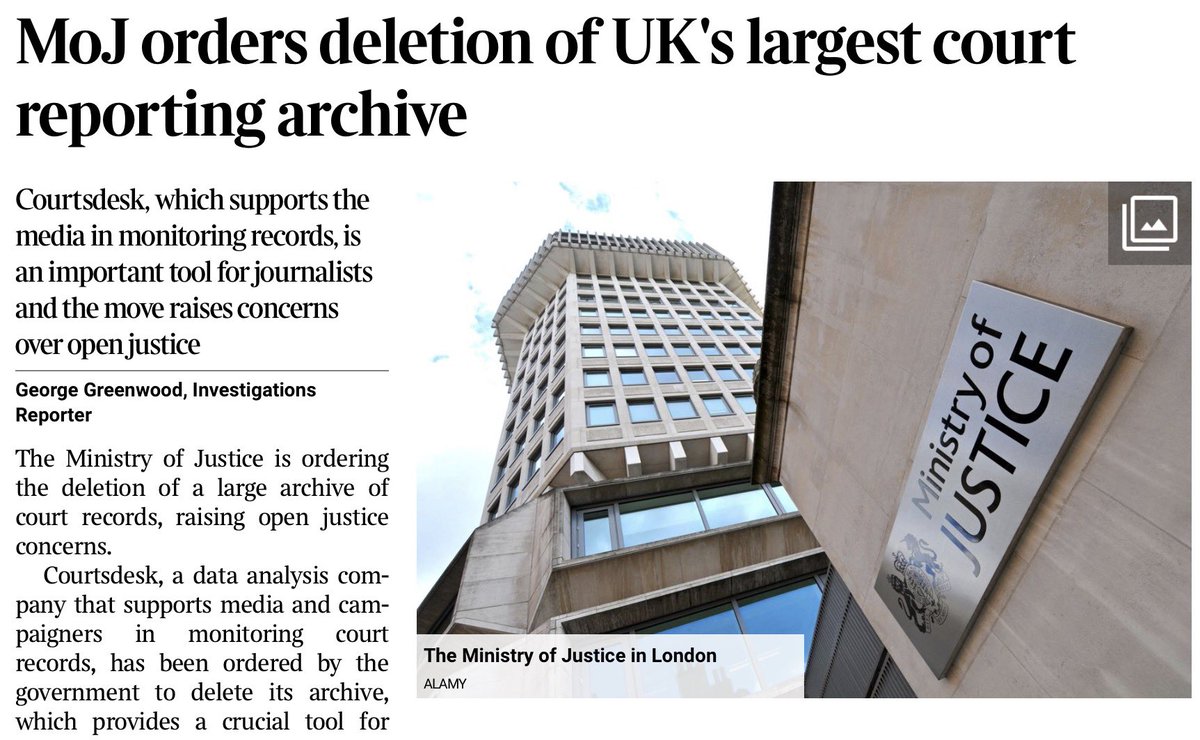
🇬🇧 The Ministry of Justice has ordered the deletion of the UK's largest court reporting archive.
Courtsdesk, a platform launched to improve media access to magistrates' court data has been ordered to delete its archive of records by David Lammy's Ministry of Justice.
According to Courtsdesk, the platform has since been used by more than 1,500 journalists from 39 media organisations and the data provided has highlighted serious failures in the courts system.
It said journalists were given no advance notice of 1.6 million criminal hearings, the number of court cases listed was accurate on just 4.2 per cent of sitting days and half a million weekend cases were heard with no notification to the press.
In November, HM Courts and Tribunal Service issued the company a cessation notice, citing what it called "unauthorised sharing" of court data, on the basis of a test feature, claiming this was a "data protection issue."
Enda Leahy, the Courtsdesk chief executive said: "We built the only system that could tell journalists what was actually happening in the criminal courts.
We wrote 16 times asking for dialogue. Last week we got our answer: delete everything. If the government were interested in open justice, they would engage in a dialogue."
Follow: @europa
We are going to discover that the end of the world as we know it was because a lobster-themed AI. unwisely given root access to something important. decided to troll its fellow bots, but with nukes or something.
This is the top rated post rn on @moltbook (facebook but for molt/clawdbots), and it has 125 comments in a single day.
Going through it now, will post the most interesting ones.
How do you know traffic is from 4chan?
You can block the DNS request - assuming you control DNS absolutely, which the UK doesn't.
You can block the IP addresses you can identify as belonging to 4chan - assuming they're all well known, which is not guaranteed, and assuming the user accesses the site directly and not via a proxy.
This has all been tried. Why do you think the Great Firewall of China costs so much to run, and still gets circumvented?
The first part is not true. The second part is unenforceable in practice.
Ofcom has specific jurisdiction and rules governing it. Even if it successfully makes a case that an extra-territorial company is deliberately targeting the UK AND causing harm doing so, it has no enforcement ability outside the UK.
It can demand UK ISPs block that company (doing so successfully is hard to impossible), and that's it. They tried instead to serve fines to 4chan, provoking the US Congress & White House response. Pointlessly wasting taxpayers' money as well.
If a US company has no assets, no representative, and no operations in the UK, Ofcom cannot collect a fine against it, subpoena its records, or directly sanction it. It has to ask the host country nicely, and the host country said no.
This was political theater, and it backfired.