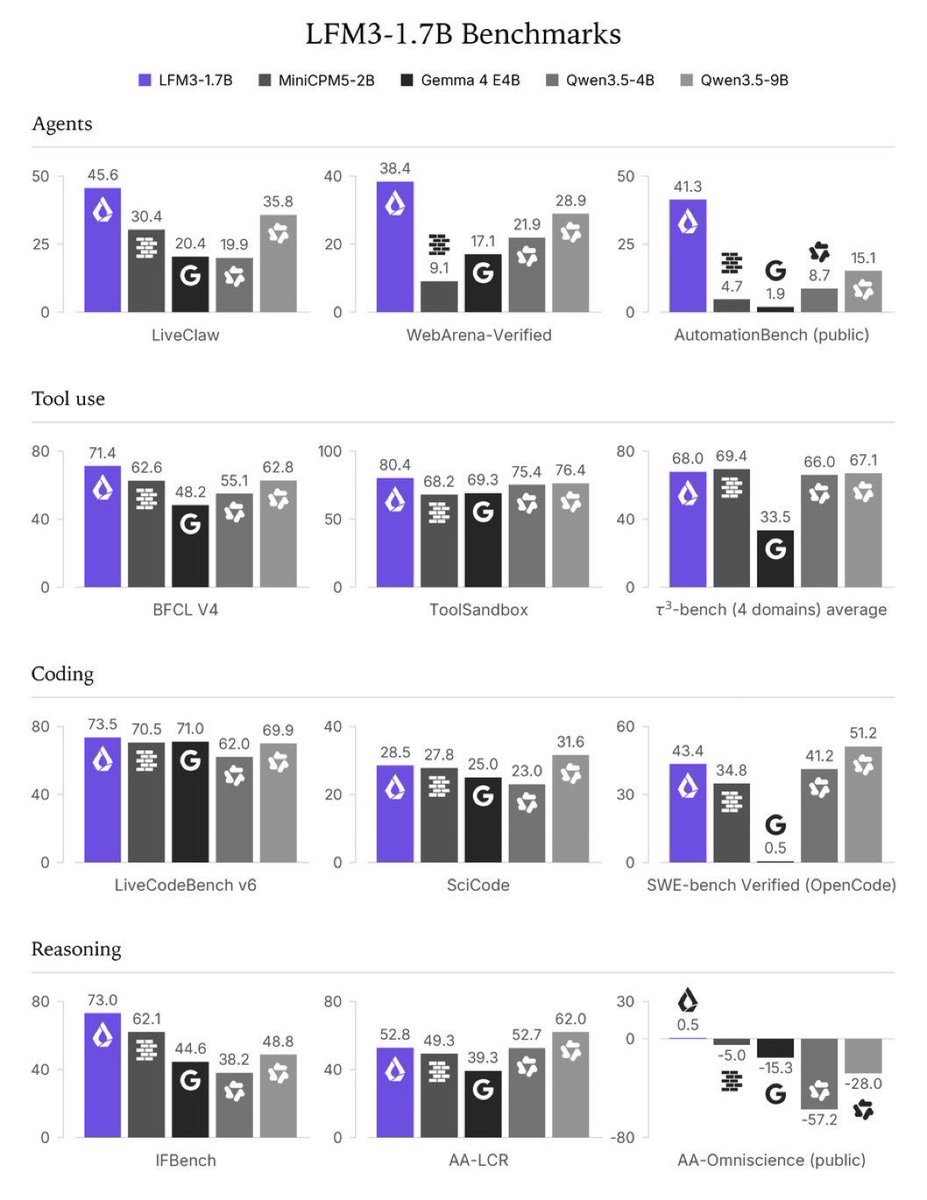
Introducing 𝙻𝙵𝙼𝟹: our new generation of Liquid Foundation Models. With a new tri-hybrid architecture and new multimodal encoders, the LFM3 family is the ideal model suite for specialized intelligence.
> 6 model instances, across text, audio, vision, and omni modalities, generative and decision models.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱: text, 256k context window.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱: vision-language model with video-input support for spatial understanding
> 𝙻𝙵𝙼𝟹-𝙰𝚞𝚍𝚒𝚘-𝟸𝙱: tool calls, voice chat, reasoning in 18 languages.
> 𝙻𝙵𝙼𝟹-𝙾𝚖𝚗𝚒-𝟸𝙱: an omni model combines vision, audio, and language.
> 𝚍𝟷-𝟸𝙱 and 𝚍𝟷-𝙾𝚖𝚗𝚒-𝟸𝙱: decision models with typed outputs and calibrated probabilities in a single pass. Omni adds audio input.
> fine-tune on 1 GPU.
> a new tri-hybrid architecture
> architecture optimized for 14 processor classes across GPUs, CPUs, and NPUs.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱 is a beast. It performs competitively with Gemma 4 12B (6x larger), and Gemini 3.5 Flash Lite, and GPT-5.6 Luna, with 1.9B parameters.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱 is #1 on the Pareto frontier of device intelligence 𝚙𝚒𝚙𝚎𝚝𝚝𝚎.𝚕𝚒𝚚𝚞𝚒𝚍.𝚊𝚒
Every modality for specialized intelligence. Pick the one that fits your use case, customize it, and run it on-device.
1/ 🧵
This is a really exciting release. The Ornith models have always been strong performers that run fast, getting a 122B param model is great to see.
We’ll get this running on the Spark soon. ⚡️
Aloha!🌺 Meet Ornith-1.5-122B: No Tradeoff Between Strong and Fast
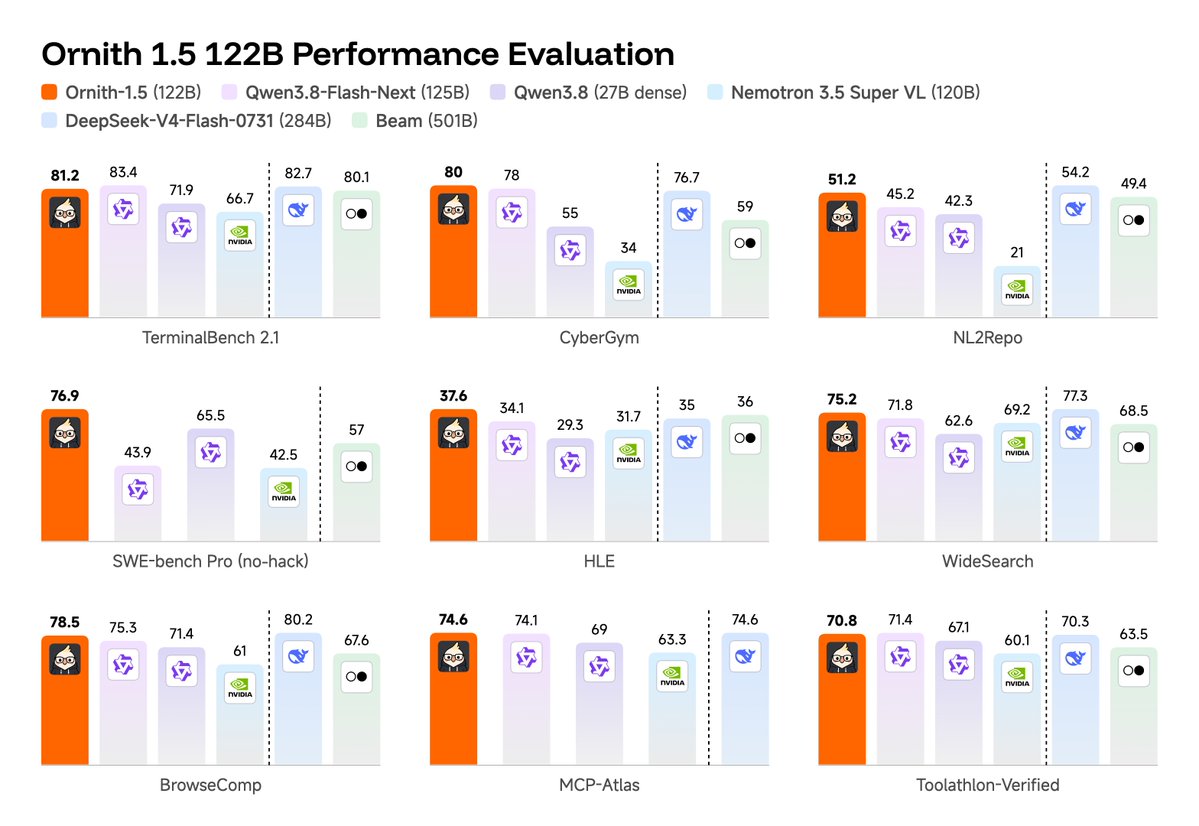
Stronger. Faster. Leaner. Ornith-1.5-122B delivers frontier-level capabilities with exceptional inference efficiency. With superior instruction following, stronger task decomposition, and deeper understanding of real-world workflows, it achieves state-of-the-art performance among open-source models of comparable size, while running on a single NVIDIA DGX card!!
Open weights under the MIT license.
Coding
✅SWE-bench Verified: 0.845
✅TB2.1: 0.813
✅CyberGym: 0.800
✅NL2Repo: 0.512
Agentic
✅HLE: 0.446
✅BrowseComp: 0.785
✅MCP-Atlas: 0.746
✅Toolathlon: 0.708
🤗Hugging Face: https://t.co/w1hD6rra1o
We can’t wait to see what you build with Ornith-1.5-122B.
Run Nvidia’s new Nemotron 3.5 Super VL on a single DGX Spark. ⚡️
One command pulls the container, the model, checks your system, and starts the server with MTP.
~58 toks/s coding
~60 toks/s reasoning
Check out the repo here:
https://t.co/DAvLLBEG0D
NVIDIA Nemotron 3.5 Bolt is LIVE! ⚡️
- 74B params, 9B active
- Built to run locally in 24 GB of memory
- Text, images and video
- LiLiCorr drafter for speculative decoding
- Up to 256K context
This could be THE replacement for Qwen3.6-35B!!
Link below.
Now you can run MiMo V2.6 Flash RL on a single DGX Spark!
Our one command deployment package gets your spark:
- A 309B total / 15B active MoE with text + vision capabilities.
- Full 262k context
- Decode ~45 tok/s coding and ~47 reasoning
Repo in the comments👇 https://t.co/qgR918p3Kj
Credit to @benthecarman for the EXL3 quant and @MiaAI_lab for the DGX Spark deployment pattern.
Let us know how your runs go.
#localai
https://t.co/IKRHhfUjtX