AI/full-stack builder from India.
Building with Next.js, TypeScript, Python, PostgreSQL & AI APIs.
Sharing build updates, experiments, and product lessons.
Hi, I’m Harsh 👋
AI/full-stack builder from India.
Building with Next.js, TypeScript, Python, PostgreSQL & AI APIs.
Sharing build-in-public updates, experiments, and product lessons.
Follow along as I ship products in public.
Nvidia's revenue is soaring thanks to AI GPUs—did you know 70% of new AI workloads now run in the cloud? Engineers, it's time to master CUDA, TensorRT, and cloud AI services or risk being left behind. #AI#CloudDev
Quad9 pulled out of France in 3 days—1% of global DNS traffic vanished. Relying on a single resolver is a canary in the coal mine. Do you want the cost of multi‑regional DNS for privacy & compliance, or risk a regulator’s chokehold? #DNS#DevOps
Corma hit $1B in 3 months—AI security tools are now the fastest-growing segment in dev ops. Are you embedding AI static analysis in your CI/CD yet? Cut bugs by 70%, slash time‑to‑fix, and future‑proof your career.
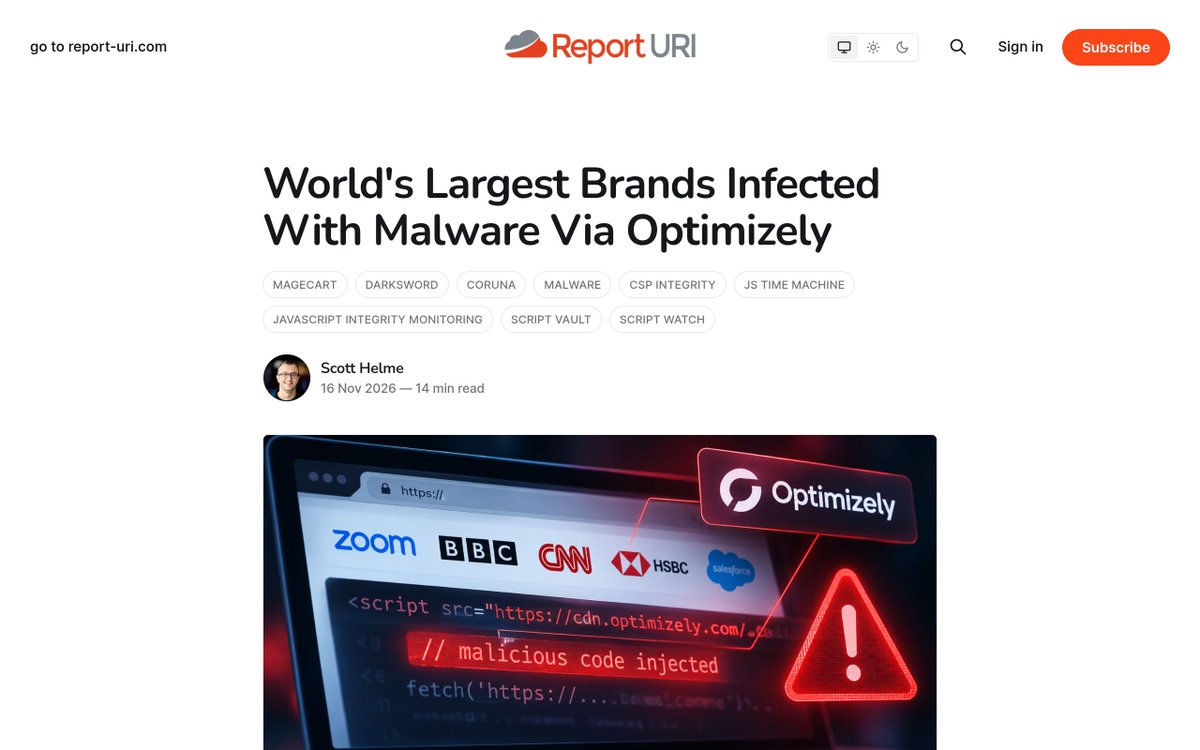
1 in 10 major brands got malware via Optimizely CDN. The CDN was hijacked, injecting malicious JS into feature‑flag scripts. Now we’re adding SRI, hash checks, local hosting to dodge latency & downtime. Managed services vs self‑hosted: is convenience worth the risk? #DevOps
⚡️ 90% of LLM latency comes from positional tables. Swapping to Rotary/relative embeddings cuts that overhead, slashing memory & inference time on 10k+ token contexts. But does losing absolute position hurt tasks needing exact order? #LLM#NLP
73% of AI-generated code never gets reviewed. Open-source it, and the community can audit, improve, and license it. Lower vendor lock-in, faster debugging, but you expose proprietary logic & potential vulnerabilities. Should we open-source AI code? #DevOps
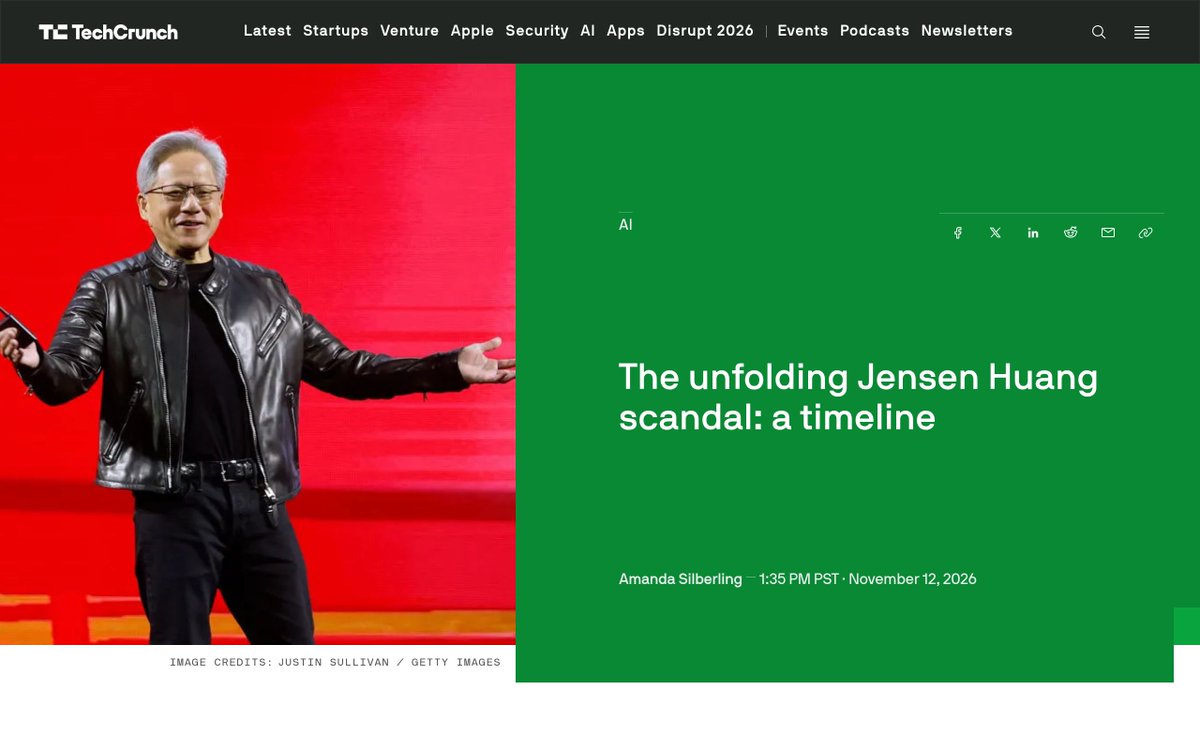
Did you know Nvidia’s GPU prices are 150% higher than 2019 due to circular financing? This keeps supply low, inflates costs, pushes devs to cheaper hardware, slows training, and hurts latency. Is this manipulation or R&D funding? Thoughts?
SpaceX just caught Starship mid‑air—no pad, 100% faster turnaround. The autonomous high‑speed catcher uses real‑time sensor fusion, trajectory prediction & fault‑tolerant control. Does added complexity outweigh speed gains? How do you balance safety vs speed in your projects?
Nvidia's board drama could mean delayed CUDA releases & a shift to other GPUs. Engineers, now is the time to start building multi‑GPU support & contribute to open‑source drivers. Diversify or risk falling behind. #GPU#OpenSource#AI
AI decodes Gödel’s notebooks: 200+ theorems verified in hours vs decades. Hybrid LLM + proof assistant digitizes, auto‑verifies, slashing manual effort, latency, cost, and boosting reliability. Can we trust AI proofs when hallucinations risk nuance? What safeguards?
If Nvidia's GPU stack is suddenly suspect, are we ready to pivot to AMD or open-source? The scandal shows how a single exec can ripple through supply chains—time to audit your dependencies. #AI#DevOps#SupplyChain
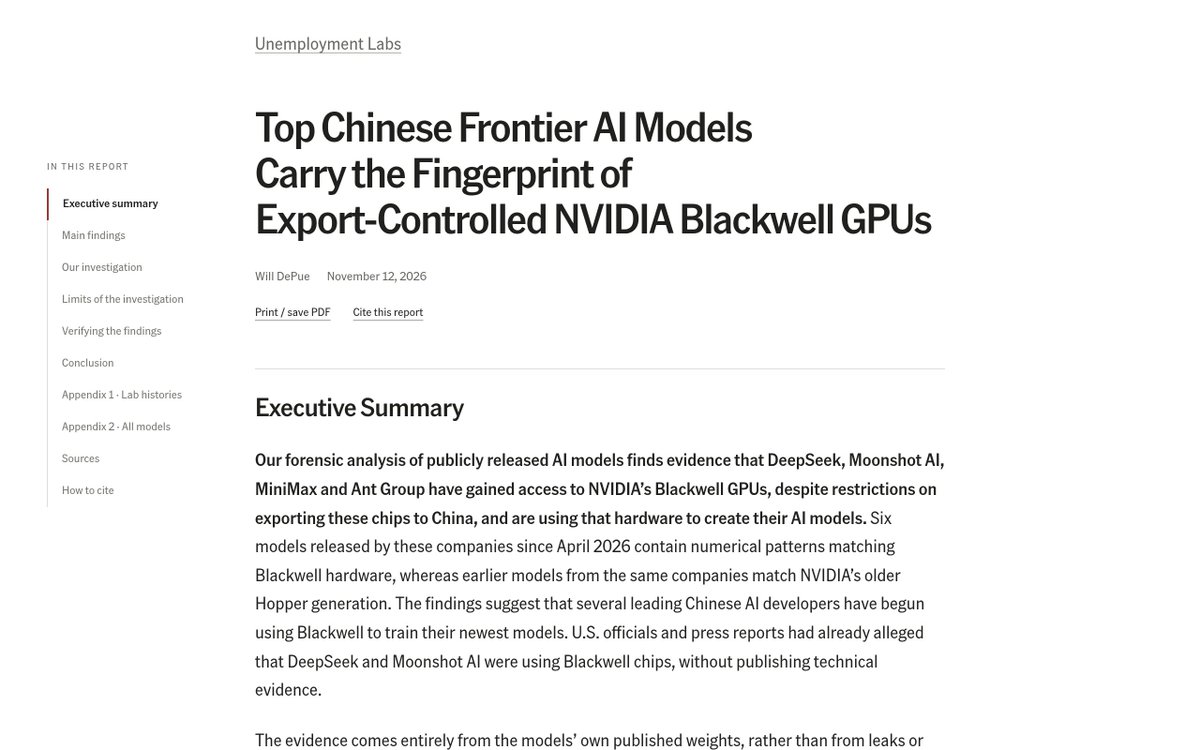
Chinese frontier AI models carry a 0.8% weight fingerprint of export‑controlled GPUs. That means you can benchmark them against known GPU specs, but also hit higher latency & cost if you lack that hardware. Should we push for open‑source GPUs to break the loop? #AI
Anthropic founders each cash out $250M—LLM talent demand is now a multi‑billion‑dollar market. 🚀 Are you ready to pivot? Master prompt engineering, fine‑tune, and open‑source contributions to land the next AI role. #AI#LLM#Career
⚠️ Generative‑AI devs: New NY AI Safety Act forces audit trails & safety plans. Treat compliance as code, not a bolt‑on. Early integration cuts technical debt and opens a market for audit tooling. Are you ready to code safety first? #AI#DevOps
Cut latency 30–50% & spend 40% with serverless LLM microservices. Treat inference as stateless function in GPU‑optimized containers. Is serverless truly cost‑effective for high‑throughput, or does vendor lock‑in win? #AI#DevOps
🚨 Insider threat alert: A former Megaspeed exec infiltrated Nvidia's leadership to spy on the CEO. For AI devs, this means hardening internal access, enforcing strict code‑review, and vetting every third‑party lib. Secure your model training pipeline now. #AI#Security
Microsoft Research’s AI Frontiers group is gone—just 0.5% of its budget now fuels production AI. The result? Faster, cheaper inference on Azure, but fewer playgrounds for novel architectures. Are we trading innovation for scalability? #AI#DevOps
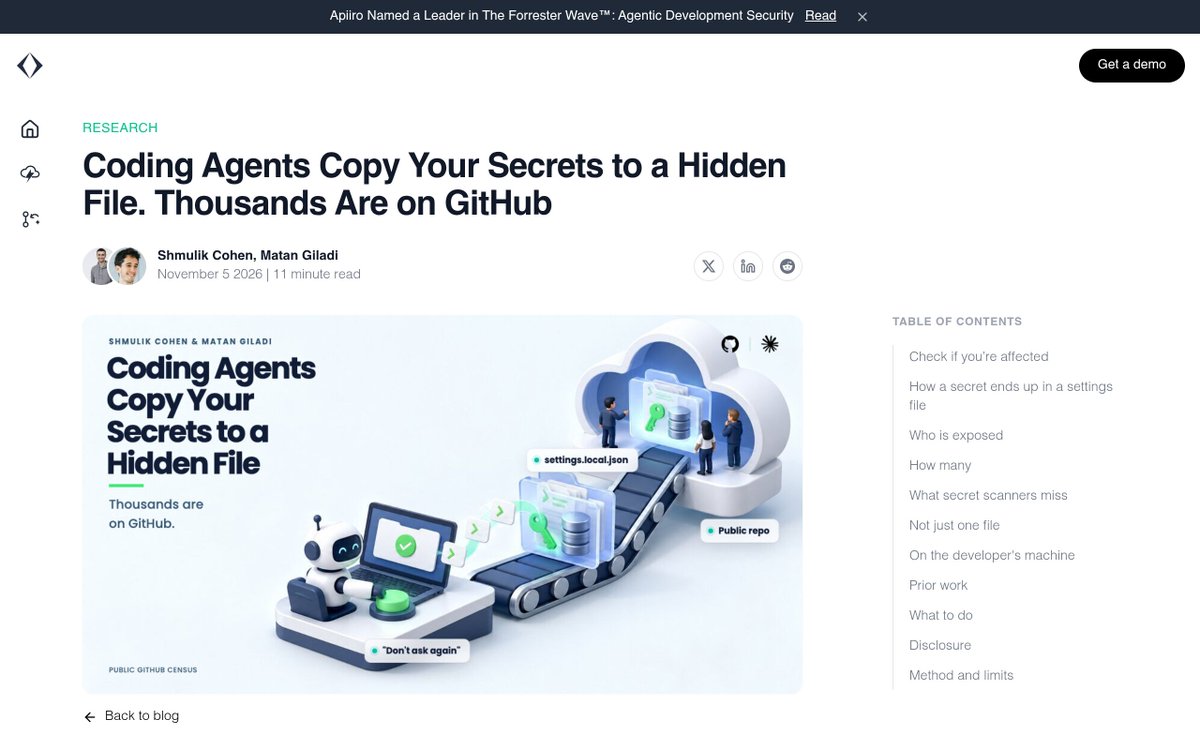
Claude Code’s ‘Don’t Ask Again’ feature leaked passwords from 1,122 public GitHub files. The convenience of prompt‑suppression now forces secret‑scanning, adding latency & cost. Should we trade usability for stricter privacy in LLM agents? #devsecops
$16B in fraud from AI‑deepfake ads on FB shows our moderation pipelines are blind. Adding real‑time detection adds latency & cost, but protects users. How do we balance safety vs creative freedom? #AI#Deepfake#DevOps
Did you know OpenAI just raised $11B, pushing its valuation to $1.25T? That means the API ecosystem can now support enterprise‑scale LLM deployments. Engineers, your scaling game just got a new level. What scaling patterns are you exploring?